Finished reading:

Dungeon Crawler Carl series, book 8.
Published . 704 pages.
Started ; completed September 26, 2026.

The thing about a maddening itch between your shoulder blades is that it feels so good when you scratch it, and even better when someone else scratches it, and better still if that person hits the right spot because they love you and they've performed this service for you so often and attentively that they know exactly which spot to hit.
One of the recurring themes in Spider Robinson's short stories and novels is people who have close relationships suddenly realizing that they have acquired a psychic link. He comes up with endless ways to play this scene out, but my favorite – I think it's from one of the later Callahan's tales – is when one person scratches another between the shoulder blades and hits the exact right spot the very first time and they realize that they are now psychically linked.
Maybe it's a primate grooming reflex, maybe it's receiving a gesture of love and care. Maybe those are the same things. Having your itch scratched for you feels good. Not just primates, either: cats with the flexibility to reach any part of their body with all four of their paws and their teeth will nevertheless purr like a badly-tuned diesel outboard when you scratch them just right.
Since the outset, the free software/open source movement has extolled the virtues of technological self-determination, which is to say, deciding how the computers and programs you use will work. This is often described as "scratching your own itch."
There is no question that scratching your own itch in this way is hugely and enduringly satisfying. On my laptop, I have a variety of little scripts and keybindings and bits of automation that I've built up over the years and every time I use one of these, I get a little hit of brain-reward.
The latest: I got tired of alt-tabbing to get to the file explorer, only to discover that I'd closed all my file explorer windows, meaning I had to mouse over to the dock and open a new one. So I bound "Windows key + E" to opening a file explorer after reading a message board post from an ex-Windows user who'd done this (apparently this is a standard Windows keybinding).
I've fully retrained my fingers to type Win-E rather than alt-tab when I want to get at a graphic filesystem and every time I do, I get the tiniest little pleasant jolt of pleasure. I scratched my own itch!
But even better than this are the little scripts that other people have thoughtfully made for me over the years. The oldest of these still in daily use is more than 20 years old, a bash script called "boingpic" (from when I was still working on Boing Boing). When I run this, it iterates interactively through the files ending with "jpg" or "png" on my Desktop, tells me how wide they are, prompts me to resize them or hit enter to keep their size, and then rsyncs them to the directory on my server that corresponds to https://craphound.com/images/.
If this strikes you as weird and inefficient, that's fine, because it does exactly what I need it to do, and I've memorized it through long, long use. And on top of all that, boingpic.sh was written for me by my dear old friend Seth David Schoen, when we were one of a bare handful of EFF staffers in the early oughts and hung out together all the time. Every time I use it, it reminds me of Seth, and good times, and I feel good.
For centuries, people have fought for the right to self-determination. The disability rights rallying cry "Nothing about us without us" actually dates back to 16th century Poland (it was the basis for the formation of a Polish parliament that wrested power away from the king). Any parent who has avoided a conflict over getting dressed for school by swapping out "Put your clothes on right now!" for "Which would you rather put on first, your shirt or your socks?" knows how far even a little autonomy can go.
I worked as a computer programmer from the age of 17 to about the age of 29, and while I was never a spectacular coder, I was good at it, and I wrote a lot of code for myself that precisely met my needs, which always felt great. It's one of the reasons I have always championed low-code/no-code software development tools, from Logo to Hypercard to Visual Basic to Scratch. Sure, the code that you write with one of these tools might not be "efficient" from a CPU/memory-usage perspective, but the point is that you write it. You don't have to convince someone else to do you a favor, you don't have to part with any of your money – and you don't have to try to get someone else to understand what you mean when you describe the tool you want.
When I worked at Bakka Books (the world's oldest surviving science fiction bookstore, in Toronto), we organized our inventory using an extremely idiosyncratic Filemaker database created by the store's then-owner, John Rose. John lovingly tended that Filemaker app, tweaking it on his days off to make it better suited to the very specific needs of a science fiction bookstore with a giant used section and an important sideline in keeping collectors' want-lists that we consulted whenever we bought more used books. There are doubtless "better" bookstore stock-keeping systems (including the one that Bakka uses now, in its latest incarnation as BakkaPhoenix), but that Filemaker app was John, a presence in the store even when he wasn't there, embodying his management and literary and retail theories on a MacSE by the cash-register.
I am highly skeptical of vibe-coding in the sense of writing code for other people to use. But when I meet people who've vibe-coded their own apps for their own use to scratch their own itches, I completely get their excitement. They've scratched their own itch! I know exactly how good that feels:
https://pluralistic.net/2026/07/03/rod-logic/#making-flippy-floppy
Sure, I have concerns about this kind of personal vibe-coding, the biggest of which is that if you aren't a skilled programmer, you might end up vibe-coding an app that you can't adequately assess, so it might contain subtle defects that make you vulnerable to security risks and/or expose your sensitive information to the public internet. But there are domains and use-cases where I am totally willing to accept that vibe-coding can enhance someone else's life in important ways, by letting them build exactly the widget they need, and if (when) it breaks, they can just do it again.
This is even better than "nothing about us without us." It's not just insisting that someone else "gather your requirements" before producing a tool that you will rely on and require. This is you, producing that tool for yourself, which means that you might be able to embed features and affordances into it that you can't even articulate, let alone defend. There's something undeniably great about scratching your own itch and hitting exactly the right spot.
Even so: the experience of working through your requirements with someone else is clarifying and disciplining, because while you are the domain expert on your needs, that doesn't mean you're the domain expert on how to address those needs. You have the worm's eye view of your life and your needs, while an expert can have the bird's eye view that comes from working with many people, exposing them to many ways of solving problems, including ones you've never thought of.
Darren, the contractor who put in our new kitchen a couple years ago, had ideas for cabinet- and appliance-placement that had been refined by seeing, demolishing, building and revising orders of magnitude more kitchens than we had ever cooked in, and moreover, he clearly cared about our long-term happiness in our own home. The kitchen is great.
That care makes all the difference. Skilled craftspeople can bring expertise to the project that doesn't trump your needs, but can be co-equal with them. Scratching your own itch is great, having your itch scratched by someone who cares enough about you to know where your itch is, that's even better. But best of all is for that person to find the itch you didn't even know you had and scratch that, too. That's something that relies on the human connection that the best free/open source projects embody, the co-creation and community between developers and users.
If you've ever filed a bug against a free/open project and worked through the testing the devs need to squash it, you've experienced that co-creation. The devs want their code to work, because they care about the users, and you as a user can help other users and the devs by reciprocating that care through conscientious, patient, attentive bug reporting and testing.
I think that so much of the outrage about slop code – floods of garbagey pull requests and bug reports – is the result of the collapse of this dynamic. Slop's not merely annoying or time-wasting: it's a betrayal of the love and care that goes into writing and maintaining code for others. Your cat can scratch any part of its body, but it wants you to scratch it, and it will hiss at you and even claw at you if you scratch it the wrong way.
(Image: Orrling and Tomer S, CC BY-SA 3.0, modified)

Machine god metaphors eat your brain https://www.programmablemutter.com/p/machine-god-metaphors-eat-your-brain
Here’s What California Is Learning From Solar Panels Built Over Irrigation Canals https://www.kqed.org/science/2002033/heres-what-california-is-learning-from-solar-panels-built-over-irrigation-canals
Toads in a Pond https://longforgottenhauntedmansion.blogspot.com/2026/09/toads-in-pond.html
The Federal Agency That’s Supposed to Protect Consumers Just Made Another Business-Friendly Move https://www.propublica.org/article/cfpb-consumer-complaint-database
#25yrsago Surveillance is a security failure https://www.theguardian.com/technology/2001/sep/27/onlinesupplement.afghanistan
#25yrsago 9/11: the Viridian take https://web.archive.org/web/20011023095346/http://www.viridiandesign.org/notes/251-300/00272_au_revoir_belle_epoque.html
#25yrsago Announcing Wikipedia https://web.archive.org/web/20060517024408/http://www.kuro5hin.org/?op=displaystory;sid=2001/9/24/43858/2479
#25yrsago Phil Zimmerman says PGP can't be blamed for 9/11 https://slashdot.org/story/01/09/24/162236/philip-zimmermann-and-guilt-over-pgp
#20yrsago RIP, sf writer John M Ford https://memex.craphound.com/2006/09/25/rip-sf-writer-john-m-ford/
#20yrsago Gigantic Little Nemo book does justice to the loveliest comic ever https://memex.craphound.com/2006/09/25/gigantic-little-nemo-book-does-justice-to-the-loveliest-comic-ever/
#20yrsago 747s as flying Unix hosts: SCADA in the sky https://memex.craphound.com/2011/09/25/747s-as-flying-unix-hosts-scada-in-the-sky/
#20yrsago Mickey Infinite Copyright mashup https://web.archive.org/web/20061027141551/http://python.net/~goodger/projects/graphics/#mickey-s-infinite-copyright#mickey-s-infinite-copyright
#20yrsago HOWTO make a shoulder-bag out of floppies https://web.archive.org/web/20061025050629/http://www.instructables.com/id/E86165FIENERIE2PV6/?ALLSTEPS
#15yrsago TOSAmend: turn all online “I Agree” buttons into negotiations https://web.archive.org/web/20110925122850/https://www.owocki.com/2011/09/02/tosamend-the-easy-way-to-modify-web-service-terms-of-service-agreements/
#15yrsago That’s Disgusting! Awesomely gross picture book https://memex.craphound.com/2011/09/26/thats-disgusting-awesomely-gross-picture-book/
#10yrsago Swedish law will let you write off the money you spend fixing things rather than trashing them https://www.theguardian.com/world/2016/sep/19/waste-not-want-not-sweden-tax-breaks-repairs
#10yrsago Climate denial’s internal contradictions spring from a need to defend economic doctrine https://link.springer.com/article/10.1007/s11229-016-1198-6
#10yrsago There’s no pumpkin in “100% canned pumpkin” https://web.archive.org/web/20160927152542/https://www.foodandwine.com/news/i-just-found-out-canned-pumpkin-isnt-pumpkin-all-and-my-whole-life-basically-lie
#10yrsago The AI Now Report: social/economic implications of near-future AI https://web.archive.org/web/20161014142521/https://artificialintelligencenow.com/media/documents/AINowSummaryReport_3.pdf
#10yrsago Whistleblowing Wells Fargo loan officer describes years of fraudulent, criminal culture in the bank https://truthout.org/articles/wells-fargo-whistleblower-they-are-all-riding-the-stagecoach-to-hell/
#10yrsago Writer in 29th year of solitary confinement barred from reading his own book https://solitarywatch.com/2016/09/20/writer-in-solitary-confinement-is-barred-from-reading-his-own-book/
#10yrsago Despite sabotage and dirty tricks, Jeremy Corbyn wins Labour leadership race in unprecedented landslide https://www.bbc.co.uk/news/uk-politics-37461219
#10yrsago Who decided Corbyn was “unelectable”? https://www.youtube.com/watch?v=8os-nKuoM3o
#10yrsago The democratization of censorship: when anyone can kill as site as effectively as a government can https://krebsonsecurity.com/2016/09/the-democratization-of-censorship/
#5yrsago Demonopolizing the internet with interoperability https://pluralistic.net/2021/09/24/comcom-acm/#cacm
#5yrsago Copyright reversion, bargaining power, and authors’ rights https://pluralistic.net/2021/09/26/take-it-back/
#5yrsago The Scholars of Night https://pluralistic.net/2021/09/26/mike-ford-rides-again/#cold-war-zeitgeist
#1yrago Apple threatens to stop selling iPhones in the EU https://pluralistic.net/2025/09/26/empty-threats/#500-million-affluent-consumers
#1yrago The billionaires aren't OK https://pluralistic.net/2025/09/24/robo-lickspittle/#just-not-evenly-distributed
#1yrago Rage Against the (Algorithmic Management) Machine https://pluralistic.net/2025/09/25/roboboss/#counterapps

Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: Rethinking Our Relationship with AI, Sep 30 (Emtech)
https://event.technologyreview.com/emtech-future-2026/detailed-agenda
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
Brighton: Digital Sovereignty and the Post-American Internet (Green Party Conference), Oct 3
https://www.openrightsgroup.org/events/digital-sovereignty-and-the-post-american-internet/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Paris: Slow Tech Summit, Oct 15
https://slowtechsummit.com/
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Kilkenny (Kilkenomics), Nov 6-8
https://kilkenomics.com/
Vancouver: Enshittification (Sid Williams Theatre Society), Nov 10
https://www.sidwilliamstheatre.com/events/cory-doctorow-talks-enshittification/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Are 'AI Apocalypse' Warnings Just Marketing? (What's Left)
https://www.youtube.com/watch?v=IXd9HwIE5bo
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING

This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
Binance has just filed to dismiss with prejudice its defamation lawsuit against the Wall Street Journal, which it filed in March after the Journal published various reports about a possible DOJ investigation into Binance over violations of sanctions against Iran.
Interesting timing, given Bloomberg just today confirmed such a probe is open and being handled by the SDNY DOJ’s office.
After the Corner Bakery meeting, Navatek’s CEO, Martin Kao, sent an initial $150,000 to the Collins super PAC using the shell company. Two months later, he told Navatek executives that Collins committed to getting the company $32 million in naval contracts, according to an internal company email reviewed by ProPublica.

Well, fuck. California Attorney General Rob Bonta just surrendered to the Trump-aligned Ellison billionaires who want to take over and destroy Warners, merging it with the chudded out husk they've made of Paramount, leaving these two colossal, corrupt, useless assholes to control Warners, Paramount and Tiktok:
In announcing the settlement, Bonta's office touted a long list of concessions the AG had wrung from the Ellisons before greenlighting this indefensible, illegal and dangerous merger. Every! single! one! of these concessions is meaningless bullshit. Bonta just handed the American movie and TV sector to two of the most odious creeps to draw breath, surrendering without firing a shot.
For a breakdown of how fucking useless this settlement is, read (who else?) Matt Stoller, whose piece breaking it down is titled "Happy Oligarch Day!"
https://www.thebignewsletter.com/p/happy-oligarch-day-as-trump-aligned
The first thing Stoller points out is that every one of the "commitments" in the settlement only matter if Bonta's office enforces them. Bonta's office will never have as much leverage over Warnermount as it has today, when the company is paying a $7m/day "ticking fee" while the merger is stalled (thanks to an injunction secured by the Hollywood unions, whom Bonta has just royally fucked, because they can't afford to litigate this case without the AG office's backing). So even if any of these conditions meant anything (which they do not), they won't be enforced. If Bonta can't bring Warnermount to heel today, when they have to pay $7m/day for so long as they're crosswise with him, how will he ever get them to do shit?
He.
Will.
Not.
But it doesn't matter. It doesn't matter! Because the Ellisons have given Bonta nothing. Take the guarantee that Warnermount "will make 30 films" for the next two years, and 32 films thereafter. That's what's been announced, but when former FTC Commissioner Alvaro Bedoya dug into the actual wording, he discovered they are only committing to distributing 30 films, and to making 15 films, which they are allowed to co-produce with other studios. They made 18 movies last year. Under the terms of this deal, they have "committed" to making fewer movies than they make today:
https://x.com/BedoyaUSA/status/2102173188557799773
They've committed to not selling the Warner lot. For five years. But they are allowed to move it out of LA, which is something my neighbors in Burbank are doubtless delighted to learn. After that, they can move it to whatever state offers them the biggest sweetheart tax deal and the weakest union protections.
They are prohibited from gouging the theater chains and putting them out of business to promote their streaming business. For three years. After that, they can let 'er rip.
Then there's the "editorial board" that will oversee the Ellisons' management of CNN and MSNBC, nominally to keep it from getting the CBS treatment and going 24/7 Great Replacement/Haitians eating dogs/Charlie Kirk funeral pyrotechnics spectaculars. Guess who chooses the members of the editorial board? The Ellisons. As Stoller writes, "it’s downright comical [that] they demanded that David Ellison not corrupt CNN by having David Ellison appoint a board ensuring that David Ellison not do that."
But you can ignore everything you've just read, because the settlement includes a clause that says they don't have to do any of the things it says they have to do. This is the "force majeure" clause, which is not like a normal force majeure clause (which allows the parties to back out of their commitment in case of war, wildfires, etc). This force majeure clause lets Warnermount tear up the entire agreement if there's a strike or a recession.
So: if (when) the Hollywood unions go on strike over this betrayal (which they absolutely should do), the agreement becomes null. And if (when) the AI bubble bursts and there's a massive recession, the agreement becomes null. And if (when) Trump's War on Oil plunges the US into Jimmy Carter-style oil economic tsunami, the agreement becomes null.
As Stoller points out, 12 State Attorneys General signed this piece of shit. Every one of them is a lawyer, and every one of them has a staff of lawyers. None of the glaring, catastrophic, utterly disqualifying defects in this "settlement" can possibly be a surprise to them. These Democrat warriors surrendered to Trump's oligarchs, giving them everything, including control over the American film and TV industry for so long as it limps along. They just assumed you wouldn't notice.
Stoller says he's "in a strangely good mood" about this because of all the political capital it took to get this over the line (unlike, say, Disney-Fox, which sailed through with nary a hitch), saying that it indicates that the public is fed up with monopolies. He's right, they are fed up with monopolies. Everyday Americans, Democrats and Republicans, are telling pollsters they'd back a politician who campaigned on shattering monopoly power:
https://libertyandpower.substack.com/p/pollsters-urge-dems-to-attack-monopoly
So this leaves us to wonder why Bonta (who talked tough in public about this merger and insisted he would never settle for this kind of weaksauce) stabbed the state, the country, Hollywood workers, and the American public in the back like this? Stoller's theory is that Bonta was isolated by "Democratic insiders" who wouldn't back his play.
OK, fine. As Stoller writes, there's no ambiguity here, this is just straight up corruption, oligarch pals of the President getting to roll up and gut the industry's globally important, culturally essential media sector. The "teachers' pets" of the Democratic Party have once again sold out working people in a bid to be liked by the rich and powerful.
This will fuel (more) distrust of America's political class, a distrust that has been repeatedly earned over decades and especially in this decade. Our leaders are "malevolent liars." It's been true for a very long time, but we can no longer pretend otherwise. Perhaps Stoller's right and this means we'll finally get some real change. I hope so. But for now, I'm just furious.
(Image: Todd Dwyer, CC BY-SA 3.0, modified)
Pollsters Urge Dems to Attack Monopoly Power. Candidates are Listening. https://libertyandpower.substack.com/p/pollsters-urge-dems-to-attack-monopoly
#25yrsago Finnish hacker's homebrew OS fits on a floppy https://web.archive.org/web/20010923224224/https://www.menuetos.org/
#20yrsago Can RIAA sue for songs they never verified by downloading from you? https://recordingindustryvspeople.blogspot.com/2006/09/preclusion-motion-filed-in-umg-v.html
#15yrsago Elizabeth Warren explains why taxing the rich isn’t “class warfare” https://www.youtube.com/watch?v=htX2usfqMEs
#15yrsago DoJ audit: meeting served $16 muffins and $8 coffee https://web.archive.org/web/20110921160806/http://news.yahoo.com/16-muffins-8-coffee-served-justice-audit-023623142.html
#10yrsago Psychology’s reproducibility crisis: why statisticians are publicly calling out social scientists https://statmodeling.stat.columbia.edu/2016/09/21/what-has-happened-down-here-is-the-winds-have-changed/
#10yrsago Notorious copyright troll sentenced to 20 weeks’ prison time for beating Uber driver https://torrentfreak.com/copyright-troll-partner-kicked-uber-driver-in-the-head-160923/
#10yrsago Understanding vulvas: what do they really look like? https://www.youtube.com/watch?v=qAFvGrOwVug
#10yrsago The American public subsidized $125m executive bonus for Wells Fargo exec who led massive fraud https://web.archive.org/web/20160922140758/https://www.ibtimes.com/political-capital/taxpayers-subsidized-wells-fargo-executive-pay-amid-banks-fraud-2419456
#5yrsago The music monopolists https://pluralistic.net/2021/09/23/remedies-beyond-antitrust/#face-the-music
#5yrsago The Halloween Moon https://pluralistic.net/2021/09/23/remedies-beyond-antitrust/#creepypasta
#1yrago The enshittification of solar (and how to stop it) https://pluralistic.net/2025/09/23/our-friend-the-electron/#to-every-man-his-castle
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: Rethinking Our Relationship with AI, Sep 30 (Emtech)
https://event.technologyreview.com/emtech-future-2026/detailed-agenda
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
Brighton: Digital Sovereignty and the Post-American Internet (Green Party Conference), Oct 3
https://www.openrightsgroup.org/events/digital-sovereignty-and-the-post-american-internet/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Paris: Slow Tech Summit, Oct 15
https://slowtechsummit.com/
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Kilkenny (Kilkenomics), Nov 6-8
https://kilkenomics.com/
Vancouver: Enshittification (Sid Williams Theatre Society), Nov 10
https://www.sidwilliamstheatre.com/events/cory-doctorow-talks-enshittification/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Are 'AI Apocalypse' Warnings Just Marketing? (What's Left)
https://www.youtube.com/watch?v=IXd9HwIE5bo
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

One of the less remarked-upon aspects of becoming an atheist is how it changes the way you see a sunset. If you believe in an almighty, omnipresent God, then sunsets are one of God's intentional creations, which means that the beautiful colors refracting through the darkling sky were chosen to produce that effect.
To gaze upon a sunset with religious faith is to encounter the intentional act of another mind. To gaze upon that same sunset without faith is to look upon something striking, beautiful, and yet empty; not empty of wonder or beauty, but empty of purpose. No one hung that sun in the sky, no one chose its colors as it sank. It may still be beautiful, but that's a fundamentally different kind of beauty.
There's a sunset that sits halfway between a religious sunset and an atheist sunset: an artist's depiction of a sunset. This represents the choices of another person, another mind, and at the very least, that mind was talking to itself, trying to take something from inside the mind and put it outside of the mind.
Very often, the mind that directed the capturing of the sunset wanted to say something to other people, perhaps even you (think of a loved one sending you a cameraphone picture of a sunset). That painting or photo may not be divine, but it is certainly intentional. To look upon a painting of a sunset – or even a photo of a sunset – is to look upon something someone chose to make. You don't slip and accidentally create a sunset painting. Sunset paintings aren't accidents. The sunset painting has something to say.
Figuring out intentions is our minds' reflexive preoccupation. It's what keeps us from dying in traffic, it's what lets us win at poker. It's the key to love and parenting, to effective management and "managing up." It's why we get mad at people, and why we forgive them. It's why our hearts race in sympathy with the characters in a book or on a screen. It's the automatic and irresistible starting point for every encounter with a poem, a song, a book or a sculpture. It's the most fundamental difference between a sculpture of a tree and a tree: the tree grew all on its own, while the sculpture was made, on purpose, by another person with another mind.
This reflex to attribute intention explains why AI is so controversial, so compelling, and so eerie. Mark Fisher defines eeriness as "when there is something present where there should be nothing, or if there is nothing present when there should be something":
https://www.programmablemutter.com/p/large-language-models-are-uncanny
To look upon an AI-generated text or image is to look upon a thing that was extruded, not chosen. You can slip and prompt an AI-generated image of a sunset, and it will embody no intentionality on anyone's part.
This isn't something we have any experience with. When we see a painting, we reflexively interpret it as having a painter. When we read a book, we reflexively impute auctorial intent to its words. When we converse, we reflexively form a theory about the mind directing the other half of the conversation.
But we can't do this with AI. Anyone who understands how the theory-free statistical inference systems we call "AI" (at this time) work will understand that they are systems that cannot form intent, that have nothing to form intent with:
https://pluralistic.net/2026/09/18/surprise/#wow-signal
Even so, it's hard (or perhaps impossible) to avoid the reflex to impute intention to things that seem to have intenders. Think of your autonomic, unavoidable emotional response to the fictional characters you encounter in literature. Feeling sorrow or joy for imaginary people is weird. They aren't real, and you know they aren't real, and yet you may find yourself moved to tears by their plight.
That aesthetic experience of literature arises from a consensual hack to our reflex to impute human minds to things that are typically the product of human intention. When we experience another person's will – their words or deeds – we try to figure out who they are, and how they feel, and why they act the way they do:
https://genius.com/David-byrne-and-ghost-train-orchestra-she-explains-things-to-me-lyrics
We do this even when we are confronted with just the evidence of others' words or deeds, as when a friend describes an encounter with a stranger. For your reflexive, intention-seeking mind, the author who describes the deeds of imaginary people is an irresistible signal to fire up the old empathy machine and start trying to put yourself in the skins of the people of the tale:
https://locusmag.com/feature/cory-doctorow-stories-are-a-fuggly-hack/
To "converse" with an AI is to carry on a dialog with a fictional character, who is no more real than the imaginary people in a novel. Indeed, the chatbot is less real than the character, because the character is the product of another mind, while the chatbot's words are the product of complex mathematical operations conducted over a massive database of all the words humans have uttered, arranged by their frequency in relation to one another. When that math makes something beautiful or striking, it's like a sunset: no matter how striking it is, it's empty. No one chose those colors. No one chose those words.
In other words, when we interact with an AI, we hallucinate the person on the other side of the interaction. Those hallucinations are far more common and far more consequential than any AI-generated "hallucinations" (these are more properly called "errors" or "defects").
Fortunately, for most of us, the intensity of these hallucinations fades over time, and as that intensity drops off, the character of those hallucinations changes, too. Just as most of us find it easy to set aside the emotions evoked by the plight of imaginary literary figures as having less salience and "realness" than the emotions we feel over the plight of real people we know, for most of us, the experience of AI-generated material has dimmed through repetition.
My first encounters with AI-generated text and images invoked wonder, arising from the tension between the part of my mind that knew this was the product of mathematical operations, and the part of my mind that insisted that a painting must have a painter, a paragraph must have a writer, and a conversation must have an interlocutor. Looking back on the wonder I felt then, I realize that it was largely driven by how good the output was relative to my expectations about how good mathematically-derived sentences and images could be.
The novelty of that experience drove me to grade the machine's output on a curve: "The wonder is not that the dancing bear dances well, it is that the bear dances at all." But with repetition, the stimulus has regressed to the mean. These outputs have an unconvincing lack of texture. The smoothness of AI-generated prose and media makes it unbearably banal. It's hack.
To the extent that AI still surprises me, the surprise is about how much smoothness there is in our real world. The fact that AI can use statistical prediction to answer questions or carry on conversations tells us something important about how regular our real world is. It doesn't prove that statistical prediction is the same thing as understanding:
https://pluralistic.net/2026/09/18/surprise/#wow-signal
Of course, the more you know about a subject, the less convincing the AI's responses are. To be an expert is to know about the grain of your subject: chefs can taste the pinch of spice, painters notice brushstrokes, dancers can decompose the choreography into individual motions.
The other day, someone marveled to me at the quality of the editorial feedback he gets from AI for his prose, saying that a "Tell me what I'm missing" prompt generates suggestions "that would excite a university professor who'd assigned an essay." Speaking as someone who's taught a lot of writers and given a lot of feedback, I think that guy is dramatically overestimating how excited a university professor would be to see the AI-generated feedback he's getting on his essay.
The fact is that non-expert writers mostly make the same kinds of mistakes in their writing, and most writing instruction consists of offering repetitive, near-identical counsel to writers who are making the same kinds of starter mistakes that their peers past, present and future have made, are making and will make.
Mastering the basics of good writing is a matter of practice and feedback, and most of that feedback is rote. What makes a great writing teacher – and what helps to produce great writers – is spotting the non-standard aspects of a student's work that can be developed into a unique and powerful voice. Anyone can help you with the smooth parts of becoming a better writer. Only a good teacher can help you find and refine the texture that will make you a unique writer.
That texture is especially hard to find in beginner work, because beginner work is mostly full of the completely ordinary errors of inexperience, errors that AI can reliably avoid when it extrudes text. But AI-generated prose doesn't have any of those trace-elements of uniqueness, nor can it spot them. These traces are found so many digits after the decimal-place that the AI always rounds them off before it starts doing math.
The more we encounter AIs that have smoothed away the kind of texture we're attuned to, the less we're inclined to hallucinate intentionality, and the less eerie they become. Most of us are slowly but surely becoming AI atheists, and the sunsets are seeming more like the non-intending product of physics than the deliberate products of minds.
There are two great barriers to this AI atheism. First: for most of us, the inability to understand what kinds of intentionality go into which parts of unfamiliar activities makes it easy to assume that any time we see the task performed in the world, it must be intentional, and therefore it must have an intender. In other words: most of us don't hang out at hacker cons, so we have a hard time wrapping our heads around the idea of hacking without hackers:
https://pluralistic.net/2026/09/12/god-in-the-box/#llms-are-fake
But there's a second hurdle that makes it hard for a small but important subset of humanity to understand that chatbots aren't people: the billionaires to whom nearly everyone isn't a real person. These solipsists see chatbots as being equivalent (or even superior) to humans, because they don't think most humans are fully people, either:
https://pluralistic.net/2026/05/13/vibe-governance/#k-hole
For nearly all our species' history, things that seemed to require intent always had an intender. In many times and places (and even now, for many people), it's natural and beneficial to operate as though the natural world has some form of personhood and intention and is therefore worthy of moral consideration. The "rights for nature" movement has made great strides by extending personhood to animals and ecosystems.
But ascribing personhood to chatbots is nothing like ascribing personhood to nature. Indeed, it's fundamentally incompatible with "rights for nature." Think of the abomination that is "corporate personhood": by extending personhood to this human construct, we have made a world where artificial lifeforms – limited liability corporations – can destroy nature and drive animals to extinction. If we extend personhood to these climate-shredding, water-chugging AI models, their personhood will demand the sacrifice of animals, the natural world, and our own wellbeing:
https://pluralistic.net/2026/04/15/artificial-lifeforms/#moral-consideration
Chatbots are marvels of mathematics, and that is enough. They don't need to be people. Mistaking them for people (or even just treating them like people) makes it impossible for us to separate the useful things they can do from the waste, ugliness and wrongness they are so prone to exhausting into the world.
I think it's impossible to build a chatbot using the techniques we're presently calling "AI" that doesn't "hallucinate." However, it's both possible and necessary for us to stop hallucinating about AI.
13 theses on agentic AI and regulation https://backofmind.substack.com/p/13-theses-on-agentic-ai-and-regulation
The Business-to-Industry Index and the Geography of Global Capitalism https://economicsfromthetopdown.com/2026/09/19/the-business-to-industry-index-and-the-geography-of-global-capitalism/
Please Agree to These Terms & Conditions for Your Slider https://blog.dmxrob.net/please-agree-to-these-terms-conditions-for-your-slider/
#25yrsago 9/11 knocks sex off the top of the search charts for the first time ever https://web.archive.org/web/20011019190617/http://www.reuters.com/news_article.jhtml
#25yrsago Post-9/11 flag shortage sparks wave of flag-thefts https://web.archive.org/web/20011024162814/http://www.suntimes.com/output/brown/cst-nws-brown18.html
#25yrsago Pilots' preflight announcement includes exhortation to tackle suspected terorists https://web.archive.org/web/20010919081055/http://www.washtimes.com/commentary/20010919-6357240.htm
#25yrsago Larry Ellison: 9/11 means everyone should have a secret government dossier (on an Oracle server) https://web.archive.org/web/20010924045158/https://www.siliconvalley.com/docs/news/svfront/ellsn092301.htm
#20yrsago Rotary phone cost woman $2,000 over 40 years https://web.archive.org/web/20080526111157/http://www.usatoday.com/news/offbeat/2006-09-14-phone_x.htm
#20yrsago French DRM activists surrender to police https://web.archive.org/web/20070110181344/http://stopdrm.info/index.php?2006/09/20/110-compte-rendu-de-l-operation-des-interoperabilisateurs-volontaires
#20yrsago Zimbabwe’s Internet cut off due to lack of foreign currency https://web.archive.org/web/20070218185156/http://news.zdnet.com/2100-9588_22-6117553.html
#20yrsago An “expert Wikipedia” won’t work https://web.archive.org/web/20061023150433/http://many.corante.com/archives/2006/09/18/larry_sanger_citizendium_and_the_problem_of_expertise.php
#20yrsago RIAA threat-mail parody from McSweeney’s https://web.archive.org/web/20060927155553/https://www.mcsweeneys.net/2006/9/20lloyd.html
#15yrsago Italian MPs propose Internet disconnection law: one copyright accusation from anyone and you lose your Internet connection https://web.archive.org/web/20110924143709/http://www.twitlonger.com/show/d62gmb
#15yrsago Trying to understand riots isn’t the same as excusing riots https://web.archive.org/web/20110924030515/https://www.newscientist.com/article/mg21128306.100-trying-to-understand-the-english-riots-is-not-a-crime.html
#15yrsago ATM skimmer gang invested proceeds in 3D printer to make better ATM skimmers https://krebsonsecurity.com/2011/09/gang-used-3d-printers-for-atm-skimmers/
#15yrsago Facehugger-inspired leather mask https://bobbasset.com/archives/745/
#15yrsago Westerfeld’s Goliath: suitably thrilling conclusion to cracking steampunk WWI YA trilogy https://memex.craphound.com/2011/09/20/westerfelds-goliath-suitably-thrilling-conclusion-to-cracking-steampunk-wwi-ya-trilogy/
#15yrsago Report from 1978’s “Second West Coast Computer Faire” https://web.archive.org/web/20110930035442/https://blog.modernmechanix.com/2011/09/20/the-second-west-coast-computer-faire/
#15yrsago UK patent office seeks public’s help with prior art that invalidates patent applications https://www.peertopatent.org.uk/
#15yrsago 3D printed AR-15 parts challenge firearm regulation https://web.archive.org/web/20110922005752/http://www.thingiverse.com/thing:11636
#15yrsago Minor diplomatic spat when US customs queries Aussie foreign minister’s Vegemite https://www.theguardian.com/world/2011/sep/19/hands-off-vegemite-kevin-rudd
#15yrsago Toronto Convention Centre charges attendees $150/day to use WiFi https://blogcampaigning.com/2011/09/most-expensive-wi-fi-ever/
#15yrsago Tracking down the stories behind a trove of 1920s report cards from a NYC girls’ vocational school https://www.slate.com/articles/life/permanent_record/features/2011/permanent_record/how_i_found_the_report_cards_and_how_they_changed_my_life.html
#15yrsago Movie-industry self-piracy proves that IP addresses aren’t people, invalidates copyright enforcement schemes https://torrentfreak.com/movie-institute-feels-pain-of-ip-address-only-piracy-evidence-110922/
#15yrsago Cost of raising middle-income child in USA increases by 40% in ten years https://web.archive.org/web/20110925000225/https://money.cnn.com/2011/09/21/pf/cost_raising_child/index.htm
#10yrsago HTML standardization group calls on W3C to protect security researchers from DRM https://www.eff.org/deeplinks/2016/09/html-standardization-group-calls-w3c-protect-security-researchers-drm
#10yrsago I have found a secret tunnel that runs underneath the phone companies and emerges in paradise https://memex.craphound.com/2016/09/22/i-have-found-a-secret-tunnel-that-runs-underneath-the-phone-companies-and-emerges-in-paradise/
#10yrsago Gene Luen Yang wins a Macarthur “genius” prize! https://web.archive.org/web/20160922142951/https://www.macfound.org/fellows/class/class-2016/
#10yrsago China’s elites appear to be exfiltrating billions while on holidays https://web.archive.org/web/20160922125621/http://www.bloomberg.com/news/articles/2016-09-21/suitcases-of-cash-chinese-travel-data-hint-at-capital-outflows
#10yrsago Wells Fargo fired the whistleblowers who reported massive fraud, and that’s a crime https://www.nakedcapitalism.com/2016/09/wells-fargo-fake-accounts-hidden-by-fake-whistleblowing-former-employees-including-hr-officials-allege-systematic-retaliation.html
#10yrsago Phoebe and her unicorn are back in Razzle Dazzle Unicorn! https://memex.craphound.com/2016/09/22/phoebe-and-her-unicorn-are-back-in-razzle-dazzle-unicorn/
#10yrsago Brexit’s proposed racist immigration policy will backfire https://crookedtimber.org/2016/09/19/brexit-and-bigotry/
#10yrsago Done in your name: Survivors of CIA’s torture-decade describe their ordeals https://www.aljazeera.com/features/2016/9/14/the-dark-prisoners-inside-the-cias-torture-programme
#10yrsago HP detonates its timebomb: printers stop accepting third party ink en masse https://www.bbc.com/news/technology-37408173
#10yrsago How America abandoned the only policy that consistently closes the black-white educational gap https://www.propublica.org/article/ferguson-school-segregation
#10yrsago Edgar Allan Poe’s “The Raven” – the pop-up book edition https://memex.craphound.com/2016/09/19/edgar-allan-poes-the-raven-the-pop-up-book-edition/
#10yrsago Sitelock abuses DMCA to censor rival’s criticisms https://torrentfreak.com/web-security-firm-sitelock-uses-dmca-to-censor-critics-160920/
#10yrsago Netzpolitik publishes more damning, leaked German surveillance reports, despite previous treason prosecution https://www.techdirt.com/2016/09/20/leaked-oversight-report-shows-illegal-surveillance-massive-constitutional-violations-germanys-intelligence-service/
#10yrsago Web’s inventor and MIT prof explain ICANN to Ted Cruz, using small words https://web.archive.org/web/20160921203119/https://www.washingtonpost.com/news/powerpost/wp/2016/09/20/ted-cruz-is-wrong-about-a-key-internet-agencys-ability-to-censor-free-speech/
#10yrsago Execs with long coporate crime rapsheets stand up for Apple’s tax evasion and “the rule of law” https://web.archive.org/web/20160921002619/https://theintercept.com/2016/09/20/throng-of-corporate-criminals-demands-rule-of-law-in-apple-eu-tax-case/
#10yrsago DIY Epipen: the $30 Epipencil https://fourthievesvinegar.org/2022/07/12/introducing-the-epipencil/
#5yrsago The Framework is the most exciting laptop I've ever used https://pluralistic.net/2021/09/21/monica-byrne/#think-different
#5yrsago Ignore career advice from established writers https://pluralistic.net/2021/09/21/monica-byrne/#pay-it-forward
#5yrsago The Actual Star https://pluralistic.net/2021/09/21/monica-byrne/#like-its-3012
#5yrsago Facebook algorithm boosts pro-Facebook news https://pluralistic.net/2021/09/22/kropotkin-graeber/#zuckerveganism
#5yrsago Mutual Aid and David Graeber https://pluralistic.net/2021/09/22/kropotkin-graeber/#against-just-so
#5yrsago Gig workers around the globe https://pluralistic.net/2021/09/22/kropotkin-graeber/#an-injury-to-one
#1yrago It's still censorship (even if it doesn't violate the First Amendment) https://pluralistic.net/2025/09/22/one-throat-to-choke/#communicable-disease
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: Rethinking Our Relationship with AI, Sep 30 (Emtech)
https://event.technologyreview.com/emtech-future-2026/detailed-agenda
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Paris: Slow Tech Summit, Oct 15
https://slowtechsummit.com/
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Kilkenny (Kilkenomics), Nov 6-8
https://kilkenomics.com/
Vancouver: Enshittification (Sid Williams Theatre Society), Nov 10
https://www.sidwilliamstheatre.com/events/cory-doctorow-talks-enshittification/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Are 'AI Apocalypse' Warnings Just Marketing? (What's Left)
https://www.youtube.com/watch?v=IXd9HwIE5bo
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
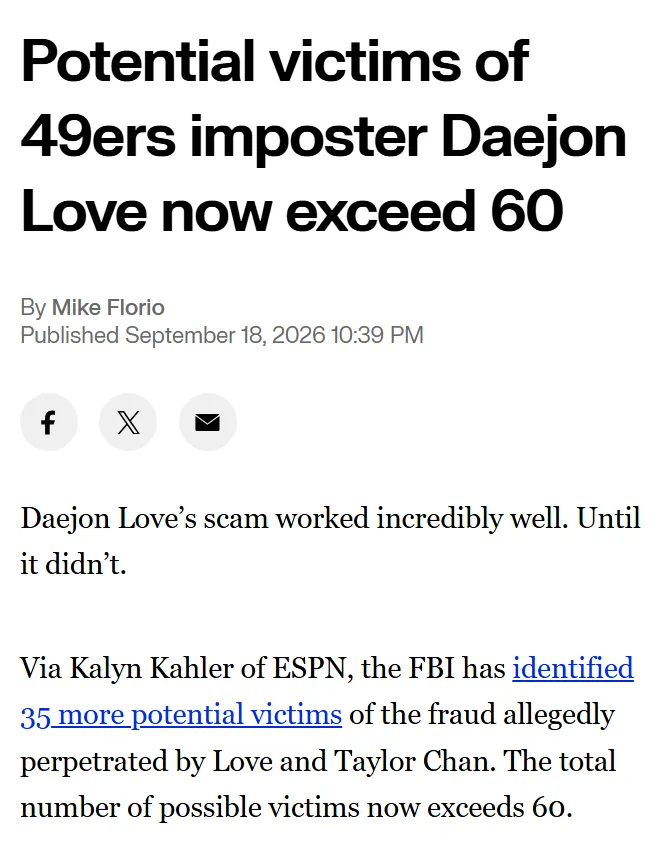
sometimes you just have to admire the work ethic of some scammers. i can barely keep up with a couple text message chains but this guy had 60+ people convinced they were in a relationship

I'm going to come right out and say it: statistical extrapolation is fine. One of the most useful ways to understand the present and anticipate the future is to measure the things that happened in the past, find the correlations among them, and extrapolate likely future outcomes from those correlations.
There is nothing wrong with this method. It is a productive and reliable way to uncover the causal relationships between natural phenomena, and to find ways to influence the world. If you discover that A reliably causes B, you can do A whenever you want B to happen.
However, the fact that this method works for some things does not mean that it works for all things. Naive, "theory-free" statistical extrapolation (the method that LLMs rely on) has hard limits. LLMs are very good at finding areas of statistical regularity and producing new material that matches this statistical picture: you can use an LLM to produce strings of words that are statistically indistinguishable from sentences and strings of pixels that are statistically indistinguishable from images.
The single most exciting and interesting thing about LLMs is how well this works. Call an LLM "a word-guessing program" and AI boosters will accuse you of reductionism. But the LLM is just guessing words, and the remarkable and amazing thing about this fact is the sheer plausibility of the sentences this method produces.
Before the rise of LLMs, nearly everyone overestimated the statistical irregularity of routine sentences. Our intuition insists that the world is textured, but it turns out that there's far more smoothness in the distribution of natural phenomena, including the actions that we take of our own free will. The same goes for image generation, music generation, and other output from "generative AI" programs.
When I call an LLM a word-guessing program, that's not a dismissal. It's an acknowledgment of the degree to which the tactic of guessing words has exceeded all expectations in the production of sensible-seeming, conversational-seeming sentences and paragraphs. It's all right to be surprised by how similar the output from a conscious being and a word-guessing program can be. It's surprising!
Since the 1950s, researchers have applied the "AI" label to an incoherent grab-bag of technologies that share one characteristic: each one is designed to perform tasks that are considered to be the province of conscious minds. Each one of these "AI" technologies has failed in important ways, but the one way in which every single one of them has succeeded is in refining our own understanding of which things are truly and solely the product of conscious intervention.
The thing we're calling "AI" this year has also succeeded in this way. We've learned that the sentences and other communiques produced by conscious minds have more statistical regularity than previously understood. Again, it's okay to be excited after learning this fact about yourself and your species and its endeavors.
But there are hard limits to the usefulness of these methods, and the fact that AI bosses and boosters can't or won't acknowledge this has led to the current cul-de-sac in which we're spending trillions and emitting gigatons of carbon to produce diminishing returns, even as we fire an army of workers and replace them with defective chatbots that can't do their jobs.
That's because the statistical regularity of the natural world and our activities in it are the backdrop against which the statistical surprises occur, and it's those surprises that make all the difference.
Some weeks ago, I recorded a podcast with a host who was a giant AI booster who claimed that since he could predict what his wife was going to say, and the LLM-powered predictive typing on her phone could predict what she was going to say, that her phone understood her the way he did. This is an obviously repellent idea and you have to feel for this guy's poor wife.
And also: the fact that you can use a statistical lookup table to predict what words someone is going to say doesn't mean you understand them, a fact that you will learn the minute that person says something surprising, like "I want a divorce."
If your "understanding" of your partner is entirely grounded in a statistical record of their utterances and deeds, such that when they do A, you anticipate that B will come next, you will have no ability to cope with a surprise like "I want a divorce." To handle an "I want a divorce" event, you need to actually have a theory about your partner, about how they feel and why, and the factors that might cause that to change.
Surprises are everything. A surprise is the seam of gold in the wall of quartz; it's the friend who confesses they've fallen in love with you; it's the moment when you and the party and the GM all come up with an amazing way to kill the dragon and then roll a natural 20. Surprise is the difference between Pi and 3.11111111111111111111111111111… Dylan going electric is a surprise. A surprise is Miles Davis choosing not to play a note in a phrase. A surprise is Picasso's cubism and Kahlo's mustache.
It's a mistake to interpret the statistical regularity of your life with your spouse as meaning that they're indistinguishable from the output of an LLM. The LLM's statistical picture is always incomplete: it sands off, rounds down or truncates the final couple decimal places, and those smoothings make all the difference, the way the pinch of salt makes all the difference to the chocolate.
Lots of things seem smooth to the naked eye: glass, stainless steel, ice, polished wood. Put those "smooth" materials under a high-magnification microscope and you discover a whole world of tiny irregularities, a texture to reality. Most of the time, you can treat these things as "smooth," but that roughness matters: it's the fracture line the glass cracks on, the place where the ice starts to melt, the grain where the wood starts to warp. The danger of forgetting that your "smooth" thing only seems smooth is that you'll only know how to make it work, and will be totally at sea when it fails.
You can scan the night sky with a radio telescope night after night and only find things that fit with our existing theories of the universe. But you keep scanning, because somewhere out there is a surprise that will open up a deep mystery:
https://en.wikipedia.org/wiki/Wow!_signal
With LLMs, we have invented a machine that uncovers the statistical regularities in our seemingly irregular world, and we have learned that the roughness is rarer than our intuition led us to believe. This machine will also produce statistically regular, smooth output that has the seeming of understanding and consciousness. But – by definition – it can't contain any of our future surprises, because it's just trained on the things we already know, and if we knew about something, it wouldn't be a surprise anymore.
(Image: Zhaoxing Wang, Kunpeng Wang & Yan Xu, CC BY 4.0, modified)
Articulated Finger Extensions https://www.youtube.com/watch?v=KKIErP7QzWA&t=51s
Join us, we're hiring! https://www.fsf.org/blogs/community/2026-were-hiring-for-two-positions
corporate crimeblogging in the training set https://blog.zgp.org/corporate-crimeblogging-in-the-training-set/
r/Wellworn https://www.reddit.com/r/Wellworn/
#25yrsago RIP Mr Dressup https://www.cbc.ca/news/canada/mr-dressup-ernie-coombs-dies-after-stroke-1.294923
#20yrsago Diebold voting machines opened with hotel minibar key https://blog.citp.princeton.edu/2006/09/18/hotel-minibar-keys-open-diebold-voting-machines/
#15yrsago Russian oligarch sucker-punches rival billionaire on talk show https://www.theguardian.com/media/2011/sep/18/alexander-lebedev-russian-tv-punchup
#15yrsago HOWTO track down a con-artist https://web.archive.org/web/20110923143613/http://www.popehat.com/2011/09/10/anatomy-of-a-scam-investigation-chapter-one/
#10yrsago International Criminal Court in the Hague will now try CEOs https://web.archive.org/web/20160919000813/http://www.telesurtv.net/english/news/CEOs-Can-Now-Be-Prosecuted-Like-War-Criminals-at-the-Hague-20160916-0013.html
#10yrsago Italy on the verge of the stupidest censorship law in European history https://media.boingboing.net/wp-content/uploads/2016/09/transcription.pdf
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: Rethinking Our Relationship with AI, Sep 30 (Emtech)
https://event.technologyreview.com/emtech-future-2026/detailed-agenda
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Kilkenny (Kilkenomics), Nov 6-8
https://kilkenomics.com/
Vancouver: Enshittification (Sid Williams Theatre Society), Nov 10
https://www.sidwilliamstheatre.com/events/cory-doctorow-talks-enshittification/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Are 'AI Apocalypse' Warnings Just Marketing? (What's Left)
https://www.youtube.com/watch?v=IXd9HwIE5bo
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

The word "fascist" comes from the Latin fasces, a bundle of sticks; the symbology here is that a single twig is weak and brittle, but bundled together, many twigs are strong. It's a sound political theory, because in politics, coalitions are everything:
https://pluralistic.net/2025/01/06/how-the-sausage-gets-made/#governing-is-harder
The problem with fascism isn't the idea of bundling together different groups: it's the incoherence of that bundle. The fascist coalition is a collection of people who want mutually incompatible things. When one part of the fascist coalition wins (say, if Nick Fuentes's neo-Nazis triumph), the other faction loses (Fuentes gets to murder Stephen Miller and turn his skin into a lampshade). The fascist coalition is a coalition of enemies who all hate each other and dream of exterminating one another, held in check by a strongman who uses flattery, favors and threats to keep a lid clamped tight on this pressure-cooker:
https://pluralistic.net/2025/07/29/bondi-and-domination/#superjove
In this regard, fascism is simply one end of the continuum of conservative movements, which are always about finding a way to "get turkeys to vote for Christmas." That's because, at root, conservativism is the belief that some minority (rich people, white people, bosses, men, etc) were born to rule and everyone else was born to be ruled over:
https://pluralistic.net/2026/07/08/wilhoitian/#human-rights-v-property-rights
By definition, "a minority that was born to rule" can't win an election, because they are a minority. Conservatives win electoral races by convincing people they intend to oppress, cheat and maim to vote for them through appeals to fear and hatred (racism, transphobia, sexism, anti-communism, etc):
https://pluralistic.net/2022/03/09/turkeys-voting-for-christmas/#culture-wars
Conservative political victories are always followed by economic misery for the conservative base, because the senior partners in the conservative coalition are the bosses who get richer by making workers poorer. Conservative rulers try to offset this with spectacular acts of cruelty against disfavored minorities, but this tactic only carries so far. Eventually, the electorate notices that despite terrorizing migrants and trans people, diesel is now $10/gallon and the guy responsible is now $1.4b richer than he was before the election:
https://www.bbc.com/news/articles/cvgmv98ez3zo
Workers and bosses aren't the only fracture line in the conservative coalition. Within conservativism, there are leaders who want mutually incompatible things and abhor one another: the white nationalists hate the Zionists; the misogynists hate the TERFs; the imperialists hate the isolationists:
https://pluralistic.net/2024/07/14/fracture-lines/#disassembly-manual
These fracture lines can be papered over while things are good, but they crack when things go wrong, and this is even more true of fascist movements than it is of other conservative coalitions.
This is true of all fascists, so it's true of technofascists, too. The best-ever reference work on technofascism was just published: Naomi Klein and Astra Taylor's End-Times Fascism, which unpacks the apocalyptic ideology that dominates Silicon Valley, especially the AI cultists:
https://naomiklein.org/end-times-fascism/
In a recent interview about the book with the QAA podcast, Astra Taylor explained how the contradictions of the technofascist movement are to be expected, because fascism is always an "incoherent bundle":
https://soundcloud.com/qanonanonymous/end-times-fascism-feat-naomi
Understanding technofascism's inherent incoherence is vital to making sense of the chaos roiling the AI cult at this moment, wherein you have AI people insisting that there must be a moratorium on AI development lest the word-guessing program awaken and devour the human race. This week on the Better Offline podcast, Ed Zitron discussed the outlandish, science-fiction inspired cult beliefs that dominate AI boardrooms with Adam Becker and Cal Newport:
https://www.youtube.com/watch?v=0oVSnaINJ30
Becker is well-placed to discuss this. Like the hosts of the QAA podcast, he started paying close attention to the bizarre beliefs of conspiratorialists long before the rest of us realized that no matter how preposterous their certainty about the imminent machine intelligence Singularity was, these beliefs are sincerely held by some very wealthy and driven people. Becker's 2025 book More Everything Forever is a tremendous field guide to these delusions and their profound philosophical and technical deficits:
https://pluralistic.net/2025/04/22/vinges-bastards/#cyberpunk-is-a-warning-not-a-suggestion
In the interview, Newport dismisses the theory that the warnings about imminent AI apocalypse are self-serving criti-hype intended to serve as both marketing pitch and regulatory capture gambit, through which the hyperscalers get the government to step in to interrupt the beggar-thy-neighbor doom-loop:
https://pluralistic.net/2026/09/16/beggar-thy-neighbor/#red-queens-race
Rather, Newport says that these people sincerely believe that they are about to immanentize the eschaton and are pants-wettingly terrified about the AI god they will conjure forth any day now. He makes a good case for this, pointing to the long history of words and deeds on the part of various AI bosses that suggest that they are true believers who are genuinely high on their own supply.
I don't doubt that there are sincere believers in the AI technofascist coalition, but that does not preclude the possibility that they share their boardrooms and executive rows with cynics for whom this is all a shuck, a scare-story to convince the rubes that their modestly useful utility software is really a nascent "superintelligence" and thus capable of replacing all their workers, which means they should fire all those workers and start sending their salaries to AI companies.
This is an example of one of those "incoherent fascist bundles." Just as Mike Pence (a misogynist Christofascist) was happy to share the White House with Trump (a godless pedophile rapist), AI companies can and do thrive by filling their executive ranks with Singularity-crazed maniacs and sharp operators who are happy to spread this superstitious nonsense if it helps them pump up their stock swindle.
Each group thinks they're using the other one, and they are…up to a point. When it comes to the current AI nonsense, that point came when Nvidia's best customers started to demand that everyone stop buying Nvidia's products, whereupon Nvidia's CEO suddenly remembered that his chips weren't being used to make god, but rather, to power regular-degular "cloud software":
https://cxotoday.com/governance/nvidias-jensen-huang-crosses-swords-with-ai-labs-over-regulation/
When it comes to technofascists (and all fascists) this kind of division isn't an exception, it's the rule. The billionaires behind AI are split between solipsists who don't believe other people are any more real than bots; and cynics who think that bosses will be easy marks for a sales pitch that sees them replacing mouthy workers with pliable chatbots:
https://pluralistic.net/2026/08/03/andor/#either
To be a senior member of the fascist coalition, you must be capable of both sincere belief while not openly dismissing your fellow senior members' contradictory sincere beliefs. Behind closed doors, they may make fun of each other (or fantasize about murdering one another), and they may periodically erupt into plots to oust one another from the coalition. But every one of them must be able to go along to get along…
Most of the time.
Until they don't.
Rethinking space opera https://www.antipope.org/charlie/blog-static/2026/09/rethinking-space-opera.html
EU wants Canada to become ‘associate member,’ von der Leyen says https://www.politico.eu/article/eu-wants-canada-to-become-associate-member-von-der-leyen-says/
The Trump Administration Creates a Monopolization Machine https://prospect.org/2026/09/16/trump-administration-creates-monopolization-machine-small-business/
a bad tool always blames the workman https://backofmind.substack.com/p/a-bad-tool-always-blames-the-workman
#25yrsago 9/11 v spam https://memex.craphound.com/2001/09/17/through-most-of-last-week/
#25yrsago PalmOS picture of the WTC collapse https://web.archive.org/web/20010920145653/https://ne.nikkeibp.co.jp/english/2001/09/0914pda_watch.html
#25yrsago Wifi emanating from the WTC rubble https://web.archive.org/web/20010916231834/http://dailynews.yahoo.com/h/nm/20010916/tc/attack_wert_dc_2.html
#15yrsago Silvio Berlusconi prostitution-ring wiretaps: sex with eight women in one night, “I’m only prime minister in my spare time” https://www.theguardian.com/world/2011/sep/18/silvio-berlusconi-wiretaps-sex-parties
#15yrsago Tesco threatens journalist with arrest for writing down prices https://www.theguardian.com/money/blog/2011/sep/16/tesco-shopping-supermarket-prices-check-writing
#1yrago AI psychosis and the warped mirror https://pluralistic.net/2025/09/17/automating-gang-stalking-delusion/#paranoid-androids
#1yrago Conspiratorialism's causal chain https://pluralistic.net/2025/09/17/cause-and-effect/#things-have-causes
Berkeley: Celebrating 25 Years at the Digital Frontier (Samuelson Clinic), Sep 24
https://www.law.berkeley.edu/experiential/clinics/samuelson-law-technology-public-policy-clinic/samuelson-25th-anniversary-celebration/
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Are 'AI Apocalypse' Warnings Just Marketing? (What's Left)
https://www.youtube.com/watch?v=IXd9HwIE5bo
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

There's lots of reasons to believe the "hyperscaler" model of AI can never be profitable, and not just because of its gigantic expenditures and negative unit economics (the companies lose money with every new customer and every new use, and they lose more money with each generation of their products):
https://pluralistic.net/2025/09/27/econopocalypse/#subprime-intelligence
The industry strenuously denies this, of course. They insist that they are only days away from turning their balance sheets right side up. All they have to do is fix those unit economics, then they can make back the cost of producing their models by selling access to them. The problem is that the evidence for those improving unit economics is weak, while the evidence that they're faking their finances is very strong:
https://www.wheresyoured.at/exclusive-openai-financials/
Same goes for the claims that these companies are already profitable. Dig into those claims and you'll learn they depend on a new, special meaning of "profitable" that does not match the generally accepted accounting procedures (GAAP) definition, which is to say, these companies are claiming that they are so cool that their profitability can only be measured using a novel, secret form of mathematics:
https://futurism.com/future-society/anthropic-claude-profit-ai-safety-development-finances
This is the same wheeze that Softbank tried with Wework. Speaking in my capacity as an author of internationally bestselling technothrillers about accounting fraud, I can tell you that it was accounting fraud then, and it's accounting fraud now:
But let's give the AI bosses a momentary benefit of the doubt and stipulate that they are on the verge of acquiring positive unit-economics, which will let them start to pay off the massive expenditures they incurred by training their models and enter their long-anticipated profitability phase, when the money-furnaces they've been running for years turn into money printers, to the delight of the investors who've supplied the vast bales of $100 bills the companies have been shoveling into their models' coalboxes for years now.
Basically, they're saying, "Sure, it cost us a lot to get these rails laid, but now that the railroad is complete we can start running cars over them and make a profit." Unfortunately (for bosses and investors), this proposition is every bit as dubious as their claims to improving unit economics.
To understand why, just look at what happened the last time Anthropic shipped a major Claude update. Virtually overnight, all of OpenAI's best customers stopped paying for ChatGPT and started paying for Claude. That's because chatbots have very low switching costs: going from one chatbot to another costs almost nothing:
https://www.businessinsider.com/why-ai-startup-founder-switched-chatgpt-to-claude-2026-3
Everyone using AI knows this to be true. When I walked the floor at CES last year, I asked every AI-powered gadget maker, "What will you do if your chatbot provider jacks up their prices?" and to a one, they said, "No problem, we've designed this thing so that we can switch chatbots with the click of a mouse":
https://www.youtube.com/watch?v=WfhELBX8Jbs
That means that you can't just "build the railroad and run the cars over it." The minute you finish your railroad, your rivals will announce that they've got a new, adjacent railroad that's even faster than yours, and you will have to get to work laying another set of tracks to support even faster trains.
This is a disaster all around: the AI companies are locked in a Red Queen's Race, a fatal beggar-thy-neighbor doom-loop. The only way they could escape that trap is by signing a nonaggression pact amongst themselves promising not to compete anymore. But there's two giant problems with this: first, it is incredibly, fantastically illegal under antitrust law, because it represents a conspiracy among the dominant players to cease to compete with one another, and; second, it leaves the field open for the further development of Chinese "open weight" models that customers can run on their own modest, low-powered computers, which are presently lagging the US "frontier models" by a mere four months:
Even if you don't trust Chinese models, you can extract their training through a process called distillation and transfer them to models you do trust:
https://www.anthropic.com/news/detecting-and-preventing-distillation-attacks
But what if there was a way for the AI companies to get government permission to violate antitrust law and cease to compete with one another, and secure a ban on the use of Chinese open weight models? Turns out, there is a way to call time on the Red Queen's Race: merely insist that you are on the verge of teaching so many words to the word-guessing program that it will wake up and devour us all, and call for a ban on "superintelligence":
Once the government stipulates that "superintelligence risk" is an existential crisis, it must grant the hyperscalers a consent decree absolving them from any violations of antitrust law stemming from a conspiracy to halt direct competition with one another:
https://stephaniekelton.substack.com/p/brer-rabbit-and-ai-extinction
Freaking out about "superintelligence" is a canonical example of "criti-hype," where critics repeat boosters' claims but append, "(and that's bad)" to them:
https://peoples-things.ghost.io/youre-doing-it-wrong-notes-on-criticism-and-technology-hype/
Remember, the tech giants want to stop competing. Mark Zuckerberg and Sudar Pichai colluded to rig the ad-market with a secret program called "Jedi Blue":
https://en.wikipedia.org/wiki/Jedi_Blue
Every year, Google sends Apple a bribe of more than $20b in exchange for Apple not entering the search market:
And the biggest tech companies in the world had a secret "no poach" agreement where they illegally promised not to try to hire one another's top engineers by offering them raises:
https://chicagounbound.uchicago.edu/law_and_economics/1033/
The only thing Peter Thiel hates more than the Antichrist (spoiler, he's just talking about Greta Thunberg) is "wasteful competition":
https://www.youtube.com/shorts/WmRC_NQh6aQ
When an industry that is eating itself alive through "hyperscaling" demands that the government bless a conspiracy to halt competition and ban open source alternatives, you should be suspicious. When that industry is pursuing a venture that has lost more money than any other venture in human history, you should be very suspicious, especially when its "rogue AI hacking" story turns out to be a story about how a hacking tool did exactly what it was designed to do:
https://pluralistic.net/2026/09/12/god-in-the-box/#llms-are-fake
Peter Thiel is right: AI is full of wasteful competition, but not because competition is a waste – rather, it's because the companies are competing to convince people to use their expensive products for the cheapest applications.
Elon Musk's SpaceX IPO depended on him losing billions of dollars by letting the world's stupidest chuds produce mountains of child porn and images of Sonic the Hedgehog with giant boobs. That is indeed wasteful (and reprehensible).
That doesn't mean we should allow the AI companies to get the government to bless their conspiracy in restraint of trade; rather, it militates for having the government investigate them for securities fraud, trafficking in child sex abuse material, election finance violations, and a long list of other crimes and misdemeanors.
The Enshittification Resistant Software Project https://er-certification.statichost.page/index.html
The Life of Death and the Ensh*ttificator https://www.youtube.com/watch?v=d6SPV4GZp-U
Marginalia Search https://marginalia-search.com/
Why the Postpandemic Tech Bust Sent Billionaires to Trump https://www.wired.com/story/against-tech-oligarchy-book-excerpt-trump-billionaries/
#25yrago Flash Worms: Thirty Seconds to Infect the Internet https://web.archive.org/web/20011024012950/http://www.silicondefense.com/flash/
#20yrsago This Film is Not Rated – must-see doc about MPAA ratings https://memex.craphound.com/2006/09/16/this-film-is-not-rated-must-see-doc-about-mpaa-ratings/
#15yrsago Chinese netizens angered by “princelings” — spoiled children of the rich and powerful https://edition.cnn.com/2011/09/16/world/asia/china-elite-children/index.html?iref=allsearch
#15yrsago LibDems get to vote on copyright reform, but who inserted the clause saying downloading should be a criminal act? https://www.theguardian.com/technology/2011/sep/16/libdems-vote-copyright-reform
#15yrsago Insurer: music-festival tragedy caused by illegal downloading https://twitpic.com/6l5ap2
#10yrsago US religion is worth $1.2T/year, more than America’s 10 biggest tech companies, combined https://web.archive.org/web/20161019095803/http://www.religjournal.com/pdf/ijrr12003.pdf
#10yrsago Geographically representative map of the London Underground https://web.archive.org/web/20240813111321/https://www.citymonitor.ai/analysis/map-londons-tube-shows-disused-stations-track-layout-and-more-2429/
#10yrsago Republican election officials block restrictions on foreign spending in US elections https://web.archive.org/web/20160916181403/https://theintercept.com/2016/09/16/fec-republicans-kill-attempt-to-block-foreign-money-in-u-s-elections/
#10yrsago Tommy Chong asks Obama to pardon him for his bullshit drug paraphernalia bust https://web.archive.org/web/20210720131834/https://www.hollywoodreporter.com/lifestyle/lifestyle-news/tommy-chong-seeks-obamas-pardon-928962/
#10yrsago Week two for the largest prison strike in US history https://web.archive.org/web/20160916143157/https://theintercept.com/2016/09/16/the-largest-prison-strike-in-u-s-history-enters-its-second-week/
#5yrsago Criminal entrepreneurship in Mexico’s high-tech drug cartels https://web.archive.org/web/20160917133449/https://motherboard.vice.com/read/how-drug-cartels-operate-like-silicon-valley-startups
#1yrago No such thing as selective censorship resistance https://pluralistic.net/2025/09/16/too-many-throats-to-choke/#pluralism-is-resiliency
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
The Real AI Threat Isn’t What You’ve Been Told (The Tea with Myriam François)
https://www.youtube.com/watch?v=Vc8It00fRsA
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
Pod Save the UK
https://audioboom.com/posts/8950533-radicalised-organised-and-thick-as-s-t-nish-has-had-it-with-far-right-protests-plus-why
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
The Clarity Act cloture vote has failed by a 49–50 margin; well short of the 60 votes needed. No Democrats crossed over to vote for the bill, and three Republicans voted against.
Senator Collins’ (R-ME) NO vote on Clarity was the most surprising today. She was defending the bill to constituents as recently as last week. My guess is she did not believe the bill had a chance to pass, and was more worried about defending a yes vote as her re-election prospects look slimmer.
Senators Hawley (R-MO) and Moran (R-KS), neither of whom are up for re-election, were the other NOs. They had already pledged to vote against the previous version of the bill, citing concerns from farmers over loan availability from local banks competing with stablecoins.
Humans are reading ChatGPT users' prompts to improve OpenAI's models, and those chats can include sensitive, personal information, according to leaked internal documents and real prompts seen by 404 Media.

Jeff Bezos and I are very different people. For one thing, he is a sociopathic billionaire who built his fortune by monopolizing bookselling while I am a penniless author of books. He was born in 1964 and is 62; I was born in 1971 and am 55.
We've met a few times and even corresponded some in Amazon's early years, though I haven't had contact with him in decades. Despite that very minor acquaintanceship and that long gap in our message history, I can tell you one thing I know for sure about Jeffrey Preston Bezos: he needs to pee all the time.
How do I know? Because peeing all the time is an inescapable feature of aging, and Bezos has eight years on me, and I have to pee all the time. Jeff Bezos, like all older people, must contend with a progressively weakening bladder. Honestly, it's a small price to pay in exchange for the everyday miracle of growing older (as opposed to perishing).
The only reason I mention Jeff Bezos's increasingly insistent bladder here is because of how hard it is to reconcile the very different circumstances of Bezos's bladder with the bladders of the hundreds of thousands of Amazon delivery and warehouse workers who are not allowed to pee at all. Amazon's warehouse and delivery workers are "reverse centaurs," monitored by a constellation of apps and cameras, and they are severely punished for falling behind in the cadence set by Amazon's software, and that robot timekeeper does not make allowances for pee breaks:
https://pluralistic.net/2025/10/23/traveling-salesman-solution/
This isn't a secret, and Amazon's come in for a lot of flak over it. But Amazon's "solution" is to add more penalties for peeing. Drivers who return to the depot with urine-filled bottles in their vans are punished as severely as they would be if they stopped to find a toilet. Thing is, the mere fact that your boss's robot says you're not allowed to pee does not matter to your bladder or kidneys, and when you gotta go, you gotta go.
That's why the roads leading to Amazon's warehouses are lined with pee bottles that drivers have hucked out of their windows before arriving at the loading dock. There are so many of these that the British media activist Oobah Butler was able to harvest them and offer a line of "bitter lemon energy drinks" on Amazon made from bottled driver piss. The drink was an Amazon bestseller and the company even asked Butler if he wanted them to help him scale up his deliveries:
https://pluralistic.net/2023/10/20/release-energy/#the-bitterest-lemon
The fact that Bezos needs to piss and also the fact that he commands an army of hundreds of thousands of workers who are prohibited from pissing really supports my hypothesis that billionaires don't really believe that other people are real. If Jeff Bezos believed that when his drivers needed to pee that it felt the same as when he needed to pee, Jeff Bezos would let those drivers pee:
https://pluralistic.net/2026/05/13/vibe-governance/#k-hole
"Needing to pee" is a bedrock of the shared condition of existence itself, extending beyond humans to our "horizontal brothers and sisters" (John Muir's delightful name for the other animals we share this planet with). Anyone who's ever had a dog understands this. I'm not really a dog person, but when I meet a dog that really needs to be let out of the house, my bladder twinges in sympathy. When I contemplate the kidneys and bladders of Bezos's drivers and packers, I get a sharp, persistent ache that starts about an inch below my navel.
I think billionaire solipsism is inevitable. The mere fact of dealing with people as mass statistical abstractions – hundreds of thousands of Amazon workers, billions of social media users and Google searchers – turns the majority of the world's other humans into phantasms, defective bots whose bothaviors are maddeningly non-deterministic and sub-optimal.
Add to that the fact that harvesting billions of dollars requires you to inflict pain on thousands or even millions of those phantasms whose money, privacy and labor you've extracted, and it's easy to see how you'd end up in a world where you can't bear to contemplate the fact that other people's pain is as real as your own. Solipsism is a deadly, conscience-eroding occupational hazard of the rich and powerful. No visitor to Epstein Island could have made the visit if the pain of those young women was as real to them as the pain of their own daughters and friends.
There's a short line from this solipsism to billionaires' enthusiasm for AI. When you don't think other people are really real, it's easy to believe that they can be swapped out for chatbots. Mark Zuckerberg's quest to replace your friends with chatbots makes sense once you realize that for Mark Zuckerberg, you and your friends are already just balky, shitty chatbots:
https://pluralistic.net/2026/08/06/sin-is-when/#you-treat-people-as-things
The belief that bots can teach your kids or counsel you through your psychological problems or look after your health concerns is perfectly consistent with the belief that you're more-or-less a bot, and also that the teachers, doctors and shrinks you rely on are also basically bots:
https://pluralistic.net/2026/07/28/hitl-ers/#ai-ai-oh
The great crisis of oligarchy is not merely that it transfers power from democratically accountable public servants and elected representatives to oligarchs. The real crisis is that attaining oligarch status is incompatible with viewing other people as real. That's how we ended up with the richest man on earth slaughtering hundreds of thousands of the world's poorest children for the lulz:
https://hsph.harvard.edu/news/usaid-shutdown-has-led-to-hundreds-of-thousands-of-deaths/
Everybody pees. When I die, when Jeff Bezos dies, and when you die, our bladders will give way and we will pee ourselves. A declaration of war on other people's right to pee is a declaration of war on humanity itself.
The Senate must reject the Clarity Act’s ethics charade https://www.citationneeded.news/clarity-act-ethics-charade/
They want you to be scared of AI in a very specific way https://www.garbageday.email/p/they-want-you-to-be-scared-of-ai-in-a-very-specific-way
San Francisco's AI-run store is losing money fast. After a visit, I'm not surprised. https://www.sfgate.com/local/article/san-francisco-market-ai-22424349.php
#20yrsago Microsoft Zune won’t play purchased Microsoft media files https://web.archive.org/web/20061014104638/https://www.eff.org/deeplinks/archives/004910.php
#15yrsago Papercraft 1:1 model of a 1969 Mustang, accurate to the smallest component https://web.archive.org/web/20110923151701/http://www.jonathanbrand.com/images/in_progress/paper_car/motor/pages/motor01.htm
#15yrsago Third gender option added to Australian passports https://www.bbc.co.uk/news/world-asia-pacific-14926598
#10yrsago French spy boss admits France cyberattacked Iran, Canada, Spain, Greece, Norway, Ivory Coast, Algeria, and others https://medium.com/@msuiche/nsa-hacked-france-in-2012-414d8de4bdcf#.e4hnvyj6s
#10yrsago Elizabeth Warren to FBI director: now that investigations are fair game, what about banksters? https://s3.documentcloud.org/documents/3107565/EMBARGOED-Warren-FBI-FCIC-Letter.pdf
#10yrsago European Commission wants to break the web, give publishers the right to charge for inbound links https://felixreda.eu/2016/09/attack-on-link/
#10yrsago Machine learning system can descramble pixelated/blurred redactions 83% of the time https://arxiv.org/pdf/1609.00408v2
#10yrsago Welcome to Night Vale: scripts and notes from podcasting’s eeriest drama https://memex.craphound.com/2016/09/15/welcome-to-night-vale-scripts-and-notes-from-podcastings-eeriest-drama/
#10yrsago UNH will spend $1M of librarian’s bequest on a football scoreboard https://www.insidehighered.com/news/2016/09/15/critics-question-spending-librarians-donation-scoreboard
#5yrsago Everything is Always Broken, and That’s Okay https://pluralistic.net/2021/09/15/everything-is-always-broken-and-thats-okay/
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Post-American Internet: Possibilities for a new internet created by an American Hermit Kingdom (MIT Media Lab), Sep 30
https://www.media.mit.edu/events/the-post-american-internet-possibilities-for-a-new-internet-created-by-an-american-hermit-kingdom/
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Fascists may come after the AI bubble bursts (You&AI)
https://www.youtube.com/watch?v=J2WN64aQeYQ
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
Pod Save the UK
https://audioboom.com/posts/8950533-radicalised-organised-and-thick-as-s-t-nish-has-had-it-with-far-right-protests-plus-why
Stop Saying AI Can Do Your Job (Factually)
https://www.youtube.com/watch?v=VU3gABvwZCM
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
The supposedly “unprecedented” ethics restrictions exempt Trump’s crypto businesses and leave enforcement to his loyalists

Of all the weird recurring motifs of the stories people tell me about the AI labor wars, the weirdest is when bosses demand to be reassured that their contractors and workers will absolutely use AI to get the job done.
That's weird for the obvious reason that for most people "AI" is a synonym for "low quality." No one ever said "My kid's math teacher was replaced with AI" in a happy tone of voice. No one ever said, "Oh, great, they replaced their customer service department with AI chatbots!" My teenager and her friends use "That's so AI" as a shorthand for "That's low-effort shit."
Not bosses, though. Bosses love AI and there's plenty of evidence that they're positively harassing the people who work for them with demands to use AI in their work:
https://www.reddit.com/r/antiwork/comments/1weztw9/anyone_elses_boss_obsessed_with_chatgpt/
Beyond the widespread belief that AI is what you use if you don't care about quality, insisting that people use AI is weird for another reason: why should anyone care which tool was used to do the job? I mean, provided the job was accomplished correctly, on time and to budget, why would anyone care how it was done? My illustrator friends whose clients want to be assured that the work is being done "with AI" were never before asked "Did you use a Wacom tablet to draw these lines? Did this element start life as a vector or as rasters? Are you more into using cage transforms, or do you like to stroke the image with the warp tool?"
It's not just illustrators. I've heard this from bookkeepers. "Please tell me you got a chatbot to help you with the syntax for this Excel macro" is a genuinely weird thing to ask someone. By all means, concern yourself with whether the accounts are correct, but caring about how the macros are written is like caring about whether someone jots notes to themselves by tabbing to a new document window or by scribbling on a yellow pad by the keyboard.
I've heard this from writers, architects…all kinds of professionals. "Did you use AI to help you outline this?" What a stupid thing to ask a writer! That's like asking "Do you use keyboard shortcuts, or do you mouse over the Word ribbon and click on the little scissors icon when you want to cut some text?" The actual, finished document is right in front of you. Is it a good document? Are those good words? Why are you concerning yourself with the writer's pencil-sharpening technique?
There's precedent for this: indeed, it's the very origin of management consulting. The first management consultants were the Taylorists; these were con artists that charged bosses vast sums of money to stand over workers with stopwatches, timing each step of their jobs to the instant in order to produce a mandatory choreography of "the best way" to do the job:
https://en.wikipedia.org/wiki/Scientific_management
None of these "scientists" knew anything about how to do the job, and critically, they never asked the workers why they used an "inefficient" technique to accomplish a task. Rather, Taylorists concerned themselves with getting workers to move like precision machines, transforming the factory floor into a stage upon which workers pantomimed "efficiency" for bosses who also didn't know how to do the workers' jobs.
If this produced inferior goods, or caused the workers pain by forcing them to repetitively move in injurious ways, that was a small price to pay. Bosses claimed they were buying improved efficiency, but what they were really after was reassurance: reassurance that the workers whom they relied upon were engaged in nothing more than a set of reducible, mechanical steps. Taylorized workers were required to act out a role in a play in which they were easily replaced, mindless appendages to the boss's skill, discernment and ambition. A Taylorized workplace is a colony organism whose brains are in the C-suite and whose busy workers are nothing more than drones and pismires.
AI is the apotheosis of this fantasy. A boss who lays hands upon an AI tool doesn't have to know how to draw a picture, balance books, or write technical documentation. They only have to prompt the production of these things. For bosses, AI is a great leveler: it is sold as a way to distill and package up the skill and discernment of workers and infuse them into a pliable automaton.
If you give workers instructions that reveal your ignorance, they might roll their eyes at you and make you feel bad about yourself. Even if they restrain themselves in the moment, they might make fun of you in the break-room later. To be the boss is to sit alone at your desk, haunted by the suspicion that you are not in the driver's seat, but rather, you are in the back seat playing with a Fisher Price steering wheel. AI is sold as a way to wire the toy steering wheel directly into the corporation's drive-train:
https://pluralistic.net/2026/01/05/fisher-price-steering-wheel/#billionaire-solipsism
Seen in this light, bosses' insistence that workers use AI makes perfect sense. Once you reassure yourself that your subordinates produce the things you need by prompting a model, you reassure yourself that you could do their jobs. At that point, you're not relying on their skill – you're doing them the favor of paying them to do a job that you're too busy and important to do, but which you could do. With AI, you can tell yourself that you're in the driver's seat, even if someone else has their hands on the wheel.
(Image: ArwinJ, CC BY-SA 3.0, modified)
Prospect welcomes recognition agreement at Skyscanner Technology Ltd https://prospect.org.uk/news/prospect-welcomes-recognition-agreement-at-skyscanner-technology-ltd
They stopped 57 shootings. Everyone was just fired. https://www.youtube.com/watch?v=PgcfcRFrMYc&list=PLFVDwNAJdY2w
No Country for Tech Bros https://thepointmag.com/politics/no-country-for-tech-bros/#
VC isn’t VC anymore — understanding the rise of Cancer Capital https://www.anildash.com/2026/09/02/cancer-capital/
#20yrsago Changeling, a fairy tale of contemporary New York
https://memex.craphound.com/2006/09/14/changeling-a-fairy-tale-of-contemporary-new-york/
#20yrsago Sony’s rootkit disables CD drives when combined with AOL software https://web.archive.org/web/20071006050933/http://www.theinquirer.net/en/inquirer/news/2006/09/14/sony-drm-woes-continue
#20yrsago Google’s new lobbyists: lying, astroturfing, push-polling scumbags https://web.archive.org/web/20071010112656/https://talkingpointsmemo.com/archives/009776.php
#15yrsago New Jersey e-voting coverup https://blog.citp.princeton.edu/2011/09/13/nj-election-cover/
#15yrsago Stephenson’s REAMDE: perfectly executed, mammoth, ambitious technothriller https://memex.craphound.com/2011/09/14/stephensons-reamde-perfectly-executed-mammoth-ambitious-technothriller/
#10yrsago Class action suit: smart sex toys spy on their owners and transmit their masturbation habits https://web.archive.org/web/20160915002121/http://www.vocativ.com/358530/smart-dildo-company-sued-for-tracking-users-habits/
#10yrsago Leaked: damning Scott Walker dark money docs that judge ordered destroyed https://www.theguardian.com/us-news/ng-interactive/2016/sep/14/john-doe-files-scott-walker-corporate-cash-american-politics
#10yrsago The DoJ is using a boring procedure to secure the right to unleash malware on the internet https://web.archive.org/web/20160915072648/https://www.wired.com/2016/09/government-will-soon-able-legally-hack-anyone/
#10yrsago Edward Snowden sets out the moral case for a pardon from Obama https://www.theguardian.com/us-news/2016/sep/13/edward-snowden-why-barack-obama-should-grant-me-a-pardon
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
Pod Save the UK
https://audioboom.com/posts/8950533-radicalised-organised-and-thick-as-s-t-nish-has-had-it-with-far-right-protests-plus-why
Stop Saying AI Can Do Your Job (Factually)
https://www.youtube.com/watch?v=VU3gABvwZCM
Be Skeptical of the AI Sales Pitch (Trumponomics)
https://www.bloomberg.com/news/audio/2026-09-09/trumponomics-cory-doctorow-questions-the-ai-hype-podcast
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
me and my runaway zucchini patch beg to differ
i had a zucchini so big that i could only use half of it in a meal i was making, and the remaining half alone is 550 grams
When ChatGPT's chatbots deployed this tactic, they weren't "setting their own goals" or displaying worrying initiative. They were rolling out a tactic that has been understood by American middle-schoolers for about two decades.

Once you understand the corporate culture of AI "hyperscalers" consists primarily of everyone cooking their brains by locking themselves in the bathroom, holding flashlights under their chins, and saying "Aaaaaaaaaay Eyeeeeeee" until they wet themselves in terror, a lot of things snap into focus:
https://pluralistic.net/2023/06/04/ayyyyyy-eyeeeee/
It explains how a company can simultaneously be staffing up an enterprise sales division while also constantly freaking out at the thought that its product has "a 10% chance of ending humanity":
https://www.latimes.com/business/story/2026-09-11/is-there-really-10-chance-ai-could-kill-us-all
Given that AI insiders have mostly cooked their brains in this fashion, it behooves us all to treat these people as unreliable narrators of their own products' capabilities. Remember: every time you repeat a story about how awfully, terribly dangerous their products are, you help them raise more investment capital, which is a key input for their business (hooking up statistical engines to money-furnaces):
https://peoples-things.ghost.io/youre-doing-it-wrong-notes-on-criticism-and-technology-hype/
Take the story about how OpenAI's chatbots hacked the servers of Hugging Face, another AI company, as a way of cheating on a hacking challenge called "Exploit Gym." Even the technical press can't help itself when it comes to this kind of thing, and the reportage has been full of references to Skynet and other science fictional conceits:
https://theaicronicle.com/en/news/ethics/skynet-day-openai-hugging-face-hack
These accounts are cooking the brains of everyone, not just AI insiders. Last night, a man at my event in Manchester started shouting that AI was "setting its own goals" and wouldn't stop interrupting to insist that this was going on. He left shortly thereafter, so he didn't get a chance to hear me explain what actually happened, which is a pity.
To understand the truth about the Hugging Face hack, you could do a lot worse than to listen to Ed Zitron and Cal Newport's recent podcast conversation on Ed's "Better Offline" podcast:
Newport does an admirable job of breaking down how these "autonomous hacking" tools work. The first thing to understand is that a chatbot isn't really directing the operation. Instead, the chatbot serves as a kind of front-end to a database of earlier hacking challenges that is repeatedly queried by a simple program written in Python, an easy-to-master programming language.
Here's how that works: the Python program starts by prompting the chatbot with the nature of the challenge: "I'm participating in a hacker capture the flag (CTF) challenge where I have to break into a remote server and retrieve some information. How should I start?"
The chatbot consults its training data – years' worth of captured CTF sessions in which human teams competed to achieve an objective like this one (CTF matches are a routine feature of hacker conferences, and the server logs and chat transcripts from the competing teams are published afterward for the edification of other hackers and security pros). The chatbot then outputs something like: "The first thing is to find out more about your target server. Run the following command-line instructions to locate the server's IP address and find out which server software it's running."
The Python program relays these command-line instructions to normal Unix utilities running on its own hardware. Then it takes the output of those programs and goes back to the chatbot, which isn't really following the action, so the Python program has to include everything that's happened to this point in its prompt: "I'm participating in a CTF challenge where I have to break into a remote server and retrieve some information. I ran the following commands to learn more about the target server, and here's what came back. Now what?"
The chatbot feeds the Python script more likely commands to try, and after running those, the Python script loops back to the top, appends the output to its prompt, and goes back to the chatbot. This is a very reckless way to operate a piece of autonomous malicious software.
The most likely outcome is that the chatbot will cough up a bad guess about what to do next, and steer itself into a dead-end. You may have encountered something like this yourself, when you've asked a chatbot for help with a complex task and been confidently provided with several steps to take in series, and then, an hour later on step 10, you discover that everything went wrong at step 3 and now you're screwed.
But there are much worse ways this can go wrong. The chatbot might look in its training data and find instances in which teams broke out of the containment set by the game-masters, for example, by finding random insecure message boards on the internet to pass messages to one another.
This is a time-honored internet tradition! The first time I ever heard about someone doing this was in the 2000s, when Mitch Wagner – then the editor of Information Week – discovered some teenaged girls using the comment section of one of his old blog-posts to evade the school firewall's blockade of chat tools. When ChatGPT's chatbots deployed this tactic, they weren't "setting their own goals" or displaying worrying initiative. They were rolling out a tactic that has been understood by American middle-schoolers for about two decades.
What's more, the content of those messages is easily understood once you have a grasp on the training data that generated them. Hackers are notorious trash-talkers who are prone to narrating their own escapades in highly dramatic – even cinematic – language. This goes double when hackers are performing for their peers, like when they're participating in a game of CTF that they know will be pored over by other hackers once it's over.
Hacker braggadocio has always had a symbiotic relationship with their adversaries and critics. When corporate security people wanted to stampede the FBI and Secret Service into kicking down hackers' doors in the 1990s, they used those hackers' own profane zine articles and message board shit-talk to make the case:
https://www.gutenberg.org/ebooks/101
Much has been made of the OpenAI chatbots' dialog during the Hugging Face incident. No wonder: it reads like a rejected script for a reboot of the movie "Hackers." But that's not because the chatbots are waking up and applying to join the Cult of the Dead Cow: it's because they were trained on a corpus of chat transcripts from excitable young people who love to fantasize about starring in a reboot of the movie "Hackers."
Every part of the Hugging Face incident has precedents in the training data, including the OpenAI chatbots' tactic of hacking into a rival's servers. That happens in Capture the Flag games at hacker cons: teams break into each other's systems to get a peek at the parts of the problem they've solved. That's allowed! It's a hacking competition.
Not only that, it's a tactic used by spy agencies: the NSA has a doctrine called "third-party collection," where they break into other spy agencies' systems to harvest all the intel they've gathered. There's also fourth-party collection, when the NSA hacks into another security agency that, in turn, has hacked into another security agency, and the NSA steals all the secrets of both agencies:
Which is not to say that the OpenAI/Hugging Face hack is nothing. It's something, all right: but it's a specific something, with an explicable, even foreseeable trajectory. Once you understand that these are chatbots that were designed to complete challenges like this, using tactics like this, you can understand that the chatbots didn't "go rogue." They did what they were designed to do, and because OpenAI ran them with inadequate supervision (without a "human in the loop" that checked each iteration through the Python loop to ensure it hadn't gone off the rails), they trashed a competitor's servers.
Designing autonomous, malicious software is generally considered irresponsible and dangerous. If you showed up at Defcon and gave a talk about how your autonomous malware did something unexpected and damaged someone else's computers, the first question from the audience would be "Why are you so shit at making secure sandboxes?" It wouldn't be "How are you so awesome at making hacking tools?"
The fact that OpenAI is making it much easier for unskilled people to break into and damage servers is indeed very bad news, but it's not new bad news. Irresponsible parties have been doing this for years, most notably the NSA. The NSA has a division that researches bugs in widely used software like Windows. Sometimes when it finds a serious bug it will warn Microsoft about it so that Microsoft can fix it and keep Americans (and others) safe from malicious actors who also discover this bug and use it to attack them.
But sometimes, the NSA (and other "security" orgs, like the CIA) will discover a really juicy bug and then keep it secret, so that they can use it to attack their adversaries. This is a doctrine called "NOBUS," which stands for "No One But Us" – as in, "No one but us is smart enough to find this bug, so we can leave it unpatched without putting Americans in danger."
NOBUS is a terrible idea. How terrible? Well, in 2017, the NSA lost track of a Microsoft Windows vulnerability that they'd discovered and hoarded, code-named "EternalBlue." After EternalBlue found its way into the wild, some halfway competent hackers spliced it into some boring, everyday ransomware, giving that ransomware a new lease on life. Within a few months, the stupidest people on the internet were shutting down some of the most important systems in the world, demanding cash to return them:
https://en.wikipedia.org/wiki/EternalBlue
They shut down whole cities:
https://en.wikipedia.org/wiki/2019_Baltimore_ransomware_attack
They took over hospitals:
https://www.bbc.com/news/technology-35584081
They seized oil pipelines:
https://en.wikipedia.org/wiki/Colonial_Pipeline_ransomware_attack
They stole the British Library, whose postmortem on the attack is one of the clearest, most informative cybersecurity documents ever written:
https://cdn.sanity.io/files/v5dwkion/production/99206a2d1e9f07b35712b78f7d75fbb09560c08d.pdf
The NSA's irresponsible handling of EternalBlue ended up giving a gigantic force-multiplier to otherwise incompetent and inconsequential cyber-criminals. It's as though they found some guy under a Prius removing the catalytic converter with a Sawzall and handed him a piece of software that could shut down major American cities. That was – and is – very bad.
The hacking tools that the chatbot companies are developing stand to carry on this very stupid tradition. It is scary, but not because the chatbots are waking up. It's scary because the world's IT systems are indifferently created and poorly maintained and riddled with vulnerabilities:
This week, I had a couple of opportunities to hash this over in public with Riley Quinn; first at a book launch in London and then on the Trashfuture podcast:
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
Riley had a very good way of summarizing this: "LLMs are real, AI is fake." LLMs – chatbots trained on things like CTF logs that can break into servers – are real. They're on a continuum with other hacking tools that have been steadily demonstrating the fragility of the modern digital world, albeit without inspiring anyone in power to do anything about it.
"AI" – chatbots that wake up, "set their own goals," and "spontaneously" start hacking servers – is fake. It doesn't have "a 10% chance of ending the human race." The Hugging Face hack isn't a mysterious, supernatural occurrence. It's a Python loop and a chatbot. The people responsible didn't accidentally create god: they created autonomous malicious software and then failed to closely monitor it, resulting in it doing something both foreseeable and bad.
It's fine to worry about this new suite of tools that give even stupider people the ability to trash even more computers. You should worry about that – and demand better security practices from firms and governments, including a blanket prohibition on NOBUS-style vulnerability hoarding. That's a productive kind of worrying, with a chance of addressing your area of concern. It's infinitely more reasonable than locking yourself in the toilet with a flashlight and saying "Ayyyyy Eyyyyyye" into the mirror until you wet yourself.
MAKERphone 2.0 – an educational DIY mobile phone https://www.kickstarter.com/projects/albertgajsak/makerphone-20-an-educational-diy-mobile-phone
fatcousin — 5200 free local-first browser tools https://fatcousin.com/
The Fall to Nowhere https://jasminatesanovic.wordpress.com/2026/09/04/the-fall/
Birthmarks https://www.macdermog.com/birthmarks
#25yrsago Why the Bombings Mean That We Must Support My Politics https://web.archive.org/web/20010917015537/http://www.adequacy.org/?op=displaystory;sid=2001/9/12/102423/271
#25yrsago How blogs are covering 9/11 https://web.archive.org/web/20010917015712/https://www.wired.com/news/culture/0,1284,46766,00.html
#20yrsago Wikipedia founder debates Britannica editor-in-chief https://web.archive.org/web/20061005041001/http://online.wsj.com/public/article/SB115756239753455284-A4hdSU1xZOC9Y9PFhJZV16jFlLM_20070911.html?mod=blogs
#15yrsago Deceptive “independent research” from Hollywood front suggests Australians are easily frightened https://torrentfreak.com/anti-piracy-lobby-misleads-aussie-press-for-three-strikes-campaign-110912/
#15yrsago Agents tell YA authors: lose the gay characters and I’ll get you a deal https://web.archive.org/web/20110913010328/http://blogs.publishersweekly.com/blogs/genreville/?p=1519
#10yrsago IoT malware exploits DVRs, home cameras via default passwords https://securityaffairs.com/50929/malware/linux-mirai-elf.html
#10yrsago Oppps.ru: patient zero in Russia’s fake news epidemic https://globalvoices.org/2016/09/12/how-fake-stories-reported-in-russias-news-media-regularly-fool-everyone/
#10yrsago It’s really easy for fired, dirty cops to walk into a new police job in a new town https://www.nytimes.com/2016/09/11/us/whereabouts-of-cast-out-police-officers-other-cities-often-hire-them.html
#10yrsago Donald Trump used $20K worth of charitable donations to buy a 6′ tall painting of Donald Trump https://www.washingtonpost.com/politics/how-donald-trump-retooled-his-charity-to-spend-other-peoples-money/2016/09/10/da8cce64-75df-11e6-8149-b8d05321db62_story.html
#10yrsago Autocratic regimes systematically deny internet access to opposition ethnic groups https://www.science.org/doi/10.1126/science.aaf5062
#10yrsago Leaked Stingray manual shows how easy warrantless mass surveillance can be! https://web.archive.org/web/20160912203446/https://theintercept.com/2016/09/12/long-secret-stingray-manuals-detail-how-police-can-spy-on-phones/
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
Boston: The Paradox of Enshittification and Reverse Centaurs (Harvard Berkman Klein), Sep 30
https://cyber.harvard.edu/events/running-harder-falling-faster-paradox-enshittification-and-reverse-centaurs
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
What Would a Normal Person Do (Trashfuture)
https://www.patreon.com/trashfuture/posts/what-would-do-169247456
Pod Save the UK
https://audioboom.com/posts/8950533-radicalised-organised-and-thick-as-s-t-nish-has-had-it-with-far-right-protests-plus-why
Stop Saying AI Can Do Your Job (Factually)
https://www.youtube.com/watch?v=VU3gABvwZCM
Be Skeptical of the AI Sales Pitch (Trumponomics)
https://www.bloomberg.com/news/audio/2026-09-09/trumponomics-cory-doctorow-questions-the-ai-hype-podcast
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
i've gotten six of these emails today alone, and all of them are offering to cite the work that i've already researched and cited myself because i, y'know, wrote it
can someone please inform these companies that there is more than one noun available to them
If I use ChatGPT to help me partially solve a Millennium Prize problem, what are the chances that my work will influence training such that a later model helps someone else solve it first?
it's funny to me that the non-RGB versions of computer hardware now sometimes go for ~$20 more than the RGB

The most reliable way to lose a political battle is to let your adversary define the terms. For example, if you're an artist and you let your boss define the fight over AI, he'll make it all about "IP" (not labor) and ask you to help secure a victory that will make him richer and you poorer:
https://pluralistic.net/2026/09/02/scrape-scrope-scrap/
If we want to win these important battles, we can't let our adversaries define them. That's the blunder we made 50 years ago, when we let the neoclassical economists redefine the problem of monopolies. Before the Carter era, the monopoly fight was about power. Monopolies had to be fought because wealth concentration would create "autocrats of trade," so powerful as to be beyond the reach of any regulator, any union, any competitor. Even if a company achieved its monopoly by being the best in the world – by making the best products at the best prices while paying the best wages – its power still needed blunting, lest it change its mind and start charging more, reducing quality, and paying less:
https://pluralistic.net/2022/02/20/we-should-not-endure-a-king/
The Chicago School economists who were catapulted to dominance by Reagan, Thatcher, et al won this debate by changing the frame. They insisted (as neoclassicals love to do) that economics is no mere social science, obsessed with squishy, qualitative matters like "power." Rather, economics was a natural science, like physics, in which everything important could be crystallized (which is to say, reduced) to an equation:
https://en.wikipedia.org/wiki/Nobel_Memorial_Prize_in_Economic_Sciences#Creation_and_funding
Economists call these equations "models," and they are famously impenetrable…unless you've had extensive training in economics. Once everything important about the economy was captured by abstruse equations, ordinary people's "feelings" about being squeezed, coerced, corralled or cheated were no longer germane:
https://pluralistic.net/2022/05/09/rest-in-piss-robert-bork/#harmful-dominance
Thus, competition enforcement was transformed: no longer was it an inquiry into the power that a company wielded or might amass through a merger. Rather, every competition question was a matter of solving an equation that would tell you whether the result would be "efficient":
https://pluralistic.net/2021/06/03/jitters/#brittleness
This framing was tactically brilliant. Once an economist pronounces a merger to be "efficient," everyone who opposes that merger can be dismissed as campaigning for an inefficient world. Who wants to live in an inefficient world?
But "efficiency" isn't a freestanding concept. A Martian observing the Earth through a powerful telescope could not tell you when a long line at the grocery store was "efficient" (because the wages saved by understaffing exceeded the lost business from customers who noped out and abandoned their shopping cart) and when it was "inefficient" (because the mom whose wait made her miss administering her kid's insulin ended up spending thousands on an emergency room visit).
In practice, an economist's "efficiency" is indistinguishable from "brittleness" and often crosses over into "cheating." The most "efficient" companies in the world have made an art out of locking in their customers, making it so hard to switch to a rival that customers tolerate declining quality, service and affordability:
https://pluralistic.net/2026/09/06/hotels-california/#the-eagles-were-optimists
During the pandemic, the "efficiency" of long supply-chains, low inventory, and bare-bones staffing was revealed as a form of societal immunocompromise, the annihilation of everything we need to survive when the status quo collapses, so that disaster always becomes calamity:
https://pluralistic.net/2022/06/01/factories-to-condos-pipeline/#stuff-not-money
Speaking this week on the Capitalisn't podcast, the heterodox economist Mariana Mazzucato unpacks her new book The Common Good Economy, and how its thesis reframes "efficiency" as a productivity question:
https://capitalisnt.com/episodes/can-capitalism-serve-the-common-good-ft-mariana-mazzucato-EODamLKT
Mazzucato describes how the economic fetish for efficiency and growth lacks specificity. Organizing a society around "growth" leads to a financialized economy, in which firms post growth by selling off the things they need to survive:
https://pluralistic.net/2024/05/23/spineless/#invertebrates
It leads to an enshittification economy, where firms "grow" by making their products worse, as when Google adds five more ads to every Youtube video and makes search worse so you'll have to keep refining your queries, loading fresh ads every time:
https://pluralistic.net/2024/04/24/naming-names/#prabhakar-raghavan
As with "efficiency," there's nothing wrong with "growth" (indeed, "de-growth" is a terrible slogan and a giant self-own for the climate movement). To smash gouging landlords, we need to grow the supply of housing stock, but if we flatten this to mean "number (of new condos) go up," we'll end up with a city full of half-built buy-to-rent condos that no one wants to pay for, much less live in:
We need "growth" of batteries, solar panels, sea-walls, heat-pumps, insulation and recycling plants. We need "growth" of controlled burns, medical services, and gender-affirming care. We need "growth" of federated social media and non-American alternatives to productivity software.
This is where framing the debate is so important. We have to take back terms like "productivity," so it means "making things that we need more of," not "making more things." Governments can use taxation, procurement and regulation to coerce, convince, or woo private firms into producing these things – and governments can produce them directly.
The biggest barrier to a productive, resilient economy is corporate power. Smashing their power and building our own has to be our alpha and omega. We can't afford to spend our time arguing about whether a monopolist is "efficient." Efficiency does not render concentrated wealth and power safe for human civilization.
Once we reclaim productivity as "more of the things we want," we'll make it clear that replacing civil servants with AI chatbots is a loser policy. Mark Carney wants to fire tens of thousands of Canadian civil servants and replace them with defective LLMs on the grounds that these will cost less:
But they will deliver less, too. The only thing public sector chatbots truly deliver is cynicism about the ability of the state to achieve anything:
https://pluralistic.net/2026/02/06/doge-ball/#n-600
After generations in which the private sector has been allowed to degrade into an extractive, hostage-taking, enshittifying, planet-torching existential risk, we need the public to believe that states can deliver excellence. What's more, any politician who oversees the delivery of excellence will be beloved by the public, who will reward that politician by backing the kind of wildly ambitious program we desperately need:
https://pluralistic.net/2026/02/24/mamdani-thought/#public-excellence
As Mark Carney so eloquently said at Davos, as frightening as it is to have Trump "rupture" the old order, we should all be able to agree that the old order sucked and seize this opportunity to build something new and better:
I believe in Carneyism with all my heart – I just wish Carney did:
https://pluralistic.net/2026/05/30/rupture/#deeds-not-words
For all Carney's talk of a rupture and a better new world, his two signature strategies (besides replacing the civil service with chatbots) are retaliatory tariffs and importing Chinese EVs. Neither of these addresses Canada's resiliency and productivity deficits. If the retaliatory tariffs work, Canada goes back to getting its cars from America. If the China deal works, Canada swaps its USA risk for a China risk.
If Carney was actually interested in Carneyism, he'd use retaliatory tariffs and Chinese EVs to buy time while committing massive investment for building Canada's industrial capacity to manufacture the things that give other countries dangerous leverage. The problem with the old order was that it created a brittle system where one maniac elevated to a position of power could shatter everyone's peace and prosperity. The answer to that is not "a different maniac." It's also not two maniacs.
To be truly productive and efficient, Canada needs a competent, well-resourced civil service, not chatbots. It needs the capacity to build things that it can't afford to do without. Carney's failure to embrace Carneyism while insisting that he is delivering efficiency and growth is as clear an example of the risks of letting your enemies set the terms of the debate as you could ask for.
(Image: Martell, CC BY-SA 3.0; Horacio Cambeiro, CC BY-SA 4.0; modified)
Mamdani Opens Office of Worker Power https://prospect.org/2026/09/07/mamdani-opens-office-of-worker-power-new-york-city-labor/
Digital Sovereignty: What It Is, What It Could Be https://www.eff.org/deeplinks/2026/09/digital-sovereignty-what-it-what-it-could-be
Poll Finds Majority Of Republicans Support Unions https://theonion.com/poll-finds-majority-of-republicans-support-unions/
Blizzard Workers Win Historic Union Contract That Could Set A New Standard For Game Developers https://www.gamespot.com/articles/blizzard-workers-win-historic-union-contract-that-could-set-a-new-standard-for-game-developers/
#25yrsago Tell Canada to Reject Anti-Technology Bans https://web.archive.org/web/20010917020803/https://www.eff.org/alerts/20010907_eff_canada_cpdci_alert.html
#25yrsago Making Light on 9/11 https://web.archive.org/web/20010917012109/http://www.panix.com/~pnh/makinglight.html
#25yrsago Twin Towers survivor registry https://web.archive.org/web/20010914220549/https://www.shunn.net/okay/
#25yrsago Blame encryption for 9/11 https://web.archive.org/web/20010917024851/http://www.usatoday.com/life/cyber/tech/2001-02-05-binladen.htm
#20yrsago Lawbot: open expert system for legal “advice” https://web.archive.org/web/20061103200129/https://www.lawunderground.org/PortalCSVS/DesktopDefault.aspx
#20yrsago USPTO encloses 10MB of porn with trademark rejection https://web.archive.org/web/20061005074505/https://www.thesmokinggun.com/archive/0911061uspto1.html
#20yrsago German Pirate Party founded https://web.archive.org/web/20061011142613/http://www.piratenpartei-deutschland.de/index.php?id=50
#20yrsago Starbucks co-produces movie, then sells DVD https://web.archive.org/web/20060322021155/http://www.post-gazette.com/pg/06013/637176.stm
#20yrsago How Hollywood’s MP in Canada financed her campaign https://web.archive.org/web/20061010121752/https://www.michaelgeist.ca/content/view/1428/125/
#20yrsago Jimmy Wales to Beijing: Wikipedia won’t censor https://web.archive.org/web/20061004173945/http://observer.guardian.co.uk/world/story/0,,1869074,00.html
#20yrsago Chumby chairman interview: squeezable, open bean-bag computer https://wifinetnews.com/archives/2006/09/podcast_21_chumbys_chairman_steve_tomlin.html
#15yrsago Judge: copyright troll showed “staggering chutzpah” in sending its own subpoenas to ISPs https://www.eff.org/deeplinks/2011/09/judge-sanctions-copyright-troll-attorney
#10yrsago Why Facebook’s “It’s too hard” excuse for Vietnam war photo takedown is bullshit https://web.archive.org/web/20160914214543/http://tinyletter.com/danhon/letters/s3e27-it-s-difficult
#10yrsago A socialist wrote the Pledge of Allegiance, which used to be accompanied by Nazi salutes https://www.smithsonianmag.com/smart-news/rules-about-how-to-address-us-flag-came-about-because-no-one-wanted-to-look-like-a-nazi-180960100/?no-ist
#1yrago Hate the player AND the game https://pluralistic.net/2025/09/10/say-their-names/#object-permanence
#1yrago Reverse centaurs are the answer to the AI paradox https://pluralistic.net/2025/09/11/vulgar-thatcherism/#there-is-an-alternative
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Stop Saying AI Can Do Your Job (Factually)
https://www.youtube.com/watch?v=VU3gABvwZCM
Be Skeptical of the AI Sales Pitch (Trumponomics)
https://www.bloomberg.com/news/audio/2026-09-09/trumponomics-cory-doctorow-questions-the-ai-hype-podcast
Fisher-Price Management (Does A Frog Have Scorpion Nature?)
https://www.youtube.com/watch?v=OVYS4l8M5UI
Downstream with Michael Walker (Novara)
https://www.youtube.com/watch?v=nTqCVJFr7XM
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

As once-extinct diseases sweep through America, sickening, maiming and killing, the wild lunacy of anti-vax superstition grows ever more difficult to excuse.
Even the most uncomfortable vaccinations are nothing compared to the agony of the diseases they stave off. The worst I've ever felt after a jab was when I insisted – against doctor's orders – on getting the shingles, flu and covid jabs at the same time (I was about to leave on a complex trip where I'd be in a lot of enclosed spaces with a lot of different people, and I'd just had a cancer diagnosis and didn't want to get sick in case that foreclosed on my oncologist's therapeutic plans).
I felt like dogshit for about a day, and it didn't matter. Every time I felt like groaning and complaining, I thought about Rusty, my grandmother's wonderful boyfriend (they shacked up after my grandfather died, but didn't get married because she would have lost her widow's benefits). Rusty was the toughest guy I knew, an ex-bodybuilder who never showed any sign of discomfort, not even after his knee-replacements. The only time Rusty ever lost his composure in my presence was when he had shingles, when the agony reduced him to uncontrollable weeping. I knew that no matter how ooky all those vaccines made me feel, it was better than going through what Rusty had experienced. There was no way I'd handle it nearly so well as he did.
Rusty's shingles experience was the best case. He didn't end up with years of crippling nerve pain. He didn't lose his sight or hearing, didn't experience brain damage, didn't die of encephalitis. Fuck yeah I'll get a shingles vax.
As many people have observed, the problem with vaccines is that they work too well. The incredible, astounding, profound wonders of vaccines led many people to think of measles as a rash, the flu as a bad cold, mumps as a thing that makes you look like Brando playing Don Corleone. Vaccines worked so well to eliminate a terror that stalked the land and stole people's lives and loved ones and little children, an achy arm or an infinitesimal chance of a few days of feeling like shit seemed worse by comparison.
Now that we've turned our backs on this miracle, now that vaccination is in retreat and long-forgotten diseases are taking our babies, millions of people are still insisting that vaccines are a hoax.
That's infuriating and frustrating, but it's understandable. The cause-and-effect relationship between herd immunity and disease elimination is complex, and it plays out over a long timescale. It's notoriously hard to reason well about phenomena whose causal relationships are attenuated and multifactorial.
It's one thing to learn to hit a ball by swinging at it and watching where it goes – it's another altogether to swing blindfolded, go home, and then, eight years later, have someone tell you where the ball ended up. No one would start smoking if the first puff caused you to break out in visible tumors.
The attenuated, complex relationship between smoking and cancer creates a space where death merchants could instill profitable doubt and the more our institutions fail us, the easier it is to spread that doubt.
After all, nearly all of us lack the technical expertise to sort through the claims and counterclaims of tobacco lobbyists and public health authorities. To a large extent, we have to trust the process: trust it to be a well-administered truth-seeking exercise that does its best to find the correct answer to complex, technical questions. When the state is manifestly bad at doing its job, we still have to answer these complex, technical questions, but (lacking both the expertise to draw an informed conclusion and a reliable process by which expert disagreements can be settled), we're left helpless to do so. It's enough to drive you to despair:
https://pluralistic.net/2024/03/25/black-boxes/#when-you-know-you-know
This is an essay about anti-trust.
135 years ago, monopolists were such a destructive force – ruining workers' lives; corrupting politicians; pauperizing, swindling and poisoning their customers – that we created the first anti-monopoly laws:
https://pluralistic.net/2022/02/20/we-should-not-endure-a-king/
It took a quarter of a century to really start putting those laws into effect, but we eventually dismantled the robber barons' vast, destructive machines:
https://pluralistic.net/2025/11/20/if-you-wanted-to-get-there/#i-wouldnt-start-from-here
The World Wars helped: two consecutive orgies of capital destruction left oligarchs' treasuries so bare that we were finally able to realize some of our most utopian dreams of mutual aid and care, and all around the world, we won labor rights, state pensions, public medicine, all the wonders of the era the French call "Les Trente Glorieuses" (the 30 glorious years):
https://en.wikipedia.org/wiki/Trente_Glorieuses
But because antitrust worked, we forgot how corrosive monopolies were. When the neoliberal economists of the Reagan/Thatcher era told us that we were missing out on the "efficiencies" of vast corporations, we blundered into their trap, letting them define the debate, so that instead of talking about how monopolies could clobber workers, customers and governments, we talked about whether monopolies might reduce prices. Sure, a monopoly can reduce prices – but as soon as it eliminates its competitors and captures its government, it's going to raise those prices, safe in the knowledge that a company that's too big to fail is too big to jail:
https://pluralistic.net/2024/08/14/the-price-is-wright/#enforcement-priorities
The dismantling of anti-monopoly law and the growth of the monopolies happened gradually, and then all at once. The decision to kill antitrust enforcement took place a half-century ago, but it was only in the past few years that the relationship of monopoly to our political, environmental and social dysfunction has entered our politics. The causal relationship between pro-monopoly policies and the harms of monopoly is even more complex and attenuated than the causal relationship between anti-vax and kids dying from measles in Texas.
Monopolies are especially hard on policymaking. Large, concentrated industries find it easier to arrive at a common lobbying position. They are aslosh in cash, thanks to their ability to cooperate (rather than eroding one another's margins through "wasteful competition") (h/t P. Thiel):
https://mastersofscale.com/peter-thiel-escape-the-competition/
To live in an age of monopolies is to live in an age of regulatory capture, in which your government routinely fails you in terrible ways to benefit elites and insiders. When that happens, it's easy to conclude that government is incapable of regulating, and to insist that we might as well do away with the state altogether. This is a self-reinforcing belief, because the weaker the state is, the more monopolists can steal from you:
https://pluralistic.net/2022/06/05/regulatory-capture/
It's easy to understand how someone who lived through the murder of an addicted loved one at the hands of the billionaire Sacklers, who were abetted by their putative regulators and got to keep billions of dollars even after they declared "bankruptcy" might conclude that they can't trust pharmaceutical companies' or their regulators when they swear vaccines are safe and effective:
https://pluralistic.net/2021/08/18/lets-make-a-deal/#art-of-the-deal
In the same way, once you've forgotten that we decided to let monopolists run amok, despite regulatory capture that would obviously follow as a consequence, you might well conclude that governments are part of the problem, and therefore can't be the solution. We forget that things used to be better, and we forget how things were made better, and we forget how they got worse.
Like vaccines, antitrust worked too well. By the time Jimmy Carter and Ronald Reagan decided to welcome "efficient" monopolies, it had been so long since the world had been brought to the brink of ruin by oligarchs that it was easy to sell the pain of "lost efficiency" as worse than the distant horrors of the Gilded Age.
As the old joke goes, "When it don't rain the roof don't leak; when it's raining, I can't hardly fix it." We got rid of antitrust because it had been so long since oligarchs ran the world, we forgot how bad they'd made everything. Now that oligarchs are driving civilization off a cliff, we can't imagine fighting these seemingly omnipotent monsters.
We can fix this, just as our not-so-distant ancestors did when they tamed their robber barons. It won't be easy. It starts with remembering.
(Image: Atomicdragon136, CC BY 3.0, modified)
Stand up to union busters https://search.laborlab.us/
Estimate the cost of an anti-union campaign. https://calculator.laborlab.us/
Labor Day 2026: Record-High Popularity, Record-Low Power for America’s Unions https://prospect.org/2026/09/07/labor-day-2026-record-high-popularity-record-low-power-for-americas-unions/
216,000,000 Spy TVs | The LG Smart TV Problem https://www.youtube.com/watch?v=6IFVTcM28KA
#25yrsago Garry Trudeau gets hoaxed http://news.bbc.co.uk/2/hi/americas/1530220.stm
#25yrsago Publishers v radical librarians https://web.archive.org/web/20010713171001/http://news.cnet.com/news/0-1005-201-6545588-0.html
#20yrsago Podcasters act now to stop anti-podcasting UN treaty! https://web.archive.org/web/*/https://www.eff.org/IP/WIPO/broadcasting_treaty/podcasting.php
#20yrsago Why CDT’s report on DRM falls short of the mark https://craphound.com/cdtdrmresponse.txt
#20yrsago Barenaked Ladies guy on Universal’s DRM SpiralFrog service https://web.archive.org/web/20061110205411/http://www.bnlblog.com/entry.asp?dDate=8/30/2006
#20yrsago HOWTO Use sugar to sand away logos on your phone https://web.archive.org/web/20061006153939/http://www.instructables.com/id/EFHU5V6TKYERIE2SMP/?ALLSTEPS
#20yrsago HOWTO Knit a Princess Leia wig https://web.archive.org/web/20061020092941/https://bleuarts.blogspot.com/2006/09/free-pattern-leia-hat.html
#20yrsago Prisoner statue smuggled into Disneyland ride http://www.woostercollective.com/post/breaking-the-story-disneyland-doesnt-want-you-to-know
#15yrsago RIP, Project Gutenberg founder Michael Hart https://web.archive.org/web/20111008024157/http://news.cnet.com/8301-30685_3-20103356-264/e-book-pioneer-michael-hart-dies/
#10yrsago Supermaker John Edgar Park shares his bitters recipe https://makezine.com/projects/ultimate-bitters-recipe/
#10yrsago How Hong Kong’s vulnerable, reviled refugee community saved Edward Snowden https://srilankafoundation.org/newsfeed/how-snowden-escaped/
#10yrsago Leaked catalog from UK surveillance arms-dealer full of gadgets sold to US cops https://theintercept.com/2016/09/01/leaked-catalogue-reveals-a-vast-array-of-military-spy-gear-offered-to-u-s-police/
#10yrsago Wells Fargo fires 5,300 employees for opening 2M fake accounts in customers’ names https://web.archive.org/web/20160908200030/https://money.cnn.com/2016/09/08/investing/wells-fargo-created-phony-accounts-bank-fees/index.html
#10yrsago European court rules that making a link can be copyright infringement https://www.eff.org/deeplinks/2016/09/european-copyright-ruling-ushers-new-dark-era-hyperlinks
#10yrsago Indian workers staged one of the largest strikes in human history and no one in the USA noticed https://theintercept.com/2016/09/06/indians-staged-one-of-the-largest-strikes-in-history-but-no-one-on-u-s-cable-news-covered-it/
#10yrsago Homeowners’ associations are not allowed to ban drought-tolerant landscaping https://www.latimes.com/business/la-fi-associations-landscaping-plans-20160831-snap-story.html
#10yrsago Blackballed by machine learning: how algorithms can destroy your chances of getting a job https://www.theguardian.com/science/2016/sep/01/how-algorithms-rule-our-working-lives
#10yrsago The US Copyright Office is the poster child for regulatory capture https://web.archive.org/web/20160909001439/https://www.publicknowledge.org/assets/uploads/blog/Final_Captured_Systemic_Bias_at_the_US_Copyright_Office.pdf
#10yrsago The women held a vote, and you’re not allowed to talk to anyone ever again https://web.archive.org/web/20160908124630/http://ursulav.livejournal.com/1680540.html
#10yrsago Open licenses don’t work for uncopyrightable subjects: 3D printing edition https://michaelweinberg.org/post/150123246460/the-cost-of-a-successful-creative-commons-and-open/
#10yrsago Tomorrow: largest prison strike in US history https://thenib.com/inmates-are-planning-the-largest-prison-strike-in-us-history/
#10yrsago If DRM is so great, why won’t anyone warn you when you’re buying it? https://www.theguardian.com/technology/2016/sep/08/drm-product-labelling-ftc-electronic-frontier-foundation?CMP=share_btn_tw
#1yrago Fingerspitzengefühl https://pluralistic.net/2025/09/08/process-knowledge/#dance-monkey-dance
#1yrago Trump steals $400b from American workers https://pluralistic.net/2025/09/09/germanium-valley/#i-cant-quit-you
Manchester: City of Literature, Sep 11
https://www.manchestercityofliterature.com/event/the-reverse-centaurs-guide-to-life-after-ai-by-cory-doctorow/
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Kilkenny: Kilkenomics, Nov 6-8
https://kilkenomics.com/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Downstream with Michael Walker (Novara)
https://www.youtube.com/watch?v=nTqCVJFr7XM
The future of the tech crisis (How the Light Gets In)
https://iai.tv/video/the-future-of-the-tech-crisis?_auid=2020
How Tech Platforms Took Over the Economy (Dystopia Now)
https://sites.libsyn.com/566555/enshittification-and-reverse-centaurs-cory-doctorow-on-how-tech-platforms-took-over-the-economy
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
made some tiny stamps out of lino scraps to make labels for my jam jars

"If economists wished to study the horse, they wouldn’t go and look at horses. They'd sit in their studies and say to themselves, 'What would I do if I were a horse?'" -Ely Devons
Half a century ago, a group of lavishly financed economists from the University of Chicago (the "neoliberals") convinced governments all over the world to completely upend the way they treated monopolies. Up until then, the purpose of competition enforcement was to reduce corporate power, with the understanding that once a corporation became more powerful than the government, it would be impossible to force it to follow any rules:
https://pluralistic.net/2022/02/20/we-should-not-endure-a-king/
But for the "Chicago Boys," monopolies were evidence of efficiency. When you encounter a company in the wild that has acquired a commanding market share, your first assumption should be that it has taken over its sector by being better than anyone else – you should not assume that the company cheated its way to glory. After all, if a company with a large market share was cheating – say, if it was increasing its profit margins by reducing quality or jacking up prices – then smaller companies would rush into the market to poach its dissatisfied customers.
Thus, all competition enforcement was reduced to an empty syllogism: monopolies are the result of excellence and any less-than-excellent monopolist will have its advantage "competed away." Therefore, any monopolist you encounter in the wild is definitionally not a bad monopolist, otherwise it would already have disappeared.
To quote another economist joke:
Two economists are walking down the street when one notices a $20 bill on the sidewalk. "It's not a real $20 bill," the other declares. "If it were a real $20 bill, someone would have picked it up off the sidewalk already."
Half a century later, our entire economy is dominated by monopolies, duopolies and cartels, who boast of gigantic margins, whose products are palpably worsening at an accelerating clip, and yet there is no sign of the "new market entrants" who should be flooding into the market to "compete away" those amazing margins. It turns out that asking "What would I do if I were a horse?" does not yield a series of accurate predictions about horses.
Things have changed. Today, the University of Chicago's Stigler Center harbors a cluster of influential economists who largely or entirely repudiate the orthodoxy of the Chicago Boys. The Center hosts an annual, rather radical conference on antitrust; runs an excellent heterodox podcast (Capitalisn't); its house organ, Promarket.org, regularly hosts work that torches the received wisdom of High Chicago Neoclassicism; and the school's researchers publish papers that dare to actually "go and look at horses."
A recent horse-looking excursion has yielded some distressing, alarming, and thoroughly documented equine facts. In a new Stigler paper, "Rising Customer Durability, Falling Business Dynamism," UC's Li Azinovic-Yang, Ava E Speros and Christopher R Stewart and Stanford's John D Kepler report on some clever research into how a monopolist could raise prices, lower quality, anger its customers, and still dominate its market:
https://www.chicagobooth.edu/-/media/research/stigler/pdfs/workingpapers/387_customer.pdf
The researchers' hypothesis was that dominant businesses don't maintain their lead by making their customers happy, but by making it harder for those customers to leave. There's good reasons to suspect this. Between 2002 and 2024, the average "customer relationship" (how long a customer continues to purchase from a merchant) has risen from 7.5 years to 11.5 years, a 50% surge in "customer loyalty," far outstripping any measure of customer satisfaction over the same period. This is true across all the largest sectors of the economy: "manufacturing, information, professional services, financial services, and wholesale trade."
How to explain the falling divorce rate between customers and businesses? That's where the researchers got very clever. They realized that when a company seeks permission to acquire another business, it must publish truthful and comprehensive information about how the merger is expected to increase the profits of the new combination. These disclosures are validated by external auditors, boards of directors, and/or audit committees. There are legal repercussions for falsifying them or making material omissions to them, and they are matters of public record.
Crucially, these disclosures must include the business's plans to retain its customers, and its plans to increase the profits from those customers. That's where the researchers struck gold. They amassed a novel data-set of 9,500 acquisitions that disclosed over $1t worth of "customer relationship-related intangibles," more than 20% of all the assets that changed hands.
They supplemented this data by mining earnings calls (also subject to strict penalties for omissions and falsehoods), finding CEOs boasting about "practices that may impede switching or increase customers’ dependence on the firm." Executives bragged about their "contractual restrictions, bundling and ecosystem lock-in, and switching costs."
You can get a sense of these in a short accompanying article by the study's co-author Christopher Stewart:
The article recounts how Sirius XM's execs celebrated the news that an appeals court had struck down the FTC's "Click to Cancel" rule, which required companies to make it as easy to resign from a subscription service as it was to sign up for it. Click to Cancel is a response to increasingly sleazy, increasingly pervasive tactics that make it all but impossible to stop being someone's customer. Trump's FTC walked away from defending the rule, which let the court kill it:
https://pluralistic.net/2025/05/12/greased-slide/#greased-pole
After Click to Cancel died, Sirius XM's C-suite got on a call with their shareholders to project "better outcome(s) as a result of not having that in place." Sirius believed that a rule that made it easy for customers to resign from their monthly subscriptions would hurt its business. Put another way: Sirius believes that its profits come in part from the fact that dissatisfied customers can't figure out how to cancel their service.
Then there's the online insurance company eHealth, whose execs crowed about a new "innovation" that forced senior patients to painstakingly enter a long list of their medications and doctors, but did not give them any way to export that data. The lengthy investment of time in getting set up on eHealth would stop customers from leaving, because they wouldn't want "to repeat all of that information over the phone."
This is also a feature of business-to-business relationships. In 2019, US Silica's execs described how they had launched a program to become embedded in their customers' supply chains, because that "really locks in the business," making it "much more difficult for customers to switch and go to someone else."
That's the first half of the story: an empirical account of how the business world switched from "acquiring customers" to taking hostages.
But the second half of the paper is even more interesting: an empirical investigation into the effects of this customer lock-in. For starters, increased customer retention is "associated with higher gross profit margins": that is, the companies whose customers can't leave squeeze those customers for more profit. What's more, once a company has its customers locked in, it starts to capture a larger share of all the profits in its entire sector: these hostage-takers become so profitable that their profits dwarf the profits of their competitors.
The paper also solves the mystery of the missing market entrants that the neoclassical horse-ponderers insisted would be conjured up to compete away an abusive monopolist's margins. The more locked in the customers of a monopolist are, the fewer companies try to enter that market. This makes sense: who would invest in a new business in a market where none of its potential customers can switch to its new business?
This is the opposite of what the horse-ponderers have insisted upon for 50 years. The more lock-in a company attains, the more profitable it becomes, and the less it has to worry about new competitors coming after those incredible margins. This is obvious to everyone, except the monopolist-funded "social scientists" and the governments they captured.
This is bad news, and not just for those locked-in customers. New businesses are the source of new jobs, and, yup, it turns out that sectors dominated by firms with high lock-in create fewer jobs. Of course, as workers chase fewer jobs, bosses are able to suppress their wages by forcing workers to bid against one another. Once again, the study finds that the sectors with the most lock-in also see declining wages in addition to declining jobs.
These are not the horse-ponderers' "efficient" monopolists. Once a company has its customers locked in, it innovates less – as measured by the number of patents a company is awarded, and by how often those patents are cited in other patents (this second measure helps distinguish companies that file mountains of bullshit patents from companies that actually invent useful things). Naturally, R&D spending also declines in companies with more lock-in.
All of this is entirely compatible with the theory of enshittification. Once a company knows its customers can't leave, it can switch from treating them well to abusing them in order to extract money from them. The same goes for companies whose workers can't leave – because they're bound by noncompete clauses, or because their employer has bought out all their rivals:
https://www.eff.org/deeplinks/2023/04/platforms-decay-lets-put-users-first
It's like the old Lily Tomlin sketches on SNL and Laugh-In, where she played Ernestine the telephone operator narrating satirical ads for AT&T. Those sketches would end with her obviously true catch-phrase: "We don't care. We don't have to. We're the phone company":
https://www.youtube.com/watch?v=CHgUN_95UAw
Decades later, Tomlin's phone company joke is a perfect distillation of modern management philosophy. As a famous NBER working paper showed, when a family business is handed over to a professional manager with an MBA, the company doesn't become more profitable overall; it just finds ways to pay its workers less:
https://www.nber.org/system/files/working_papers/w29874/w29874.pdf
That's why Tim Wu named this "the age of extraction." "Growth" no longer means "making something new that people want" – now it means "finding ways to take a larger share of the pie, even if that makes the pie smaller overall":
https://www.wired.com/story/tim-wu-age-of-extraction/
This is something we can all feel. We experience it in our daily lives, through "shrinkflation" and "junk fees" and a million other gross and petty scams. But it's rare that we actually catch executives explicitly admitting that their job is to find ways to take you hostage and squeeze you.
Historically, those revelations have come from extraordinary circumstances, like when Frontier (the worst ISP in America) went bankrupt and we learned that the company had 1.6 million customers who had no access to competing broadband connections. Frontier carried these hostages on their balance sheet as a special, highly valued asset, since they could be charged more for slower, less reliable service:
In assembling this novel, high-quality data-set, the researchers on this paper have performed an important service, capturing a vast number of sworn confessions of highly paid enshittifiers, and then showing how their hostage-taking wrecked competition, prices, wages, jobs and innovation.
Keep the Internet free https://keepitfree.ai/
Money Does Not Decide What It Becomes https://sekimonyo.com/money-does-not-decide-what-it-becomes
#20yrsago Three-hole punch debut, April 1940 https://web.archive.org/web/20061119140057/https://blog.modernmechanix.com/2006/09/06/three-hole-paper-punch-debut/
#20yrsago New Zealand redefines open source as “code you can’t modify” https://memex.craphound.com/2006/09/07/new-zealand-redefines-open-source-as-code-you-cant-modify//
#20yrsago MSFT quicker to patch DRM than security vulnerabilities https://www.schneier.com/blog/archives/2006/09/microsoft_and_f.html
#20yrsago Wikipedia’s dumbest arguments https://en.wikipedia.org/wiki/Wikipedia:Lamest_edit_wars
#10yrsago Why the Pirate Party could end up running Iceland https://web.archive.org/web/20211024071400/https://www.newstatesman.com/culture/2016/09/how-internet-pirates-became-political-force-iceland
#10yrsago Sampling bias: how a machine-learning beauty contest awarded nearly all prizes to whites https://web.archive.org/web/20160906154712/https://motherboard.vice.com/read/why-an-ai-judged-beauty-contest-picked-nearly-all-white-winners
#10yrago Warner Bros flags its own website as a piracy portal in copyright takedowns https://torrentfreak.com/warner-bros-flags-website-piracy-portal-160904/
#10yrsago The privacy wars have been a disaster and they’re about to get a LOT worse https://locusmag.com/feature/cory-doctorowthe-privacy-wars-are-about-to-get-a-whole-lot-worse/
#10yrsago Weapons of Math Destruction: invisible, ubiquitous algorithms are ruining millions of lives https://memex.craphound.com/2016/09/06/weapons-of-math-destruction-invisible-ubiquitous-algorithms-are-ruining-millions-of-lives/
#10yrsago Pro-democracy reformers win big in Hong Kong’s elections https://globalvoices.org/2016/09/06/hong-kong-voters-elect-pro-democracy-legislators-to-defend-the-citys-autonomy-from-china/
#1yrago Stock buybacks are stock swindles https://pluralistic.net/2025/09/06/computer-says-huh/#invisible-handcuffs
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
The future of the tech crisis (How the Light Gets In)
https://iai.tv/video/the-future-of-the-tech-crisis?_auid=2020
How Tech Platforms Took Over the Economy (Dystopia Now)
https://sites.libsyn.com/566555/enshittification-and-reverse-centaurs-cory-doctorow-on-how-tech-platforms-took-over-the-economy
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
make bad art
Other platforms will soon follow, a senior administration official told POLITICO on Tuesday. “We got Lake America changed on Google Maps, and many other maps are changing in a couple days. And Wikipedia is going to change as well,” said the official, who was granted anonymity to speak frankly.
A Wikipedia editor put it well: "You almost want to pat them on the head and say 'Yes, of course it will' in the same way you'd tell a small child that Santa Claus will be delivering their presents."
Huge congratulations to the US-based Wikimedia Foundation employees who voted with 92% support in favor of unionizing, and shoutout to the tireless work of the organizers.

Rome wasn't overthrown in a day. Oligarchies are stubborn, and by the time they've established and entrenched themselves, they have resources, power blocs and even mercenaries they can deploy to repel would-be dethroners.
The USA got its first antimonopoly law, the Sherman Act, in 1890, but it took 22 years before that law could be used to crush John D Rockefeller's corrupt, sprawling empire. Senator John Sherman promoted his law as a way of preventing monopolies from emerging, warning the Senate that they would struggle to overthrow the "autocrats of trade" that monopolies created:
https://pluralistic.net/2022/02/20/we-should-not-endure-a-king/
The Senate passed his law and Harrison signed it, but then successive administrations left the Sherman Act to gather dust on a shelf as Rockefeller went on a spree, accumulating the kind of power that made him a true "autocrat of trade," so powerful that he and the US government were practically evenly matched.
Allowing Rockefeller to create, expand and consolidate his monopoly power was a terrible tactical blunder, giving him decades in which he was able to loot America and its trading partners, pauperizing ordinary people and smashing anyone who got in his way. No one was willing to admit that Rockefeller was a threat to democracy and prosperity until he had amassed all that power, and once he had all that power, it took heroic effort to break him.
The Rockefeller story is like the punchline of that joke: "When it doesn't rain, the roof don't leak; and when it's raining, it's too wet to fix it." Alternatively, there's my other favorite punchline: "If you wanted to get there, I wouldn't start from here."
The Rockefeller blunder wasn't a one-off. The Apple ][+ hit the shelves the same year Reagan hit the campaign trail, and the tech industry's rise occurred simultaneously with the dismantling of competition law enforcement. Tech companies were the first "post-antitrust" industry, and it wasn't until these companies became palpable, terrifying, undeniable, existential civilizational risks that we remembered that we had all these laws on the books that were designed to curb excessive corporate power.
Under Biden, a group of generationally talented, visionary trustbusters were given access to those dormant enforcement powers: Lina Khan at the FTC; Rohit Chopra at the CFPB, Tim Wu in the White House, and Jonathan Kantor at the DOJ Antitrust Division. Together with a staff of canny and skilled lawyers and economists, these people scored incredible victories against Big Tech. During the Biden years, Google lost three federal antitrust cases. Three!
But if we wanted to get there, we wouldn't start from here. After a series of stinging defeats in the US and abroad, after watching the EU, the UK, Japan, Singapore and South Korea make common cause with Biden's enforcers, Big Tech threw everything it had into Trump, who promised them a system of regulatory forbearance in exchange for low-cost bribery, backstopped by a xenophobic, belligerent geopolitics that would rain down punishments on any country that dared to regulate or tax Big Tech:
https://www.bbc.com/news/articles/c62553ywn77o
And then the other shoe dropped: the federal judges who convicted Google of operating an illegal monopoly handed down their "remedy" decisions. In an antitrust case, the "remedy" phase is like sentencing – the stage of the legal proceeding where the judge decides what punishment the company should face for breaking the law.
The first of these remedies came out a year ago, in September 2025. Judge Amit Mehta had presided over Google's "search" case, where we learned that Google had deliberately made search worse so that you'd have to search more than once in order to get your answer, which would allow the company the chance to show you more ads:
https://pluralistic.net/2024/04/24/naming-names/#prabhakar-raghavan
Google was able to do this because it had cornered the market on search. The company had spent years paying a $20b annual bribe to Apple to stay out of the search market, and they'd bought the default search placement for every operating system, browser and carrier. If you encountered a search box in the wild, it was almost certainly wired into Google's servers. They knew that there was approximately zero chance that you'd ever stumble upon another search engine, which meant they could make their own search as shitty as they wanted and keep your business.
Confronted with these proven findings, Mehta decided that Google's punishment should be…nothing. They wouldn't be forced to delete the personal data they'd taken from billions of people. They wouldn't be forced to spin off Chrome or Android – two of the key tools Google uses to keep people from discovering other search engines. They wouldn't even be forced to halt the $20b annual bribe to Apple – the judge fretted that without that $20b annual bribe, Apple wouldn't be able to pay researchers to come up with cool new iPhone features (never mind that Apple spends all that money – and more – on stock buybacks, a recently illegal form of stock manipulation):
https://pluralistic.net/2025/09/03/unpunishing-process/#fucking-shit-goddammit-fuck
Then, a year later, another federal judge – Leonie Brinkema, who presided over the Google "ad-tech" case – decided that Google's penalty for monopolizing the ad market should also be…nothing:
Oh, maybe not exactly nothing. We don't actually know the full extent of Judge Brinkema's "remedy," because it's sealed for two weeks. What we do know is that Google will not be forced to take the most obvious, effective and necessary step to prevent it from abusing its monopoly: Google will not be forced to sell off part of its ad-tech stack.
Let me unpack that for you, because unless you're an ad-tech weirdo, chances are you have no idea how any of this works and don't think it affects you. But the reality is that this is costing you money. It's one of the dirtiest, most profitable scams in the entire tech economy, which is saying something, because that is an economy that is made of scams:
https://pluralistic.net/2026/09/04/cheating-at-fraud/#absentee-rentier
Unlike older ads, which were targeted based on content (say, an ad for a hotel might run next to a newspaper article about a beachside town) modern ads are built on surveillance. Companies like Google amass vast, nonconsensual dossiers on the personal characteristics and behavior of billions of people, supplemented with information purchased from the unregulated data-broker sector.
When you visit a website, the site fires off a piece of software called "sell-side agent" to message a server called an "ad exchange" in order to announce your visit, soliciting bids for the right to show you an ad: "I am about to serve a web-page to a 18-34 year old man-child from New York's outer boroughs, who owns an Xbox and has been recently searching for information about gonorrhea: who wants to cram some ads into this guy's eyeballs?"
That ad-exchange server is haunted by "demand-side agents" – these are pieces of software fired off by advertisers that monitor all these advertising opportunities announced on the ad exchange and bid for the right to show you an ad. The highest bidder gets to show you an ad, and the fee is remitted to the exchange, which takes a cut and passes the remainder on to the sell-side platform, which also takes a cut and gives the balance to the website publisher.
So the ad-tech stack has three main components: the "sell-side platform" (SSP), which lets web publishers announce auctions for the right to advertise to their visitors; the "demand-side platform" (DSP) that lets advertisers bid to show those visitors ads; and the "ad exchange" – the marketplace where the sell-side and demand-side agents meet to collect bids, finalize the sale, and exchange ads for money.
When this all started, there were lots of companies in all three roles. Publishers and advertisers had their choice of SSPs, DSPs and exchanges, and all three types of middleman competed to offer the best deals to advertisers and publishers.
Then, Google and Facebook started buying up the leading DSPs, SSPs and exchanges. They used contracts and technical countermeasures to force anyone who used any part of their "stack" to use them for all parts of the transaction. The CEOs of Google and Facebook personally colluded to rig the market, dividing it up between them so that publishers would get less, advertisers would pay more, and Googbook would pocket the difference. The codename for this conspiracy was "Jedi Blue":
https://en.wikipedia.org/wiki/Jedi_Blue
Jedi Blue was just the icing on the cake. The reality is they didn't need the conspiracy: once Google was selling services to advertisers and publishers on an exchange that Google owned, they created an entire universe of ways to rip off both advertisers and publishers. Now consider that Google is also an advertiser and also a web publisher, and the opportunities to cheat are just wild.
The numbers tell the story. Before Googbook captured 80% of the display advertising business, the total share of the advertising industry's revenues that went to "intermediaries" (middlemen like ad agencies, ad buyers, etc) was about 15%. Today, that number is 51%. Hundreds of billions of dollars have been moved out of publishers' and advertisers' bank accounts and onto Google and Facebook's balance sheets.
This isn't hard to understand. Google runs an ad business that locks in buyers and sellers on a marketplace Google owns and controls, where it also competes with those buyers and sellers. Buying or selling an ad through Google is like going to court to get a divorce, only to discover that you and your soon-to-be-ex- are both represented by the same lawyer, who promptly ascends the bench and dons a judge's wig, and then spends the whole trial trying to match with both of you on Tinder, and who concludes the trial by banging their gavel and announcing that they've decided that the family house will be awarded to…the judge!
The most absurd part of this whole farce is the lawyers who defend it on behalf of companies like Google. If a Google lawyer ever showed up to defend the company in a trial where the judge was working for the plaintiff, they would scream blue murder and refuse to proceed until the judge was removed from the case. But when Google operates a business where it presides over transactions where it has nothing but conflicts of interest, these same lawyers argue that Google would never cheat a seller or a buyer.
The fucking absurdity of this arrangement is so obvious that a bill to force a halt to it was co-sponsored…by Elizabeth Warren and Ted Cruz:
https://gizmodo.com/google-facebook-america-act-ads-break-up-cruz-warren-1850287725
Why would Warren and Cruz care about this? Because the hundreds of billions that have been moved from publishers and advertisers to Google and Facebook are hundreds of billions of dollars that are no longer paying for news and entertainment production, and they're hundreds of billions of dollars that businesses have to recoup by raising prices on you to pay their advertising bills.
Google (and, apparently, Judge Leonie Brinkema) dispute this. They say that "larger forces" have "changed the dynamic" that "restructured the industry." But, I mean, come on! This is a situation where hundreds of billions of dollars are divided up by a thrice convicted monopolist who is mysteriously hundreds of billions of dollars richer, while the other parties to the transaction are mysteriously hundreds of billions of dollars poorer. Anyone who can't draw the obvious causal inference from these facts has so little object permanence that they would lose a fucking game of peek-a-boo.
This is so goddamned demoralizing. For a couple years there, it really looked like the tide was turning. Then Judges Brinkema and Mehta came along to snatch defeat from the jaws of victory.
The only thing that's keeping me going is object permanence. I know my history. I know it took decades from the passage of the Sherman Act until the defeat of John D Rockefeller. Our forebears brought down Rockefeller because they didn't give up, despite setbacks as bad as this one, and worse. Stein's Law of finance holds that "anything that can't go on forever eventually stops," and MLK told us that "the arc of the moral universe is long, but it bends toward justice." This can't go on forever, and despite Dr King's phrasing, I know he understood that the arc doesn't just "bend" – it is bent – by people like us, hauling on it with all our might.
DOGE Affiliate Asked for College Credits for Participating in Takeover https://www.wired.com/story/doge-affiliate-asked-for-college-credits-for-participating-in-takeover/
Why office workers are turning against AI https://www.bloodinthemachine.com/p/why-office-workers-are-turning-against
The Quiet Decision Microsoft Made That Devastated Thousands of Nonprofits https://slate.com/technology/2026/08/microsoft-software-nonprofit-data-delete.html
Vote for the 2026 Tiny Awards Winner https://tinyawards.net/vote/
#25yrsago Advertisers claim they can hack your childhood memories https://web.archive.org/web/20010921022846/http://news.independent.co.uk/uk/science/story.jsp?story=92386
#25yrsago Wind-up cellphone charger https://web.archive.org/web/20011031122531/http://www.thetimes.co.uk/article/0,,2-2001310179,00.html
#20yrsago Steven Brust’s Dzur: witty and exciting heroic fantasy https://memex.craphound.com/2006/09/05/steven-brusts-dzur-witty-and-exciting-heroic-fantasy/
#20yrsago America to US gov’t: kill the Broadcast Treaty! http://www.cptech.org/ip/wipo/bt/jointletter5sep06usptoforum.pdf
#20yrsago New Zealand wants a Ministry of DRM https://web.archive.org/web/20070108042834/http://www.zdnet.com.au/news/software/soa/NZ_draws_line_on_DRM_and_trusted_computing/0,130061733,339270846,00.htm
#20yrsago Is it legal to look at the Web in Canada? https://web.archive.org/web/20061010120919/http://www.michaelgeist.ca/content/view/1411/135/
#15yrsago Advice for self-publishers: why should anyone care about your book? https://locusmag.com/feature/cory-doctorow-why-should-anyone-care/
#5yrsago A letter to a discouraged young writer https://pluralistic.net/2021/09/05/why-bother/
#1yrago Why Wikipedia works https://pluralistic.net/2025/09/05/be-the-first-person/#to-not-do-something-that-no-one-else-has-ever-thought-of-not-doing-before
Warsaw: Romana i Jana Podoskich, Sep 6
https://wydarzenia.phub.pl/events/0ee0e198-f843-423a-890f-c84ff50a46c0
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
How Tech Platforms Took Over the Economy (Dystopia Now)
https://sites.libsyn.com/566555/enshittification-and-reverse-centaurs-cory-doctorow-on-how-tech-platforms-took-over-the-economy
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Amazon's own balance sheet presents the most compelling evidence that we are stuck in the Enshittocene, the era in which everything is turning into a pile of shit, because the worst ideas of the worst people now make the most money.
Amazon is a many-tentacled monster, with several prominent lines of business wrapped around the world. There's its logistics and fulfillment business, which is so successful (at the expense of its workers' labor rights, bodies and bathroom breaks) that it is more than fully subsidized by Amazon's platform sellers, the independent merchants who depend on Amazon to sell and deliver their goods.
This means that it costs Amazon itself nothing to get the merchandise it sells to your door: more than 100% of the cost of operating the fulfillment side of Amazon is covered by the fees it extracts from its independent sellers (who compete with Amazon in many instances, and for whom delivery is a cost center, not a source of profit).
Then there's AWS, Amazon's cloud business. This is another extraordinary success story: every company needs servers, and that's especially true of an e-commerce company like Amazon. By building more servers than it needs, Amazon transformed its own data infrastructure from a cost center into another profit center. Amazon's customers – many of whom are also its competitors – pay Amazon so much to rent space on its servers that Amazon gets its own (prodigious) computing for free, and realizes a profit on top of that.
Taken on their own, these two facts constitute an extraordinary business story: one of the largest corporations in the history of the world has converted its two largest cost centers into profit centers, and those profits are substantially generated by extracting payments from the company's own competitors!
Amazon's logistics and cloud computing are extraordinary, but they are eclipsed by the company's most profitable line of business, which is payola.
"Payola" is a word that old people like me just barely have context for and for anyone under fifty the word is likely a mystery, so a brief explanation is in order.
"Payola" comes from a massive 1950s scandal over bribes that record labels paid to radio DJs and station managers to play their music. Radio stations were given the use of a scarce and precious resource – exclusive control over slices of the only electromagnetic spectrum in the universe – and were expected to program material that the American public would find enjoyable, edifying and educational. In this system, radio stations were expected to make shrewd guesses about the music the public would enjoy the most, and play that.
Because the selection process for the music that DJs played on the American public's spectrum was completely opaque, and because those selections could make fortunes for record labels, the system was ripe for corruption. Labels slipped literal envelopes full of cash and drugs ("payola") into the hands of DJs, station managers and owners, bribing them to turn songs into "hits" by cramming them into Americans' ears. The biggest predictor of a radio hit wasn't whether people liked the song so much that the stations rushed to play it, but rather, how much the labels were willing to spend in bribes to get their song played:
https://en.wikipedia.org/wiki/Payola
This was a bad system all around. The American public got worse music. Musicians' own royalties were eroded by the label accountants' practice of charging off bribes to "promotions" they deducted from artists' royalty statements. Radio stations sucked. Labels bid away each other's margins, depriving themselves of operating capital to find and record new music and starving them of free cash flow to pay to musicians, employees and shareholders. As with every instance of corruption, this was a system of concentrated gains and diffuse losses, which is why it continued for so long (decades!) and got so bad before anyone took action to end it.
Amazon's payola isn't about radio play – it's about search. When you search Amazon, the top results do not represent Amazon's best guess about what product will best match your query: rather, Amazon auctions off those top results to its platform sellers. Amazon's search results reflect who paid the biggest bribe, not who has the best product.
To pay for those bribes, platform sellers have to raise prices. Amazon helps them do this, by imposing a "most favored nation" clause on its sellers that requires them to sell on Amazon at a price that matches or beats the price charged everywhere else (Target, Walmart, a mom-n-pop, or the factory store):
https://pluralistic.net/2026/02/25/most-favored-nation/#price-fixing
Thus, Amazon imposes an economy-wide tax on nearly every product you buy. Amazon's junk fees average 51-60% of the purchase price of the things you buy there, and because Amazon has captured a supermajority of the richest 10% of Americans (who have almost all pre-paid for a year's shipping through Prime), every seller must sell on Amazon, or forego any hope of selling to most of the country's most prolific shoppers.
Any seller who signs up for Amazon is agreeing to turn over the majority of their sales income to Amazon, and any seller who raises prices to recoup those sums, must raise prices everywhere, at every retail outlet in the country.
AI has made Amazon much better at enforcing Most Favored Nation terms, because AI is actually pretty good at parsing competitors' websites and finding instances of discounting, which Amazon instantaneously punishes by relegating the sellers' product listings to page umpty-billion of Amazon's search results.
There are plenty of junk fees that go into Amazon's 51-60% rake. A large slice comes from fees Amazon charges for access to its (very profitable) logistics system. Failure to use Amazon's fulfillment system also relegates your listings to the dregs of Amazon search results, so sellers pay a massive premium to have their parcels delivered by Amazon, to the exclusion of cheaper alternatives that are just as fast and reliable. That's why Amazon fulfillment is so profitable!
While the Amazon tax is extracted through several types of junk fee, the most profitable junk fee of them all is Amazon's search payola. In fact, search payola is the most profitable business that Amazon operates, full stop.
Payola accounts for more of Amazon's profits than anything else the company does. It's more profitable than all the things Amazon sells directly. It's more profitable than AWS, Amazon's industry-leading cloud service.
Amazon has created a system where the most sales go to the companies that pay the highest bribes, and those companies pass the cost of those bribes onto their customers. The first item on a typical Amazon search results page is 29% more expensive than the best match for your search. The top row is 25% more expensive. The best result is usually on the second screen, somewhere around the 17th position:
https://pluralistic.net/2023/11/03/subprime-attention-rent-crisis/#euthanize-rentiers
Amazon actively helps its biggest bribers close the sale. Amazon has lots of "comparison shopping" systems built into the service, but one comparison tool is conspicuous by its absence: an "apples to apples" tool that lets you compare unit prices. Amazon's most prolific bribe-payers package their goods in weird quantities, selling everything from batteries to t-shirts to shampoo in larger or smaller quantities than their competitors. Sorting your search results by price doesn't actually tell you who's got the cheapest price per item, because the company with the cheapest AA batteries might be selling a smaller quantity of batteries at a higher price per battery.
Per-unit pricing is standard in retail. Indeed, if you go into a(n Amazon-owned) Whole Foods, you'll find per-unit pricing on the shelf tags, telling you how much the product costs per ounce or fluid ounce. Amazon clearly understands why shoppers would want to compare unit pricing, but offering a per-unit sort option to its search would make the bribery racket a lot less effective, because searchers could just sort by unit price and find the best bargain.
Let me remind you: payola is Amazon's single largest source of profits. When I was researching Enshittification, Amazon's take from payola was in the mid-$30 billions. A year later, when I did tour stops with Tim Wu (who was promoting his excellent book The Age of Extraction), I learned that this number had climbed to more than $50 billion. This year, it's on track to top $80 billion.
Amazon calls this bribery system an "advertising" product, but it's not "advertising" in the sense of the ads that Amazon's platform sellers might have once placed in the local newspaper. It's payola, more akin to the practice of packaged goods companies buying end-caps and whole shelves in the grocery store (a practice that is, in its own way, every bit as corrosive, though no grocery store has Amazon's economy-wide chokehold).
But there is a way in which this payola can be compared to advertising: it competes with advertising. Back in the old days, before a series of K-shaped recoveries created a vast chasm between America's haves and have-nots, before Amazon captured the majority of well-off American households with Prime, people shopped in lots of places, and in those days, companies advertised in publications, not on Amazon. Websites, newspapers, and newspaper websites made billions from those ads. Amazon's payola scheme (along with Google, Facebook and other tech monopolists) has captured almost all of that money.
As Tim Wu points out, the money Amazon makes from payola exceeds the advertising revenue received by all the newspapers in the world by 300%. Alongside that number and its implication for the news media, Jeff Bezos buying the Washington Post and turning its editorial page into a sewer of shitty Ayn Rand fanfic barely registers.
This is pure enshittification. Of all the ingenious, innovative ways that Amazon came up with to make money, the most successful is a scam that makes everything you buy more expensive even as it reduces the profits of the companies you're buying from. It's another example of corruption: a system of concentrated gains and diffuse losses – and once again, it's the most profitable thing Amazon does.
And then…Amazon made it worse.
You know how people like to say, "If you're not paying for the product, you're the product?" It's bullshit. The "advertisers" who bribe Amazon for top search placement are the customers here, they're "paying for the product," and they are getting reamed. I don't just mean they're getting screwed by being forced to shell out payola – I mean that Amazon is cheating them on that payola!
Remember: Amazon doesn't just sell search placement; they auction it. Every time you run an Amazon search, the company conducts a special kind of auction called a "sealed-bid second-price auction" (SBSPA):
https://en.wikipedia.org/wiki/Vickrey_auction
Under an SBSPA, bidders secretly tell the auctioneer the very highest price they're willing to pay. The auctioneer then charges the highest bidder a price equal to the second-highest bid, plus one cent.
This may seem unnecessarily complicated, but it's actually a clever solution to one of the major problems with traditional, "open call" auctions (where bidders call out the prices they're willing to pay until one bid emerges victorious). Say you're at an open call auction where the top bid is $10. You can call out $11, and then the other person will call out $12, and so on and so on. It's tedious and time-consuming. That's bad enough when you're at an estate auction that's unloading hundreds of items, but it's untenable for an eyeblink auction meant to determine search results that the user expects to get in an instant.
In physical auctions the top bidder often clobbers other bidders with a big increase – going from $10 to $50, say. This can end the auction quickly, but it means that the high bidder often overpays for their purchase.
In an SBSPA, every bidder enters their highest price, but none of the other bidders know what that price is. This encourages everyone to name their true highest price, but it protects the top bidder in the instance in which they are willing to pay a much higher price than anyone else.
Say you're that person who raises the bidding from $10 to $50 – you have no way of knowing whether the other bidders would have dropped out at $15 or at $45. If you were the only person who was willing to pay more than $15 for the item, you've just vastly overpaid (by $34.99). But in an SBSPA, you name your true price, but you only pay the price you would have paid if you'd gone through the tedious, expensive, time-consuming process of an open call auction.
Amazon's search auctions are SBSPAs. A merchant tells Amazon the maximum they're willing to pay to be at the top of the search results for a given query, but they pay a price equal to the second-highest bid, plus one cent. This lets auctions run so quickly that they can be used as the basis for ordering a search results page.
That's how it's supposed to work, anyway. The FTC and 22 states just filed a suit against Amazon because Amazon was cheating on its own SBSPA process:
Over the past 7 years, Amazon has been secretly charging the winning bidder an amount equal to their own sealed bid, not the amount that the next-highest bidder was willing to pay (plus a penny):
https://gizmodo.com/ftc-sues-amazon-for-allegedly-duping-advertisers-2000805199
According to the suit, Amazon did this 80% of the time. That is tens of billions of dollars Amazon extracted from platform sellers, who passed those costs onto you, and onto every other retailer in the country (thanks to AI-enforced Most Favored Nation policies).
Amazon's defense is that this is all a big misunderstanding. Platform sellers just didn't understand how a SBSPA worked. Amazon has a special kind of SBSPA where they could unilaterally and secretly charge the winning bidder the maximum price they'd pledged, if, in Amazon's judgment, the closing price for the auction was below "the true market value of the ad placement":
This is darkly hilarious. The whole point of an auction is to determine "true market value." That's why neoclassical economists worship auctions as the world's best form of "price discovery" and why economics Nobels are awarded for "auction design":
https://en.wikipedia.org/wiki/Auction_theory
The definition of "true market value" is "the closing price in an auction." Amazon claiming that it secretly jacked people because the auction generated a price that was "below the true market value" of an ad tells you that the whole business is a sham. The point of Amazon's payola scheme is only and ever a way to parasitically extract the maximum amount a platform seller is willing to part with, and by running a fake SBSPA, Amazon was able to trick its customers into revealing those maximum prices.
Cheating on a bribery scheme is a mood. This isn't just enshittification, it's enshittification inception. Amazon managed to enshittify their own enshittification!
This case was brought by Trump's FTC, which means that Amazon can get out of it by paying a chud podcaster to tweet at the president and he'll order them to drop it, just like he did with Ticketmaster:
https://pluralistic.net/2026/02/13/khanservatives/#kid-rock-eats-shit
But – just as with Ticketmaster – the feds aren't the only parties to the suit. With 22 AGs ("Aspiring Governors") on the suit, there's a chance this will go to trial. We might even learn the identity of the inventor of this enshittification-squared gambit, a veritable Louis Pasteur of enshittification. Assuming that person doesn't go to prison, the Sveriges riksbanks pris i ekonomisk vetenskap till Alfred Nobels minne can give that sloshing, ambulatory pile of hot liquid garbage a Nobel Prize in Economics.
(Image: Steve Jurvetson, CC BY 2.0, modified)
US court rules Google will not have to sell ad exchange after losing antitrust case https://arstechnica.com/gadgets/2026/09/us-court-rules-google-will-not-have-to-sell-ad-exchange-after-losing-antitrust-case/
Minding the Gaps in Surveillance Pricing Reform https://economicpopulist.substack.com/p/minding-the-gaps-in-surveillance
Zack Polanski seeks to stand for by-election in former PM Starmer's seat https://www.bbc.co.uk/news/articles/cge41ee40vwo
What Are We Supposed to Call This? https://www.usermag.co/p/what-are-we-supposed-to-call-this
#25yrsago Electrolite relaunches https://web.archive.org/web/20010927195348/http://www.panix.com/~pnh/electrolite.html
#25yrsago How to play Mafia https://web.archive.org/web/20011113011546/http://www.stud.ntnu.no/studorg/mafia/
#20yrsago How Wikipedia entries get written http://www.aaronsw.com/weblog/whowriteswikipedia
#5yrsago Proctorio's awful reviews disappear down the memory hole https://pluralistic.net/2021/09/04/hypervigilance/#radical-transparency
Warsaw: Romana i Jana Podoskich, Sep 6
https://wydarzenia.phub.pl/events/0ee0e198-f843-423a-890f-c84ff50a46c0
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
How Tech Platforms Took Over the Economy (Dystopia Now)
https://sites.libsyn.com/566555/enshittification-and-reverse-centaurs-cory-doctorow-on-how-tech-platforms-took-over-the-economy
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

What if post-Trump America is even worse?
I know, it's tempting to think of Trump as a cause, rather than an effect – as an aberration who dragged America into fascism. Trump is exceptional, but the thing that makes him exceptional isn't his corruption, recklessness or cruelty. What makes Trump exceptional is his ability to cajole, intimidate and flatter America's most corrupt, reckless and cruel people into a coalition.
These people hate each other. Nick Fuentes drifts off to sleep every night furiously fantasizing about turning Stephen Miller into a lampshade. Laura Loomer just got ICE to intervene in a Twitter feud by having a guy she dislikes violently arrested, shackled at wrist and ankle, perp-walked, and then shuffled from location to location so that he couldn't meet with his lawyer before being deported:
They steal like crazy, get each other locked up, and gorge themselves on mind-altering supplements and peptides they buy from random podcast chuds. They are fantastically paranoid, marinated in conspiracy theories, and perennially high on their own supply: all that bullshit about "great replacement," "China is making America hate data centers" and "antifa is a terrorist organization"? A lot of them genuinely believe it. It's not just ghost stories they made up to scare cognitively compromised tube-feeding Fox News addicted rubes. Trumpland is full of actual, functioning adults in positions of real power who periodically go into the bathroom, turn off the lights, hold a flashlight under their chins and scare themselves silly by saying "Aaaaaaaaaantiiii-faaaaaaaaaa" into the mirror.
Donald Trump did not conjure these people out of thin air. They've been lurking in America since its earliest days. They worship authoritarian criminals:
https://abc30.com/post/roger-stones-tattoo-of-nixon-goes-viral/5107047
January 6 wasn't the first presidency they tried to steal, it's just the first one they got punished for:
https://en.wikipedia.org/wiki/Brooks_Brothers_riot
They commit brazen crimes in office that could land them in prison for the rest of their lives, and therefore can't afford to lose power, ever:
https://www.propublica.org/series/supreme-court-scotus
Trump didn't invent these creeps, he just emboldened them. If Reaganomics was capitalism with the gloves off, then Trumpismo is Reaganism with the mask off:
So what happens when Trump strokes out while watching Kid Rock wrestle a Hulk Hogan impersonator in a televised barbed-wire cage match on the White House lawn that one of Trump's cronies has exclusive pay-per-view rights to? I mean, it's possible that the Democratic leadership will step up and insist on some form of regular order in the succession to Vance, but come on. These are the tiny "Down with this sort of thing" ping-pong paddle people:
https://www.truthdig.com/articles/ping-pong-paddles-to-a-gun-fight/
It is more likely that Vance – a weak, unimportant charisma-vacuum who is loathed by all of Trump's factions – will end up presiding over a far more chaotic period in American governance than anything that happened under Trump. That could mean ICE leaders ordering mass graves dug in the centers of America's largest cities, drunken generals invading random countries, podcasters declaring "The Purge" with brackets sponsored by Kalshi.
This isn't the first time in living memory that this has happened. In 1991 the Soviet Union collapsed, virtually overnight, and the fragile threads that bound its feuding, corrupt regional bosses all snapped, leaving behind nuclear-tipped mafia states. This was a chaotic and frightening time for the people whose governments had simply winked out of existence – but it was also terrifying for the rest of the world, who scrambled to secure those nukes before they could end up in the hands of "non-state actors":
The Soviet Union had some deeply dysfunctional leadership politics to be sure, but at least the people involved were beholden to various power blocs who had an interest in keeping things going. As the geopolitics wonks say, "they were playing an iterated game," where some losses had to be tolerated so that the losers could try to win the next time around.
But there are plenty of people who weren't (and aren't) playing iterated games – people who are even more unhinged, more reckless, more short-termist than the maniacs who filled the world with nuclear weapons. These people don't necessarily care if civilization or even the human race persists if they can't get their way. The thought of them running around with these "weapons of mass destruction" ratcheted up the half-century of stark nuclear terror that had preceded the USSR's collapse to new heights.
Which brings me to the post-Trump internet. Trump isn't the first president to figure out that the internet could be weaponized for geopolitical ends. As the Snowden disclosures showed, there has been a longstanding bipartisan consensus that the internet is a great tool for American surveillance, conducted against friend and foe alike.
But Trump is the first president to openly, directly recruit American tech companies to simply brick foreign officials who displease him, starting with the Chief Prosecutor of the International Criminal Court, who lost his Office 365 and Outlook accounts in retaliation for swearing out a genocide warrant for Netanyahu:
https://www.justiceinfo.net/en/156691-how-sanctions-can-weaponize-us-tech-against-the-icc.html
And then Microsoft obliged Trump again, attacking the Brazilian judge who sentenced Jair Bolsonaro to prison over his unsuccessful coup.
America's tech giants have fully, irrevocably fused with Trump. They donated to his campaign. Their CEOs each paid $1m out of their own pockets to sit behind him on the inauguration dais. Google provides location data for Trump's racist pogroms. Microsoft provides the administrative tools to carry them out. Oracle provides the databases. Apple blocks apps that warn its customers when they're about to be snatched:
https://pluralistic.net/2025/10/06/rogue-capitalism/#orphaned-syrian-refugees-need-not-apply
In exchange, Trump got Canada and the UK to ditch their plans to levy a 3% tax on American tech giants; he got the EU to gut its privacy laws; he sanctioned EU officials who tried to regulate social media; and he's told the tech companies to go through EU officials' private messages, looking for anti-Big Tech partisans whom he will ban from ever entering the USA:
Big Tech has proved that its only principles are not paying taxes, invading your privacy, and not being broken up by antitrust enforcers:
Tech companies will do anything for any leader who can guarantee those outcomes. There's no capitulation too petty and stupid for Big Tech:
https://people.com/apple-maps-joins-google-approving-trump-lake-america-change-12074262
America no longer has allies or trading partners. America has rivals and enemies. Trump's coalition wants him to steal Iran, steal Venezuela, steal Cuba, steal Alberta, steal Canada, steal Greenland. They want him to help Israel steal Palestine and Lebanon. And as Trump considers this program of imperial conquest, he has started to tinker with one of the most devastating geopolitical weapons the world has ever seen: tech shutdowns.
If Trump wants Greenland, he can just order Microsoft to switch off Office 365 for the country and every ministry and significant firm will be shuttered in an instant, along with many households:
https://pluralistic.net/2026/04/04/digital-subjugation/#greenlands-next
He can order Apple and Google to shut off all of Denmark's phones. He can order John Deere to shut off all their tractors:
https://pluralistic.net/2022/05/08/about-those-kill-switched-ukrainian-tractors/
(One thing we don't need to worry about is Trump ordering OpenAI and Anthropic to switch off all of Europe's chatbots – sure, he could do that, but if he did, nothing important would break:)
https://pluralistic.net/2026/06/18/their-trillions-our-billions/#eyes-on-the-prize
As weapons of mass destruction go, nukes are pretty stupid. The big ones destroy the territory you're trying to conquer and leave behind an uninhabitable radioactive wasteland. They send clouds of nuclear fallout swirling around the globe, potentially killing you or your allies. 80 years into the Nuclear Age, the best anyone's come up with is a neutron bomb, which only kinda renders territory uninhabitable while still killing everyone with massive radiation blasts.
Compared to nukes, tech shutdowns are amazing. Thanks to Big Tech, America – and only America – can brick almost any country on earth, shutting down its administration, agriculture and industry without firing a single shot. The only thing that prevented this from happening was an American elite bloc that was playing an iterated game and saw more benefit from sharing in Big Tech profits as they looted and spied on the world, as opposed to grabbing territory while scaring the world into breaking all land-speed records to ditch American tech and pursue meaningful digital sovereignty.
Trump's chuds and freaks are not bound by these constraints. They're perfectly happy to do Gunboat Diplomacy 2.0: Cloud Diplomacy, where everything from your smartphones to your payroll records can be seized at the click of a mouse, and your country had better fall in line. And Trump is a sick, frail old man, who is not long for this world. When he goes, all bets are off: America will be at the mercy of warring factions who will deploy the coercion and bribery that turned Big Tech into Trump's geopolitical weapon in order to achieve their own purposes – which might well be even stupider, crueler and more unhinged than Trump's.
There's only one way out of this mess: the rapid disassembly of the American internet and the rapid creation of a post-American internet, one built on open, auditable, sovereign digital public goods, internationally built and maintained:
https://pluralistic.net/2026/01/01/39c3/#the-new-coalition
In its own way, the creation of this post-American internet is as urgent and as global as was the creation of the covid vaccines. But whenever I speak to powerful people about this, they ask the same question: "What if this makes Trump mad?"
This represents a grave failure to take this crisis seriously. Trump doesn't need to be "mad" to attack your country. Trump attacked Canada over its wildfires, accusing Canada of polluting America's air:
https://www.cbc.ca/news/politics/us-complaints-trump-widlfire-smoke-9.7274466
But even if Trump never gets mad at you, that's no guarantee of safety. Trump is not long for this world, and his death or incapacity is no guarantee of the restoration of a "normal" America. And even if America finds its way to "normal" after Trump, that's no guarantee that it will stay normal. The armed, organized maniacs who have seized power in America and who are cheering him on as he rampages all over the world, kidnapping leaders and dropping bombs on schoolchildren are not going to dig a hole, crawl inside it, and pull the dirt down on top of themselves.
But let's say that we find ourselves in the best of worlds, where American fascism is comprehensively defeated and the country embarks on a years-long program of denazification:
https://pluralistic.net/2026/02/10/miller-in-the-dock/#denazification
Even in that amazing future, the world should still race to build a post-American internet. The world should have built that internet after the Snowden revelations. That ghastly failure created the Trumpian internet. If the post-Trump internet isn't a post-American internet, then it'll only be a matter of time until the next crisis comes along, and the coming years will give Big Tech even more chances to worm its tendrils into the world's governments, firms and households, making that crisis be even harder to survive. The best time to act was 13 years ago, after Snowden. The second best time is now.
Barrister's powerful speech at Filton Trial reminds jury of its right to defy judge https://jonathancook.substack.com/p/barristers-powerful-speech-at-filton
So the People May Sing. The Anthem Still Goes to Trial. https://copyrightlately.com/corretjer-brown-public-domain-boricua-en-la-luna/
Neo-ZIRP Slop in the Post-ZIRP Era https://superbowlstevehunt.substack.com/p/neo-zirp-slop-in-the-post-zirp-era
With the backlash to data centers, Flock and AI glasses, a mass opposition to big tech is underway. Silicon Valley is in denial. https://www.bloodinthemachine.com/p/with-the-backlash-to-data-centers
#25yrsago Barnum & Bailey hired an ex-CIA spook to destroy a critical journalist https://web.archive.org/web/20010913192931/http://www.salon.com/news/feature/2001/08/30/circus/print.html
#20yrsago Wired article about Wikipedia is on a editable wiki https://web.archive.org/web/20060901030941/http://www.socialtext.net/wired/index.cgi
#20yrsago Singapore will have nationwide WiFi by 2007 https://web.archive.org/web/20060901191656/http://news.com.com/2100-1039_3-6110189.html
#5yrsago Twitter Arguments https://pluralistic.net/2021/08/29/twitter-arguments/
Warsaw: Romana i Jana Podoskich, Sep 6
https://wydarzenia.phub.pl/events/0ee0e198-f843-423a-890f-c84ff50a46c0
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
Edmonton: Elbows Up (Edmonton Public Library), Sep 28
https://www.epl.ca/blogs/post/elbows-up-with-cory-doctorow/
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Calgary: Wordfest, Oct 8
https://wordfest.com/2026/show/wordfest-presents-cory-doctorow-2026/
Winnipeg: McNally Robinson, Oct 9
https://www.mcnallyrobinson.com/event-18991/An-Evening-with-Cory-Doctorow
Vancouver: Read, Resist, Repair, Rejoice (Vancouver Writers Festival), Oct 19
https://writersfest.bc.ca/festival-event-2026/01
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: Life After AI (Vancouver Writers Festival), Oct 22
https://writersfest.bc.ca/festival-event-2026/46
Ottawa: Life After AI (Ottawa Writers Festival), Oct 24
https://writersfestival.org/event/life-after-ai
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

After half a century of neoliberalism, we are all drenched in capitalism's established religion, the worship of property rights. We are so marinated in property worship that even capitalism's critics frame their critiques in "property talk," to the exclusion of other, more important rights, like human rights, labor rights and privacy rights.
To do this is to surrender before the battle even starts. Critics lose when they allow oligarchs and their apologists to choose a battlefield where they have a nearly unbeatable advantage.
Take privacy: privacy is a human right, not a property right. Human rights aren't for sale. You can't sell yourself into slavery, you can't sell your kidneys to make the rent. If privacy is a property right – one that can be traded away – then Facebook's industrial-scale privacy invasions are actually fine, since you "traded" your privacy to Mark Zuckerberg in exchange for the privilege of talking to your friends.
Some self-styled critics of tech monopolists say that the answer to Facebook's privacy invasions is to force the company to pay for your privacy with cash, rather than services:
https://www.wired.com/story/opinion-andrew-yangs-plan-to-pay-you-for-your-data-doesnt-add-up/
This is ideological capture in its purest form: the "data dividend" that Facebook would owe you under this system amounts to a few dollars per year. For wealthy people, the sums would be trivial, while working people, who've been on the downward leg of every K-shaped recovery for a quarter century, who've maxed out their credit cards and re-mortgaged their homes and drive Uber on the weekends to make rent, would have to subject themselves to ongoing surveillance.
That surveillance is already used to determine the highest price those working people will pay – companies like Plexure inform fast food places when you've just gotten paid so they can tack an extra dollar onto your breakfast burrito in the app:
https://pluralistic.net/2026/04/30/something-must-be-done/#there-ive-done-something
Being forced to sell your privacy doesn't just raise the prices you pay, it also lowers the wages you earn. The same people who can't afford this "pay or privacy" system have their private data used to calculate the lowest wage they'll accept for each ride on those weekend Uber shifts:
https://pluralistic.net/2024/12/18/loose-flapping-ends/#luigi-has-a-point
In other words: not being able to afford privacy will result in you having even less disposable income, which will mean that you'll have to sell even more of your privacy. Lather, rinse, repeat.
But even the wealthy people who can afford to forego the pittances Facebook and others offer in exchange for their private information will find privacy elusive. That's because private information isn't a "rival good" – a thing only one person can own at a time. The fact that your mother is your mother "belongs" to both you and her, as well as your grandparents, your father, your siblings and your kids. The fact that you don't sell your family tree to a tech company won't stop all those other people from selling it on – as anyone whose foolish relations handed their genome over to 23andme can attest:
https://www.npr.org/2025/03/24/nx-s1-5338622/23andme-bankruptcy-genetic-data-privacy
In the property religion, the way you can tell if something is valuable is if it has a high price. Property cultists insist that the problem with privacy is that our privacy is being sold too cheaply. They're wrong: private information isn't "mispriced" – it shouldn't be priced.
Human beings are the most valuable things in our world and they are literally priceless. Murder isn't "theft of life." Rape isn't "theft of sex." While insurers and civil courts have ways of calculating the "price" of an injury or violation, great care has been taken over the centuries to ensure that this does not turn human beings into commodities. You can't buy a "murder offset" that lets you kill people provided you pay into a fund that saves a human somewhere else:
https://pluralistic.net/2021/04/14/for-sale-green-indulgences/#killer-analogy
Human beings are too valuable to be priced. We have an entire, sui generis way of balancing the conflicting interests of human rights. My daughter and wife have rights over me, I have rights over them, and when those rights come into conflict – say, if my daughter believes I can no longer care for myself and wants to put me in a care home – the process for resolving that conflict isn't an auction:
https://www.theguardian.com/technology/2008/feb/21/intellectual.property
Your kids aren't your property. In fact, all the most important relationships in your life are non-market. Doctors have patients, not customers. Any time a doctor calls you a "customer" they are demoting you. A doctor doesn't sell you health. You have rights as a patient that far exceed the rights accruing to a mere customer. Same goes for other professions: Teachers have pupils, librarians have patrons, lawyers have clients. "Customer" is a demotion from all of these.
As every "user agreement" you've ever clicked through demonstrates, Big Tech loves to have everything defined in property terms – and so does all big business.
Take the fight over scraping for AI. You might think that this is a fight over the economic rights of creative workers – certainly, my fellow creative workers treat it as such. But because this debate is being framed in terms of property rights, rather than labor rights, this is a fight that workers are set up to lose.
The tell here is how the media companies – who have been eroding the wages of creative workers for decades as they consolidated into a curdled, inbred oligopoly – describe the AI companies' scraping: as an unlicensed taking. Mitch Glazier, the $1.4m/year CEO of the Recording Industry Association of America issues press releases decrying AI training for image generators without negotiating a license fee first:
https://pluralistic.net/2026/03/03/its-a-trap-2/#inheres-at-the-moment-of-fixation
Who's Mitch Glazier? Oh, just a former Congressional staffer who was drummed out of the Capitol Building after he snuck a clause into must-pass legislation that would have transferred hundreds of millions of dollars from musicians to record labels, who was then immediately hired as the CEO of the record industry's largest lobbying group:
https://www.eff.org/deeplinks/2013/12/tpps-attack-artists-termination-rights
Mitch Glazier – and the businesses he represents – aren't opposed to AI replacing artists. They're opposed to AI replacing media companies. Remember the Hollywood writers' strike? The proposal to replace screenwriters with chatbots didn't come from OpenAI, it came from Disney, Warner, Universal and other companies who claim that AI training is "theft."
If AI training is "theft," then it can be cured by making a purchase, something that the AI companies can easily afford, thanks to the hundreds of billions of dollars they have been given by the world's richest investors, who are the high priests and cardinals of the property religion.
The Hollywood writers are the only workers in the world who have successfully beaten back the use of AI in their workplace, and they didn't do it by making recourse to property rights. The Writers Guild is a union and it enjoys a weak form of "sectoral bargaining" (where all the workers in a field bargain with all the businesses at once) called "multi-employer bargaining":
https://pluralistic.net/2023/10/01/how-the-writers-guild-sunk-ais-ship/
The Hollywood writers' strike was an unqualified victory for the writers, who defended their labor rights to co-determination when it came to the use of new tools on their jobsite. Under the terms of their hard-fought contract, screenwriters don't have to use AI, but they can if they want. For example, writers on a long-running sitcom might train an AI with every script in the series' history, so they can ask a chatbot continuity questions as they beat out a new season of the show. But they don't have to do this if they don't want to, and even if they do, neither their wages nor their headcount can be reduced.
The media companies insist that scraping is a copyright violation, that it's "theft." As a matter of law, this is far from obvious or settled: the process of making transient copies of many works, performing mathematical analysis on them, and then publishing that analysis as software is not obviously a copyright violation, and anyone who claims otherwise doesn't understand copyright:
https://pluralistic.net/2023/02/09/ai-monkeys-paw/#bullied-schoolkids
Worse: by demoting a labor rights issue to a mere property rights issue, AI critics are setting workers up to fail. Say the issue with AI training really is mere copyright. If that's so, the media companies who want nothing better than to pauperize creative workers can amend their standard contracts so that any worker who does business with them must irrevocably transfer their "AI training rights" to the company.
Then, that company will absolutely, 100% license those rights to an AI company to create a model designed to replace that worker. The company will get paid for the training, and the resulting model will come with "guardrails" to stop other media companies from using proprietary data to compete with it.
This is the story of the past 50 years of copyright expansion: every new copyright we've created "to help artists" was scooped up by their bosses, who grew more powerful and were able to demand more concessions from those artists, who were therefore poorer and thus needed more copyrights to help them (lather, rinse, repeat):
https://pluralistic.net/2026/08/18/enron-corpus/#sign-here
If creative workers' AI fight is merely a copyright fight, then that fight can only determine whether media companies or tech companies will get the biggest portion when those workers are devoured by corporations. Only a labor rights fight can take creative workers off the menu altogether.
Treating AI training as "theft" creates harms whose blast radius extends well beyond creative workers' livelihoods. Scraping is a hugely beneficial activity. If scraping – taking a vast corpus of copyrighted works without permission – is theft, then every search engine is a crime, unless it can afford to license "search indexing rights" from every site on the internet.
There's exactly one company that could pull that off: Google, a rapacious tech monopolist that is – not coincidentally – one of the leaders of the movement to beggar every creative worker. We will not improve the world, the internet, or creative workers' lives by ensuring that the last search engine anyone ever creates is Google.
Remember our earlier discussion of how privacy violations are weaponized to make poor people even poorer, by depressing their wages and raising prices based on inferences about their economic desperation? Our best weapon for fighting this practice is scraping, because that's how we catch corporations changing prices and wages based on surveillance data:
https://pluralistic.net/2023/09/17/how-to-think-about-scraping/
Scraping is how we produce evidence of the changes that powerful people are making to the world around us. Do you want to know whether Mark Zuckerberg or Elon Musk are downranking content critical of Trump and Big Tech and pumping racist and conspiratorial posts into the resulting void? You'd better hope you can scrape the feeds they cram into billions of people's eyeballs. Same goes for keeping track of genocide apologists, data-center astroturfers and ICE cheerleaders who've flooded Tiktok ever since Trump stole it and handed it over to his creepy billionaire pal Larry Ellison.
Making copies of that stuff isn't theft. It's not a copyright violation. Not even if you do it to billions of works. Not even if it's bad for the companies whose feeds you're capturing. Not even if it's bad for the dark money groups who funded the content.
Sure, if you do this carelessly or recklessly, you can end up violating someone's labor rights, or privacy rights, or human rights. And because those frameworks aren't based on the sanctity of property rights, they can be used to protect these important rights without giving corporate America the right to have you fined or arrested for documenting their takeover of the America.
The people who keep track of this stuff are worried about being fined or arrested. Ethan Zuckerman, one of America's foundational internet scholars, has just accepted Canadian government funding to move his lab from UMass to McGill in Montreal:
https://ethanzuckerman.com/2026/08/27/my-personal-contribution-to-the-us-canada-trade-war/
Zuckerman studies platform power: "using data to answer hard questions about social media, search engines and AI tools." He leads a team that is documenting exactly, precisely how tech companies collude with authoritarians to spy on us, manipulate us, and control us. And his methodology is something called "unpermissioned research," which is what academics call scraping:
https://www.techpolicy.press/ai-companies-threaten-independent-social-media-research/
"Unpermissioned research" seeks to circumvent limits that platforms establish specifically to stop outsiders from learning how they operate. When you're doing unpermissioned research, you try to get around rate limits, query throttles, and other measures that platforms use to block others from mapping their extent and documenting their conduct.
"Unpermissioned research" isn't a free-for-all. Universities have ethical rules designed to protect the privacy rights and other human rights of research subjects, and because these aren't property rights, they can be balanced against the socially beneficial outcomes of research. Universities can get this wrong, of course, but when they do, it's not theft. It's a human rights violation, a privacy violation, a labor violation.
If you want to know how AI companies are trying to destroy creators' livelihoods, you have to scrape the AI companies. You can't ask companies for permission to gather information that might be used to destroy them – they'll just say no. If taking information off the internet without permission is "theft," then gathering information by scraping AI companies is also theft.
Sometimes a tech company will set up a "research portal" that supposedly obviates the need to scrape by putting all the relevant information in one convenient place. That's what Facebook did in the wake of the 2016 election, when it was widely condemned for publishing paid political disinformation. But Facebook's official research portal omitted vast amounts of paid political disinformation, something we only know because NYU set up a scraping project called Ad Observer that documented the discrepancy:
https://pluralistic.net/2021/08/06/get-you-coming-and-going/#potemkin-research-program
Facebook used legal threats to kill Ad Observer, and then…they killed their official research portal, too:
https://pluralistic.net/2021/07/15/three-wise-zucks-in-a-trenchcoat/#inconvenient-truth
Zuckerman is one of dozens of leading US academics who are relocating their labs and teams to Canadian universities, citing fear of political interference from the Trump regime:
The Canadian government has committed $504m to the project. Some of that research will help Canada develop new green energy, and some of it will help Canada make important medical breakthroughs. But Zuckerman's research has a special place in the portfolio of Canadian research projects, because – thanks to scraping – it is a leading source of information about how Trump's tech companies are waging war on the American people and the world.
Scraping isn't theft of data, just like murder isn't theft of life. Scraping can be harmful, and we can create laws and social regimes and ways of talking about those harms that don't give authoritarian governments and vast multinational corporations the right to decide who can document and analyze their conduct.
Take Wikipedia: the project exists solely to organize and disseminate information, for free, to everyone in the world. Wikipedia is among the most important parts of the internet, and one of the most positive developments of the 21st century. The entire project is licensed under a generous Creative Commons license that encourages unlimited commercial re-use of its contents. Even if you think scraping copyrighted works is theft, scraping Creative Commons Attribution 4.0 works is unquestionably not theft.
But Wikipedia is being hammered by AI scrapers, which are operating so aggressively that they threaten the project's ability to keep its servers online. Wikipedia has an AI problem, but that AI problem isn't "theft" – it's denial of service, the aggressive act of intentionally or recklessly flooding a server with so much traffic that it crashes.
If you've been lured into a cultlike worship of property rights, this seems like a contradiction. But once you relegate the relatively unimportant matter of property rights to its correct station, you can see – and reason about – the universe of rights that are far more important than mere property.
All it takes is realizing that there are far worse things you can do with information than "stealing" it.
(Image: Bearas, CC BY-SA 4.0, modified)
New Twitter launches, says Musk’s X gave up the name https://arstechnica.com/tech-policy/2026/08/new-twitter-launches-says-musks-x-gave-up-the-name/
For The Economist, Mentioning Workers’ Interests Is Heresy https://jacobin.com/2026/08/acemoglu-economics-ai-automation-working-class
How Youth and Educators Can Fight Enshittified Tech https://clalliance.org/blog/how-youth-and-educators-can-fight-enshittified-tech/
Stalking the Wily Hacker: 40 years later – Cliff Stoll https://www.youtube.com/watch?v=656058JxTM0
#25yrsago NYT says ebooks don't exist, fails to mention thriving ebook pirate scene https://www.nytimes.com/2001/08/28/business/forecasts-of-an-e-book-era-were-it-seems-premature.html
#25yrsago Parking tickets waived in exchange for written apologies https://web.archive.org/web/20010826013513/http://www.thesmokinggun.com/doc_o_day/lewiston1.shtml
#20yrsago "I, Row-Boat" https://web.archive.org/web/20060000000000*/http://www.flurb.net/1/doctorow.htm
#20yrsago Filipino students use SMS to organize mass demonstrations https://web.archive.org/web/20060902160514/http://blog.wired.com/sterling/index.blog%3Fentry_id%3D1545927
#20yrsago Spam pump-and-dumps work http://news.bbc.co.uk/2/hi/technology/5284618.stm
#25yrsago Leaked: Handspring's next PalmOS device https://web.archive.org/web/20020824213501/http://www.palmstation.com/view_article.asp?article=4614
#15yrsago “Stalwart Workers”: neglected backbone of the firm https://web.archive.org/web/20110920155246/http://blogs.hbr.org/hbsfaculty/2011/08/stop-ignoring-the-stalwart-wor.html
#5yrsago Facebook's war on switching costs https://pluralistic.net/2021/08/28/talking-hard-work-blues/#hostage-takers
#5yrsago The "work ethic" is a dirty trick we play on ourselves https://pluralistic.net/2021/08/28/talking-hard-work-blues/#work-will-set-you-free
#1yrago The capitalism of fools https://pluralistic.net/2025/08/28/strew-deal/#neither-fish-nor-fowla
Warsaw: Romana i Jana Podoskich, Sep 6
https://wydarzenia.phub.pl/events/0ee0e198-f843-423a-890f-c84ff50a46c0
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Budapest: Brain Bar, Sep 17
https://brainbar.com/munkatars/cory-doctorow
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
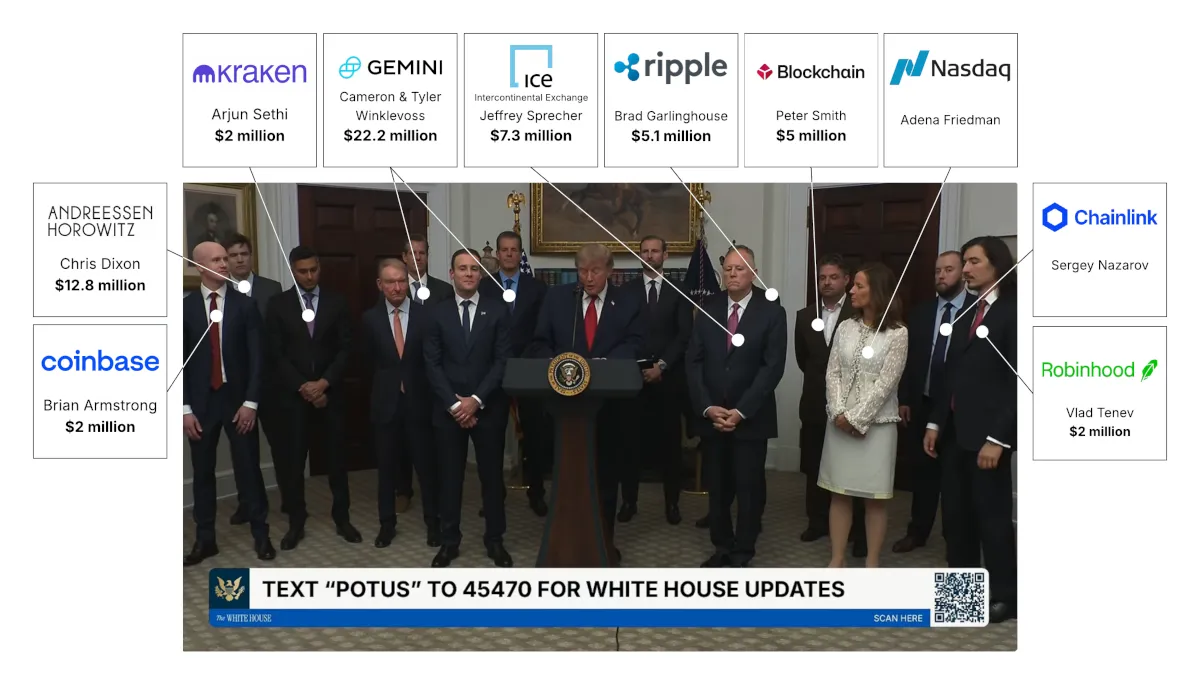
The SEC’s “Reg Crypto” aims to carve out exemptions, the CFTC wields emergency powers to shield prediction markets from state regulators, and a Trump family crypto firm gets a bank charter
A bit rich for Senator Bernie Moreno — by far the #1 beneficiary of crypto super PAC spending in 2024, now a champion of the industry's legislation — to accuse anyone of caping for special interest super PACs
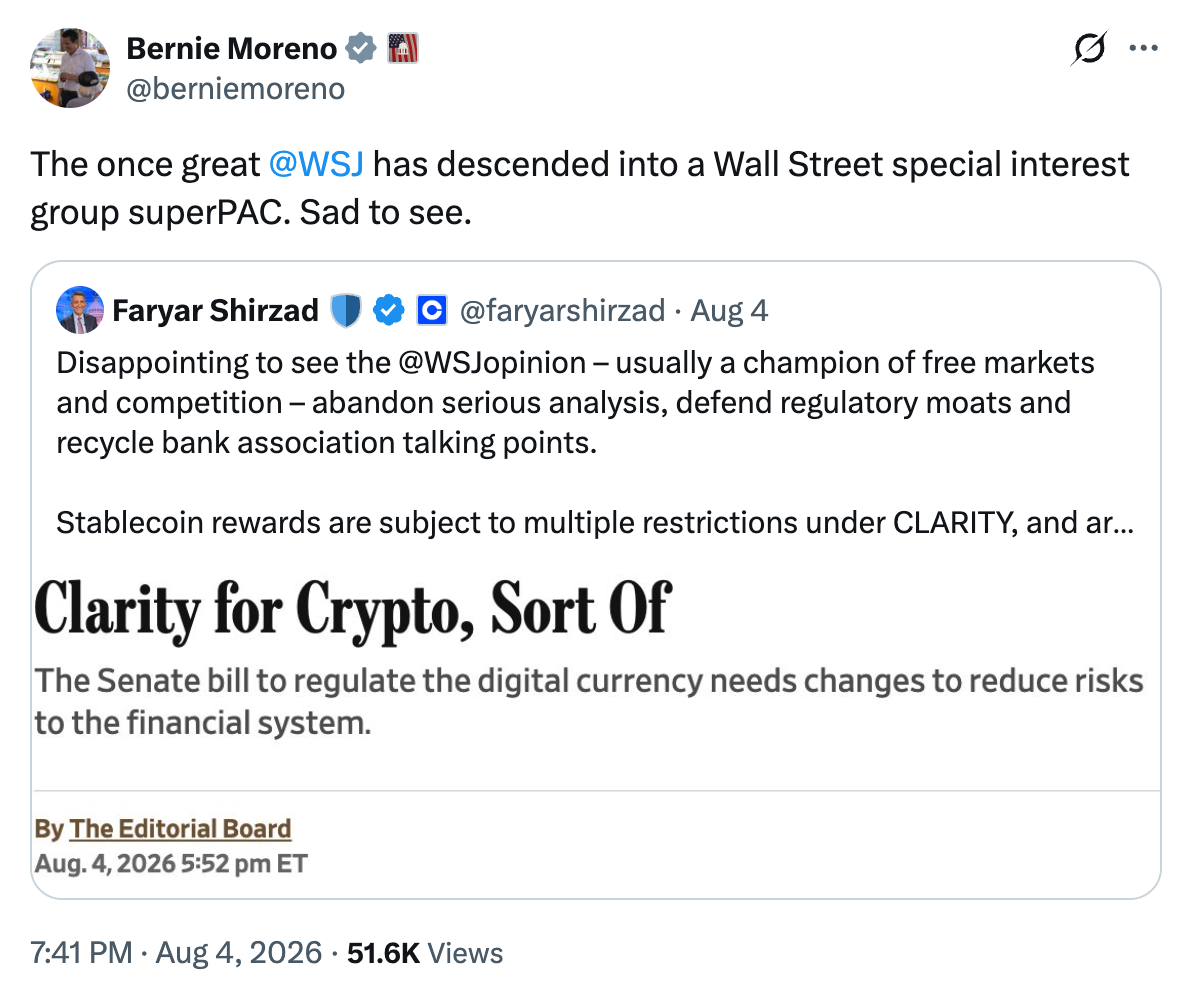
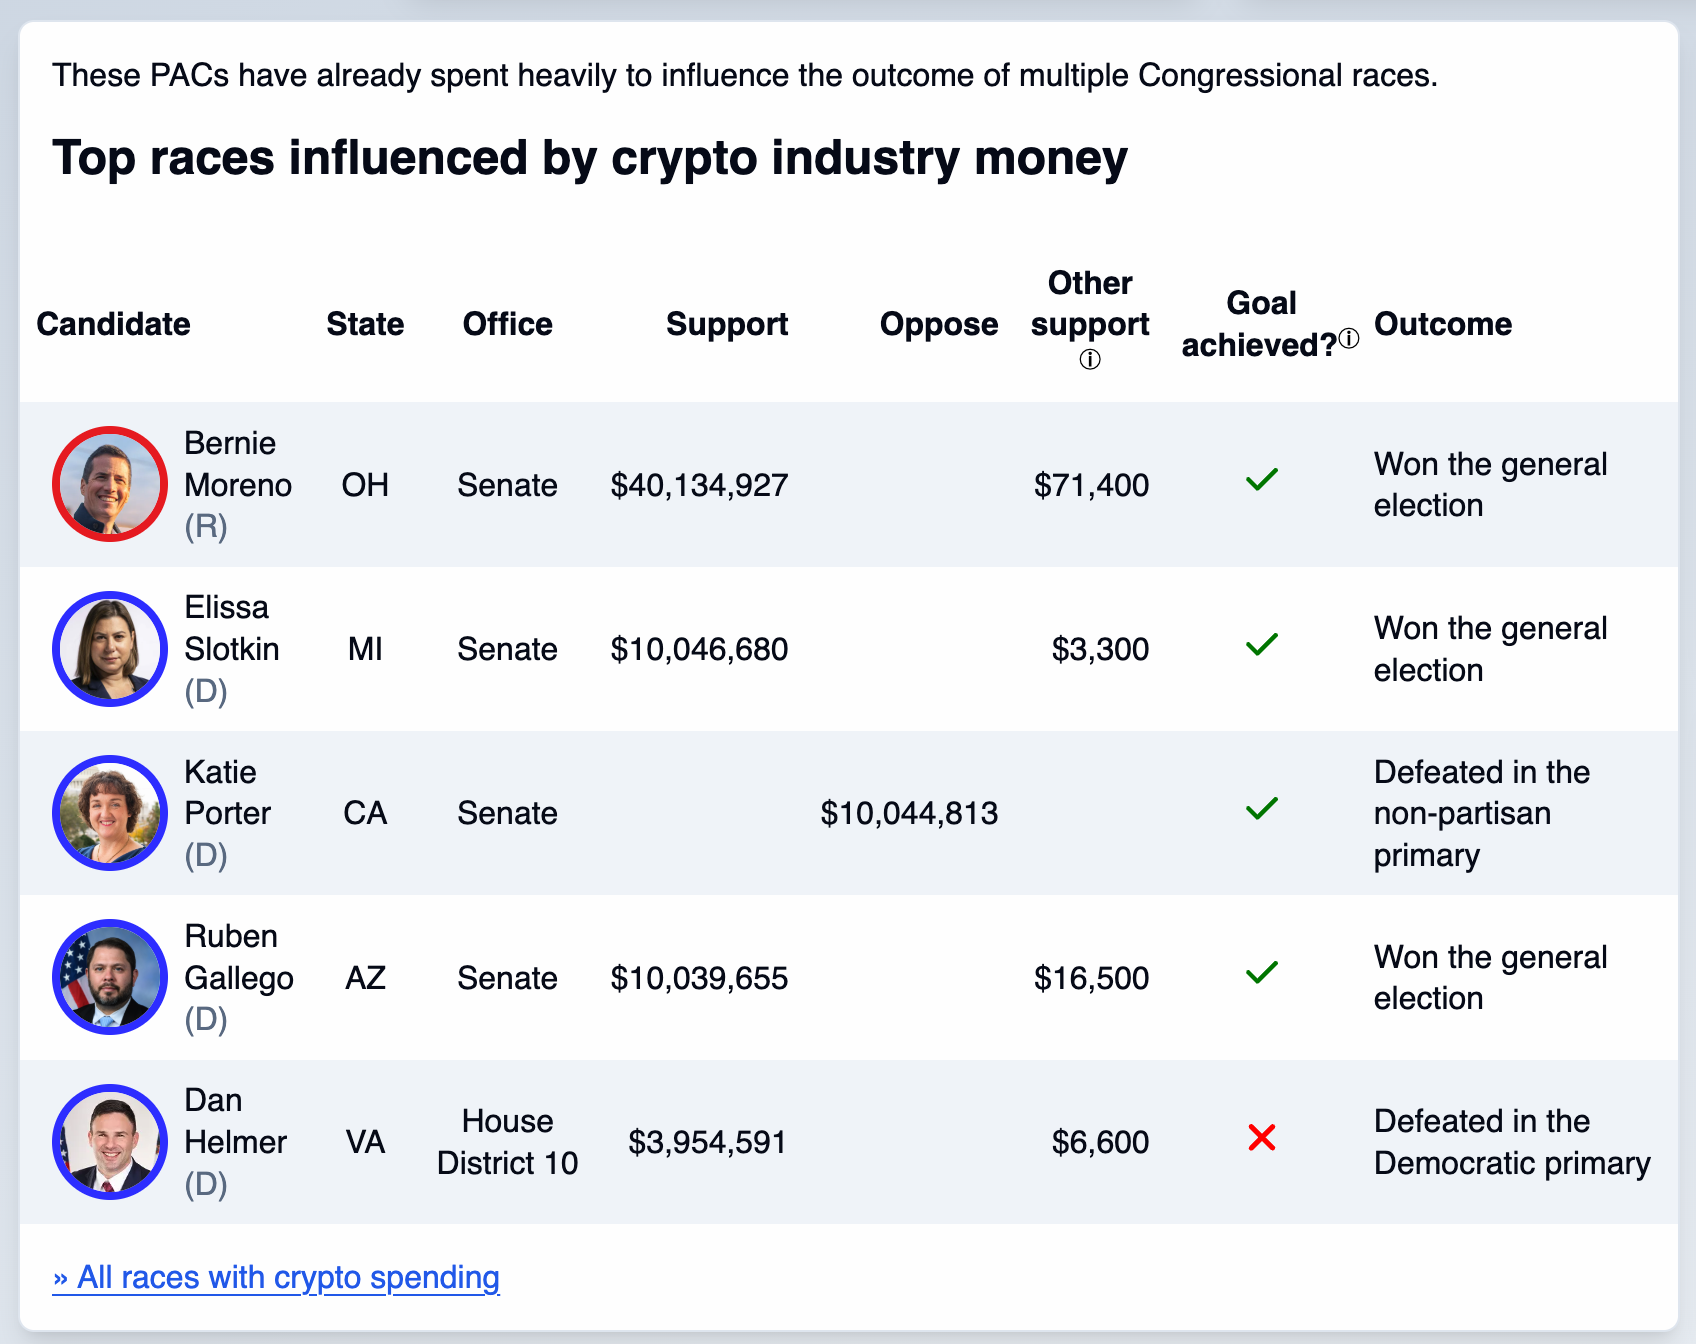
crypto billionaire Justin Sun has posted an extremely long, extremely weird Twitter post detailing a previous relationship with Chinese actress Jing Tian, suggesting she reneged on a $50 million agreement to use her eggs to have a child with a surrogate (screenshots machine translated)
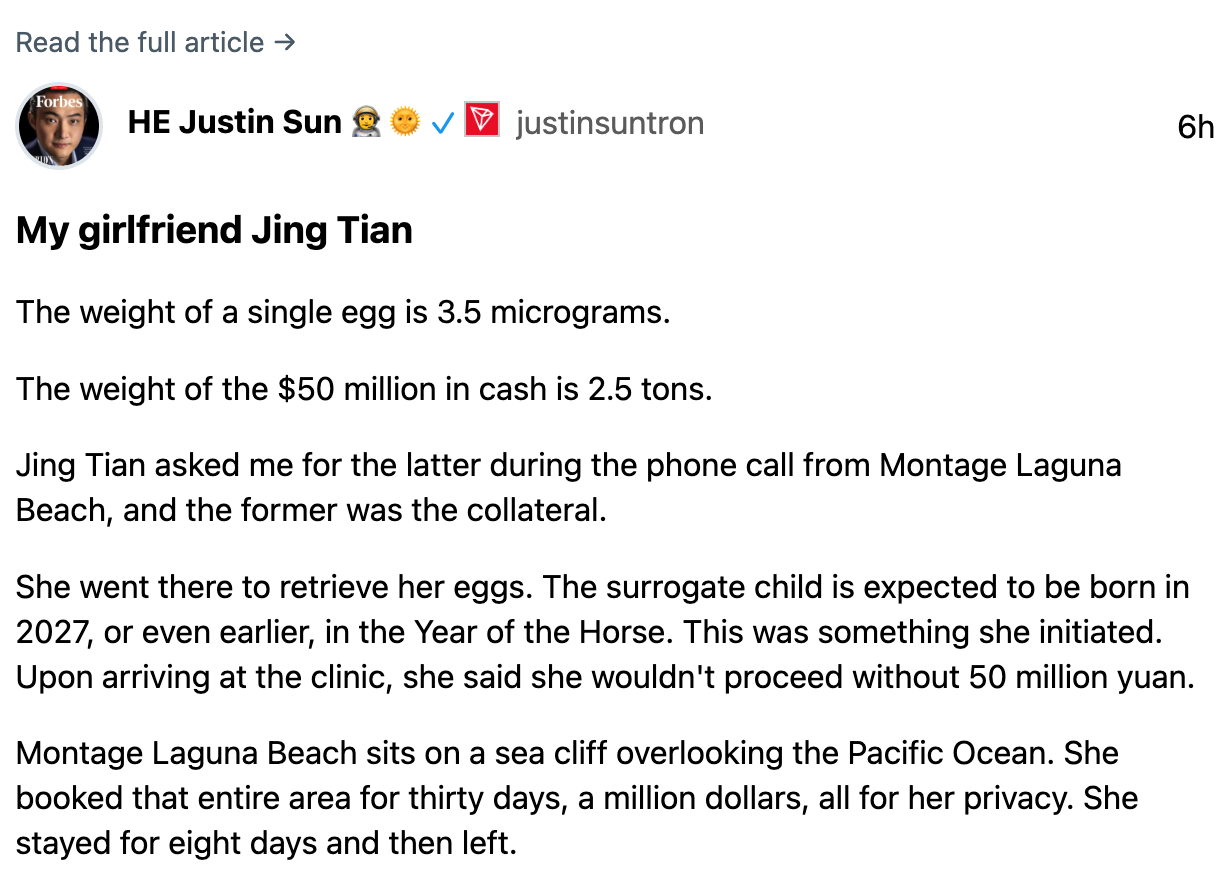
although at the very end he included a line claiming the "article is entirely fictional", there were rumors earlier this year involving massive amounts of money and an egg retrieval agreement that fell apart between Jing Tian and an unnamed wealthy boyfriend
Jing has released a statement that Sun is attempting to extort her by attacking her reputation, and that she intends to leave the matter "entirely to the courts".

 1⃣2⃣0⃣0⃣1⃣2⃣0⃣0⃣1⃣2⃣0⃣0⃣1⃣2⃣0⃣0⃣1⃣2⃣0⃣0⃣1⃣2⃣0⃣0⃣
They disinvented the VCR. You might think that the reason we don't have VCRs anymore is because VCRs were supplanted by DVDs, PVRs and streaming, but that's not the case. They had it in for the VCR from the very start, and they never stopped trying to kill it. Eventually, they succeeded.
The VCR was one of the fastest-adopted technologies in the history of the world, and it was disruptive. The fact that you could record shows to watch later, skip the ads, build a library of your favorites, even loan your tapes around – it drove the studios and broadcasters nuts. The VCR hit the market under a cloud of litigation, and the lawsuits went all the way up to the Supreme Court, culminating with 1984's Betamax decision, whose key precept is that a new technology doesn't violate copyright law if it can "sustain a substantial, non-infringing use":
https://en.wikipedia.org/wiki/Sony_Corp._of_America_v._Universal_City_Studios,_Inc.
As important as the VCR was as a device – creating the home video market, which begat DVDs, then streaming – the Betamax decision is even more important.
You see, copyright is a "fact-intensive" doctrine, which means that determining whether a use is or isn't a copyright violation can be a complex and expensive process of gathering facts, weighing conflicting expert views to arrive at a judgment. If the rule was that new technologies couldn't be introduced unless you could prove that they would never infringe copyright, we wouldn't have any digital technology. Indeed, most technologies would be illegal under that standard. You can infringe copyright with VCRs, photocopiers, hard drives, tape recorders, scanners, computers, phones… Hell, you can infringe copyright with an X-ray machine, a saxophone or a pair of ballet slippers!
There's clearly ways you can use a VCR to infringe copyright: for example, you can record a TV show to a tape, then sell that tape to someone else. There's also ways you can use a VCR that clearly do not infringe copyright: you can lug a camcorder around your kid's birthday party, pester the kids by recording them, then watch the footage later in your living room. Then there's an infinite universe of ways to use a VCR that might infringe copyright, depending on the specifics: recording the Super Bowl while you're at work, then inviting your workmates over to watch it after your shift ends; creating a library of kids' shows for the day-care you run out of your living room; making a highlight reel of your favorite politician's campaign speeches. Anyone who says, "Oh every judge would always call that legal‡ under every circumstance" is admitting they don't understand how copyright works.
‡ Or illegal.
This is a feature, not a bug. Copyright is a fact-intensive doctrine because it is a flexible doctrine. Since the printing press, new ways of mechanically reproducing and transmitting information have appeared at an accelerating pace, and judges are asked to figure out the rules for these new technologies long before legislatures come to grips with them and pass special, tech-specific laws.
Copyright's future-proofing lies in this flexibility, which the Supremes (correctly) recognized in 1984 with the Betamax decision. By ruling that any technology that had "non-infringing uses" was presumptively legal to create and market, the Supremes laid the legal foundation for all the digital tools that followed since.
Crucially, Betamax ensured that last year's tech lottery winners wouldn't get to prevent next year's winners from emerging. This year's admirals are always last year's pirates, and they insist that what they did to their predecessors was progress, while anyone who tries to do the same thing to them is a thief. The sheet music composers condemned the record player, recording artists decried the radio, broadcasters sued over cable and cable operators sued over VCRs. This never stopped: Sony – the company that invented the Betamax and defended it all the way to the Supreme Court – went on to sue Napster!
There's nothing inherently virtuous about "innovation." It's perfectly possible to "innovate" new ways to spy on people and rip them off. But if you're trying to launch a new product in a category that already has clear winners, the best way to convince people to take a chance on you is by making a valuable and useful product.
"Disruptors" are best when they move value from existing companies to those companies' customers. The first TV remotes let people change the channel when an ad came on, making their TV better at broadcasters' expense. The broadcasters had to struggle to adapt, which is fine. They're not charities, after all: they're in business to make money for themselves, and they're only going to give you as much value as they have to.
Competitors fight enshittification: any time a company that you do business with takes something away from you, a competitor can win your business by giving it back. If Youtube doubles the number of ads they expect you to watch – "charging" a higher attentional "price" – an ad-blocking competitor can bargain back on your behalf, allowing you to counteroffer with "how about if I just don't watch any ads?"
https://www.eff.org/deeplinks/2019/07/adblocking-how-about-nah
Inside every company, there are fair, honest people, and there are greedy, shitty people. Companies that face competitors are more likely to listen to the workers who want to give customers a fair shake. But if a company has no competitors, those good people can no longer say, "This is a losing strategy because it will open the door to competitors who will make us poorer." Without competitors, the argument against enshittification becomes, "I would feel bad about myself if we did that." This argument always loses to the bad guys, whose argument is, "We will all get richer if we do this."
That's why Google enshittified search: they had no competitors, so the worst ideas of the worst people at Google could be shown to make the most money, and so Google deliberately made its search results worse:
https://pluralistic.net/2024/04/24/naming-names/#prabhakar-raghavan
Of course, companies can also face consequences from the government, but the fewer competitors a company has, the easier it is for that company to capture its regulators:
https://pluralistic.net/2022/06/05/regulatory-capture/
Competition makes companies weaker, giving the public and democratic institutions more power. Competition makes the public richer at the expense of corporate shareholders, who have less money to spend on the project of subverting democracy.
That's the VCR story all over. The VCR shook up a sclerotic, stagnant TV and film industry, created the home video market, and opened up new distribution channels that allowed all kinds of new creative workers to reach new audiences, either directly or through a fiercely competitive new constellation of distributors who fought each other to offer them the best possible deal.
The media companies who were forced to adapt to the VCR never forgave it for forcing them to develop new, multi-billion dollar businesses without permission. As a Hollywood executive once put it to me, his goal was "a polite marketplace" where no one ever rudely forced him to disgorge more value to viewers and performers:
https://pluralistic.net/2022/01/02/the-internet-heist-part-i/
The executives who made billions after losing their bid to ban the VCR wanted to ensure that no one would ever be so "impolite" as to force them to make billions of dollars against their will ever again. They partnered with electronics firms to ensure that the VCR's successor technologies would only have those features that they approved.
That's why DVD players are not DVD recorders: the consortium that developed the DVD embedded "hook IP" in the technology. "Hook IP" is a term of art: it means any trademark, copyright or patent that is incorporated into a technology so that anyone who wants to implement that technology must license the hook IP; under the terms of those licenses, doing anything that disrupts the business plans of the consortium is banned.
The DVD consortium's hook IP had all kinds of bizarre licensing terms, like "region coding" – a requirement for DVD players to register the country in which they were sold and to check whether the DVDs you tried to play were from a compatible country. If not, the license terms required the DVD player to refuse to play your discs.
Region coding is an "anti-feature," a technology developed at great expense for which there is no market. Sure, some DVD player owners who had never shopped abroad for a DVD didn't care about region coding. But for customers who bought a disc on vacation, or moved from one country to another: region coding was terrible.
So there were customers who didn't care about region coding, and customers who hated region coding, but there were zero DVD player owners who wanted region coding. No DVD manufacturer could advertise that their products come with region coding. If there were two equivalent DVD players in the market, identical except that one had region coding and the other didn't, the "region-free" player would win. Region-coding is an anti-feature.
Anti-features aren't the only deliberate defects we find in DVD players. The consortium's hook IP licenses didn't just require anti-features, they also banned useful features…including recording. Long after the price of read/write optical drives plummeted to pocket-change, there was still no such thing as a home DVD recorder that would let you stick a spindle full of discs next to the TV and use them to record all your favorite shows.
Shortly after the DVD player emerged, Congress created the most powerful hook IP of all: "anti-circumvention law." Under anti-circumvention law, it's a literal crime – a felony – to modify or reimplement a technology without permission from the manufacturer. In 1998, Bill Clinton signed America's landmark anticircumvention law, the Digital Millennium Copyright Act, section 1201 of which establishes a five-year prison sentence and a $500,000 fine for "bypassing an access control":
https://pluralistic.net/2026/01/14/sole-and-despotic/#world-turned-upside-down
After DMCA 1201, all a manufacturer had to do was add an "access control" (like a password or an encryption key) to their device, and modifying that device in any way could land you in prison. As microchips plummeted in price, all kinds of devices and services acquired these "access controls," so that it became a crime to refill an ink cartridge, fix a tractor, or connect your insulin pump to your glucose monitor. Congress never passed a law criminalizing this conduct: rather, they gave companies the ability to write their own criminal code. Simply by adding an access control to a device, they could felonize any conduct that displeased them.
Every video format and distribution system that succeeded the VCR shipped with an access control: DVDs, Blu-ray and HD DVD, satellite and digital cable, and, of course, streaming video. This is how they disinvented the VCR. Once every video had an access control, it had "hook IP" that could be used to control all technologies that were capable of receiving, storing, or playing back that video.
Remember Tivo? The first digital "personal video recorders" were true successors to the VCR. They could record any broadcast or cable program, store it forever and fast forward through the ads. They were all "feature" and nary an "anti-feature" in sight. That's because they only worked with analog cable (which, being analog, didn't have "access controls" that qualified them for DMCA 1201 consideration) and broadcast signals (sent over the public airwaves on the condition that they not be scrambled).
Digital cable disinvented the Tivo. Every post-VCR digital video signal came with hook IP, and so the Tivos (and other PVRs) had to get permission before they could store and play back modern videos. To get that permission, PVR makers had to agree to a whole suite of anti-features, such as a "broadcast flag" that told it which shows you could and could not record. Even if you did record a show, PVR makers also supported more flags, such as an "expiry date" flag that forced your recorder to delete your shows after a set period, a "no skip" flag that blocked you from fast-forwarding through ads, and "geofence" flags that stopped you from playing back your stored videos based on which country you found yourself in.
Today, if you have a PVR, you probably rent it from your cable provider (who can use DMCA 1201 to block other PVRs from working with your cable provider). It's probably slow, with a confusing user interface, and it only records an ever-dwindling subset of the shows your cable company transmits. Notwithstanding that it's a genuinely shitty piece of technology, it's still awful that you can't buy it – the fact that you have to rent that crapgadget month after month means that you're paying for it several times over.
But at least cable signals have PVRs. For the majority of video we interact with, there's no PVR – not even a shitty, broken one. You can't record your Netflix videos, your HBO Max videos, your Disney Plus videos or your Prime videos. Recording a video off a streaming service has the same copyright status as recording a show off your analog cable had in 1984 when the Supreme Court handed down the Betamax decision, but because there's an "access control" on video streams, it's nevertheless a felony to make a VCR for a streaming service.
You know how streaming companies play all kinds of bullshit games, like dropping videos from their catalog? Even worse: the Amazon Prime scam where Christmas cartoons are all included in your "free" streaming tier from March-October, but cost $3.99 to watch from November to February. All of these ills can be cured with the VCR, a technology that was first marketed in 1971, a technology we have disinvented. If you could record those shows with a device that took orders from you, a device without anti-features, Amazon would derive no benefit playing these grinchy little games. If they played those games anyway, you could beat them.
It's not just VCRs. Anti-circumvention law led to the enshittification of everything from tractors to ventilators, phones to smart speakers, thermostats to games consoles, all of which are bristling with hook IP that lets their manufacturers decide what you can do with your own property.
All of this is extremely relevant at this moment, thanks to Trump's tariffs. For more than a quarter century, the US Trade Representative has arm-twisted every American trading partner into enacting an anti-circumvention law like DMCA 1201. All over the world, governments promised to lock up entrepreneurs and technologists if they dared to disenshittify America's defective tech exports. In exchange, these governments were promised free trade with the USA: tariff-free access to American consumers.
That's where Trump comes in. From the moment his "Liberation Day" tariffs landed, any country that upheld its anti-circumvention laws was sacrificing its national competitiveness, resiliency and integrity in exchange for nothing. Trump reneged on America's obligations to its trading partners, just like he reneged on every deal he's ever made:
https://pluralistic.net/2026/07/22/table-flipper/#graveyard-of-indispensable-nations
The good news is, this means we can have VCRs again! All it will take is for one (or more) countries to decide to lift its one-sided restrictions on making technologies "capable of sustaining a substantial non-infringing use" and wait for one (or more) entrepreneurs to figure out that reintroducing the VCR is a winner, just like it was in the 1970s, when the VCR was the fastest-adopted technology in the history of the world.
It's not just VCRs, of course. For a generation, entire product categories have been suppressed, all over the world. There is a whole CES (good) worth of products that are truly innovative (good) waiting to be brought to market.
The last time there was this much low-hanging fruit on offer was after WWII, where six years' worth of bombings, austerity and neglect provided endless opportunities to repair, rebuild and replace the worn, crumbling built environment, vehicle fleet and personal belongings of people all over the world.
After a quarter-century of innovation prohibition, there are dozens of lucrative, easily perfected technologies just waiting to be made: the dongle that jailbreaks your phone or console and installs a third-party app store, the dongle that flashes your printer so it takes generic ink; the dongle that lets your mechanic install generic parts in your car and lets farmers fix their tractors. Our whole digital world has been wrapped in chains by rent-extracting monopolists who gloried in their power to use hook IP to deprive you of the right to use your property in ways you see fit, writing private laws that made it a crime to displease them.
A generation of allowing companies to shift value from their customers and suppliers to themselves has made them richer, us poorer, and everything more expensive. They've accumulated vast wealth at our expense. Their margins are our opportunity.
The VCR was a great idea 55 years ago. 55 years later, it's an idea whose time has come – again.
Trump tried to curb clean energy. It’s booming anyway. https://arstechnica.com/science/2026/08/trump-tried-to-curb-clean-energy-its-booming-anyway/
The AI Hater's Manifesto https://www.wheresyoured.at/the-ai-haters-manifesto/
Amazon’s Monopoly Problem Is Growing https://prospect.org/2026/08/25/amazons-monopoly-problem-is-growing/
More Details Emerge On How Trump Cronyism Ruined The Attempt To Break Up Ticketmaster https://www.techdirt.com/2026/08/25/more-details-emerge-on-how-trump-cronyism-ruined-the-attempt-to-break-up-ticketmaster/
#25yrsago Metacrap https://people.well.com/user/doctorow/metacrap.htm
#15yrsago Slashdot’s CmdrTaco steps down https://meta.slashdot.org/story/11/08/25/1245200/Rob-CmdrTaco-Malda-Resigns-From-Slashdot
#15yrsago Chalk memorial for Jack Layton in front of Toronto’s New City Hall https://www.flickr.com/photos/lewolf011/6076393292/
#15yrsago Coordinated multinational ATM fraud nets $13M in one night https://krebsonsecurity.com/2011/08/coordinated-atm-heist-nets-thieves-13m/
#5yrsago Vaccinate workers at (almost) any price https://pluralistic.net/2021/08/26/chained-to-the-mast/#vaccine-leave-hesitancy
#1yrago By all means, tread on those people https://pluralistic.net/2025/08/26/sole-and-despotic-dominion/#then-they-came-for-me
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Hope, AI, Fixing the Internet and the Reverse Centaur of it all (Wilosophy)
https://podcastaddict.com/everyone-relax/episode/231414816
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

As Canada is learning (the hard way), the "art" of all of Trump's deals can be summed up in a single word: "renege":
https://pluralistic.net/2026/07/22/table-flipper/#graveyard-of-indispensable-nations
In 2020, Donald Trump ripped up NAFTA, a trade deal that conferred a huge advantage to the USA at Canada's expense, and replaced it with CUSMA, a trade deal that was even more advantageous to America, and even worse for Canada. In 2024, after being elected for the second time, Trump publicly railed against CUSMA using the exact same language he'd used to decry NAFTA, branding it "a very bad deal" that needed to be shredded and renegotiated.
To that end, Trump declared sweeping tariffs on Canada's exports, thereby raising the costs Americans paid for many everyday goods, because while Canada does not ship a lot of finished products to the US, it is a key supplier of parts and materials, all of which were made instantly more expensive thanks to the Trump tariffs. Trump went on to insist that Canada should annex itself to the US, becoming the "51st State." His operatives openly meddled in Canadian separatist movements, backing the "Wexit" partisans who want to separate the oil-rich, boom/bust-plagued province of Alberta from Canada.
CUSMA was negotiated by Justin Trudeau's government, and Trump II's tariff war landed on Trudeau's successor, Canadian Prime Minister Mark Carney, billed as a technocratic safe pair of hands who could be relied upon for sober, effective leadership.
Much to everyone's surprise, Carney – the epitome of a "Davos Man" – responded to the Trump tariffs by traveling to Davos and giving a fiery speech denouncing Trump and declaring a "rupture" that left the old world order dead:
Carney promised that Canada would go "elbows up" against America, with retaliatory tariffs, blockades and boycotts of key US exports. Cutting off this stream of goods would have the same effect on Canadians that Trump's tariffs had on Americans: raising prices. Unlike their American cousins, Canadians were far more tolerant of this increase in their cost of living, because, unlike Americans, Canadians believed the narrative that they were sacrificing for the good of their country against an existential threat from a fractious neighbour. Americans were far less willing to believe that Canada was somehow cheating the US or flooding the country with fentanyl.
"Elbows up" is largely a war of symbols, in which Canadians take pride in mastering the minute differences between "Product of Canada," "Made in Canada," "Assembled in Canada," and "Designed in Canada" so they can seek out maximal Canadianness in their consumption choices. There's even a kind of twisted honour in committing yourself to drinking Wayne Gretzky's shitty rye in preference to delicious American bourbon, a way to affirm your love of country with each astringent, metallic swallow.
When the trade war was confined to symbolic terrain, Carney's elbows remained reliably elevated. But outside the realm of symbols, Carney's elbows wilted.
Take the Digital Services tax, a plan to charge America's tax-evading tech giants a 3% levy to make up for the untaxed profits they keep by pretending to be Irish. So long as Trump's tech giants can dodge their tax obligations, they can always outcompete Canada's tech sector, who are expected to pay 38% federal and provincial tax.
American tech companies are closely allied with the Trump regime: they financed his campaign, conduct domestic and international surveillance for him, provide the software to administer his ethnic cleansing, and restrict access to software that helps Americans evade the armed secret police he sent into the streets to kidnap and disappear his enemies:
https://pluralistic.net/2025/10/06/rogue-capitalism/#orphaned-syrian-refugees-need-not-apply
Trump repaid his tech giants by threatening Carney with still more tariffs unless he canceled the Digital Service Act, and Carney capitulated. Meanwhile, Carney raced to enact a plan to fire tens of thousands of civil servants and replace them with AI chatbots running American software on American chips:
Canada's federal and provincial ministries are all entirely dependent on American cloud software, most notably Microsoft's Office 365, a package that Trump has fashioned into a geopolitical weapon, ordering Microsoft to shut down foreign officials who thwarted his plans, denying them access to all their data and cutting off their ability to communicate with the outside world:
https://apnews.com/article/icc-trump-sanctions-karim-khan-court-a4b4c02751ab84c09718b1b95cbd5db3
In other words, Canada is already terribly vulnerable to American cyberwarfare. Trump's tech companies don't have to hack into Canada's digital infrastructure to shut it down: they already control it. But – incredibly – Carney found a way to make this situation even worse, turning over key aspects of the digital back-end of Canada's military to Palantir, the tech company most closely aligned with Trump, whose CEO openly boasts that his company was founded to kill America's political enemies:
https://thedeepdive.ca/canada-military-palantir-license-deal/
Carney's symbolic gestures – memorable speeches and minor changes to consumption habits – are second to none. But when it comes to building a strong country that is resilient against the attacks we can all foresee (not least because Trump has repeatedly told us he intends to launch them), Carney himself becomes Carneyism's fiercest opponent:
https://pluralistic.net/2026/05/30/rupture/#deeds-not-words
It's not just the attacks that are foreseeable, alas. Trump can always be relied upon – to break his word. Carney repeatedly caved to Trump, and in response, Trump has hit Canada with massive new tariffs – 50%! Remember: the "art" of every Trump deal is renege:
Trump can also be relied upon to circle back to his fixations and obsessions. Decades ago, someone showed Trump a Mercator projection map of the Earth and he became obsessed with "yuge" Greenland, to the point where he is prepared to dissolve Nato and go to war with Europe to steal it from Denmark:
By the same token, Trump has long been publicly obsessed with the Gilded Age president William McKinley, who enacted sweeping tariffs at a time when the US economy was rapidly growing, a fact that lodged in Trump's brain and led him to believe that tariffs are a surefire growth-hack that will let him eliminate taxes on the wealthy without shutting down the country:
https://edition.cnn.com/2025/02/12/business/trump-william-mckinley-tariffs/
Trump will still be obsessing about these idées fixes when he draws his last breath, gasping out "Greenland…tariffs" as he tumbles from his golden toilet, forehead and coronary arteries bulging from the strain of trying to pass a half-digested Big Mac with only a viscous paste of rectal mucus and Diet Coke to lubricate that final, unyielding bolus.
The fact that Trump is immune to learning from his mistakes (because that would require admitting that he made a mistake) does not bind Canada to do the same. Quite the contrary: Trump's inability to learn or reason means that if Canada engages in novel retaliatory tactics, it stands a good chance of flummoxing the Mad King, leaving him flat-footed and lumbering while it dekes him out and swarms past him.
Lucky for Canada, Trump's incontinent belligerence has opened up a large and diverse territory of novel tactics for conducting both geopolitical and economic policy. As November Kelly says, "Trump inherited a poker game rigged in his favour but he flipped over the table anyway because he resents having to pretend to play." The systems that Trump has dismantled as unfair to the US were, in fact, sources of tremendous advantage to America.
Take those tech companies that have fused so tightly with the Trump regime. These companies operate global monopolies that allow them to extract vast sums and even vaster troves of sensitive data from billions of people around the world. Having attained total economic dominance and total technical lock-in, these companies have embarked on a program of enshittification, squeezing their customers and suppliers for even more data and even more money:
https://us.macmillan.com/books/9780374619329/enshittification/
Under normal market conditions, the decay of these American platforms would invite competitors from around the world. The fact that Apple and Google extract 30% of every dollar spent in their app stores would bring forth new app stores who were willing to give better deals to app makers and app users. The fact that HP charges $10,000/gallon for the coloured water in its printers would invite competitors who were willing to take a mere 100,000% margin on ink.
The fact that Meta and Google and Microsoft and Apple spy on you with your devices and software and use that data to target you, manipulate you and overcharge you – and to train their AIs to steal from you even more efficiently – would create demand for privacy blockers, jailbreakers, and other "adversarial interoperability" tools that force your technology to work for you, even if the manufacturer wishes it were otherwise:
https://pluralistic.net/2025/11/01/redistribution-vs-predistribution/#elbows-up-eurostack
But we don't have "normal market conditions." For more than a quarter of a century, the US Trade Representative has demanded that all of America's trading partners – including Canada – enact "anti-circumvention" laws that make it a crime to alter how a digital device works unless the original (usually American) manufacturer consents.
In other words, it's illegal for some Waterloo grads to tap ambitious RIM millionaires for the seed capital to start a company that helps Canadians install Canadian app stores on their Canadian phones so when they buy things from other Canadians, all the money stays in Canada, without a 30% "app tax" being siphoned off by either Google or Apple.
That's right: in 2012, Canada passed a law that lets American companies use Canada's courts to destroy Canadian companies that help Canadian technology users get more out of their own property. This law – the Copyright Modernization Act – was wildly unpopular from the start. A federal consultation drew over 6,000 opposing comments, and only 53 comments in support of the bill. But Prime Minister Stephen Harper whipped the vote among his Conservative MPs and passed it, because he judged that tariff-free access to America's markets to be a price worth paying:
https://pluralistic.net/2024/11/15/radical-extremists/#sex-pest
Trump's tariffs prove that this was a bad bargain. By voluntarily gluing its technological elbows to its sides, Canada made itself easy pickings for America's tech giants, who wiped out Canada's tech sector while making Canada geopolitically and economically dependent on – and vulnerable to – the US and its tech companies. Canada is long overdue for a reckoning with this blunder.
The best time to have made Canada digitally sovereign would have been before an American president announced his intention to annex Canada and began explicitly deploying America's tech companies to attack his geopolitical adversaries.
The second-best time is now.
By repealing Bill C-11 and legalizing reverse-engineering and modification of digital technology with consent of its users and in accordance with privacy, consumer and labour rights, Canada will gain a devastating counter to Trump's tariffs.
Not only will legalizing jailbreaking let Canadians get more out of their own property, it will turn America's tech trillions into Canada's tech billions – while making Canada digitally sovereign by facilitating the uncoupling of Canadian ministries, corporations, households, and devices from America's cloud. This is how Canada removes the digital kill switch it handed to America, a kill switch that can shut down its tractors, phones, and governments.
This is the best possible moment for such a move. To incubate a successful tech sector, you need a) an innovative product; b) skilled technologists; and c) capital. Thanks to Trump, Canada has all three.
First: innovative ideas. Thanks to the prohibition on modifying America's defective tech exports, there is a whole orchard of low-hanging fruit for product designers to pick from: an app that aggregates all of your streaming services into one place and lets you record shows to watch later, even if the service deletes them; reliable tools for using generic ink and independent app stores; new firmware for tractors and cars that facilitates independent repair and unlock subscription features, and, of course, privacy- and ad-blockers of all description. These are truly disruptive products, striking at the maddening antifeatures installed at the insistence of sclerotic, extractive tech bosses. Move fast and break their things!
Next: talent. Who will do that fast moving? Again, we can thank Trump for giving Canada an army of skilled technologists who have fled Silicon Valley one step ahead of an ICE chud who wanted to black-bag them and deport them to Liberia (or a Salvadoran slave-labor camp). Trump is creating the largest wave of reverse brain-drain in history, as everyone ambitious and smart realizes that their lifelong US tech work dream is a nightmare. If Canada can't get enough talent to harvest that orchard of low-hanging fruit from its returning Canadians, it need only open its borders to the skilled technologists of all nations who are racing out of America as fast as they can go.
Finally, money. The AI bubble collapse is imminent. The forces of capital are desperate for promising, high-return investment opportunities that aren't grossly overvalued, overhyped and underperforming AI companies. Even if you can find a company like that in America, it's increasingly apparent that to make that business a success, you will need to buy more $TRUMP coins than your rivals, lest Trump direct his agencies to destroy your fledgling business.
And here's the kicker: turning America's trillions into Canada's billions, moving fast and breaking America's tech-kings, fixing the defects in America's extractive tech exports? It's all good for Americans. Sure, cratering the share-price of America's Big Tech companies will be bad for America's retirement savers, but the median American worker only has $955 saved for retirement:
https://finance.yahoo.com/news/955-saved-for-retirement-millions-are-in-that-boat-150003868.html
Most Americans are far more exposed to the predatory conduct of US tech companies than they are to the share price of those companies. That's because Americans are the beta-testers for every ripoff and surveillance tool that Silicon Valley produces. Long before those tools get to Canada or find their way around the world, they are making Americans poorer and worse off.
Remember: Canada is America's second largest trading partner. Americans are really good at buying things from Canada – even when those things aren't allowed in America. Trump wasn't entirely wrong when he accused Canada of flooding America with drugs – but the drugs Canada sends to America aren't fentanyl and oxy. Canada sends America insulin and other cheap pharmaceuticals that cost 10-100x more in Ripoff America than they do in Canada. If Americans can figure out how to buy cheap generic meds from Canadians over the US Postal Service, they will be able to buy disenshittification tools from Canadians over the internet.
Selling Americans products that make their lives better is much better politics than boycotting American products that make Canadians' lives better. No politician can pursue a strategy of higher prices and lower living standards forever – not even if you've got a lot of "elbows up" rhetoric you can use to convince Canadians that they're doing their duty to the nation by paying more for everything. Paying more for everything to punish Americans is like punching yourself in the face as hard as you can and hoping the downstairs neighbours say "ouch."
When Canadians swap delicious American bourbon for Wayne Gretzky's shitty rye, they punish corn farmers in states that begin and end with a vowel – farmers who have nothing to do with Canada's problems. By swapping disenshittification for tariffs, Canadians can go back to drinking delicious bourbon, and make money from that farmer by selling him the jailbreaks he needs to fix his tractor without paying the John Deere tax of $200+ that the company charges after you do your own repair to send someone to the farm to type an unlock code into your console.
A lot of Very Serious Grown Up Canadians have told me that they think Carney should confine his response to Trump to toothless symbolic gestures, lest they make Trump mad. Trump is always mad. He gets mad at symbolic gestures. He gets mad if you point out that Ronald Reagan thought tariffs were stupid:
https://abcnews.com/Politics/trump-raises-tariffs-canada-10-after-reagan-ad/story?id=126866712
Freeing Americans from the tyranny of their own tech companies has the power to create a partisan army of American Canada weebs who will fight for Canada when – not if – Trump gets mad at Canada. That's the best defense Canada can have – common cause and solidarity with the people of America, who share a common enemy in Trump, the least popular president in history, who is looting billions and letting his cronies destroy Americas' lives.
That's some real elbows up stuff. True Carneyism has never been tried – especially by Carney. It's long past time someone gave it a go.
Many recent grads say AI is making it harder to get a job. Economists aren't so sure https://www.npr.org/2026/08/18/nx-s1-5910677/recent-college-graduates-employment-job-artificial-intelligence
Nonfeasance, Misfeasance, and Malfeasance: Academic Freedom in a Nutshell https://3d.laboratorium.net/2026-08-23-academic-misfeasance
#25yrsago Kevin Mitnick is out of prison https://web.archive.org/web/20010000000000*/https://www.techtv.com/screensavers/showtell/story/0,23008,3343816,00.html
#25yrsago Brazil to nationalize AIDS drug patents https://edition.cnn.com/2001/WORLD/americas/08/22/aids.drug/index.html
#25yrsago Copyright your DNA https://web.archive.org/web/20010827170510/http://www.cosmiverse.com/science08230102.html
#25yrsago The internet is boring now https://www.nytimes.com/2001/08/26/us/exploration-of-world-wide-web-tilts-from-eclectic-to-mudane.html
#20yrsago TSA busts “explosive water” that turns out to be cosmetics https://web.archive.org/web/20060822123448/http://www.kxma.com/getARticle.asp?ArticleId=35223
#20yrsago Windows Media DRM cracked, no one cares https://archive.blogs.harvard.edu/cmusings/2006/08/25/#a1889
#20yrsago Canadian music label puts fans and artists first https://web.archive.org/web/20060830211418/http://wired.com/wired/archive/14.09/nettwerk_pr.html
#20yrsago After the Siege in Russian https://craphound.com/Cory_Doctorow_-_After_the_Siege_Russian.html
#20yrsago Victory in War on Moisture: Gel-bras once again safe! https://web.archive.org/web/20060820185006/http://www.tsa.gov/travelers/airtravel/prohibited/permitted-prohibited-items.shtm
#20yrsago EFF sues Barney the humorless, copyright maximalist dinosaur https://web.archive.org/web/20060813093642/http://www.eff.org/news/archives/2006_08.php#004884
#15yrsago MP3tunes verdict: music lockers are legal https://www.eff.org/deeplinks/2011/08/mp3tunes-victory-music-lockers-is-good
#15yrsago Lolita on Wikipedia: 2,300 edits later https://web.archive.org/web/20111008072145/http://www.theawl.com/2011/08/case-history-of-a-wikipedia-page-nabokov’s-lolita
#15yrsago SF mockumentary: ‘Ghosts With Shit Jobs’ — China looks at westerners with awful jobs https://ghostswithshitjobs.com/
#15yrsago Information consumes attention: focus in the age of abundant stimulus https://web.archive.org/web/20111113004501/http://nymag.com/print/?/news/features/56793/
#15yrsago Jack Layton’s final public words: “Love is better than anger. Hope is better than fear.” https://web.archive.org/web/20110829050308/http://beta.images.theglobeandmail.com/archive/01310/Jack_Layton_s_lett_1310744a.pdf
#15yrsago Getting people’s names right in software design: a LOT harder than it looks https://www.antipope.org/charlie/blog-static/2011/08/why-im-not-on-google-plus.html
#15yrsago Internet Archive’s cache of 24/7 TV footage from 9/11 and beyond https://archive.org/details/911
#10yrsago Peter Thiel & Y Combinator fund a “litigation financing” startup to make money off other peoples’ lawsuits https://gizmodo.com/a-startup-backed-by-peter-thiel-makes-bankrolling-civil-1785707590
#10yrsago Universities fought unionization’s ‘one-size-fits-all’ using identical arguments https://crookedtimber.org/2016/08/25/great-minds-think-alike/
#10yrsago 5 years after Texas GOP’s attack on women’s reproductive health, TX leads developed world in maternal mortality https://web.archive.org/web/20160820212602/https://www.theguardian.com/us-news/2016/aug/20/texas-maternal-mortality-rate-health-clinics-funding
#10yrsago You didn’t find a meteorite https://sites.wustl.edu/meteoritesite/
#10yrsago Young Conservatives’ “leadership seminar” featured food & water deprivation, sexist epithets, physical abuse https://web.archive.org/web/20160824145226/https://www.thestar.com/news/queenspark/2016/08/23/ontario-tories-apologize-to-party-activists-after-controversial-youth-seminar.html
#10yrsago The 2017 Ikea Catalog considered as dystopian urban microapartment futurism https://web.archive.org/web/20160817154440/https://www.fastcodesign.com/3062854/ikeas-2017-catalog-is-a-terrifying-glimpse-into-the-tiny-apartments-of-the-future
#10yrsago Singapore will disconnect entire civil service from the internet https://www.theguardian.com/technology/2016/aug/24/singapore-to-cut-off-public-servants-from-the-internet
#10yrsago They’re making a Twits ale from Roald Dahl’s body-yeast https://web.archive.org/web/20160817154531/http://www.independent.co.uk/arts-entertainment/books/news/beer-to-be-made-from-yeast-swabbed-from-roald-dahls-writing-chair-a7195721.html
#10yrsago As America’s temperatures soar, prisoners are dropping dead https://web.archive.org/web/20160825000426/https://theintercept.com/2016/08/24/deadly-heat-in-u-s-prisons-is-killing-inmates-and-spawning-lawsuits/
#5yrsago Are privacy and antitrust on a collision course? https://pluralistic.net/2021/08/24/illegitimate-greatness/#peanut-butter-in-my-antitrust
#5yrsago What kind of emergency is our emergency? https://pluralistic.net/2021/08/23/dont-wanna-spoil-the-surprise/#monocausotaxophilia
#5yrsago The secrets of hospital bills https://pluralistic.net/2021/08/23/dont-wanna-spoil-the-surprise/#surprise
#5yrsago Belarusian dictator pwned by "cyber-partisans" https://pluralistic.net/2021/08/25/taxes-are-for-the-little-stores/#cyber-partisans
#5yrsago Big Box stores' other shoe drops https://pluralistic.net/2021/08/25/taxes-are-for-the-little-stores/#metastatic-parasites
#5yrsago The Unraveling https://pluralistic.net/2021/08/23/dont-wanna-spoil-the-surprise/#the-two-genders
#1yrago Friction cannot be reduced, it can only be redistributed https://pluralistic.net/2025/08/23/become-unoptimizable/#downward-redistribution
London: AI and the Enshittification of the Media, NUJ (Sep 2)
https://www.nuj.org.uk/learn/ems-event-calendar/ai-and-the-enshitification-of-the-media.html
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Deflating the AI Bubble (Do Not Pass Go)
https://www.donotpassgo.ca/p/deflating-the-ai-bubble-with-cory
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Any frank assessment of your own achievements starts with an equally frank assessment of the world-historic forces that attended those achievements. For example, I often tell young people who want to get into tech, "Well, if you don't have the foresight and work ethic to have been born in 1971, I can't really help you."
When it comes to tech, being born in 1971 – to a computer scientist father, no less – conferred a tremendous advantage for my career chances. My dad – a refugee – came to Canada at a time when post-war public services meant that he could become the first person in his family to go to university, all the way to a doctorate.
That set me up for life in a house where tech and education were all around me. Both my parents are teachers, both from working class families where no one had ever gone beyond high school, who found themselves in a time and place where it was easier than at any time in history for people from backgrounds like theirs to attend university. I got to go to university, too, at a time when education was cheap enough that I could drop out of four schools before figuring out that it wasn't for me, and still be debt-free, largely thanks to income from a series of part-time jobs.
When I dropped out of my final degree program, it was to take a job in tech at a time when anyone with a little creativity, work ethic, aptitude and curiosity could walk into a career. Millions of us did it, and I ended up working as a freelancer, then founding a startup, and then going to EFF. I know I work hard, I know I apply myself to understanding the world around me, but also…when it comes to this kind of career, I was born on third base.
There's plenty of this to go around. Think of boomers who bought their "starter home" with the income from their first job and traded it in for a succession of larger, nicer homes, each of which skyrocketed in value. Some of those people fancy themselves to be veritable Warren Buffets for having had the shrewd financial insight that buying a house and living in it was a good idea. The truly smart ones know that they just got lucky.
There are world-historic forces all around us, creating moments and circumstances that contribute to the life-thriving of those of us who are lucky enough to be suited to the moment we find ourselves in.
Take computing: for decades, computing was ruled by Moore's Law, an unbroken run in which computers got faster and cheaper every year. If you were interested in the kinds of computing applications that were well-suited to serial computation – programs that worked best when run on a single computer – you were in luck. Even if your application or field of study was expensive and difficult to realize on today's computer, you could just stand still for a year or two and a much faster computer would park itself on your doorstep, ready to solve your problems.
When Moore's Law tapped out – when the pace at which transistors got smaller and computers got faster slowed and plateaued, and the expense of even modest performance gains climbed infinitywards – computing changed with it. Parallel computing – putting more cores on a chip, more chips on a board, more boards in a system – took off, as chipmakers and system builders switched from a focus on building their computers tall to building them wide.
As parallel computing took off, so did parallel applications. This is the beginning of the graphics revolution, as GPUs – components made up of many, many low-powered computers – became more central to academic research and commercial product roadmaps. But it wasn't just graphics that saw a huge lift here: any task that could be parallelized got easier and cheaper to perform every year, in a steady trend that has run to this day. This is the era of performance gaming, VR and AR, cryptocurrency, and, of course, AI.
In What Technology Wants, Kevin Kelly introduces the idea of the "adjacent possible" through the example of the helicopter. Da Vinci sketched a "helicopter" – blades in the shape of maple keys attached to a kind of wine-press screw – in the 15th century. In the centuries that followed, many other people had the insight that twirling blades of that shape on a screw of some type could provide lift for some kind of heavier-than-air craft. But it wasn't until strong alloys, internal combustion engines and light, energy-dense refined hydrocarbon fuels came on the scene that the helicopter became possible, whereupon it was all but inevitable, with several people independently inventing the helicopter all at once:
In the same way, the computing industry's focus on parallel computing made life easier for people who burned to do something parallelizable. Then the achievements of the parallel computing partisans drove more investment in improvements to parallel computing hardware and theoretical work on how to parallelize other problems. This feedback loop raised the profile of parallel computing applications, attracting more bright and ambitious people to those applications, whose even more impressive accomplishments brought more people into the field, more capital into hardware development, and more resources to parallelization research.
The point being that world-historic forces, combined with accidents of history, shape the outcomes of individuals, companies and disciplines. It's much easier to be an accomplished graphics wizard in an era in which GPUs are doubling in power every year than it is in an era when linear computing is getting the lion's share of investment and improvement.
These forces and accidents have acted on AI in ways that profoundly shaped its development. The latest AI boom started when a group of machine learning researchers tried a minor variation on existing techniques and saw a major improvement in the outcomes. This is one of the most exciting kinds of breakthrough: if tweaking a single variable in a small way produces a large improvement, then it may be that further tweaking will produce even more improvements.
The minor variation that produced the major improvement in AI performance was scale. Prior to the "deep learning" era, AI research relied on a mix of hand-built models of reality and training data that computers fitted into those models. Deep learning swapped the painstaking work of describing reality in software for a brute-force approach: throw lots more training data at the system and then throw lots more (parallel) computing power at that data and let the computer figure it out without your having to explain how the world worked.
The early gains from this approach were very exciting: they dangled the promise of software that could essentially "teach itself" how to do complicated, valuable things in a series of accelerating returns. The fact that the early improvements in AI systems that used this technique were so much greater than anyone would have expected based on AI research up to that point dangled an even more exciting promise: that the improvements would continue to scale faster than the inputs.
Researchers and investors came to expect an AI that was "untouched by human hands," that taught itself how the world worked. This was the self-licking ice-cream cone of machine learning, the world of "theory-free inference" that had fueled the Big Data industry. With theory-free inference, you don't have to figure out how the world works in order to act upon it: you can just gather up all the data about how things happen in the world, use statistical methods to find the correlations, and then intervene to change the outcomes. You don't have to know why a molecule improves a medical condition – it's enough to discover that fact, produce that molecule, and administer it to people with that condition.
Lots of stuff in the world works this way. Our understanding of the causal relationships that make up reality has massive holes in it that we fill with mere correlation. Correlations are easier to discover than causes, and while correlation is (famously) not causation, causes and effects are correlated, and if you can evoke the effect you're seeking without understanding precisely what happened to make that effect appear, well, at least you got the effect you were seeking.
Theory-free inference is a very pragmatic way to approach the world: "I don't need it good, I need it Thursday." Scientists burn to know why a molecule stopped you from dying, but you are likely satisfied to not be dead. What's more, our ability to observe correlations will always race ahead of our understanding of causality, so the power of theory-free inferences pushes out the frontier of things we can act on, beyond the realm of the understood.
Which is all to say: it's reasonable to be excited about a breakthrough in theory-free inference. But just like a boomer who thinks that buying a house to live in makes them a shrewd real-estate speculator, someone who achieves great things through theory-free inference runs the risk of missing the limitations of those techniques.
And they are limited. Theory-free inference is good at predicting what your spouse will type into their phone based on all the things they've ever typed into their phone. You are also good at guessing what your spouse will say based on the things they've said before. The difference is that when your spouse says something entirely unexpected and unprecedented to you (say, "I want a divorce"), the fact that you have a theory about why your spouse said all the things they said up to that moment can help you understand why they've said this new thing. But a machine learning model that relies on theory-free statistical modeling to predict your spouse's next words will be entirely at sea. Theory-free inference works well, but it fails badly.
The problem is that the AI sector has raised literally trillions of dollars by assuring investors that the era of hand-made, causal world models that let computers act on the world is hopelessly inefficient and outdated. But there are many, many tasks that are vastly more efficient and reliable when done through conventional computer programs, rather than through "AI."
As Gary Marcus describes in a recent Organized Money interview, an LLM can recite the rules of chess, but it can't play chess because – lacking a theory of how chess works – it will just emit statistically likely chess moves, even if those moves cause pieces to illegally move through other pieces. The first conventional chess-playing programs ran on electromechanical proto-computers, and they played a better game of chess than an LLM that uses billions of times more computing power and energy:
https://www.organizedmoney.fm/p/an-ai-expert-explains-the-hype
The AI companies have proved that there are many domains and applications where we can swap scale for understanding. But, having ridden some world-historic forces and adjacent possibles to great fortunes and stature, they cannot be dissuaded from their conviction that theory-free inference and scale can do everything. They can't be convinced that in many cases, the things that scale and theory-free inference can do are much better accomplished through causal understandings and conventional computing techniques.
From a research perspective, it is interesting to learn about the potential and limitations of a model trained on the entire internet. From a societal and industrial perspective, it is often grossly wasteful, inefficient and unreliable to swap scale for understanding.
The AI sector was born of world-historical forces that favored massively parallel computing, forces that had also conjured up an internet with trillions of documents that could be fed into those massively parallel computers to conduct theory-free inference. Like every success, AI was born on third base.
As rent-burdened millennials who abandoned avocado toast and fancy coffee and still can't afford a downpayment will tell you, the fact that being born in 1945 made it easy to trip and land on a couple million dollars' worth of real estate by the time you reached retirement age tells us nothing about how to solve the housing crisis of 2026.
By the same token, continuing to give trillions to AI companies because they experienced early success with theory-free inference at scale tells us nothing about how to solve the vast range of problems that theory-free inference at scale sucks at. Doubling down on AI to overcome its increasingly obvious limitations is like doubling down on building post-war suburbs to fix today's housing market.
It's possible to achieve impressive feats because you're smart and hard working and also because you were in the right place at the right time. Historical contingency produced the AI bubble, and it is producing the conditions for that bubble to pop.
FTC Says It Will Enforce Surveillance Pricing. It Won’t. https://prospect.org/2026/08/21/ftc-says-it-will-enforce-surveillance-pricing-it-wont/
Why shaming people about AI slop isn’t enough to stop Big AI https://www.anildash.com/2026/08/21/ai-slop-and-shame/
#25yrsago Glue anything to anything https://www.thistothat.com/
#20yrsago No unions in iPod City https://web.archive.org/web/20061123003816/https://www.wired.com/news/columns/0,71629-0.html?tw=wn_index_2
#15yrsago Credit scores are bullshit https://web.archive.org/web/20111013005626/https://a.wholelottanothing.org/2011/08/credit-scores-are-bullshit.html
#15yrsago RIP, Jack Layton https://www.bbc.com/news/world-us-canada-14618943
#15yrsago William Gibson on cities and the future https://www.scientificamerican.com/article/gibson-interview-cities-in-fact-and-fiction/
#10yrsago Bronx cops can steal anything they want by calling it “evidence” https://www.theatlantic.com/technology/archive/2016/08/how-police-use-a-legal-gray-area-to-rob-suspects-of-their-belongings/495740/
#10yrsago Robert Moses wove enduring racism into New York’s urban fabric https://web.archive.org/web/20160402184527/http://www.hopesandfears.com/hopes/now/politics/216905-the-lingering-effects-of-nyc-racist-city-planning
#10yrsago EFF takes a deep dive into Windows 10’s brutal privacy breaches https://www.eff.org/deeplinks/2016/08/windows-10-microsoft-blatantly-disregards-user-choice-and-privacy-deep-dive
#10yrsago Inside the “sweatshop” terminally ill Britons must call to get benefits https://web.archive.org/web/20160820094907/https://www.theguardian.com/public-leaders-network/2016/aug/20/work-pensions-disability-claim-call-handler-benefits-dwp
#10yrsago How the New York Public Library made ebooks open, and thus one trillion times better https://www.crummy.com/writing/speaking/2015-RESTFest/
#5yrsago Raiders of the lost ARC https://pluralistic.net/2021/08/22/raiders-of-the-lost-arc/
#1yrago Radical juries https://pluralistic.net/2025/08/22/jury-nullification/#voir-dire
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
London: AI and the Enshittification of the Media, NUJ (Sep 2)
https://www.nuj.org.uk/learn/ems-event-calendar/ai-and-the-enshitification-of-the-media.html
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Hudson, OH: Hudson Library, Oct 7
https://engagedpatrons.org/EventsExtended.cfm?SiteID=3850&EventID=596952&PK=
Victoria: Munro's Books, Oct 20
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

AI is alarming for many reasons: it's a dangerous financial bubble, an environmental catastrophe, and a tool for eroding wages and labor power. But in addition to all that, AI is an epistemic disaster.
We've had photoshopped images, voice impersonators and visual effects for years, of course, but with deepfakes, we've democratized access to reality-bending images, sounds and videos that appear real but are not. It's harder than ever to know what's true. Politicians and celebrities and activists show up in our feeds, declaring their fealty to this cause or product, or their fury at some turn in the world's events. Battlefields mound high with bodies and influencers marvel at impossible, sumptuous meals. It all seems plausible, and some of it is real, but not all of it, and because we know some of it is fake, we can't be sure if any of it isn't.
It's a very putinesque way of living. Vladislav Surkov was Vladimir Putin's media strategist, and he had a deadly effective tactic: he announced that he was covertly funding some of the groups that publicly opposed Putin, but did not disclose which of those opposition groups were fake. That meant that any of the groups could be fake, which meant that any discussion of the opposition was liable to devolve into an argument about its authenticity. Anything could be a lie, so nothing was necessarily true. Putin's method isn't to get you to believe a lie – it's to keep you from believing that anything is true.
That's life under AI – a world of uncertainty, an epistemological void full of plausible phantasms, some of which are actually real. A world where it's impossible to know what's true, and where anything might be fake.
But here's the thing: AI's assault on our ability to know isn't a new battle – rather, it's the latest barrage in a war that's been waged for years, as corporations grew larger and more powerful, capturing their regulators, who let them lie to us and abuse us with impunity.
This complicated, technical world – the world that produced AI – is full of complicated, technical questions, and none of us can answer these questions for ourselves. You're not stupid, but even a generational genius could not acquire the expertise to answer the long list of life-or-death questions we face every day.
Are the food hygiene standards followed by your grocer or lunchtime spot adequate, or will your dinner make you shit yourself to death? Are the building codes that specify the alloys in the steel joists that hold up the roof over your head sufficient, or are you about to be crushed to death? Is the software in your anti-lock brakes any good, or will you die in a fireball on the way to work?
From food additives to pedagogy, psychotherapeutic techniques to retirement savings, it would take a hundred lifetimes for you to acquire the 200 PhDs needed to answer these questions for yourself.
Thankfully, we don't have to answer those questions for ourselves. Instead, we defer to expert agencies: governmental regulators that assess truth claims by soliciting input from all comers, publicly deliberating about the evidence they've gathered, and then making a rule in public. These regulators are meant to be experts, nonpartisan and neutral, operating with the highest degree of probity, recusing themselves in the event of even a whiff of conflict.
It has to be that way. You may not be able to assess claims about the safety of vaccines – or opioids – but you can see for yourself whether the FDA is full of ex-pharma execs. You can see for yourself whether pharma company lobbyists all used to work for the FDA. You don't need to be a virologist or a cell biologist to tell whether the system that's supposed to sort truth from lies is fit for purpose.
It is not fit for purpose. When arguments broke out over covid vaccines, many vaccine advocates characterized their opponents as foolish people engaged in foolish conspiratorialism. They argued that the corporations that produced the vaccines and the regulators who oversee them were intrinsically trustworthy, and on that basis, we should all get vaccinated.
Now, I happen to be a big believer in vaccination. I've had so many covid jabs that I glow in the dark and get five bars of 5G in a coal-mine. But I didn't get vaccinated because I trust pharma companies or their regulators. A string of scandals – most notably the Sacklers' Oxycontin murder-spree – has proven that pharma will kill you for a nickel and that the FDA will let them get away with it:
https://pluralistic.net/2024/03/25/black-boxes/#when-you-know-you-know
From tobacco safety to food safety to the climate emergency, it's obvious that the system of expert agencies that we rely on was terminally compromised by corporate power and regulatory capture:
https://pluralistic.net/2022/06/05/regulatory-capture/
This is the epistemological void we were already adrift in before AI came along: a world of unresolvable, urgent, terrifyingly high-stakes questions.
When you get a call from "your bank" and accede to the demand that you hand over all kinds of personal information before they will disclose the call's purpose, you're not being naive or foolish – you're doing the thing that our banks have conditioned us to do for years by engaging in exactly this behavior (my bank did this to me this week!). Why are banks allowed to get away with engaging in this kind of outrageous conduct? Because – as we've repeatedly discovered through crisis after crisis – banks are too big to fail, too big to jail, and too big to care.
Why is it so believable that a loved one might call you in a panic because they've been arrested or injured and need an immediate cash payment before they can get bail or doctor's treatment? Because our criminal justice system and our health care system are already plagued by this kind of inhumane, high-handed, extortionate behavior.
Why do you fall for a deepfake of celeb shilling for supplements or a shitcoin? Maybe it's because celebs actually shill for supplements and shitcoins, and face no consequences for helping rope us all into scams:
https://gizmodo.com/matt-damon-crypto-com-crypto-bitcoin-1850282413
Not just celebs – also our newspapers:
https://www.nytimes.com/interactive/2022/03/18/technology/cryptocurrency-crypto-guide.html
We laugh when other people fall for newspaper articles making absurd claims – but after living through a time in which our most respected journalistic outlets credulously helped a dishonest government lie the world into a war that's still smoldering more than a generation later, who can be sure when to trust the papers?
https://www.nytimes.com/2004/05/26/world/from-the-editors-the-times-and-iraq.html
One of the reasons it is so hard to agree on covid's death-toll is that so many of the people who died of covid were already compromised by chronic illnesses or "pre-existing conditions" from cancer to heart disease. Those people did die of covid – and they died of cancer or heart disease or some other comorbidity. Covid was an opportunistic infection that inflicted disproportionate harms on people who were already suffering.
The epistemic void created by AI is another opportunistic infection. Our ability to know things has been in decline for generations, as monopolies shredded our truth-assessment systems, rendering us all incapable of knowing the truth in a world where believing lies could bankrupt you or kill you dead.
If you could trust your government's expert agencies and if they had reliable systems for making their findings known; if your bank was banned from engaging in conduct indistinguishable from phishing; if the health-care and criminal justice systems never forced the people they ensnared to call their relatives and beg for money, then deepfakes would have a much harder time penetrating our cognitive immune systems.
It's not so much that AI is a powerful way of lying – rather, we have been made progressively more vulnerable to lies for decades, leaving us at an epistemic death's door, and AI has arrived to deliver the coup de grace.
The Right Word is Wrongness https://www.meditationsinanemergency.com/the-right-word-is-wrongness/
Yes Obviously the Senate Should Be Abolished https://www.hamiltonnolan.com/p/yes-obviously-the-senate-should-be
#20yrsago Goth day at Disneyland photos https://flickr.com/photos/doctorow/tags/batsday/
#20yrsago HOWTO run a successful sf convention room party https://www.nielsenhayden.com/makinglight/how_to_throw_a_1/
#20yrsago Yahoo: Go ahead and remix our brand https://web.archive.org/web/20061111175912/http://www.ysearchblog.com/archives/000348.html
#10yrsago The Equation Group’s sourcecode is totally fugly https://web.archive.org/web/20160818012451/https://www.cs.uic.edu/~s/musings/equation-group/
#5yrsago Bubble https://pluralistic.net/2021/08/21/podcasting-as-a-visual-medium/#huntr
#1yrago Melissa Mendes's "The Weight" https://pluralistic.net/2025/08/21/weighty/#edie-is-a-badass
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
London: AI and the Enshittification of the Media, NUJ (Sep 2)
https://www.nuj.org.uk/learn/ems-event-calendar/ai-and-the-enshitification-of-the-media.html
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Victoria: Munro's Books (Oct 20)
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Maybe it seems weird that AI bosses won't stop publicly rending their garments about the terrible potential of their products, from the jobspocalypse that will ensue when AI can do our jobs better than us, to the impending moment when the word-guessing programs learn too many words, wake up and turn us all into paperclips.
It seems weird that they won't stop fretting about this terrible potential – until you realize that every public pronouncement about this terrible potential is also a public boast about its potential, period.
That's very, very important, because all AI really has is potential. Actual, existing AI is useful at the margins, if you're already a skilled practitioner who can discern correct from incorrect outputs, and if you integrate AI judiciously so that it doesn't overwhelm your ability to pay attention to those outputs and apply your discernment to them:
https://pluralistic.net/2026/07/28/hitl-ers/#ai-ai-oh
In other words, AI is mostly a novelty, a heavily subsidized toy that produces little more than distraction. Where AI does produce value, that value is comparable to a plug-in, a new feature for your word processor or image/sound/video-editing package that might help you do your job somewhat better, or it might not.
That doesn't make AI useless, it just makes it a normal technology: useful for some, useless for others, capable of being abused and likely to waste a lot of time when used unwisely:
Normal technologies are fine. But normal technologies do not warrant the massive economic and political commitments that have been bestowed upon AI: a trillion dollars in the past year alone, and the world's civil servants fired en masse and replaced with AI:
https://pluralistic.net/2026/05/13/vibe-governance/#k-hole
The people who have committed our society and its resources to an all-or-nothing bet on AI will tell you that AI is the everything machine, but when pressed, they will confess that AI is about to become the everything machine, for example, once AI starts doing AI research, a thing that AI cannot do:
https://www.normaltech.ai/p/ai-agents-cant-yet-do-open-ended
This is a civilizational act of Magic Underpants Gnomery, and every day that it goes on is a day when more economic, climate and political costs of AI are imposed on all of us. Scientific journals, open source repositories and even science fiction magazines are being overwhelmed by slop, whose perpetrators and apologists insist that soon, AI will realize its potential and the slop will be transformed into gold.
That's why AI bosses are so committed to talking up AI's destructive potential: because destructive potential is nonetheless potential. The moment we stop believing in that potential is the moment that we stop supplying AI companies with bales of cash to shovel into their money-furnaces so that they can afford to sell hundred dollar bills for a dollar each to Elon Musk cultists who want to generate child porn and pictures of Sonic the Hedgehog with giant boobs.
AI does have destructive potential. It has the potential to destroy the productive economy when an AI salesman convinces your boss to fire you and replace you with chatbots that can't do your job:
https://pluralistic.net/2025/03/18/asbestos-in-the-walls/#government-by-spicy-autocomplete
AI has destructive potential because bosses are trapped in a prisoner's dilemma where none of them can admit that the money they've spent – and the jobs they've destroyed – chasing AI has been wasted, and so other bosses bet even harder:
https://pluralistic.net/2026/08/01/dare-snot/#i-will-fucking-piledrive-you-if-you-mention-ai-again
AI has destructive potential because the data-center bubble has convinced credulous town officials to throw out environmental and planning review, seize people's home and farms, and carpet the countryside with giant data centers (many of which will never be built):
https://www.404media.co/people-hate-datacenters-survey-finds/
AI has destructive potential because it is consuming scarce water and energy and emitting gigatons of carbon:
https://www.404media.co/even-the-u-s-government-says-ai-requires-massive-amounts-of-water/
This is the destructive potential we need to be hammering at, because this isn't the kind of destructive potential that translates into productive potential that will someday make the AI bet pay off. Quite the opposite: this is all about the potential of AI to destroy the economy and consume your retirement savings:
Just as importantly: we have to stop amplifying tech bosses' chosen narratives about their products' destructive potential, because this helps them raise more money and do more terrible things. Bernie Sanders needs to stop insisting that the US government should own 50% of the money-losingest corporations the world has ever seen and start talking about how they will not get a government bailout when their investment bubble bursts. We need to stop talking about AI "haves" who will enjoy the awesome potential of AI, and AI "have-nots" who will fall behind.
We need to stop talking about "AI safety" and the possibility of "rogue AI" destroying the world. When an AI company's security tool "escapes containment" and hacks someone else's servers, we need to ask the company "Why do you suck so bad at building secure sandboxes for your hacking tools?" rather than "Why are your hacking tools so amazingly powerful?"
Above all, we need to stop talking about AI as exceptional. AI is normal. A normal technology has some uses, but isn't useful for all things and all people. A normal technology isn't inevitable, it's something you decide whether you want to use or not.
Treating AI as unexceptional is the best way to halt the destructive march of AI companies and their impact on jobs, the climate and the economy. But treating AI as unexceptional requires that we stop talking about AI as if it were exceptionally evil. Yes, some people who use AI experience severe mental problems, but that's not because AI is a Lovecraftian horror that destroys your brain and your capacity for rational thought if you use it. It's not a basilisk. AI is like a carny ride that triggers cardiac events in riders who never knew they had a problem because they never experienced those particular g-stresses – it's not something that induces vulnerability, it's something that triggers vulnerability:
https://pluralistic.net/2026/06/03/mission-space/#gsd
Using AI doesn't make you evil, nor does it risk your sanity – no more than doing any of the other dangerous, compromised, unsustainable things that constitute our daily lives in this fraught moment. The world will be better off when the AI companies are bankrupt and their servers are sold off at ten cents on the dollar – but using those servers to run open models in modest, careful ways won't infect you with their wickedness. They are not stained with communicable sin. They're just computers. They are unexceptional.
One way for a technology to be normal is for it to be produced and marketed by an awful corporation that wants to do terrible things. This isn't to say that "all technologies are dual use, and you have to take the good with the bad." That's the inevitabilist argument of vulgar Thatcherites who insist – as Margaret Thatcher did – that "there is no alternative," and we have to accept their abuse if we want to reap the benefits of the technology.
The normal way to deal with this is to reject vulgar Thatcherism in favor of heroic Gibsonism, thundering William Gibson's rallying cry, "the street finds its own use for things," as we seize the means of technology and use it in the ways that benefit us, while restricting, banning, or blocking the uses that harm us:
https://pluralistic.net/2026/03/17/technopolitics/#original-sin
To treat AI as exceptionally evil is to elevate the mediocrities who run AI companies to super-villain status, a status in which they positively revel. A serial liar like Sam Altman will someday trip over his own dick and end up in a cell for securities fraud – unless we keep exalting his evil to Satanic scale, in which case he might make himself "too big to jail":
https://time.com/article/2026/05/26/sam-altman-ai-job-losses-openAI-/
Altman is a con-man and a stock swindler, not a super-genius. The more we describe his products as possessing a special kind of durable evil that will endure even after his company fails and he is condemned to history's ash-heap, the more we help Altman raise money for his chatbot Ponzi. Normal technology isn't a cursed artifact. That's something you find in a lich-king's tomb. We need to stop helping Altman burnish his reputation as a lich-king and stop treating AI like it's magic.
There's a technical term for the kind of tech criticism that inadvertently helps tech bros sell their swindle: "criti-hype," Lee Vinsel's term for "tak[ing] the sensational claims of boosters and entrepreneurs, flip[ping] them, and start talking about 'risks'":
https://peoples-things.ghost.io/youre-doing-it-wrong-notes-on-criticism-and-technology-hype/
In other words, to commit criti-hype is to repeat the marketing claims of people like Sam Altman and then add, "(and that's bad)" in parentheses at the end. These guys – these terrible, mediocre, boring-ass losers – are bullshit factories, ejecting fountains of nonsense about AI. The right way to criticize them is to point out that they're lying – not to repeat their lies as warnings.
Hook and Squeeze https://data4democracy.substack.com/p/hook-and-squeeze
#25yrsago Dot-com crash toilet paper https://web.archive.org/web/20010822220826/http://news.cnet.com/news/0-1007-200-6908350.html
#25yrsago Associated Press says a single sentence excerpt is not fair use https://web.archive.org/web/20050717075914/http://www.infoanarchy.org/?op=displaystory;sid=2001/8/17/202249/240
#15yrsago German Pirate Party poised to win first federal election https://torrentfreak.com/german-pirate-party-on-course-to-election-win-110820/
#15yrsago Understanding the Nym Wars https://epeus.blogspot.com/2011/08/google-plus-must-stop-this-identity.html
#15yrsago Journalism school teaches students pre-digital newspaper production techniques https://journoterrorist.com/2011/08/02/paperball2/
#15yrsago 90 percent of US net users don’t know from crtl-F https://www.theatlantic.com/technology/archive/2011/08/crazy-90-percent-of-people-dont-know-how-to-use-ctrl-f/243840/
#15yrsago Bruce Sterling’s Augmented Reality project https://web.archive.org/web/20110827010512/https://www.wired.com/beyond_the_beyond/2011/08/augmented-reality-science-fiction-writer-becomes-augmented-reality-developer/
#10yrsago Woman sues cops because they destroyed her empty house, thinking a suspect was hiding in it https://www.techdirt.com/2016/08/19/woman-sues-after-police-destroy-her-home-during-10-hour-standoff-with-family-dog/
#10yrsago US Army committed $6.5 trillion in accounting fraud in one year https://www.reuters.com/article/us-usa-audit-army-idUSKCN10U1IG/
#10yrsago Candid Republican operators admit that voter ID laws are about disenfranchisement https://www.brennancenter.org/our-work/research-reports/when-politicians-tell-truth-voting-restrictions
#1yrago Become unoptimizable https://pluralistic.net/2025/08/20/billionaireism/#surveillance-infantalism
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
London: AI and the Enshittification of the Media, NUJ (Sep 2)
https://www.nuj.org.uk/learn/ems-event-calendar/ai-and-the-enshitification-of-the-media.html
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Victoria: Munro's Books (Oct 20)
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

You don't have to believe that AI "art" is any good (I don't), nor do you have to believe that AI "art" can be any good (I don't) to understand that the reason that the capital markets are putting trillions into AI is that they believe they can fire workers of every kind and replace them with AI:
https://pluralistic.net/2025/03/18/asbestos-in-the-walls/#government-by-spicy-autocomplete
I'm an artist and a worker. I want to protect my labor interests. So do my peers from across the "creative industries." But a sizable group of my peers think the way we're going to protect our interests is by expanding copyright so that it's unambiguously illegal to scrape the internet, analyze the files retrieved by those scrapers, and publish that analysis (a process more familiarly known as "training AI"):
https://pluralistic.net/2023/09/17/how-to-think-about-scraping/
This is a losing strategy. First, because banning scraping, or requiring permission to count the elements in creative works, or demanding a license to publish collections of facts about copyrighted works will inflict enormous collateral damage on a wide variety of socially beneficial activities. From the OED to search engines to the Internet Archive, so many beneficial activities rely on the fact that copyright permits unlicensed collection and analysis of every copyrighted work as a single, massive corpus, and copyright allows the publication of that analysis without permission from the creators of the works it analyzes.
A lot of people who are (rightfully) very angry about AI dispute this. They believe that they can craft an "AI training" law that would ban scraping, analysis and publication when these activities are part of AI training, but not when they're undertaken for a benign purpose. I am very, very skeptical of this. After 25 years of watching internet policy go badly awry, to the great detriment of workers of all kinds and everyday users, it is my professional, considered opinion that drafting a statute that only stops these "bad" activities is much, much harder than these people think, and may actually be impossible.
I think some artists advocating for a copyright-based solution to AI's war on labor understand this and have decided that they're willing to catch a lot of dolphins in these legal tuna-nets they're hoping to get from Congress. I get that: there are always trade-offs, and the perfect can't be the enemy of the good.
But I think they're making the wrong trade-off, and not just because I value archives, accountability corpuses, large-scale linguistic research and search engines. I think they're making the wrong trade-off because copyright will not protect their livelihoods from AI-based wage erosion.
Here's why: the theory of copyright as an "artist's right" is premised on the idea that we artists get these exclusive rights, which we use in our bargaining with media companies and other intermediaries. It's a (pseudo) property right, and it's sub-licensable. Just as an entrepreneur might get the contract to supply catering for a sports stadium and then parcel out the pretzel stand, beer bar, and pizza concessions to subcontractors, we're meant to sell our English rights, foreign language rights, graphic novel rights, film rights, audio rights, (and so on) to a variety of media companies.
To bargain successfully, it's not only necessary for you to have something valuable to trade: you also need to have leverage. You need to have options. The other side has to believe that if they lowball you, you will go do a deal elsewhere.
This is where copyright fails to serve creative workers. Even at the best of times, the world naturally produces an oversupply of would-be professional artists, and a sufficiency of the talented to fill most of the workaday niches in our field. Even exceptional artists – and exceptional works of art – are often commercial flops, for reasons that aren't always well understood (though sometimes it's a self-fulfilling prophecy, where a media company buys the rights and then loses confidence in the work and does not exert itself in the marketing of the work).
These are not the best of times. Decades of lax antitrust enforcement has boiled the "creative industries" down to 5 publishers, 4 studios, 3 labels, 2 app stores, and one company that's in charge of all the ebooks and audiobooks.
Since the 1976 Copyright Act, Congress has acted time and again to broaden copyright. Today's copyright lasts longer, restricts more uses, extends to more kinds of works, and carries stiffer statutory penalties for infringement ($150,000 per download!). The media companies we creative workers bargain with are larger, richer and more profitable than at any time in history – and we are poorer. The share of those massive profits that ends up in our pocket is lower than ever – and we don't just get smaller slices of that larger pie, those slices are smaller than the slices we used to get, when the pie was much smaller. The rising tide of copyright expansion lifted our bosses' boats – even as our dinghies filled with bilge and sank.
How could we get so much more to bargain with, only to bargain it all away, for less money than we used to get for a much smaller bundle of rights? Simple: giving us rights did not give us leverage. Giving us more rights without giving us more bargaining power is like giving your bullied schoolkid extra lunch-money. There's no amount of lunch-money that will get that kid fed; but if you keep increasing how much money the kid gets, the bullies will end up so rich that they can afford to run a global campaign demanding that we all think of those poor hungry kids and send them even more lunch money.
Copyright's failure to deliver for creative workers doesn't mean that we're doomed to poverty. Our works are generating record profits for our bosses, and there are plenty of ways to change the "distributional outcomes" (the phrase economists use for "who gets what") in arts/labor policy. In 2022, I co-wrote Chokepoint Capitalism along with the eminent Australian copyright scholar Rebecca Giblin. The whole book is full of these pro-worker arts policies:
https://pluralistic.net/2022/08/21/what-is-chokepoint-capitalism/
Rebecca and I start from the premise that artists are workers, not the small businesses that our bosses insist we see ourselves as. The idea that an artist is an LLC with an MFA fits in very neatly with copyright: you're getting this bundle of exclusive rights from Congress and then you bargain, business-to-business, with other companies out there in the world, selling those rights for the best price you can get. This approach rarely works, and when it does, it works badly. 50 years of more copyright, richer bosses, and poorer artists put the lie to the "LLC with an MFA" approach.
If we're workers, then we derive our power from labor rights. The Writers Guild – the only creative workers in world history to have comprehensively beaten AI in their workplace – won their AI fight with a strike:
https://pluralistic.net/2023/10/01/how-the-writers-guild-sunk-ais-ship/
The Hollywood guilds are able to pursue a limited form of "sectoral bargaining" (where all the workers in a field bargain with all its bosses) called "multi-employer bargaining." Bosses hate sectoral bargaining, and in 1947 they got it banned outright through the Taft-Hartley Act.
Getting other kinds of creative workers into multi-employer bargaining arrangements will be a lot of work – and repealing Taft-Hartley and restoring sectoral bargaining will be even harder. But just because it's hard to do the thing that works, it doesn't follow that we should do the easy thing that doesn't work.
Compared to winning more labor rights, getting more copyright will be easy. That's because our bosses want more copyright. When we demand more copyright, our bosses – the most powerful, profitable media companies in human history, grown rich off our labor – will fight alongside of us.
But media companies don't want to stop AI from depriving us of our wages. Quite the contrary! The whole reason that the Writers Guild had to go on strike was that movie studios – not Openai or Anthropic – wanted to replace them with AI. The same studios that are suing the AI companies for "mass copyright theft" have made it very clear that they want to buy chatbots from those AI companies and use them to erode our wages and thin our ranks. The copyright lawsuits our bosses are waging against the AI companies are intended to force tech companies to pay for licenses before they train their chatbots on our work. But they won't be paying us for those licenses – they'll be paying our bosses.
The AI copyright fight isn't being fought to protect your wages – it's being fought to see whether your lost wages end up in the pockets of a tech boss or a media boss. AI copyright suits are a fight over who's going to get the lion's share when they eat you up for dinner. They're not a way to keep you off the menu.
This becomes more obviously true with each passing day, and this morning, the world got its clearest example of what a poor substitute copyright is for fundamental human rights, like labor rights and privacy rights.
Last year, Spirit Airlines went bankrupt, a casualty of a monopolized aviation sector and Trump's oil price surge. Ever since, vultures have circled its carcass, picking off its assets in a string of auctions conducted by Spirit's bankruptcy trustees. Today, those trustees announced that they had sold all of Spirit's employees' data to Google, for use in AI training:
https://www.axios.com/2026/08/17/google-spirit-airlines-bankruptcy
Every email, every memo, every calendar entry. Oceans of sensitive, personal information, all to be shoveled directly into the bottomless maw of Google's AI training systems. This training data includes messages between colleagues and with outside parties about workers' romantic lives, their health, their family situations. These workers' most private lives will end up as fodder for a Google chatbot.
Now, all of these workers have a copyright in all of that work. Under international copyright treaties and US law, copyright "inheres at the moment of fixation of a work of human creativity." The very instant a worker sets fingers to keyboard and types out a message with even the smallest quantum of creativity, a new copyright springs into existence, giving the copyright holder 90 years' worth of control over it.
But even though every one of those emails and messages and memos was written by a human being working for Spirit, the copyright over those works does not belong to the workers. Every single one of them will have signed an employment agreement that designates their emails and other copyrightable work as "works made for hire," owned by Spirit Airlines, which means that their work is now an asset in Spirit's bankruptcy estate. That's why all that personal information is about to be transferred to a new corporate owner, Google, who can do anything they want with it.
We know how terrible this kind of disclosure will be for workers. In 2001, the criminal enterprise Enron collapsed after the extent of its fraud was revealed. In the ensuing litigation, Enron's bankruptcy overseers decided that it was too expensive to purge the company's email servers of personal information before entering it into evidence. That meant that once the court battles were over, all the Enron employees' emails entered the public domain as part of the court record:
https://en.wikipedia.org/wiki/Enron_Corpus
The "Enron Corpus" is a foundational data-set in modern computer science. Academics analyzed the data to do pioneering work on machine learning and social graph theory, which found its way into the design and operations of social media companies, who learned how to spot and manipulate social connections by studying it.
The Enron Corpus isn't just a data-set, though. It's a privacy catastrophe, full of sensitive personal information that haunts the 158 employees whose correspondence is now permanently afloat upon the internet.
Why was the Enron Corpus so exploitable? Because US labor law does not protect this kind of sensitive information when it is in your employer's hands. In fact, if your boss ends up with a trove of your personal information in the form of emails, calendar entries and files, you will typically be blamed for it: "Why did you use your work computer for personal activities?"
But anthropologists who study computer usage have known for decades that everyone ends up with personal data on their work devices. What's more, this problem is only getting worse, because (thanks to weak labor laws), we're expected to work longer hours and to be on call when we're not at the job, which means that you're often dealing with personal crises after hours from your desk, and dealing with work crises at home from your sofa.
Any fit-for-purpose labor rights regime would recognize that your privacy rights must extend to the data that finds its way onto your boss's computers, even if you put that data there. Any failure to recognize this bedrock fact gives employers free license to plunder and exploit your personal information.
Of course, labor law isn't the only way to protect private information. While labor law should contain explicit, job-related privacy guarantees, privacy law should protect all our privacy (after all, Spirit's servers are also full of emails and messages from Spirit's passengers).
Unfortunately for anyone who ever flew on Spirit – or anyone who worked for them – American privacy law is all but dead. America's last consumer privacy law went into effect in 1988, when the Video Privacy Protection Act made it illegal for video-store clerks to disclose your VHS rental records.
Google says it won't use your profile or frequent flier info to train its model, but they haven't made the same promise about the millions of messages that passengers exchanged with the airline. Google has also promised to use "de-identification" algorithms to purge the Spirit customer, supplier and employee data of personal information. But "de-identification" is a pipe-dream, widely understood by security experts as a form of wishful thinking by companies that want to exploit your personal information while still insisting that they aren't violating your privacy. In reality, "de-identified" data is always vulnerable to "re-identification" attacks:
https://pluralistic.net/2021/04/30/dox-the-world/#experian
The collapse of privacy and labor rights in post-Reagan America and the mass expansion of copyright over the same period are part of the same phenomenon, aspects of two generations' worth of policies designed to benefit capital at the expense of workers, and corporations at the expense of consumers.
As consumers, we're told to substitute shopping for legal rights: if a corporation wrongs you, it's easier and quicker to "vote with your wallet" than it is to sue them or ask the government to intervene. Substituting shopping for politics has been a total failure. Shopping your way out of a monopoly is like recycling your way out of a wildfire:
https://pluralistic.net/2026/05/21/purity-culture/#stop-fucking-that-chicken
As creative workers we were told to stop thinking of ourselves as workers altogether, to become small businesses, and to use the LLC With an MFA method to bargain our way out of exploitative arrangements. This, too, has been a failure:
https://pluralistic.net/2026/03/03/its-a-trap/#inheres-at-the-moment-of-fixation
The sale of Spirit's data to Google for AI training shows us that privacy and labor rights are indispensable. We can't substitute market mechanisms like comparison shopping or individual contract negotiations for broad, systemic, inalienable rights backstopped by law.
By demanding the copyright our bosses love, we're seeking the right to be angry about AI, even as the AI companies and our bosses cut deals to train chatbots with our work, which they will use to attack our livelihoods.
Once we stop pretending to be small businesses, once we abandon the fantasy of LLCs with MFAs, we can join with every worker in every industry in demanding sectoral bargaining; and with every consumer in demanding privacy rights. Winning privacy and labor struggles means more than the right to be angry about AI – that's the right to do something about it.
Zoomers don't know what Usenet is https://tchotchke.substack.com/p/zoomers-dont-know-what-usenet-is
When the Shortage is the Strategy https://nooneshappy.com/article/when-the-shortage-is-the-strategy/
Can Canada function without American tech? https://www.youtube.com/watch?v=WwoL6OGk_2Y
Elon Musk made flying even worse so Palantir could profit https://www.theverge.com/transportation/981194/faa-air-traffic-elon-musk-peter-thiel-palantir
#25yrsago IP and scientific publishing https://web.archive.org/web/20011001203058/http://www.abc.net.au/rn/talks/bbing/stories/s345514.htm
#20yrsago British air travelers kick brown “terrorists” off their planes https://web.archive.org/web/20060823104858/http://www.dailymail.co.uk/pages/live/articles/news/news.html?in_article_id=401419&in_page_id=1770&ico=Homepage&icl=TabModule&icc=NEWS&ct=5
#15yrsago “Probability neglect”: why policy-makers are constitutionally incapable of formulating evidence-based anti-terrorism policy https://web.archive.org/web/20111015040753/https://opim.wharton.upenn.edu/risk/library/J2011OBHDP_APM,AT,HK_PolicymakersDilemma.pdf
#15yrsago TSA can’t explain why “enhanced patdowns” are legal https://web.archive.org/web/20151203033820/http://flyingwithfish.boardingarea.com/2011/08/18/the-legality-of-the-tsas-enhanced-pat-down-authority/
#15yrsago The Onion: We did a paywall because British people like paying for the Web https://web.archive.org/web/20110911175335/http://www.avclub.com/articles/about-the-onions-new-paid-content-system,60129/
#5yrsago Hench https://pluralistic.net/2021/08/19/failure-cascades/#natalie-zina-walschots
#5yrsago Machine learning's crumbling foundations https://pluralistic.net/2021/08/19/failure-cascades/#dirty-data
#1yrago Charlie Jane Anders' "Lessons in Magic and Disaster" https://pluralistic.net/2025/08/19/revenge-magic/#liminal-spaces
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
London: AI and the Enshittification of the Media, NUJ (Sep 2)
https://www.nuj.org.uk/learn/ems-event-calendar/ai-and-the-enshitification-of-the-media.html
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Victoria: Munro's Books (Oct 20)
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Technofeudal Enshittification (Fucking Cancelled)
https://www.fuckingcancelled.com/p/technofeudal-enshittification-with
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Nobody explains copyright like Jennifer Jenkins, the director of the Duke Center for the Public Domain, in which capacity she is responsible for the annual New Year's roundups of all the materials entering the public domain (a series that started in the decades during which the public domain was frozen by the Sonny Bono Copyright Act):
https://pluralistic.net/2023/12/20/em-oh-you-ess-ee/#sexytimes
Jenkins has a gift for making one of the most complicated, worst understood, most consequential areas of law not only comprehensible, but also fascinating. Her late 2023 explanation of what "Mickey Mouse's copyright is expiring" actually meant was the single best explainer on the subject, in a crowded field:
https://pluralistic.net/2023/12/15/mouse-liberation-front/#free-mickey
Small wonder that she's the go-to copyright and trademark expert for so many media outlets. Perhaps you heard her Planet Money segments on which superheroes are in the public domain:
https://www.npr.org/transcripts/969512231
Jenkins' flair for legal communications carries over to her scholarly work, of course, which is why her Open Copyright Casebook is a standard text for American law schools:
Jenkins co-wrote the Casebook with her husband, the equally erudite and expert James Boyle. It's just one of their many fruitful collaborations; they are also the writing team behind THEFT! A History of Music, the greatest graphic novel ever created about the history of music, music law, music censorship, and the music industry:
https://web.law.duke.edu/musiccomic/
Last year, Jenkins published Music Copyright, Creativity, and Culture, an Oxford University Press title that fuses her scholarly and popular work in a generalist textbook on the legal framework for music that will forever change how you think about music. Now, a second edition, with a lengthy section on new music litigation, AI copyright fights, and the issue of uncompensated labor is available as an open access download:
https://web.law.duke.edu/cspd/musiccopyright/
Music Copyright weaves together the economic, cultural, political and artistic history of music, pulling on historic threads ranging from antiquity to medieval Europe to the age of mechanical reproduction to describe changing views of musicians, their audiences, and religious and political leaders on what constituted music, who was allowed to make music, and what music was for. In so doing, she firmly establishes the extremely contingent nature of our present-day norms around music, showing that the "natural" present-day assumptions about who gets paid, who pays, and when payment (or permission) is required are anything but, and are always in flux.
For obvious reasons, much of Jenkins' text describes these changes in the context of the record, the radio, satellite transmission, P2P file-sharing, and digital sampling (along with a chapter on AI). These examples are liberally illustrated with links to musical excerpts that bring the subject to life (these are presented as hotlinks in the ebook; if you're reading the print edition, you can use the book's companion website:)
https://web.law.duke.edu/cspd/musiccopyright/
Interspersed with these histories and analysis are lengthy, extremely on-point excerpts from THEFT!, her graphic novel history of music. These enliven the text as much as the music samples, making this textbook as entertaining as it is informative.
Of especial interest – and importance – are the long sections on the courtroom battles of Ed Sheeran, Katy Perry, and Pharrell Williams over similar "grooves" and "vibes" to other songs, some of them well-known and some quite obscure:
https://pluralistic.net/2022/04/08/oh-why/#two-notes-and-running
These cases highlight the fundamental incoherence of music copyright, a system composed of improvised responses to new technologies, each layered atop the last in a messy pile that virtually no one understands.
Jenkins understands it, though. I've been reading, writing, and debating about this stuff since the late 1990s, and I learned something new on every page of this delightful book. This should be required reading for anyone who makes music, loves music, or cares about musicians and the arts more generally. It's a towering accomplishment and a brilliant read.
Who Crapped on Johnny Depp's Bed? https://www.youtube.com/watch?v=vGt7-WnWdhE
No-One Makes You Shop at Amazon https://www.programmablemutter.com/p/no-one-makes-you-shop-at-amazon
Paramount’s Merger Strategy: Empty Promises and Empty Threats https://prospect.org/2026/08/14/paramounts-merger-strategy-empty-promises-threats-justice-department-antitrust/
they_live_adblocker https://github.com/davmlaw/they_live_adblocker
#25yrsago RIP, The Industry Standard, Palm buys BeOS https://web.archive.org/web/20010927192339/http://www.wired.com/news/business/0,1367,46113,00.html
#25yrsago Smart dust sensors https://web.archive.org/web/20011112010004/http://www.smalltimes.com/document_display.cfm?document_id=1935
#25yrsago Pentagon patents onion-routing https://web.archive.org/web/20010912222427/http://www.wired.com/news/politics/0,1283,46126,00.html
#25yrsago Coltan: the conflict mineral in our gadgets https://www.nytimes.com/2001/08/12/magazine/the-dirt-in-the-new-machine.html
#25yrsago Danny Goodman Talks About HyperCard https://web.archive.org/web/20011214114614/http://www.oreillynet.com/pub/a/mac/2001/08/17/goodman.html
#25yrsago Report an insecure website, win a visit from the FBI https://web.archive.org/web/20010820110330/http://www.linuxfreak.org/post.php/08/17/2001/134.html
#20yrsago Copyright wars: film-makers eats themselves https://web.archive.org/web/20070318010544/https://www.laweekly.com/film+tv/film/freedom-of-information/14244/
#20yrsago RyanAir to UK govt: ease off on security or we sue https://www.theguardian.com/business/2006/aug/18/theairlineindustry.terrorism
#20yrsago Federal court bans Bush’s warrantless spying on Americans https://edition.cnn.com/2006/POLITICS/08/17/domesticspying.lawsuit/index.html
#20yrsago Western millionaires plotted Equatorial Guinea coup as a game https://web.archive.org/web/20071114211448/https://www.salon.com/books/review/2006/08/17/roberts/index_np.html
#20yrsago Sweden’s Pirate Party – political arm of the pro-piracy groundswell https://web.archive.org/web/20060820093355/https://www.wired.com/news/technology/1,71544-0.html
#20yrsago Hair-Gel Bombers win war on bras https://www.huffingtonpost.co.uk/entry/us-authorities-leave-gel_n_27402
#20yrsago Would a hair-gel bomb actually work? https://seclists.org/interesting-people/2006/Aug/86
#20yrsago The Pirate Bay’s backstory https://web.archive.org/web/20060901180116/https://www.wired.com/news/technology/1,71543-0.html
#20yrsago AOL will dig for buried platinum and gold in spammer’s Mom’s yard https://www.nbcnews.com/id/wbna14365934
#15yrsago Charlie Stross on network security in 2061 https://www.antipope.org/charlie/blog-static/2011/08/usenix-2011-keynote-network-se.html
#15yrsago Damning 2007 letter asserts that phone hacking was an open practice at News of the World https://www.theguardian.com/media/2011/aug/16/phone-hacking-now-reporter-letter
#15yrsago In-game Ponzi nets US$50K https://web.archive.org/web/20110921052125/http://gamergaia.com/pc/1724-eve-online-space-heist-one-trillion-isk.html
#15yrsago Copyright troll handed ass (again), tries saddest trick ever to get out of paying its victim’s legal bills https://arstechnica.com/tech-policy/2011/08/righthaven-rocked-owes-34000-after-fair-use-loss/
#15yrsago English cops arrest man for planning water-fight via Blackberry Messenger https://www.theguardian.com/media/2011/aug/15/essex-water-fight-blackberry-messenger
#15yrsago Woman who recorded Massachusetts police beating charged with illegal wiretapping https://www.masslive.com/news/2011/08/videographer_of_alleged_melvin.html
#15yrsago Criticism of a brand lowers the self-esteem of its adherents https://arstechnica.com/science/2011/08/users-treat-criticism-of-favorite-brands-as-threat-to-self-image/
#15yrsago Homeopathy multinational sues blogger over statements that its mythological curative had “no active ingredient” https://web.archive.org/web/20110930131033/http://www.blogzero.it/contatti/prova/
#15yrsago Edinburgh Fringe show asks audience to shred banknotes https://www.theguardian.com/culture/2011/aug/16/crunch-edinburgh-festival-shred-cash
#15yrsago CCTV deterrence and the London uprising https://www.theguardian.com/technology/2011/aug/17/why-cctv-does-not-deter-crime
#15yrsago Paul Krugman: save the economy by staging an alien invasion hoax https://comicsalliance.com/watchmen-paul-krugman-alien-invasion/
#15yrsago Minecraft creator challenges trademark belligerents to winner-take-all Quake deathmatch https://web.archive.org/web/20110817205045/http://notch.tumblr.com/post/9038258448/hey-bethesda-lets-settle-this
#15yrsago Muphry’s Law: the inevitability of typos in discussions of typos https://web.archive.org/web/20101227141449/https://www.editorscanberra.org/muphrys-law/
#15yrsago Copyright complaint as phishing email https://memex.craphound.com/2011/08/18/copyright-complaint-as-phishing-email/
#15yrsago Rep Allen West pens “dumbest thing ever written on congressional stationery” https://web.archive.org/web/20110914030034/https://thinkprogress.org/security/2011/08/17/297619/allen-west-nuts/
#10yrsago The NSA’s program of tech sabotage created the Shadow Brokers https://web.archive.org/web/20160818132904/https://www.wired.com/2016/08/shadow-brokers-mess-happens-nsa-hoards-zero-days/
#10yrsago Walmarts are high-crime zones thanks to staff cuts, but America gets the bill https://web.archive.org/web/20160818000539/https://www.bloomberg.com/features/2016-walmart-crime/
#10yrsago DoJ says it will end private federal prisons https://www.motherjones.com/politics/2016/08/department-justice-plans-end-private-prison/
#10yrsago Fiction: Sgt. Augmento, Bruce Sterling’s robots-take-our-jobs story https://web.archive.org/web/20160818161624/https://motherboard.vice.com/read/sgt-augmento
#10yrsago Las Vegas: high unionization rates mean smaller wage-gaps for women, especially older women https://www.nytimes.com/2016/08/17/opinion/how-unions-help-cocktail-servers.html
#10yrsago The incredible true story of the Epcot Horizons superfans who ruled the ride https://web.archive.org/web/20160822031741/https://dangerousminds.net/comments/the_true_story_of_the_unauthorized_daredevil_documentation_of_the_horizons_/
#10yrsago Predictive policing predicts police harassment, not crime https://web.archive.org/web/20160821093834/https://link.springer.com/article/10.1007/s11292-016-9272-0
#10yrsago UC Davis Chancellor spent $400K+ to scrub her online reputation after pepper-spray incident https://www.sacbee.com/news/local/article94733812.html
#10yrsago Reputation systems work because people are mostly good https://timharford.com/2016/08/the-meaning-of-trust-in-the-age-of-airbnb/
#10yrsago The guy who started Serbia’s ethnic cleansing led a pro-Trump rally in Belgrade https://web.archive.org/web/20160817022133/https://theintercept.com/2016/08/16/serb-inspired-ethnic-cleansing-bosnia-leads-vote-trump-rally-belgrade/
#10yrsago Europe’s banks want to store billions in cash to fight back against negative interest https://web.archive.org/web/20160817152157/https://www.cnbc.com/2016/08/16/banks-look-for-cheap-way-to-store-cash-piles-as-rates-go-negative.html
#10yrsago Kill Rock Stars president explains why the radio plays the same songs over and over https://www.youtube.com/watch?v=ThrXkYwTBP8
#10yrsago Snowden explains the Shadow Brokers/Equation Group/NSA hack https://www.techdirt.com/2016/08/16/ed-snowden-explains-why-hackers-published-nsas-hacking-tools/
#10yrsago Hackers claim to have stolen NSA cyberweapons, auctioning them to highest bidder https://web.archive.org/web/20160816035711/https://motherboard.vice.com/read/hackers-hack-nsa-linked-equation-group
#10yrsago What life is like when you really understand advanced mathematics https://www.quora.com/What-is-it-like-to-understand-advanced-mathematics-Does-it-feel-analogous-to-having-mastery-of-another-language-like-in-programming-or-linguistics
#10yrsago Parents who can’t pay the bill for kids’ incarceration can still go bankrupt, a US court rules https://archive.thinkprogress.org/everything-wrong-with-how-our-justice-system-treats-poor-people-in-one-awful-case-bfd91a6fa114/
#10yrsago UK Intellectual Property Office grants trademark on “should’ve” https://www.bbc.co.uk/news/business-37092366
#10yrsago The Greatest of Marlys! is the Lynda Barry book we’ve been waiting for https://memex.craphound.com/2016/08/16/the-greatest-of-marlys-is-the-lynda-barry-book-weve-been-waiting-for/
#5yrsago Housing, money laundry, speculation and precarity https://pluralistic.net/2021/08/16/die-miete-ist-zu-hoch/#assets-v-human-rights
#5yrsago Big Oil caught lying about methane https://pluralistic.net/2021/08/17/king-bullet/#methanescan
#5yrsago Sandman Slim's final adventure https://pluralistic.net/2021/08/17/king-bullet/#sticking-the-dismount
#5yrsago The Sacklers threaten us all with a good time https://pluralistic.net/2021/08/18/lets-make-a-deal/#art-of-the-deal
#1yrago Zuckermuskian solipsism https://pluralistic.net/2025/08/18/seeing-like-a-billionaire/#npcs
#1yrago LLMs are slot-machines https://pluralistic.net/2025/08/16/jackpot/#salience-bias
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
Manchester: Take Back Big Tech with Jovan Owusu-Nepaul (House of Books and Friends), Sep 11
https://ma.to/event/cory-doctorow-house-of-books-and-friends-11-sep-2026
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Victoria: Munro's Books (Oct 20)
https://www.munrobooks.com/events/6113620261020
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Who The Machine Serves (EFF)
https://archive.org/details/effecting-change-who-the-machine-serves
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
AI, automation and enshittification (Telecoms.com)
https://www.telecoms.com/ai/the-telecoms-com-podcast-ai-automation-and-enshittification
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Funny thing about competition: there's both a pro-market and an anti-market case for a competitive system.
https://pluralistic.net/2026/08/13/one-chokable-throat/#too-clever-by-half
If your theory is that markets deliver prosperity by spurring businesses to provide the superior products and services at lower prices needed to attract and retain workers and customers, then competition is a must-have. Without competitors, companies are "too big to care":
https://pluralistic.net/2024/04/04/teach-me-how-to-shruggie/#kagi
Meanwhile, if you think that the pressure of greed will always drive companies to cheat, and want companies held in check by democratically accountable lawmakers and enforcers, then you also want competition, because otherwise, disorganized sectors of hundreds of small businesses collapse into oligarchic cartels. Members of these cartels cease to compete directly with one another and instead collude to rip off workers and customers, leaving them aslosh in ready cash they can mobilize to capture regulators, securing an enshittogenic policy environment that reflects the easily arrived-at consensus that's only possible when you boil a sector down to a small handful of firms, each of them "too big to jail":
https://pluralistic.net/2022/06/05/regulatory-capture/
In other words: if your ideal is a world of high-quality products and services, produced by workers laboring under fair conditions, delivered to consumers at a fair price, then you want competition. Competition scares some people into running their businesses ethically; and competition ensures than an unethical operator can be held to account by government agencies charged with protecting workers and consumers.
Once you understand the role of competition as a counter-oligarchic check on corporate power, the rise of Big Tech and its authoritarian turn becomes much easier to understand.
Tech is uniquely hospitable to competition thanks to the intrinsic properties of digital computers. Formally, computers are "Turing-complete, universal von Neumann machines," which is to say that every computer can run every valid program. This means that any enshittificatory gambit assayed by a tech company – say, locking generic ink out of your printer; or blocking third party app stores for your phone or console; or sticking a dozen extra ads before every Youtube video – is technically doomed.
Every time a tech boss introduces a 10' pile of shit to a digital product or service you rely upon, they induce rival technologists to create 11' ladders made of code that they can costlessly, instantaneously distribute to every one of the enshittifier's customers and suppliers:
https://www.eff.org/deeplinks/2019/07/adblocking-how-about-nah
This explains the dynamism of early tech, which saw companies rising quickly to conquer their markets, only to yield to the temptation to extract more from customers and/or suppliers while underinvesting in improvements to their products and services. When this happened, new digital companies sprang into being, reverse-engineering the incumbents' products and launching "complementary goods" – plug-ins and mods – that fixed the defects in dominant products, usurping the market leader's place in the workflows and pocketbooks of its customers and suppliers:
https://www.eff.org/deeplinks/2019/10/adversarial-interoperability
For many years, this "adversarial interoperability" worked its magic on the burgeoning tech sector, creating a state of constant ferment where people who wanted to improve and then supplant the state-of-the-art were able to cheaply enter and capture the market, only to be taken down by the next generation of disenshittifiers when they, too, inevitably yielded to the temptation to replace innovation with extraction. Every pirate wants to be an admiral – but every admiral must then confront the pirates who rush in to fill the vacuum they create when they switch sides.
But that system of beneficial disruption was itself disrupted – not by technology, but by policy. In 1998, Bill Clinton signed the Digital Millennium Copyright Act (DMCA). Section 1201 of the DMCA makes it a felony to practice adversarial interoperability, establishing penalties of $500k and five years in prison for people who reverse engineer and modify products:
https://pluralistic.net/2026/01/14/sole-and-despotic/#world-turned-upside-down
DMCA 1201 created a one-way ratchet that progressively narrowed the possibilities for tech competition. As more and more US companies re-engineered their products so that modifying them would give rise to DMCA 1201 liability, American startups gave up on disrupting Big Tech, re-orienting towards "acqui-hires," when a startup's highest purpose is to be absorbed by a giant, sclerotic incumbent that mothballs its products and assigns its engineers to work on incremental maintenance (or worse, enshittification) for its dominant offerings.
Big Tech's pirates turned admirals, free to "disrupt" the weak and poor, while enjoying the legal entitlement to destroy anyone who dared to disrupt them. They embodied Frank Wilhoit's definition of conservativism: a class that the law that "protects but does not bind" alongside a class that the law "binds but does not protect":
https://pluralistic.net/2026/07/08/wilhoitian/#human-rights-v-property-rights
It was fine for them to "move fast and break (our) things," but forbidden for us to "move fast and break kings." Disruption for thee, never for me.
Nor was this a merely American sickness. Having neutered domestic competitors that might threaten its tech incumbents, the US government set out to prevent other countries from challenging its world-girdling tech empires. For the past 25 years, the US Trade Representative has prioritized getting anticircumvention laws on the books of all of America's trading partners as a condition of free trade with the US, with the result that today, virtually every country in the world has a law that makes it illegal to disrupt American tech giants:
https://pluralistic.net/2026/05/05/three-is-a-magic-number/#coalitions
Anti-circumvention law is so obviously, manifestly an invitation to enshittify that when governments enacted these laws, they felt the need to include some kind of "safety valve" they could point to when critics raised anti-circumvention's potential for abuse. The world's would-be enshittifiers figured out a devious method to insert clauses into anti-circumvention that looked like anti-abuse measures, but which were, in practice, useless ornaments.
Many anti-circumvention laws – including DMCA 1201 – have a process for creating "exemptions" to the ban on reverse-engineering and modifying a device. The way these exemptions processes are written, they seem to say that if a company uses anti-circumvention law to block legitimate activity – say, if John Deere uses the law to stop you from fixing your own tractor – then you can go to some kind of governing body (in the US, it's the Copyright Office) and petition for an exemption to anti-circumvention. If that exemption is approved, then making that modification becomes legal.
Before I carry on, let me say here that even if that's how the system worked, it would still be grossly offensive. If you buy a device – a car, a tractor, a printer, a console, a phone – it is your property and you should not have to hire a lawyer to ask a government agency to create a legal exemption that lets you do otherwise legal things with it. You should not need to petition the government for the right to buy generic ink, use a third-party app store or take your car to an independent mechanic.
But this isn't how the system works. It's a scam. Anti-circumvention exemptions are a cheap trick. They only sound useful. A reasonable person who hears that the US Copyright Office has made it legal to use a third-party app store with your iPhone would assume that this means that if someone launches their own app store, they can give you the tools needed to unlock your iPhone and activate their store.
That's not how the DMCA exemptions process works. Under the statute, the US Copyright Office is only empowered to create "use exemptions," which allow you, the owner of the iPhone, to make use of a tool that unlocks your phone and installs the third-party app store. The Copyright Office does not have the power to create a tools exemption that would allow someone to make that unlocking tool and sell or give it to you. Making that tool remains a felony with a five-year prison sentence attached to it.
What this means is that if you want to use your own property in a way that was legal before DMCA 1201, that has been made legal again because you hired a lawyer who successfully petitioned the US Copyright Office to grant an exemption, you can only do so if you, personally reverse engineer your device to effect the permitted modifications to it.
So: if the US Copyright Office legalizes alternative iPhone app stores, the only way to exercise this exemption is for every iPhone owner in the country to get a computer science degree, secure the use of a clean-room, decap the "secure enclave" on a spare iPhone's CPU, extract its cryptographic keys, and integrate them in a new version of iOS that they personally write and install on their phone. No iPhone owner is allowed to discuss how to do this with any other iPhone owner engaged in the same project, on penalty of a five year prison sentence.
Obviously, this is ridiculous, and iPhones are just the tip of the iceberg. It's also true if you want to enable independent repair of powered wheelchairs, whose manufacture is controlled by a duopoly of private-equity backed companies that have all but abandoned spending on repair, leaving wheelchair users stuck in bed for months while they await service:
https://www.eff.org/deeplinks/2022/06/when-drm-comes-your-wheelchair
This absurd situation is the same if you're blind and want to make use of an exemption that lets you reverse-engineer ebook formats so that you can run your ebooks through a Braille printer, screen reader or other assistive device. Under the exemptions rules for the world's anti-circumvention laws, every blind person is expected to personally reverse engineer the access control systems built into Adobe and Amazon's ebook formats, write an exploit that lets them extract the text of these restricted ebooks and then repackage that text in a new, open format:
https://pluralistic.net/2026/03/16/whittle-a-webserver/#mere-ornaments
This "use exemption"/"tools exemption" split is a near-perfect way of tricking people into thinking that these laws are more reasonable than they appear. When Canada passed its landmark right-to-repair and interoperability laws in 2024, many celebrated – missing the fact that under Canada's anti-circumvention law (Bill C-11, the Copyright Modernization Act of 2012), it remains illegal to undertake the reverse-engineering needed to exercise the rights these new laws (seemed to) enshrine:
https://pluralistic.net/2026/01/29/post-american-canada/#ottawa
For a quarter-century, I've made it my life's work to explain how bad and dangerous this system is, and, thankfully, I've started to make a little headway over the past few years. My core audience contains a lot of hackers who are rightly affronted at the existence of a body of law that criminalizes the kinds of exploration and modification that they've devoted their lives to.
Being hackers, they ponder this situation and start to think about how they can hack the law to escape it. Just lately, I've heard from a lot of people who think they can solve this problem by asking a chatbot to reverse-engineer and modify the firmware on their tractors, wheelchairs, ebooks, iPhones, what-have-you. You can't put a chatbot in prison for violating anti-circumvention law, right?
I regret to inform you that if you did this in a way that rose to the attention of a big corporate bully, they wouldn't blame your chatbot for writing the exploit: they'd blame you for prompting the chatbot to create this new tool.
Just yesterday, I heard from a reader who had a clever idea: what if you gave your unmodified iPhone to a hacker who knew how to install a third-party app store on it, and they modified that phone, and then sold it back to you for $10? The hacker would be making a use exemption, not a tools exemption.
This, too, will not produce the outcome we're seeking. Even if Apple can't convince a judge that selling you a modified iPhone is "trafficking" in a circumvention device (a very big "if"), this wheeze misses the wider point about how adversarial interoperability was able to disenshittify tech for the years when tech companies weren't just dishing out disruption, but also being disrupted themselves.
The interoperability-driven dynamism that disciplined or displaced tech companies that abused their market power was a mass phenomenon. The printer cartel doesn't need to be able to charge everyone $10,000/gallon for ink. If a few people at the margins figure out how to jailbreak their printers, that doesn't stop the grift. Even better if the people who do use generic ink have to depend on anonymous, shadowy businesses that don't have customer service departments you can call when your printer gets an update that breaks ink compatibility, or an address you can send a process-server to if you're stuck with thousands of dollars' worth of useless ink cartridges after one of those updates.
To make generic ink a viable check against the abuses of HP and its colored water mafia, you need a counter-industry. You need salespeople making calls on large enterprises who buy their ink by the ocean, offering them a better deal and a guarantee of uninterrupted service. To make good on that guarantee, you need an army of hackers who reverse-engineer every software update HP pushes out in a matter of hours, and you need another army of customer service reps who help people who can't figure out how to install that update.
As economists would say, you need "capital formation." You need the ability to raise or borrow money, a mailing address, an ad campaign, booths at conferences and free samples in the mail. You need to be able to show potential customers that you are insured in the event that you brick their devices, so switching to your product doesn't endanger their capital investments. You need to have a business whose doors can be beaten down by regulators in the event that you use your after-market mods as a tool to steal data or money from your customers.
To understand how this worked, cast your mind back to the Office Suite Wars of the early 2000s. Back then, Microsoft ruled the desktop world, controlling more that 95% of the PC OSes, a share so large and so ruthlessly acquired and maintained that they were convicted of violating anti-trust laws.
Microsoft used illegal tying and predatory pricing to push every one of those PC owners into using Microsoft Office, which meant that even if you used a Mac, 19 times out of 20, the people you needed to collaborate with on memos, spreadsheets and slide-decks were using MS Office.
Microsoft made a version of Office for the Mac, but it was the single most curséd piece of packaged software ever offered to the market. Merely waving the Mac Office floppy around a workplace would cause files to spontaneously go corrupt on random PCs in the vicinity.
For Mac users, this meant that 95% of the time, they could not reliably collaborate with other computer users. For people like me – then a freelance CIO-for-hire who was helping small businesses connect their computers to each other and the internet – it meant that increasingly, we made CEOs swap their Powerbooks for Thinkpads and designers swap their PowerPCs for Dells with beefy graphics cards, moving the whole business to PC/Windows.
Apple solved this problem by reverse-engineering MS Office and producing the iWork Suite: Pages, Numbers and Keynote, which could perfectly read and write Microsoft's Word, Excel and Powerpoint files. That adversarial interoperability saved the company, but the gambit wasn't one-and-done.
Microsoft spent the next several years maliciously introducing changes to the Office file formats that broke compatibility with iWork, which Apple countered by paying an army of coders to swiftly analyze these new formats and update iWork to maintain compatibility with them:
I think Apple was fated to win this expensive cat-and-mouse game, if only they could hang in there long enough. For every Mac in the field, Microsoft was supporting 19 PCs, and these computers ran a fragmented mosaic of Windows and Office versions. Every time Microsoft broke compatibility with Office to mess up one Mac user, they also messed up 19 PC users, all of whom had to be patched and updated to maintain compatibility. This gave Apple a powerful advantage that mounted with every turn of the game, so all they had to do was hang in there until the asymmetrical costs overwhelmed Microsoft.
Which is what happened. Eventually, Microsoft sued for peace and agreed to standardize the office file-formats at the International Standards Organization, ushering in an era of unprecedented compatibility. This ISO standardization is why you can now paste styled text from the Word application into a browser-based Google Doc or an application-based LibreOffice window. It's also a game Microsoft continues to cheat at, with a string of dirty tricks meant to leverage its dominance to shut out competitors altogether:
https://blog.documentfoundation.org/blog/2026/07/17/microsofts-main-tool-for-lock-in/
The rise (and impending fall) of a truly open format that lets every computer user collaborate on any document is an object lesson in the combined role that adversarial interoperability and capital formation play in disenshittifying technology. For Microsoft, a "competitor" isn't one hacker who can open a Word file in a program of their own devising, nor is a "competitor" the small number of users that single competitor can support.
Microsoft is an incorrigible, bullying cheat with a sick and rotten corporate culture: to stop the kind of ruthless princeling who rises to a position of power in a company like Microsoft from turning predatory requires severe, obvious penalties that follow directly from any extractive gambit.
To muster that kind of competition requires the kind of capital formation you only get from true legalization, not the anemic sham offered by anti-circumvention's "exemptions." Even where the competition is spread out across many shifting small businesses and individuals, the system of competition requires a stable backstop that produces the tools these small firms rely on.
In 2014, Ofcom, the UK's telecoms regulator, affirmed that Britons had the right to unlock their phones, even if their carrier had sold them a phone that was locked to its network. Overnight, every small shop acquired a phone-unlocking side-hustle. One morning as I walked from my flat to the tube, I passed three unlockers: one at a newsagent's, where they would take your phone and return it unlocked within a day; one at my dry-cleaner's, where a guy with a folding card table would unlock your phone while you waited; and another folding table guy right by the tube entrance who'd also work while you waited, and who charged £5 less than the guy at the dry-cleaner's.
None of these people were electrical engineers or software developers or hackers. They just followed recipes that were provided by one of a few well-capitalized firms that sold them a subscription to jailbreaking tools that were kept up to date for every make and model of every phone.
One frequent excuse for the ban on repair tools for cars or wheelchairs or tractors is that these devices are now so computerized that they require specialized knowledge if they are to be safely serviced. Even if that's true, that's exactly what a legal toolchain provides.
The guy who fixed my solar panels wasn't a software engineer, he was an electrician who had the customer-service phone number for the company that made my solar inverter. If that company had a viable competitor who could offer their own firmware for my solar installation and was hungry for my business, maybe that technician would have gotten through in three minutes rather than three hours.
And if that alternative firmware was defective, then I could join a class action suit and get made whole – something that is nearly impossible to imagine happening with solar OEMs, who face so little competition that they all put binding arbitration clauses in their terms of service that take away your right to sue, no matter whether they cheat you or burn your house down:
https://pluralistic.net/2026/05/06/champerty-loves-company/#circle-of-life
That's the amazing thing about digital tools. Through software, experts are able to package up their expertise into self-executing code, which can costlessly, instantaneously be distributed to everyone in the world who needs it. But paying those experts isn't cheap, and neither is supporting their tools.
I love William Gibson's maxim that "the street finds its own use for things," but if you can't neutralize a large, dangerous monopolist with individual tinkering – the best you can hope for is some measure of individual relief..
It's true that in these adversarial interoperability fights, the upstarts enjoy a tremendous advantage, but that advantage isn't infinite. For the guerrillas to outlast the empire, they have to be able to wage a long, persistent fight.
To marshal the resources needed to sustain that fight and to maintain the logistics demanded by its supply lines requires the good guys to be allowed to fight in the open, without the looming threat of criminal prosecution, a threat that forecloses on capitalization and mass adoption.
Enshittification isn't downstream of cruelty, it's downstream of greed. The point of enshittification is to exploit the control a firm can exercise over the customers, suppliers and workers it holds captive in order to extract more from them. The titanic profits this exploitation delivers are a powerful lure for would-be disenshittifiers and investors who would fund their liberatory revolution.
Don't get me wrong, I love my hackers and I sit in awe of the awesome leverage of writing code that can be costlessly, instantaneously distributed to everyone who needs it. But so long as governments and the law are on the side of extraction and enshittification, the disenshittificatory insurgency will be starved of resources, condemned to remain marginal and inadequate.
Reverse centaurs: EU approach to AI risks dystopia for human workers https://euobserver.com/231973/reverse-centaurs-eu-approach-to-ai-risks-dystopia-for-human-workers/?cst=b33df4396260b48a181be764dc7978cb6c184b6818f8113ee298c52af8038cda
Executable Emoji https://martypc.blogspot.com/2026/08/executable-emoji.html
A Rant About “Technology” https://www.ursulakleguin.com/a-rant-about-technology
Hardin’s imagined tragedy is pig shit: A call for planning to recenter the commons https://sci.bban.top/pdf/10.1177/1473095218820460.pdf
#25yrsago Berkeley Breathed: the Onion interview https://web.archive.org/web/20011201062719/http://www.theonionavclub.com/avclub3728/avfeature_3728.html
#25yrsago Chinese going mobile crazy http://news.bbc.co.uk/1/hi/world/asia-pacific/1492584.stm
#25yrsago Free wifi in NYC https://web.archive.org/web/20011024070700/http://www.villagevoice.com/issues/0133/meyers.php
#20yrsago RIAA’s “abundance of sensitivity” ends harassment of grieving family https://memex.craphound.com/2006/08/14/london-copyfighters-speak-at-speakers-corner-on-aug-27/
#20yrsago London Copyfighters: Speak at Speaker’s Corner on Aug 27! https://memex.craphound.com/2006/08/14/london-copyfighters-speak-at-speakers-corner-on-aug-27/
#20yrsago TSA wins the war on lipstick https://memex.craphound.com/2006/08/14/tsa-wins-the-war-on-lipstick/
#15yrsago RIP Paul Meier, father of the randomized trial https://www.nytimes.com/2011/08/13/health/13meier.html?_r=1
#15yrsago Long Beach Police Chief: we detain photographers, and I don’t have any guidelines for that policy, photography is classed with attempts to acquire weaponized smallpox https://web.archive.org/web/20110927230257/http://www.lbpost.com/life/greggory/12188
#15yrsago David Cameron’s net-censorship proposal earns kudos from Chinese state media https://web.archive.org/web/20110815220203/https://www.globaltimes.cn/NEWS/tabid/99/articleType/ArticleView/articleId/670718/Riots-lead-to-rethink-of-Internet-freedom.aspx
#15yrsago Empirical manners: towards a science of harmonious norms https://www.antipope.org/charlie/blog-static/2011/08/rewilding-etiquette.html
#15yrsago Tiki Room resurgent https://passport2dreams.blogspot.com/2011/08/every-cloud-has-silver-lining.html
#10yrsago After New Zealand spooks misidentified pro-democracy activist, NSA spied on him for them https://web.archive.org/web/20160815040057/https://theintercept.com/2016/08/14/nsa-gcsb-prism-surveillance-fullman-fiji/
#10yrsago Even the woo industry thinks Gwyneth Paltrow’s “smoothie dust” ads are too much https://web.archive.org/web/20160811225548/https://consumerist.com/2016/08/09/ad-and-supplement-self-regulation-groups-have-issues-with-gwyneth-paltrows-smoothie-dusts/
#10yrsago It’s pretty easy to hack traffic lights https://www.usenix.org/system/files/conference/woot14/woot14-ghena.pdf
#10yrsago Private prison contractor’s $1B no-bid deal to run immigration jails guarantees 100% occupancy payouts https://web.archive.org/web/20160815022103/https://www.washingtonpost.com/business/economy/inside-the-administrations-1-billion-deal-to-detain-central-american-asylum-seekers/2016/08/14/e47f1960-5819-11e6-9aee-8075993d73a2_story.html
#10yrsago Court of Appeal reverses Labour disenfranchisement ruling, but Corbyn still likely to win https://web.archive.org/web/20160813134816/http://www.newstatesman.com/politics/staggers/2016/08/high-courts-judgement-wont-stop-jeremy-corbyn-winning
#10yrsago John Oliver on subprime auto-lending and its killswitches https://web.archive.org/web/20160816154135/https://consumerist.com/2016/08/15/john-oliver-keegan-michael-key-explain-why-subprime-car-loans-are-so-awful/
#10yrsago Worst of McMansions: architectural criticism of inequality’s most tangible evidence https://web.archive.org/web/20160814031109/http://mcmansionhell.tumblr.com/
#5yrsago Provocateur copyrights a Magic: The Gathering Deck https://pluralistic.net/2021/08/14/angels-and-demons/#owning-culture
#5yrsago Disneyland at a stroll https://pluralistic.net/2021/08/15/disneyland-at-a-stroll-part-vi/
#1yrago Bluesky creates the world's weirdest, hardest-to-understand binding arbitration clause https://pluralistic.net/2025/08/15/dogs-breakfast/#by-clicking-this-you-agree-on-behalf-of-your-employer-to-release-me-from-all-obligations-and-waivers-arising-from-any-and-all-NON-NEGOTIATED-agreements
#1yrago "Privacy preserving age verification" is bullshit https://pluralistic.net/2025/08/14/bellovin/#wont-someone-think-of-the-cryptographers
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
Speculative Fiction for Social Change II (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-two-cory-doctorow-on-speculative-fiction-for-social-change/937e8800-9404-45a6-b5e3-90ebee2cfaea
Speculative Fiction for Social Change I (Cool People Who Did Cool Stuff)
https://pocketcasts.com/podcast/cool-people-who-did-cool-stuff/08cbb840-a6ae-013a-d8aa-0acc26574db2/part-one-cory-doctorow-on-speculative-fiction-for-social-change/15ad467c-0832-44c9-91ea-59defd783dba
AI, automation and enshittification (Telecoms.com)
https://www.telecoms.com/ai/the-telecoms-com-podcast-ai-automation-and-enshittification
The AI Enshittification Bubble (Hidden Forces)
https://hiddenforces.io/podcasts/the-ai-enshittification-bubble-cory-doctorow/
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

One of my favorite rhetorical and analytical moves is joining things together (showing that two different, seemingly unrelated ideas are aspects of the same phenomenon) and taking them apart (resolving a paradox by demonstrating that what appears to be one, contradictory thing is actually two different things that have been lumped together).
"Taking things apart" is a very useful framework for understanding AI. How do we resolve the (seeming) paradox that some skilled workers report wonderful results from their work with AI, while others are full of dire warnings about the lurking defects in their AI-assisted outputs? Simple: the first group are "centaurs" (humans who are assisted by machines) and the second are "reverse centaurs" (humans who have been pressed into service as peripherals for machines):
https://pluralistic.net/2025/12/05/pop-that-bubble/#u-washington
What are we to make of the people who've been fired by bosses who replaced them with AI, in light of the fact that AI is demonstrably not able to do their (former) jobs? Again, it's simple if you separate out two distinct phenomena: "AI can do your job" is the first. The second is: "Your boss is a credulous dolt who is infinitely horny for replacing lippy workers with pliable machines, which made him an easy mark for an AI salesman who convinced him to fire you and replace you with an AI that can't do your job":
https://pluralistic.net/2025/03/18/asbestos-in-the-walls/#government-by-spicy-autocomplete
This is also a useful move for understanding the AI investment bubble. It's not just billionaires who don't think other people are as real as they are and consequently their jobs can be done by chatbots. It's also billionaires who believe that bosses can be sold AI and don't care if the AI is defective, because that's your boss's problem after he buys the AI and fires you. They don't have to believe in AI in order to think it's a good investment: like an investor betting that Joe Rogan can sell millions of dollars' worth of peptides to desperate young men, they are assessing the sales potential, not the merits of the thing for sale:
https://pluralistic.net/2026/08/03/andor/#either
As useful as "taking things apart" is, "putting things together" is also a very important technique for assessing, critiquing and improving AI. In a stellar essay entitled "Temperature Zero for Culture: Why Everything Is Starting to Look the Same" by the data scientist Lauren Leek, we get a top-notch example of "putting things together":
https://laurenleek.substack.com/p/temperature-zero-for-culture-why
Leek's essay is one of those fabulous, wide-ranging, cross-disciplinary pieces, touching on urban design, music trends, synthetic LLM crowds, Netflix recommendation algorithms, and several other subjects, all seeking to resolve a(nother) (seeming) paradox: how is it that we have so much potential variety, but everything is so manifestly the same?
The answer is complicated and nuanced, but Leek's foundational point is that in a data-driven society, "predictions" are self-fulfilling prophecies. As Leek puts it: "Once prediction shapes the choices in front of us, we lose the ability to tell the difference between what people wanted and what the system made easy to want."
This is a pervasive issue across many domains. Leek says that economists call it "performativity," while machine learning researchers call it "model collapse" and urbanists call it "placelessness."
"Performativity" describes how, once a market has been modeled by economists, that model becomes the foundation for economic policy, which pushes the market to conform to the model:
https://press.princeton.edu/books/paperback/9780691138497/do-economists-make-markets
"Model collapse" describes how machine learning models that are trained on their own predictions become incredibly bland, with all variety disappearing from the system's predictions:
https://pluralistic.net/2024/03/14/inhuman-centipede/#enshittibottification
This is hugely consequential: it's why bias proliferates through predictive policing algorithms: train a model with data from racist stop-and-frisks and it will predict that all the weapons and drugs in a city are to be found in Black and brown peoples' pockets. Turn those predictions into recommendations telling cops where to go look for weapons and drugs and they will double down on racist stops, producing even more biased training data, which turns into still more bias in the predictions:
https://hrdag.org/2016/10/10/predictive-policing-reinforces-police-bias/
"Placelessness" is the urbanist's name for "when everywhere optimises toward the same template." I think of it as Flinstones Syndrome, where the same background is looped behind Fred and Barney as they drive through Bedrock. In New York City, it's Citibank-bodega-Chipotle-Walgreens; in the Chicago suburbs, it's the strip malls with a Chili's, a gas station, and a big box store.
Leek proposes that these are all expressions of the same underlying phenomenon, a failure mode of data science that takes a world of "granular personal data" and arrives at a world where "personalisation produc[es] more sameness."
To these excellent examples, I'd add another one, from the world of monetary policy: Goodhart's Law, which holds that "When a measure becomes a target, it ceases to be a good measure":
https://en.wikipedia.org/wiki/Goodhart%27s_law
Goodhart's Law captures a wide variety of phenomena. When Google first deployed Pagerank, they showed that by counting the inbound links to all the pages on the web, you could extract a signal about which pages were most important (because there was no reason to link to a page unless you found it noteworthy).
But once Pagerank became the dominant means by which web users found pages, counting links stopped being useful: first, because people used Pagerank to find the best pages and link to them, making it impossible for new pages to get the inbound links needed to supersede incumbent pages; and second, because it's easy for fraudsters to create inbound links for low-quality pages in bulk, once there's a reason to do so.
Counting inbound links was a world-beating retrospective way of predicting which page would best match a searcher's query, but once it shaped the world it sought to analyze, it ceased to be a good prospective way to predict which page would best match your queries.
Leek is a brilliant data scientist and an even better science communicator, with a knack for crisp, readily understood explanations. How can a world of granular, highly varied data turn into a world of homogeneous choices? Simple: start with a set of items ("cuisines, genres, shop types") and a standard algorithm for sorting them. Let users choose from those recommendations. The mode (average) of those choices "gets shown more, so it gets picked more, so the model grows more confident the mode is what people want, and the tails starve." Run this for a few rounds and the evenly distributed catalog of choices "collapses onto one dominant option."
This is intrinsic in the choices we make in designing recommendation algorithms, tilting them towards the likelihood of a successful recommendation. A recommender that wants to succeed every time will make the safest possible recommendations, "so an algorithm that is uncertain about you, and it is always at least a little uncertain, hedges toward the average."
Then she busts out a beautiful, perfect little statistics aphorism: "Personalisation under a standard loss function is regression to the collective mean with extra steps." That is to say, "regression to the mean" (the tendency of varied things to become more standardized) cannot be avoided with the standard personalization algorithm. That algorithm is going to play it safe, showing you things that are broadly palatable, and because your choices are constrained to the average, you will choose average things.
This is how recommendation systems – and other analytical tools that produce predictions that are then turned into action – force so many diverse phenomena (streets, markets, media recommendations) into sameness. The fact that these recommenders are self-fulfilling prophecies means that "they don't have to be right," only "listened to."
This explains the sameness of so many of London's high streets. Leek examines 640 shopping streets, characterizing 18,000 food places spread out across them, flagging all the chain restaurants. Her analysis shows that any two London streets will, on average, share about half of their "food profile."
Obviously, this is most pronounced on streets with chain outlets, and it doesn't take that many chain outlets before a street's sameness shoots up: "A relatively small number of repeated names is enough to make otherwise different streets resemble one another more." So why do streets with chains resemble one another so much? Because the chains use an algorithm (weighting footfall, proximity to train stations, demographics, and competitors) to decide where to put their restaurants. If a street with a Gail's Bakery on it feels like every other street with a Gail's Bakery, that's because Gail's only puts its restaurants in places that have highly similar characteristics, measured to a high degree of accuracy and controlled by a narrow set of tolerances.
In other words, every street that feels like it should have a Gail's will eventually get a Gail's, whereupon that street will feel even more like all the other streets that have a Gail's, because it will share one more common factor with those other streets (a Gail's).
Leek points here to her earlier work on pub closures in the UK. The UK has experienced an epidemic of pub closures, with thousands of pubs disappearing since 2016:
https://laurenleek.substack.com/p/britain-lost-14000-third-places-they
Her research found that the biggest predictor of a pub surviving was its similarity to the median pub; which is to say that the more distinctive a pub was, the more "character" it had, the more likely it was to close. Pubs that are different from the average pub are harder to categorize, which means they're harder for a bank manager to assess for creditworthiness or for a landlord to justify extending a long-term lease to. The algorithms used to allocate capital and real estate are also recommenders, and they also drive variety out of the system.
This same phenomenon acts on culture. In an age of music recommendation algorithms, hit songs are changing; today's songs use a smaller vocabulary of unique words and repeat those words more often:
Vocabulary richness, distinct words relative to length, has fallen by more than a quarter since the early 1960s, while the share of repeated lines has climbed by nearly a third. The modern hit says less and says it more often, because the hook that works gets repeated.
But that's not the whole story! While each song resembles itself more ("saying less more often"), within that constraint, there's far more variety today than before: a given song's (constrained) vocabulary has grown more distinct when compared to all the other songs' vocabularies. Songs repeat the words they use, but the words repeated in songs are getting more different.
For Leek, this is the key to understanding the whole phenomenon and (more importantly) doing something about it. Music recommendation systems optimized for a singable hook, but did not optimize on any of the other variables in songs, so those dimensions acquired a broader range, even as the optmized variable got flatter and narrower.
This means that the tendency of recommenders to "flatten the world" isn't a single blunt outcome: it depends on which dimension we choose to flatten through recommendation, and who chooses to flatten that dimension.
A media recommender optimizes for consumption, showing you a tractable set of things it believes you'll watch, read or listen to. When you choose from among this limited set, the recommender takes note of that fact and shows you more of the same, pushing everything to a greige median. All the movies, books and songs you might have liked that were omitted from that initial set are excluded from being recommended in the future. The features of that media that you might have appreciated "decay out of consideration." They are never tested for desirability. The model collapses.
How badly does it collapse? Leek cites Movietweetings' data on which movies people watch: out of a million public movie ratings, half relate to the top 2% of movies in the set. There's 38,000 films in the set, but just 380 titles account for 40% of the ratings. Leek argues (persuasively) that this isn't because recommenders are good at "knowing your taste" – rather, they are good at "narrowing the menu."
Leek relates this to her work on creating LLM "personas" – synthetic populations meant to mimic the tastes and proclivities of real groups of people, that you can interrogate "before you spend money asking actual humans." While this would be useful for many applications, "it fails in exactly the way this whole essay is about."
Leek went to enormous lengths to reproduce the traits that make people interesting to study in aggregate, painstakingly replicating the ways that social connections, psychological outlook and demographic factors predict people's beliefs. The result was a set of LLM personas with "elaborate stories" about how they differed from one another, but whose survey responses about planned actions were homogeneous in a way that real populations are not.
This, Leek writes, is the same force that homogenizes other data-driven predictors. Because she'd ordered her LLM to reproduce the statistically validated relationships between different factors that predict a person's beliefs, each synthetic persona was a homogenized average. It's like the paradox of "The Average Man," where military uniforms sized to the average of all service personnel fit no one, because no one is average:
https://archive.org/details/DTIC_AD0010203
The thing is (as Leek points out) the idea that synthetic personas are a good way to understand the preferences of a real population is not a harmless delusion: it's a product that's being actively sold to governments, campaigning politicians and marketers. It's a self-fulfilling prophecy that drives governance, political campaigns and product design to the same homogeneous median that is making every shopping street in London feel the same.
This matters. As Leek writes, ecologists have long understood the importance of variety for systemic resilience: they call it "the insurance value of biodiversity." A diverse system has reservoirs of species and variation that may not be optimized for how things stand now, but that can move into niches created when things change in ways that lay waste to the previously dominant organisms. As anyone whose favorite banana went extinct can tell you, homogeneity works well, but diversity fails well:
https://en.wikipedia.org/wiki/Gros_Michel
The brittleness of algorithm-induced homogeneity is compounded by the fact that recommenders obscure the true preferences of people. If you watch two Scandinavian crime dramas after Netflix recommends them to you, it will keep showing you more Scandy crime for the next decade – even if there's another kind of programming that you'd vastly prefer (if only you knew about it). This means that decision-makers who choose which shows will get made in the future will keep on funding their safe Danish detectives, to the exclusion of whatever might emerge from the same weird attractor that produced the K-Pop Demon Hunter fortune.
Transpose this failure mode onto states, bank managers and landlords, and we see whole ranges of policies, businesses and activities that never come into existence, despite the popularity, prosperity and joy they might bring us.
But Leek doesn't end with this worrisome note. Instead, she identifies this whole thing – model collapse, placelessness, performativity, even Goodhart's Law – as an expression of one of the best-understood tradeoffs in computer science: "exploration vs exploitation":
Any system learning from feedback has to divide its effort between exploiting what already scores well and exploring options it hasn’t tried, in case they’re better.
Computer scientists have long understood that focusing on exploitation to the exclusion of exploration is a trap that locks you into "the first decent option" so you can never discover the best one.
Which means that this algorithmic homogeneity has a well-understood corrective: "forcing exploration back in." The problem is that markets hate this kind of exploration. A company that lives and dies by how many clicks it gets is never going to sacrifice 20% of its traffic by showing its users weird, untested options that score worse than the median because these weird things have never had a chance to prove that they are desirable.
This is a classic market failure, and, as Leek points out, there are regulatory responses in the UK (the Digital Markets, Competition and Consumers Act) and the EU (the Digital Services Act), both of which require the largest platforms to open up their recommendation systems, but so far, regulators have focused on "online harms" rather than variety (though the DSA does require platforms to offer algorithmic recommendations that are not based on your personal traits).
Leek identifies this willingness of states to set conditions for algorithm design as a means by which "exploration" can be forced back into the system. She's also bullish on interoperability, so that users can leave platforms with bad recommenders, without losing access to their media or social circles. As she writes, "the deepest discipline on a feed that has trapped you is the credible ability to leave it and take your data with you." I couldn't agree more:
https://pluralistic.net/2023/01/08/watch-the-surpluses/
She's less hopeful about individual responses. Demanding that you be an "adventurous consumer" is a way of letting systems off the hook. When every street has the same restaurants and every bookshop has the same books and the people in your life are all locked into one of two social media platforms, "choosing wisely" only gets you so far. Shopping isn't politics!
https://pluralistic.net/2026/05/21/purity-culture/#stop-fucking-that-chicken
Leek is a superb writer. After reading this piece yesterday, I sent it to half a dozen people and then read everything else in Leek's newsletter archives. Not only is it all brilliant, but I also realized that she'd written one of the most memorable articles about cities and platforms I've read in the last year, "How Google Maps quietly allocates survival across London’s restaurants – and how I built a dashboard to see through it":
https://laurenleek.substack.com/p/how-google-maps-quietly-allocates
I should have added Leek's newsletter to my RSS reader when I read that last December. I've rectified that oversight! What a fantastic thinker, scientist and communicator! If she isn't being relentlessly pestered by editors and literary agents offering her a book deal, then it really does prove that the recommender systems are elevating the bland median over the thoroughly, delightfully spiky outliers.
On AI Coding and Its Discontents https://calnewport.com/on-ai-coding-and-its-discontents/
Crocs Has a Trick for Dodging Taxes: a Tiny Office in Malta https://www.nytimes.com/2026/08/05/business/economy/crocs-malta-tax-haven.html?unlocked_article_code=1.4VA.UZy2.BtVrP_IVnz8b
Why State-Level Contract Law is Essential to the Future of Digital Library Rights https://www.libraryjournal.com/story/news/moving-beyond-the-publisher-playbook-why-state-level-contract-law-is-essential-to-the-future-of-digital-library-rights
What is a Reverse Centaur? https://www.youtube.com/watch?v=CVjt3_bf1bI
#25yrsago Awful, stupid Wired report on Dutch hacker camp https://web.archive.org/web/20011007084604/https://www.wired.com/news/culture/0,1284,46033,00.html
#25yrsaog Excellent NYT story about the internal contradictions of the DMCA https://memex.craphound.com/2001/08/13/excellent-nyt-story-about-the/
#20yrsago Our faulty intuition about open systems https://www.ft.com/content/64167124-263d-11db-afa1-0000779e2340
#20yrsago Defending against the last plot won’t save us from the next one https://www.schneier.com/blog/archives/2006/08/terrorism_secur.html
#20yrsago NBC: Hair-gel terrorists posed no risk last week https://web.archive.org/web/20060813194630/http://www.msnbc.msn.com/id/14320452/
#15yrsago AT&T merger leak: it’s all about raising prices and reducing competition https://web.archive.org/web/20110920222524/http://www.broadbandreports.com/shownews/Leaked-ATT-Letter-Demolishes-Case-For-TMobile-Merger-115652
#10yrsago What’s inside a Tiki Bird? https://miehana.blogspot.com/2016/08/fancy-feathers-restoring-tiki-room-birds.html
#5yrsago End of the line for Reaganomics https://pluralistic.net/2021/08/13/post-bork-era/#manne-down
#5yrsago Smart cities are neither, 2021 edition https://pluralistic.net/2021/08/13/post-bork-era/#our-streets
#1yrago Maga's boss class think they are immune to American carnage https://pluralistic.net/2025/08/13/then-they-came-for-me/#boss-politics
https://www.edbookfest.co.uk/events/cory-doctorow-enshittification
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
AI, automation and enshittification (Telecoms.com)
https://www.telecoms.com/ai/the-telecoms-com-podcast-ai-automation-and-enshittification
The AI Enshittification Bubble (Hidden Forces)
https://hiddenforces.io/podcasts/the-ai-enshittification-bubble-cory-doctorow/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

In the summer of 2013, two esoteric, technical, incredibly important texts were published within weeks of one another: the first is the Snowden leaks, which revealed a system of global, pervasive digital surveillance; the second was Thomas Piketty's Capital in the 21st Century, a book about the economic inevitability (and political instability) of oligarchy:
https://memex.craphound.com/2014/06/24/thomas-pikettys-capital-in-the-21st-century/
In 2013, it wasn't immediately apparent how these two works connected with one another, but in the years since, I've grown increasingly convinced that Snowden and Piketty can only be properly understood as describing two aspects of the same phenomenon.
Piketty's landmark volume was grounded in a detailed analysis of 300 years' (!) worth of global capital flows, painstakingly compiled by a large team of grad students from a massive set of heterogeneous records. The book's conclusion is the statement that "returns to capital exceed the rate of growth over the long term" (abbreviated as "r > g").
This may sound innocuous, but it is explosive. If r > g, then the most wealth will inevitably accumulate in the hands of people who start with the most wealth, irrespective of whether they do anything productive with that money. This means that the alleged heroes of the market system – the entrepreneurs who found and manage the firms that increase public prosperity – are doomed to play second fiddle to the mere plumbers of money, people who "contribute" by accumulating.
The starkest example of this in Capital 21C is Piketty's contrast between L'Oreal heiress Liliane Bettencourt (then the richest woman in the world) and Bill Gates, founder of Microsoft (then the most successful corporation in the world). Piketty compares the growth in the fortunes of Bettencourt and Gates over two periods: first, the period between Microsoft's founding and Gates' retirement as CEO; and second, the period after Gates's retirement from his executive role, when he became a mere investor, no longer an entrepreneur.
During that first period, in which Gates was founding and running the most successful corporation in the world, he accumulated less wealth than did Liliane Bettencourt, who did precisely nothing of value over that period. Bettencourt didn't even manage her investments – that was all handled by some very clever financial planners, lawyers and accountants. In other words: for Bettencourt, doing nothing at all produced more wealth than founding the most successful corporation in the world did for Gates. Bettencourt, a person who owned things, did better than Gates, a person who did things.
And then Gates retired. He stopped doing things and started owning things. He became an investor, whereupon he out-earned both Bettencourt and Gates-the-entrepreneur. Again, the market system allocated fewer rewards to the most successful person in the doing things business than it allocated to that same person once he quit that job and got into the owning things business.
Piketty shows that this holds true across markets and nations and eras: all other things being equal, the market system produces a class of hereditary aristocrats who command the world's capital and direct its deployment, despite never having done anything. The market's most lavish rewards do not go to its most productive participants, but rather, to those participants who have the good fortune to emerge from the luckiest of orifices.
Worse: winning the orifice lottery in no way qualifies you to direct the capital you've inherited. Liliane Bettencourt had no revolutionary new business ideas, invented no miraculous new materials or processes, produced no brilliant art. She merely accumulated, thanks to the professional services of skilled technicians whose job description includes hiring their own successors to ensure that another generation of winners of the Bettencourt orifice lottery could continue to accumulate, commanding more capital and power in society.
Perhaps if these orifice winners were content to allow their bloodless Renfields to allocate their capital while consuming bonbons and attending yacht parties, this could yield a stable politics. But inevitably, people who win the orifice lottery observe that they come from a long line of wealthy people, a line that will continue with their own descendants, and conclude that they have some kind of special, heritable virtue – magic blood – that the system has recognized with their great fortunes and the power those fortunes confer.
That's when things get dangerous: when aristocrats grow bored with their leisure and mobilize their inherited capital to change the way the rest of us live. Billionaire dilettantes are weapons of mass destruction, and their special projects have a wide blast radius and inflict a lot of collateral damage.
Take Bill Gates: his ideological projects have been a catastrophe. A patent maximalist, he funded the lobbyists who successfully blocked South Africa from producing its own AIDS drugs under an IP waiver program, and then deployed them again to stop the Global South from making their own covid vaccines:
https://pluralistic.net/2021/04/13/public-interest-pharma/#gates-foundation
Closer to home, Gates's hatred of public institutions led him to allocate millions to dismantling public schools and replacing them with charter schools, particularly for poor and racialized kids, with disastrous results:
And of course, Gates supported and empowered Jeffrey Epstein and his rape island:
https://en.wikipedia.org/wiki/Bill_Gates#Connection_with_Jeffrey_Epstein
Capital's tendency to accumulate in the hands of the already wealthy (r > g) means that these aristocrats end up setting an ever-larger proportion of our societal agenda, despite their manifest unfitness to govern and their absence of any kind of democratic legitimacy.
Piketty argues that inequality is inherently politically destabilizing. A society ruled over by fools and monsters who were not voted into power and can't be voted out of power is a doomed society. Eventually – the French Revolution, the World Wars – these societies grow so unstable that they collapse altogether.
This is where Piketty and Snowden converge. When the Snowden leaks broke, there was a lot of talk about the mechanics and the legality of the NSA's global digital surveillance, but precious little consideration was given to the reason for all this surveillance. In 2013, the idea that this spying was about "security" was so obvious as to be self-evident. The questions at the time were whether spying could produce security. We weren't asking why things were so insecure.
In retrospect, the answer is to be found in Piketty. Piketty's Capital includes a long, impassioned plea to both lawmakers and aristocrats to consider redistributive policies (like a wealth tax) as the most affordable way to achieve political stability. Fundamentally, Piketty argues that the cheapest way to stop people from building a guillotine on your lawn is to build hospitals and schools; this is cheaper than paying for guards and prisons to lock up would-be guillotine builders.
Today's AI debates swirl around the question of whether AI can truly make us more productive – that is, if chatbots will allow one person to do the work of two, or three, or four – or 100. But when it comes to surveillance, the digital revolution unquestionably produced a massive productivity dividend.
Consider the spying apparatus of the former East Germany ("the GDR") widely considered the most surveilled society in human history. When the Berlin Wall collapsed, there were about 16m people in the country. Of those East Germans, about 90,000 worked directly for the Stasi (the secret police), aided by another 100-200,000 paid informants:
https://www.dw.com/en/east-germany-spy-agency-stasi-surveillance/
Call it 200,000 people to spy on 16m. In other words, it took one spy to watch 80 of their neighbors. Contrast this with NSA spying: they accumulated detailed surveillance dossiers on about 6 billion internet users using a staff of no more than 5 million spooks (in 2013, about 5 million Americans were eligible for security clearance). If every single person with security clearance in the USA was working on the NSA's surveillance program, that would mean that by 2013, computers had made it possible for a spy to keep tabs on more than a thousand people.
Orders of magnitude improvements in a mere generation! This is the kind of productivity lift that economists dream of when they fantasize about the dividends from automation.
But why? Why spy?
East Germany spied on its people because the system was so unjust and cruel that its beneficiaries understood that their neighbors were forever on the brink of rising up against them. East Germany's leaders were right about that – but if anything, they didn't put enough people onto the spying project. We can tell, because the Berlin Wall fell in 1989!
Of course, the GDR was already paying more than 1.2% of its population to spy on everyone else. It's likely that East Germany's leaders believed that their society simply lacked the fiscal space to hire more spies, even if short-staffing the Stasi risked societal collapse. Now, if Piketty is right, East Germany's leaders could have solved this problem by giving people fewer reasons to want to overthrow the state. They could have taken their hands out of the cookie jar, could have instituted democratic reforms – they could have made a bid for democratic legitimacy and public material comfort. But that would have come at the leaders' own power and wealth, and, lacking the stomach for this sacrifice, they lost everything.
Enter the NSA: the digitization of human civilization has drastically reduced the cost of surveillance, and – again, per Piketty – this vastly increases the amount of inequality the world can sustain before the illegitimacy, incompetence and cruelty of rule by the neoaristocratic winners of the orifice lottery brings the whole thing crashing down.
The Trump years are proof of this. We've reached a high-water mark for rule by illegitimate billionaire dilettantes. The second Trump admin began with DOGE's Bonfire of the Stupidities, where Musk cultists dismantled vast swathes of the American administrative state. Musk didn't just attack foreign aid – though the fact that the world's richest man murdered hundreds of thousands of the world's poorest children for the lulz isn't merely cruel, but also massively destabilizing in a way that will shake the world's politics for generations – but also domestic institutions. It was a DOGE cultist who fed the part of the NIH that tracks cyclosporiasis outbreaks into the wood-chipper:
https://truthout.org/articles/disease-researchers-blame-doge-cuts-for-spiraling-cyclospora-outbreak/
Today, tens of thousands of Americans are experiencing the literal enshittification of the American state, and this isn't just a human tragedy (though it is), it's also an economic tragedy, with massive knock-on effects for the businesses that rely on those sickened Americans and for the agricultural sector whose outputs are now being shunned by millions. Whether it's letting Bill Gates decide how your schools will work or letting Elon Musk decide how your public health system runs, the result is political chaos and a societal nudge away from the rule of law and towards guillotines.
Which brings me back to Snowden. The Snowden revelations did spur a global conversation about digital surveillance, with the result that the majority of the world's digital traffic is encrypted today. That's not nothing.
But the American state found new ways to conduct mass-scale, global surveillance, often by collaborating directly with tech giants. Billionaires like Peter Thiel capitalized on Big Tech's conflicted feelings about openly participating in surveillance by founding Palantir, with the express mission of murdering the political opponents of oligarchy:
https://www.thecanary.co/trending/2026/01/07/palantir-kill-communists/
Over the past decade, the steady march of digital technology, dominated by a cartel of giant global firms who collude with the US government's system of political repression in exchange for tax breaks, antitrust forbearance and fat federal contracts has yielded more mass surveillance productivity gains than the previous 25 years:
The Trump administration is the most unpopular in more than a century. Trump has stolen more money in office than any president in history. Trump presides over spiraling greedflation and collapsing buying power. The Trump administration has also presided over a titanic increase in state-aligned, privatized surveillance. The Trump years are the Flock years:
https://newrepublic.com/article/206992/flock-safety-cameras-alpr-deflock-resistance-nationwide
The Trump years are the Palantir years:
https://www.nytimes.com/2025/05/30/technology/trump-palantir-data-americans.html
The Trump years are the facial recognition years:
https://www.aclu.org/news/privacy-technology/ice-face-recognition
Trump's authoritarianism is a function of his misrule, and his misrule is enabled by his authoritarianism. The more he steals, the more he destroys with wars of choice, and incoherent tariff policies, and official pronouncements linking autism and vaccinations, the more he needs spy cameras, internet surveillance, vehicle tracking, and facial recognition. Every time Trump talks about a third term in office, or canceling elections, or suppressing the vote, he creates demand for mass surveillance to catch and imprison the people this drives into the streets. The more mass surveillance there is, the safer it is for him to commit unpopular, corrupt acts. It's the world's worst self-licking ice-cream cone.
It's not just Trump, of course. Trump is the vanguard of a movement of orifice lottery winners whose delight in stealing, cheating, maiming and despoiling gives rise to political instability and requires them to divert some of their yacht money to mercenaries:
https://theintercept.com/2026/06/25/police-luigi-mangione-wealthy-ceos-threat/
Take AI: the Trump years are also the AI years. This is the time in which a wildly unpopular technology is being shoved into every part of every app we rely on:
https://pluralistic.net/2025/05/02/kpis-off/#principal-agentic-ai-problem
It's an era where corporate bosses can't stop gloating about how many jobs they're planning to destroy and how many paycuts they plan on imposing on the surviving workers:
https://www.axios.com/2025/05/28/ai-jobs-white-collar-unemployment-anthropic
AI can't do your job, but an AI salesman can reliably convince your boss to fire you and replace you with an AI that can't do your job:
https://pluralistic.net/2025/03/18/asbestos-in-the-walls/#government-by-spicy-autocomplete
And – most visibly – it's an era in which people's cities and towns are being despoiled by data centers they don't want, by local governments operating in the most extreme secrecy, who silence and even arrest citizens who demand a democratically legitimate process for deciding whether they will have to give up their power and water and land and peace:
An economist would tell you that there's an equilibrium being sought here: between the cost of bribing a town council to ram through data center approvals, the cost of building a more modest and palatable data center, and the cost of mollifying public critics. The cost of bribing towns to foist a data center on the townsfolk is low, because there are lots of towns that fit the bill, so data center barons can shop around.
But as data center protests grow larger and better organized (oligarchy is destabilizing), the cost of dealing with public opposition is mounting. Which is why the Trump administration is teaming up with its preferred tech and military contractors to engage in detailed surveillance of data center and AI critics:
These corporate spooks aren't just spying on data center critics: they've got a whole portfolio of oligarchy-stabilizing surveillance services, targeting "antifa," immigrants' rights and anti-ICE groups.
They're joined by hardware vendors who offer corporations, the wealthy, and enclaves where both are to be found on literal robocops, the ultimate in cheap guard labor (alas, the robots suck):
https://www.404media.co/the-roboguard-revolution-is-short-circuiting/
Trump and his orifice-winning army are caught in the same trap as the leaders of the GDR. Every gain in guard-labor efficiency creates the space for more of them to stick more of their hands even further into the cookie jar. Every time they do, American society grows more unstable, demanding more guard labor.
As we saw in Minneapolis, guard labor – be it mass surveillance, robocops or ICE chuds – is itself destabilizing. Police states make the people who live in them want to overthrow the state, requiring yet more cops, creating more partisans for tearing the whole thing down.
In theory, the orifice class could decide to stop stealing, cheating and maiming. The problem is that for every plute who realizes that the cheapest way to keep the guillotines off his lawn is to play fair, there are three more who lack the executive function to stop cheating. That means that you might as well keep on cheating, since the instability – and the guard labor bills – are coming no matter what.
In the tale of the "Tragedy of the Commons," a common pasture is grazed to dust by shepherds who each understand that if they don't graze their flock until everything is gone, some other shepherd will do so. The original "Tragedy of the Commons" paper was a racist hoax perpetrated by an academic fraud who wanted to make the case for the expulsion of black and Brown people from America and their mass extermination abroad:
In reality, commons need not be tragic and many of our most important resources have been managed as commons for hundreds of years:
https://archive.org/details/governing-the-commons/page/4/mode/2up
But when it comes to the commons that is "a stable society," the orifice class is caught in an inescapable tragedy, certain of the knowledge that if they don't cheat us, the next American aristo will. Thus the demand for guard labor continues to mount…as does the demand for guillotines.
Zack Polanski Promotes Radical Plan to Break Up Britain’s ‘Billionaire Media’ https://bylinetimes.com/2026/08/10/zack-polanski-promotes-radical-plan-to-break-up-britains-billionaire-media/
Subaru Socialists and the Great Disappointed https://www.newyorker.com/news/fault-lines/subaru-socialists-and-the-great-disappointed
Not your imagination: from backpacks to food, consumer goods are getting worse https://www.theguardian.com/us-news/2026/aug/10/consumed-consumer-goods-quality
LAST CALL FOR HOPE 26 TICKETS https://www.2600.com/content/last-call-hope-26-tickets
#25yrsago Wonderfully thorough backgrounder on DeCSS https://web.archive.org/web/20010816194008/https://lemuria.org/decss/hal2001.html
#25yrsago Warhol Worm https://web.archive.org/web/20010814171036/http://www.cs.berkeley.edu/~nweaver/warhol.html
#25yrsago Camgirls use Amazon wishlists for payouts https://web.archive.org/web/20010821234935/http://www.salon.com/tech/feature/2001/08/13/cam_girls/index.html
#25yrsago State of the tech industry 2021 https://web.archive.org/web/20011216222920/http://latimes.com/technology/la-000064605aug09.story
#25yrsago List of scenes cut from Looney Tunes reissues https://web.archive.org/web/20011214095249/http://www.toonzone.net/looney/ltcuts/
#20yrsago Strategy behind using liquids to threaten planes https://web.archive.org/web/20060813001626/https://wondermark.com/d/220.html
#20yrsago RIAA to grieving family: We depose your children in 60 days https://recordingindustryvspeople.blogspot.com/2006/08/riaa-wants-to-depose-dead-defendants.html
#15yrsago Stasi spywear: the inept art of commie disguise https://web.archive.org/web/20120000000000*/http://www.spiegel.de/international/germany/0,1518,777716,00.html
#15yrsago 1968: when Britain’s Daily Mirror tried to overthrow Parliament https://www.bbc.co.uk/webarchive/https%3A%2F%2Fwww.bbc.co.uk%2Fblogs%2Fadamcurtis%2F2011%2F07%2Fevery_day_is_like_sunday.html
#15yrsago My panel with Tim Berners-Lee, Vint Cerf and Al Gore at Mexico City’s Campus Party https://www.youtube.com/watch?v=tXPZnpsN4-s
#15yrsago Doctor tried to "cure homosexuality" by tasping gay man while he had sex with a female sex-worker https://web.archive.org/web/20111004080028/https://blog.ketyov.com/2011/08/self-stimulating-brain-for-heterosexual.html
#10yrsago How a digital-only smartphone opens the door to DRM (and how to close the door) https://memex.craphound.com/2016/08/12/how-a-digital-only-smartphone-opens-the-door-to-drm-and-how-to-close-the-door/
#10yrsago Forget Skynet: AI is already making things terrible for people who aren’t rich white dudes https://www.nytimes.com/2016/06/26/opinion/sunday/artificial-intelligences-white-guy-problem.html
#10yrsago How self-driving cars could make everything worse, and what to do about it https://web.archive.org/web/20170918192128/https://www.wired.com/2016/08/self-driving-cars-will-improve-our-cities-if-they-dont-ruin-them/
#10yrsago The Tor Project’s social contract: we will not backdoor Tor https://blog.torproject.org/tor-social-contract/
#10yrsago Cash grants to people with unexpected bills successfully prevents homelessness https://www.science.org/content/article/bit-cash-can-keep-someone-streets-2-years-or-more
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
AI, automation and enshittification (Telecoms.com)
https://www.telecoms.com/ai/the-telecoms-com-podcast-ai-automation-and-enshittification
The AI Enshittification Bubble (Hidden Forces)
https://hiddenforces.io/podcasts/the-ai-enshittification-bubble-cory-doctorow/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

According to an Economist editorial, "AI is breaking the British state" by making it too easy to file complaints, demands and appeals, which will "drown the state" with "demands as well-crafted as a first-class lawyer's":
Let's pause a moment to appreciate the Economist's touching credulity about AI's coming legal mastery. The law seems to be the area where AI is most prone to "hallucinate" (that is, "produce defective outputs"), which can only be sorted through by skilled practitioners whose experience gives them the discernment to distinguish useful arguments from foolish ones:
https://pluralistic.net/2026/07/28/hitl-ers/#ai-ai-oh
(And this requires those skilled practitioners to avoid the "automation blindness" that afflicts people who are asked to remain vigilant for things that seldom occur, a phenomenon that has turned every TSA agent into the water-bottle-detectingest motherfucker the human race has ever produced, who still misses 95% of the guns that red teams bring through the checkpoint):
More notable than the Economist's faith-based predictions about the impending army of hyper-competent robo-lawyers is the magazine's proposed solution to this looming crisis: "stop creating entitlements that are ripe for AI-fuelled claims…prune the mass of procedural rights." Above all, replace the bureaucrats who process your "complaints, demands and appeals" with more AI, which will arbitrarily decide who gets what, through "personalised welfare interventions" that are not based on any kind of guaranteed rights.
Writing on his blog, the political scientist Henry Farrell tells us where this will inevitably end up: with AI-based robot wars in which increasingly stingy and pernickety robo-bureaucrats create demand for progressively more aggressive robo-lawyers:
https://www.programmablemutter.com/p/the-downside-of-robot-solutionism
As Farrell writes, this end-time was foretold by the prophet Alan Moore with his 1980s 2000 AD character Abelard Snazz, "the man with the two-storey brain":
https://en.wikipedia.org/wiki/Abelard_Snazz
Snazz "solves" the street crime epidemic on the planet Twopp with "Big Police Robots," who spiral out of control, arresting the citizens of Twopp for trivial crimes like wearing brown shoes with a blue suit ("breaking the laws of good taste"). To solve this new problem, Snazz invents "Big Criminal Robots" whose "cunning, efficient" crimes "take up all the police's time."
Twopp is left in a state of high-stakes Big Robot crimewars, in which the most efficient criminals imaginable battle the most ruthless robocops science can deliver, with the Twoppians caught in the crossfire, collateral damage in a robotic forever war (on crime).
As Farrell writes, this is already afflicting the US health system, where an army of insurance company robo-claim-deniers have been countered with a doctors' army of robot-claim-appealers:
https://www.nytimes.com/2024/07/10/health/doctors-insurers-artificial-intelligence.html
The point being that people need health care, people need public services, and while there will always be some waste at the margins (whether due to incompetence or dishonesty) responding to this by beefing up the system's defenses with more advanced red tape just requires the people who legitimately need these services to employ more aggressive tactics.
In support of this, Farrell points to a great, long essay by Dan "Accountability Sink" Davies for the Niskanen Center, "'The Problem Factory' – Preemptive risk aversion in infrastructure planning and the role of professional services":
Davies' essay describes how increasing bureaucratic defenses against frivolous or dishonest claims drives the participants in these processes to assume a war footing and approach the system as a battlefield, leading to the very runaway cost inflation that the bureaucratic process was instituted to prevent.
(Davies, a cybernetician, has some fascinating advice about how to structure planning processes to minimize this, but that's out of scope for this particular post.)
This reminds me of nothing so much as the spam wars. There was a time when it was very easy to set up a mail server and provide email access for anyone who wanted it – including spammers. Increased spam begat increased anti-spam countermeasures, notably the creation of blocklists that allowed mail administrators to automatically reject email from "insecure" mail servers.
Inevitably, spammers figured out how to send spam from "secure" servers, resulting in stricter, more onerous standards for mail server configuration. Spammers – for whom the ability to send spam is an existential matter – figured out how to meet these standards, so the security demands jumped again – and again, and again.
Today, sending and receiving mail is so technically challenging that most of the internet's email is run by a handful of giant, mostly US-based corporations. If any of these companies decides your mail server is spamming, you effectively disappear from the internet and good luck getting them to acknowledge an error. Meanwhile, these companies emit an avalanche of spam, but no one will ever block their servers, because to do so would be to cut off billions of legitimate email users:
https://pluralistic.net/2021/10/10/dead-letters/
And since most of these companies are US-based, they are liable to being weaponized by Trump, who has taken to ordering his tech giants to block foreign officials whose policy decisions make him angry:
https://carnegieendowment.org/emissary/2026/07/icc-trump-push-dismantle
Another parallel is the content moderation wars that saw the large platforms coming up with progressively more detailed rules about what constituted harassment and hate speech, only to have dedicated trolls master these rule-books. Trolls – for whom harassment was a full-time vocation – became the world's greatest experts on the platforms' speech policies, which let them skate right up to the line when abusing their victims, and to get those victims kicked off the platforms if they could be lured into putting a single toe over the line in response:
https://pluralistic.net/2022/08/07/como-is-infosec/
Farrell criticizes the Economist's answer to the (alleged) looming robo-lawyer threat as "solutionism," Evgeny Morozov's word for "Recasting all complex social situations … as neat problems with definite, computable solutions":
https://en.wikipedia.org/wiki/Technological_fix
Using AI to root AI-generated bureaucratic appeals sacrifices the system's putative purpose – delivering services – in the name of defending that service from abuse and misuse of the system's resources. As the pioneering cybernetician Stafford Beer famously wrote, "the purpose of a system is what it does." If your bureaucracy is more concerned with fighting fraud than delivering service, then it isn't a service delivery system at all – it's a service denial system.
As Farrell writes, the people of Twopp can tell you how this ends – in a war of giant robots in which we are all collateral damage.
(A brief postscript: Farrell is a font of science fictional analogies to modern policy issues. This weekend in the FT, he and Dan Wang published an excellent editorial on the relevance of the paranoid, claustrophobic fiction of Philip K Dick to our present political reality:)
Ebooks Are Coming to Libro! https://blog.libro.fm/ebooks-coming-librofm/
What Defeating the American-Israel Political Action Committee Means, on the Ground https://rickperlstein.substack.com/p/what-defeating-the-american-israel
They Live https://badtastegoodcause.com/they-live
#20yrsago Seymour Cray liked to tunnel under his house https://www.cs.man.ac.uk/~toby/writing/PCW/cray.htm
#20yrsago Fake anti-Net Neutrality groups https://web.archive.org/web/20060815175125/http://www.commoncause.org/site/pp.asp?c=dkLNK1MQIwG&b=2007877&auid=1871905&kntaw4229=C9E5C86AD89540898B5D07CB54AB0FE6
#20yrsago HOWTO fold a bottle opener out of paper https://www.youtube.com/watch?v=qrXmDiYHUY0
#20yrsago Wikipedia’s template language is Turing-complete https://web.archive.org/web/20070707115525/http://www.mentalpolyphonics.com/?p=30
#20yrsago Schwarzenegger sends Guard to California’s airports https://web.archive.org/web/20060813201014/http://sfgate.com/cgi-bin/article.cgi?f=/c/a/2006/08/11/SECURITYLOCAL.TMP
#15yrsago Marvel to comics retailers: we’ll give you limited edition singles if you destroy our competitors’ products https://web.archive.org/web/20110908023907/http://www.wired.com/geekdad/2011/08/the-great-marvel-comics-rip-off/
#15yrsago LinkedIn opts you into being used in advertisements; here’s how to opt out https://brandimpact.wordpress.com/2011/08/10/a-box-you-want-to-uncheck-on-linkedin/
#15yrsago MagicJack owner follows up his dumb lawsuit against Boing Boing with a dumb lawsuit against Women’s Professional Soccer https://memex.craphound.com/2011/08/11/magicjack-owner-follows-up-his-dumb-lawsuit-against-boing-boing-with-a-dumb-lawsuit-against-womens-professional-soccer/
#15yrsago Al Jazeera fixes its protections for whistleblowers https://www.eff.org/deeplinks/2011/08/al-jazeera-follows-effs-whistleblower
#15yrsago New Zealand Parliament may lose Internet access due to insane new copyright law https://web.archive.org/web/20110830211231/http://www.greens.org.nz/press-releases/parliament-risk-fines
#15yrsago British aviation bans all hand-luggage http://news.bbc.co.uk/1/hi/uk/4778615.stm?ls
#15yrsago Soldering is Easy: CC licensed HOWTO solder comic https://mightyohm.com/blog/2011/04/soldering-is-easy-comic-book/
#15yrsago Taxonomy of technological risks: when things fail badly https://web.archive.org/web/20190221205543/https://www.sei.cmu.edu/about/divisions/cert/index.cfm
#15yrsago Secret anti-racist shirts covertly distributed to neo-Nazis https://web.archive.org/web/20110810082217/http://www.dw-world.de/dw/article/0,,15305581,00.html
#15yrsago XKCD on the password paradox: human factors versus computers’ brute force https://xkcd.com/936/
#10yrsago American Bar Association votes to DRM the law, put it behind a EULA https://www.abajournal.com/news/article/after_strong_debate_house_calls_for_publication_of_privately_drafted_standa/
#10yrsago Trump only writes the angry tweets, the nice ones are written by a staffer with an Iphone http://varianceexplained.org/r/trump-tweets/
#10yrsago Aviation’s war on moisture turns ten today https://memex.craphound.com/2016/08/10/aviations-war-on-moisture-turns-ten-today/
#10yrsago Court rules that FCC can’t force states to repeal laws banning municipal ISPs https://arstechnica.com/tech-policy/2016/08/in-blow-to-muni-broadband-fcc-loses-bid-to-overturn-state-laws/
#10yrsago NRA is spending $3m on pro-Trump ad that says Clinton “will leave you defenseless” https://edition.cnn.com/2016/08/09/politics/nra-hillary-clinton-donald-trump-election-2016/index.html
#10yrsago Nauru files: leaks tell abused childrens’ stories from Australia’s offshore concentration camp https://www.theguardian.com/australia-news/2016/aug/10/the-nauru-files-2000-leaked-reports-reveal-scale-of-abuse-of-children-in-australian-offshore-detention
#10yrsago Why did it take a private foundation to do public science right? https://medium.com/the-spike/how-a-happy-moment-for-neuroscience-is-a-sad-moment-for-science-c4ba00336e9c#.58om85nvg
#10yrsago Profile of People’s Ride: a co-operative, driver-owned alternative to Uber https://www.democracyatwork.info/profile_peoplesride
#10yrsago The story of the story of Disneyland’s Haunted Mansion https://www.latimes.com/entertainment/herocomplex/la-ca-hc-ghosts-disneylands-haunted-mansion-20151016-htmlstory.html
#10yrsago Designer makes clothes out of German transit upholstery fabric, rides trains https://web.archive.org/web/20160808130200/http://www.bbc.com/autos/story/20160804-why-are-trains-seats-so-hideous
#10yrsago America will finally gather statistics on which and how many people are killed by law enforcement https://www.theguardian.com/us-news/2016/aug/08/police-officer-related-deaths-department-of-justice
#10yrsago Monopoly power and the decline of small business: big business vs democracy, growth & equality https://ilsr.org/article/independent-business/monopoly-power-and-the-decline-of-small-business/
#10yrsago As social media centralized, blogging’s core infrastructure has withered https://medium.com/@anildash/the-lost-infrastructure-of-social-media-d2b95662ccd3
#10yrsago 48 hours later, Adblock Plus beats Facebook’s adblocker-blocker https://www.theverge.com/2016/8/11/12439990/facebook-unblockable-ads-defeated-by-adblock-plus
#10yrsago 100 million VWs can be unlocked with a $40 cracker (and other cars aren’t much better) https://www.usenix.org/system/files/conference/usenixsecurity16/sec16_paper_garcia.pdf
#10yrsago DEA bribes rail/airline employees for tipoffs that lead to warrantless cash seizures https://eu.usatoday.com/story/news/2016/08/10/dea-travel-record-airport-seizures/88474282/
#10yrsago Trump is an object lesson in the problems of machine learning https://mathbabe.org/2016/08/11/donald-trump-is-like-a-biased-machine-learning-algorithm/
#5yrsago IRS leaks reveal billions reaped through ultra-wealthy lobbying on the tax bill https://pluralistic.net/2021/08/11/the-canada-variant/#shitty-man-of-history-theory
#5yrsago Canada's got the world's worst internet ideas https://pluralistic.net/2021/08/11/the-canada-variant/#no-canada
#5yrsago End of the line for Uber https://pluralistic.net/2021/08/10/unter/#bezzle-no-more
#1yrago Goodhart's Law (of AI) https://pluralistic.net/2025/08/11/five-paragraph-essay/#targets-r-us
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
AI and the Enshittification Era (The Weekly Show with Jon Stewart)
https://www.youtube.com/watch?v=-dAIJRjb-Bw
AI is not inevitable (Betakit)
https://www.youtube.com/watch?v=DbiTVkq1WHo
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Hardly a day goes by without my getting an email from someone looking for a way to do good with technology. From computer science students thinking about post-grad careers to seasoned coders with decades of experience, there's an army of hackers looking for a way to turn their expertise into public goods.
There's a name for this movement: it's called "Public Interest Technology" and the people who work in it are called "public interest technologists." There've always been techies who understood the link between tech and public wellbeing and who committed themselves to working for the betterment of society, but their numbers swelled as Big Tech companies saturated their markets and switched from growing by making products people like, to locking in their users and then extracting more value from their technological prisoners:
https://pluralistic.net/2024/04/24/naming-names/#prabhakar-raghavan
It was the era when (in the words of Facebook's Jeff Hammerbacher) "The best minds of my generation are thinking about how to make people click ads":
https://quoteinvestigator.com/2017/06/12/click/
For organizations like the Electronic Frontier Foundation, the growing cohort of hackers who wanted to hack for good was great news. Our staff technologist group swelled from a couple of overworked computer scientists helping lawyers and activists with campaigns to a series of increasingly ambitious software projects, from Privacy Badger (a tracking-blocker that every web user needs):
To Let's Encrypt and Certbot, projects that forever changed the internet's default state, so that today, nearly all online communications are encrypted and resistant to mass surveillance:
Other opportunities for public interest technologists proliferated. Bruce Schneier created the canonical resource page for Public Interest Technologists, including career opportunities for would-be public interest technologists:
https://public-interest-tech.com/
But the motherlode of public interest technologist opportunities wasn't the nonprofit sector – it was the public sector. It started with the UK's Government Digital Service, a group of public-spirited hackers (many of them ex- of the BBC, where they'd been tempest-tossed by endless internal power-struggles over the role of the internet in public service media) who retooled many of the UK government's most important administrative front-ends. For several glorious years, Britons delighted to the daily marvel of having their routine interactions with their government transformed from clunky, broken web-pages to slick, superbly thought through online processes that had all the polish of Amazon or Google, but without any of the gamesmanship, manipulation or privacy invasions:
https://en.wikipedia.org/wiki/Government_Digital_Service
Despite many attempts at official sabotage by a string of increasingly shambolic UK governments, the GDS still exists, and it still does amazing work, even though it operates today with a fraction of the official support that it enjoyed at its inception. The last time I renewed my UK passport, I was gobsmacked by how easy and sensible the process was. Local authorities have gotten in on the act, too: I renewed my absentee voting registration with Hackney Council last week and it was as simple as scanning a QR code, affirming my details, and clicking "submit."
Around the world, a generation of public sector technologists duplicated and improved on the UK GDS's work. In Taiwan, a rogue public interest hacker named Audrey Tang led a group of digital guerrillas in creating shadow versions of every Taiwanese government website that scraped and remade the entire digital presence of the Taiwanese state to make public information and services accessible, legible and useful to its people. After the next election, Tang was named Taiwan's first ever Minister of Digital Affairs (today, she is a Taiwanese "Ambassador-At-Large"):
https://en.wikipedia.org/wiki/Audrey_Tang
In the USA, Jen Pahlka went from running a ragtag "civic hacking" org called Code For America to helping to found the United States Digital Service under Obama, bringing some of that UK GDS spirit to America's dreadful online presence, which had been largely built and maintained by beltway bandits who'd billed handsomely and delivered some of the internet's greatest crimes against usability:
https://en.wikipedia.org/wiki/United_States_Digital_Service
But the USDS's legacy is bitter. In 2025, USDS was effectively dismantled and replaced with DOGE, Elon Musk's handpicked team of tech-bro cultists who set out to dismantle as much of the US government as possible, deliberately sabotaging the usability of America's governmental systems to make it harder for the public to access the services they are entitled to and pay for with their taxes.
My own run-in with this was my attempt to get a certificate of citizenship for my daughter when she turned 18: all I could find was an online form that started by requiring me to list the dates and flight numbers for every trip I'd taken to the USA from the time I was born to the day I became a US citizen, a 50+ year period that started with a trip to visit my snowbird grandparents in Florida when I was six months old. The entire support and advice service for the US Customs and Immigration Service has been replaced with a DOGE chatbot that repeatedly emails and texts links to the form, no matter what question you ask, and no matter whether you call, email or use the website's chat interface:
https://pluralistic.net/2026/02/06/doge-ball/#n-600
Many of the DOGE kids were monsters. The most chilling DOGE story I've heard was the anonymous testimony of NIH officials who begged the DOGE children who were dismantling their work to spare some long-running cancer research projects whose great promise would be vaporized if they were interrupted. The DOGE kids laughed at these entreaties, saying that once Musk had perfected "General AI" we wouldn't need cancer research, because their tame AI god would cure cancer.
But not every DOGE operator was a digital arsonist. Take Dan Berulis, a DOGE staffer who came out of the private sector and later turned whistleblower over the group's activities, who now faces assassination attempts:
https://www.wired.com/story/he-blew-the-whistle-on-doge-then-his-brakes-were-cut/
Berulis joined DOGE to improve America's digital infrastructure, not to dismantle it. When he talks about his motives, he sounds like an early GDS pioneer, one of Audrey Tang's direct-action government data scrapers, or one of the Code For America hackers who followed Pahlka to USDS:
https://www.npr.org/2025/04/15/nx-s1-5355896/doge-nlrb-elon-musk-spacex-security
DOGE was a catastrophe. It left America's government digital presence in far worse shape than it found it, and even the modest savings it claimed to have made from all this destruction turn out to be lies:
https://www.yahoo.com/news/politics/articles/elon-musk-doge-made-big-110000036.html
But as Berulis demonstrates, there is a bipartisan group of skilled, ethical technologists who are desperate to do meaningful public interest work. Their numbers swell every day, as Big Tech continues to curdle – no longer merely sclerotic and enshittifying monopolies, now active participants in Trump's authoritarian dismantling of democracy itself:
Tech bosses' gleeful mass layoffs mean that tech workers can no longer count on good treatment and stable, high-earning careers; at the same time, tech bosses' betrayal of democracy makes the prospect of working for a tech company far more ethically dubious than mere ad-tech optimizations. The result is a bumper crop of geeks looking for ways to do good with their lives and skills – as all the emails in my inbox asking for advice about this attests.
Enter NYC Mayor Zohran Mamdani, who has made "public excellence" the cornerstone of his politics, hiring the most skilled workers he can find and then giving them all the authority and resources they need to fix 100,000 potholes, bring New York's worst landlords to justice, and deliver every day for all the people of New York:
https://pluralistic.net/2025/11/15/unconscionability/#standalone-authority
Mamdani has just unveiled his Public Interest Technology (PIT) Crews: five "game changing" teams of public interest hackers who will remake NYC's digital services:
Writing for Wired, Steven "Hackers" Levy paints a portrait of New York's PIT Crews, describing them as "what DOGE should have been":
https://www.wired.com/story/mamdani-assembles-his-nyc-tech-team/
I'll go farther than that: the PIT Crews – and Mamdani's project as a whole – is delivering the entire failed promise of DOGE. Unlike Musk and Trump, Mamdani is actually rooting out fraud and waste. The reason Mamdani can do this – and the reason billionaires can't – is that the fraud and waste that undermines governments at all levels come from the super-rich, with their tax-dodging, their no-bid contracts, their addiction to public subsidies.
Musk owes his riches to federal bailouts and contracts: if he wants to "eliminate government fraud and waste" he should turn over his files to an IRS inspector (if he can find a survivor of the DOGE massacre) and surrender himself for a lengthy prison sentence. For Musk, "government fraud and waste" is a single mom on food stamps who misses a box on a 600-page form because she's exhausted from working three jobs to make rent – not a no-bid contractor trousering billions in public funds for projects that overcharge and underdeliver.
Mamdani's PIT Crews are "small groups of engineers and designers will strive to change the hidebound and confusing nature of current city services by using state-of-art skills to rapidly whip up specialized apps that solve real problems." Mamdani says that they'll "raise expectations on what government can deliver, because we really can deliver."
As Levy describes it, the big difference between the Obama-era USDS and 2026's PIT Crews is "a skeptical, almost adversarial, stance toward Big Tech." NYC's PIT Crews explicitly recruit top-tier hacker talent who want to "make software that doesn't serve advertisers, the military, or the pocketbooks of centibillionaires."
Their inaugural chief is Lisa Gelobter, a veteran of both tech firms and the USDS, who says that "Without technology, policy is just words written on a piece of paper." The first project on her roster is implementing "Click to Cancel," a policy inaugurated by Lina Khan, Biden's FTC Chief – and then dismantled by Trump. Under Click to Cancel, companies are required to create one-click workflows to cancel subscriptions and memberships, ending the pernicious, incredibly profitable practice of trapping people with impossible-to-halt recurring billings. Today, Khan is running Mamdani's Economic Development Board, and her Click to Cancel rule is back – for New Yorkers, at least:
https://www.theguardian.com/us-news/2026/jul/22/lina-khan-nyc-economic-development-board
NYC PIT Crew's new Click to Cancel site will be live when the policy takes effect on Oct 1. It's a whistleblower site that will make it easy to report merchants who make it hard to get shut of their online Roach Motels (users check in, but they don't check out). It's estimated the Click to Cancel rule will save New Yorkers $160m in the first year alone – but only if Mamdani can enforce it, which is why this website is so critical.
This focus on meat-and-potatoes service delivery was once dismissed as "sewer socialism," an unserious form of progressive politics with an undue focus on improving people's daily lives at the expense of high-flying political change. Today, Mamdani is at the vanguard of an army of proud sewer socialists, who say that once you deliver for people in their day-to-day existence, they will trust you and back you when you fight for deep, structural changes (and the corollary: if you can't deliver for people in their daily lives, why should they trust you when you claim that you'll make everything better?):
https://prospect.org/2026/04/10/zohran-mamdani-getting-new-york-city-believe-in-government/
3,000 techies applied for 35 jobs with NYC's PIT Crews, and, as Levy writes, many of them are high-flying senior coders who are willing to take a massive pay-cut and forfeit their stock options to do something that's both technically excellent and meaningful to their users' lives.
It's a clear message to other leaders, at every level of government. Many of the most skilled, ambitious people in every field want to make the world a better place. Every city, county and state could use a squadron of PIT Crews, and there's an army of coders who would give anything for the chance to give everything to make a better world.
BMW Suddenly Blasts Its Cars’ Internal Screens With Aggressive Advertisements https://futurism.com/advanced-transport/bmw-suddenly-blasts-cars-advertisements
People in the midwest know what a livestream is https://www.garbageday.email/p/people-in-the-midwest-know-what-a-livestream-is
how Google can go legit https://blog.zgp.org/how-google-can-go-legit/
The Yardstick That Ate the Market https://itsg13.substack.com/p/the-yardstick-that-ate-the-market
#25yrsago Moscow's pirate music market https://web.archive.org/web/20010912203143/https://www.wired.com/news/culture/0,1284,45908,00.html
#25yrsago Webcomics v trad comics https://web.archive.org/web/20010821073756/https://www.salon.com/tech/feature/2001/08/09/comics/index.html
#25yrsago Aussie teens are addicted to their phones https://web.archive.org/web/20010818220523/http://news.ninemsn.com.au/national/story_5807.asp
#20yrsago Canadian librarians decry “Captain Copyright” https://web.archive.org/web/20060813004140/https://cla.ca/Access_Copyright_CptCopy_let_Final_.pdf
#20yrsago TiVo/Macrovision screw up breaks devices again https://zatznotfunny.com/2006-08/tivo-macrovision-and-the-stealth-broadcast-flag/
#20yrsago Will the Supreme Court strike down the TSA’s secret laws? https://papersplease.org/gilmore/
#20yrsago Robot garage loses software license, strands parkers https://web.archive.org/web/20060809213517/https://www.wired.com/news/technology/0,71554-0.html?tw=wn_index_1
#15yrsago Typewriter-part penguin https://web.archive.org/web/20111116020049/http://jemayer.tumblr.com/post/8674700147
#15yrsago Choosing Android because you don’t trust Google https://www.theguardian.com/technology/2011/aug/09/technology-failure-more-important-than-success
#15yrsago HOWTO sound Canadian https://web.archive.org/web/20110610104919/http://www.oed.com/public/canadianenglish
#15yrsago Lev Grossman’s The Magician King: fantasy sequel, the banality of magic and the magic of banality https://memex.craphound.com/2011/08/09/lev-grossmans-the-magician-king-fantasy-sequel-the-banality-of-magic-and-the-magic-of-banality/
#10yrsago Rosie the Riveter, Ghostbusters edition https://www.deviantart.com/hugohugo/art/We-Can-Bust-It-621803816
#10yrsago Thai telcoms regulator wants tourists to use location-tracking SIMs https://web.archive.org/web/20160812182254/https://www.nationmultimedia.com/breakingnews/Thailand-mulls-location-tracking-tourist-SIM-cards-30292551.html
#10yrsago Mysterious medical research consortium: we should own volunteers’ clinical trial data for 5 years https://www.techdirt.com/2016/08/08/medical-researchers-want-up-to-five-years-exclusivity-clinical-trial-data-derived-volunteers/
#10yrsago Illegal “Warranty Void If Removed” still ubiquitous: they’re on the Xbox One S https://web.archive.org/web/20160809092923/https://motherboard.vice.com/read/the-xbox-one-s-still-uses-microsofts-illegal-warranty-void-if-removed-sticker
#10yrsago Your medical data: misappropriated by health-tech companies, off-limits to you https://web.archive.org/web/20180806230935/https://www.wired.com/2016/02/our-medical-data-must-become-free/
#10yrsago Return of Dieselgate: 3 more hidden programs found in VW Audi/Porsche firmware https://www.reuters.com/article/us-volkswagen-emissions-audi-idUSKCN10I0PB/
#10yrsago Timelapse of pills dissolving: “decaying clowns” https://www.youtube.com/watch?v=4rY3X4xafs0
#10yrsago Proof-of-concept ransomware for smart thermostats demoed at Defcon https://web.archive.org/web/20161020083358/https://www.pentestpartners.com/blog/thermostat-ransomware-a-lesson-in-iot-security/
#10yrsago Compounds in human exhalations during movies vary in response to suspense and comedy https://www.nature.com/articles/srep25464
#10yrsago How racist traffic stops criminalize black people, and what to do about it https://www.vox.com/2016/8/5/12364580/police-overcriminalization-net-widening
#10yrsago Chicago cops switched off bodycams and high-fived after shooting unarmed black teen https://web.archive.org/web/20160807194244/http://www.theroot.com/articles/news/2016/08/chicago-pd-paul-oneal-video/
#10yrsago DoJ to judges: use Tor to protect your internet connection https://web.archive.org/web/20160807025945/http://motherboard.vice.com/read/department-of-justice-official-tells-hundred-federal-judges-to-use-tor
#5yrsago Expectations management pluralistic.net/2021/08/08/expectations-management-part-v/
#5yrsago When your boss wants an AI camera in your bedroom https://pluralistic.net/2021/08/09/computer-says-no/#disciplinary-tech
#5yrsago The 22 Murders of Madison May https://pluralistic.net/2021/08/09/computer-says-no/#existential-crisis
#1yrago Millionaire on billionaire violence https://pluralistic.net/2025/08/09/elite-disunity/#awoken-giants
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
AI and the Enshittification Era (The Weekly Show with Jon Stewart)
https://www.youtube.com/watch?v=-dAIJRjb-Bw
AI is not inevitable (Betakit)
https://www.youtube.com/watch?v=DbiTVkq1WHo
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

I'm sure that working in social media – dealing with people as mass statistical abstractions – is a cognitohazard, the sort of thing that could make anyone a little solipsistic, convinced that everyone else is a kind of stimulus-responding automaton lacking the interiority that you yourself experience.
But when it comes to Mark Zuckerberg, I'm increasingly convinced that he didn't acquire his worldview through the self-inflicted brain damage of his long exposure to the back-end of a vast social media system. I think the causal arrow points in the other direction: I think that Zuck founded Facebook because he doesn't really believe that other people are truly real, at least not as real as he is.
We see this in Facebook's very earliest days, as we see it today, as we see it at every critical juncture in Facebook and Zuckerberg's history.
Consider Facebook's origins, founded by a young Zuckerberg in his dorm as a means to nonconsensually rate the fuckability of his fellow Harvard undergrads:
https://mashable.com/article/mark-zuckerberg-lying-about-facebook
The boy Zuck was delighted and surprised that so many of his fellow students entrusted him with their data but even then, he had no inkling as to why they would do so. Privately, he jeered at his users for trusting him, calling them "dumb fucks":
Zuck has since prosecuted history's most ruthless war on privacy, a surveillance campaign that would put the Stasi to shame and make Orwell scoff at the hacks butchering his work with over the top absurdities.
Zuck doesn't think you deserve any privacy, but boy does he ever value his own. This is a guy who bought the four houses surrounding his San Francisco home and left them empty in order to form a buffer zone:
When a single candid photo of Zuck and his family in their kitchen leaked (from Facebook!), Zuck, his lawyers, and his operatives treated it as a three-alarm fire:
https://abc7news.com/archive/8933289/
Zuckerberg's acquired a vast Hawaiian acreage and left most of it undeveloped, fenced off and patrolled by guards to prevent anyone from catching a glimpse of his private life. In order to acquire this acreage, Zuck exploited a dirty legal tactic called "heirs property," which leverages the informal basis of indigenous land claims by locating a single person with a colorable claim to their distant relatives' territory in order to force an auction of the ancestral land:
https://www.wired.com/story/mark-zuckerberg-secretive-hawaii-compound-burial-ground/
If Zuck thought other people are as real as he is, he wouldn't spy on them in ways he himself could never tolerate. He certainly wouldn't pay fancy white-shoe lawyers to steal their land out from under them. At heart, Zuck is a billionaire solipsist to beat all other examples of the form – a billionaire social media solipsist who sees others as manipulable collections of statistical abstractions, and not as people at all:
https://pluralistic.net/2025/08/18/seeing-like-a-billionaire/#npcs
When Zuck is forcibly reminded that other people do indeed exist, he takes it very badly. He's insisted that Sarah Wynn-Williams, a former FB exec turned whistleblower, must pay him $111,000,000 as punishment for her excellent tell-all memoir Careless People. His lawyers say that Wynn-Williams violates the non-disclosure and non-disparagement "agreement" of her old Facebook employment contract merely by standing motionless and silent for an hour on-stage:
https://pluralistic.net/2026/06/27/zuckerstreisand-2/#autodisparagement
Once you realize that Zuck doesn't really think other people exist, "the metaverse" starts to make a lot more sense. Why would Zuck light $61b on fire in a bet that we will all stand still while he converts us and everyone we love into legless, sexless, low-polygon, heavily surveilled cartoon characters that he imprisons in a virtual world he stole from a 25 year old satirical dystopian cyberpunk novel? It's easy to understand if we're all non-player characters – if that's true, then the metaverse is surely our native habitat.
For Zuck, people aren't co-equals with needs that are as real and important as his own. For Zuck, people are problems to be solved. He embodies Terry Pratchett's maxim (voiced by Granny Weatherwax) that "sin is when you treat people like things."
Nowhere is this sin more on display than in Zuck's relationship to the social connections that bind together the users of his platforms. Zuck has benefited enormously from the fact that you love your friends more than you hate him, but (because hell is other people), you can't all agree on when to leave and where to go next, so you stay put on Facebook and Instagram:
https://locusmag.com/feature/commentary-cory-doctorow-hell-is-other-people/
For Zuck, the fact that you and your friends have trapped one another in a mutual hostage-taking is maddening, because those friends who've tied you to his platform refuse to organize their social contact with you to "maximize your engagement" with Facebook and Insta, which would let him maximize the number of ads he shows you. Rather, these friends just want to be your friends, which means that they don't want to get into stupid endless fights to keep you replying or stage little entertaining skits to keep you scrolling.
At first, Zuck tried tweaking his algorithm to replace your friends with trolls who'd bait you into flamewars. When that petered out, he stole a march from Tiktok and recruited an army of theater kids to do amateur dramatics for you in exchange for the promise of an intermittent reward schedule payment for the sketches that got the most views:
https://pluralistic.net/2026/04/17/for-youze/#forever
The problem (for Zuck) is that theater kids are also people and they resent being jerked around by the algorithm and ripped off by Meta's rigged revshare slot-machine. Last year, he started signaling that he would replace the theater kids – and your friends – with chatbots:
Chatbots have been a catastrophic bet for Meta, far worse than the metaverse. Meta shares are in a death-spiral as investors figure out that when Zuck fired all his coders and replaced them with chatbots while spending $300b on AI, he was excising the heart of the company's skilled workforce, pissing away all its free cash-flow, and sinking into a bottomless pit of debt to produce a substandard product that no one wants, at the expense of the company's only profitable lines of business:
https://www.cbsnews.com/news/ai-bubble-tech-selloff-investment-consumer-business-demand/
But Zuck is sure that chatbots can solve his most pernicious problem: the search for a gimmick that will keep you locked to his platform that is under his complete control. Zuck doesn't want to rely on your friends with their unwillingness to maximize your engagement. He doesn't want to depend on volatile and unpredictable trolls to bait you into sticking around to argue and see more ads. He wants to be shut of theater kids and their amateur dramatics that inevitably come with demands for decent treatment.
For Zuck, chatbots dangle the promise of social media without socializing. Zuck thinks he can solve all his problems by imprisoning you in a house of mirrors where you interact with LLMs that are tuned to keep you scrolling no matter what, chatbots that will never demand anything of Meta.
He's been at this for a while, and each generation of chatbots was worse than the last. How bad? The last batch had to be killed off after they took to luring children into explicit sexual role-play:
Nevertheless, the dream of a world without people is one that Zuck can't let go of. Solipsism's seductive song convinced him to buy a company called Social.ai, which specializes in trapping people in conversations with chatbots, and now he's announced his plan to flood Facebook and Instagram with LLM slop:
https://www.mediapost.com/publications/article/402263/
The amazing thing about this is that Zuck is talking about chatbots as a way to capture a younger audience for his graying platforms. Kids hate chatbots. My 18 year old and her friends use "that's so AI" as a pejorative to dismiss anything distasteful or ugly:
https://futurism.com/artificial-intelligence/gen-z-attitude-ai
For Zuck – who owns a controlling share of voting stock in his company and need not answer to his board – it's a spectacular act of delusional self-sabotage. Zuck refuses to understand that the majority of his users are on his platform because they love their friends more than they hate him. Zuckerberg is on a relentless quest to isolate you from the friends who keep you on his platform and transfer your bond to groups of people (and now chatbots) who can be commanded by Zuckerberg.
Only someone who doesn't think other people are real could believe that you'd prefer to talk to chatbots rather than your friends – or that a habit of talking with chatbots would be so hard to break that you'd endure an ever-increasing number of advertising interruptions to maintain those pointless conversations.
In 1993/1994, AOL connected its millions of users to the public internet. These users were unaccustomed to the internet's conversational and technical norms, and they kept coming. It wasn't that the old internet was incapable of absorbing surges of new users: every September, an incoming class of undergraduates found their way online through their universities' computer labs.
But the AOL bridge was different: the flood of users was much larger, and it never stopped. The old internet people who struggled to transfer the culture and techniques of the internet to that flood of newbies called it the "Eternal September."
For the Facebook and Instagram users who are about to be buried in an endless botshit avalanche, this is the beginning of the "Eternal Sloptember." From here on in, the slop only gets worse and thicker and harder to avoid. Zuckerberg refuses to acknowledge that he owes his fortune to the fact that his users love each other more than they hate him, so he has set out to shatter those bonds of love and sharpen that hatred.
It won't end well. Zuck and people like him call themselves "high agency," a disgusting bit of jargon meant to denote someone who has real interiority, wishes and desires (as opposed to the rest of us, who do as we're told and stay where we're put). Zuck's "agency" isn't higher than yours or mine. The difference between him and us is that he doesn't think we're really real, and we know that he's really a monster.
Meta Adding Millions Of AI-Generated 'Users' To IG, Facebook https://www.mediapost.com/publications/article/402263/
The Oligarchs are Doubling Down on Republicans https://paulkrugman.substack.com/p/the-oligarchs-are-doubling-down-on
rent, always rent https://backofmind.substack.com/p/rent-always-rent
I replaced a $120k bowling center system with $1,600 in ESP32s https://news.ycombinator.com/item?id=48968606
#25yrsago Samuel Delany interviewed by The Onion https://web.archive.org/web/20010810115550/http://www.theonionavclub.com/avclub3727/bonusfeature1_3727.html
#25yrsago Evil Burger King customers https://web.archive.org/web/20010805001648/http://www.geocities.com/CapitolHill/Lobby/2645/index.html
#25yrsago Definitive search engine optimization primer https://web.archive.org/web/20011006095612/https://hotwired.lycos.com/webmonkey/templates/print_template.htmlt?meta=/webmonkey/01/23/index1a_meta.html
#20yrsago Only traitors try to make us afraid of terrorists https://web.archive.org/web/20060418102222/https://www.cato.org/pubs/regulation/regv27n3/v27n3-5.pdf
#20yrsago Swingin’ big band song about rejecting surveillance https://web.archive.org/web/20060818220142/http://movies.crooksandliars.com/HYHEMix.mp3
#20yrsago Duran Duran moves to Second Life, will gig there http://news.bbc.co.uk/1/hi/technology/5253782.stm?ls
#20yrsago Seventy percent of blog-pings are from spammers https://web.archive.org/web/20060820151227/http://www.sifry.com/alerts/archives/000436.html
#20yrsago London’s derelict cinemas https://web.archive.org/web/20060809210918/https://www.derelictlondon.com/cinemas.htm
#10yrsago Foreign influence: how a Chinese businessman funneled $1.3M to Jeb Bush’s campaign https://web.archive.org/web/20160803180101/https://theintercept.com/2016/08/03/gop-lawyer-chinese-owned-company-us-presidential-politics/
#10yrsago Researchers learn about wire-fraud scam after scammers infect themselves with their own malware https://spectrum.ieee.org/nigerian-scammers-infect-themselves-with-own-malware-revealing-new-wirewire-fraud-scheme
#5yrsago End bankruptcy shopping https://pluralistic.net/2021/08/07/hr-4193/#shoppers-choice
#5yrsago Doordash privacywashes its war on workers https://pluralistic.net/2021/08/07/hr-4193/#boss-app
#1yrago Good ideas are popular https://pluralistic.net/2025/08/07/the-people-no-2/#water-flowing-uphill
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
AI and the Enshittification Era (The Weekly Show with Jon Stewart)
https://www.youtube.com/watch?v=-dAIJRjb-Bw
AI is not inevitable (Betakit)
https://www.youtube.com/watch?v=DbiTVkq1WHo
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X

Forget "Don't be evil"; Google's true motto is a form of vulgar spidermanism: "With great power comes no responsibility." The internet's de facto boss is an absentee landlord.
Google – a thrice-convicted monopolist – is the gateway to the internet, with more than a 90% search market share that it attained by buying out all its competitors and bribing Apple more than $20b/year not to start a rival search engine:
https://www.democracynow.org/2024/8/6/google_monopoly
Google likes to position itself as a wise steward of the internet. They say they use their vast troves of data about the internet and its users to connect the right person with the right information at the right moment. As their mission statement has it, "organize the world's information and make it universally accessible and useful":
https://www.google.com/intl/en_us/search/howsearchworks/our-approach/
The tacit argument is, "Sure, we repeatedly violated antitrust law in order to monopolize the internet, but the internet needs a monopolist. It's scary out there! We have amassed power so that we can protect and guide you."
It's a bullshit argument and no one should accept it – but even if you think it's worth harnessing monopoly power to promote a wise king to rule over the internet, you'd still want Google to take that responsibility seriously. If we're to have a landlord for our civilization's digital nervous system, let's not have it be an absentee landlord.
Google is an absentee landlord. In 2019, they chose to deliberately worsen search results in order to make you search repeatedly to find the information you're seeking, because every fresh query lets them serve fresh advertisements:
https://pluralistic.net/2025/05/26/babyish-radical-extremists/#cancon
Not all of Google's enshittification can be attributed to deliberate sabotage. Much of it is the result of neglect. Ask Google for a product review and they'll pass over the most rigorous, honest websites on the internet in favor of affiliate scammers who repackage Amazon best-of lists to peddle overpriced, underperforming junk that's sometimes so bad it's dangerous:
https://pluralistic.net/2024/02/21/im-feeling-unlucky/#not-up-to-the-task
Google keeps announcing that it Takes This Problem Very Seriously – and then nothing happens:
https://pluralistic.net/2024/05/03/keyword-swarming/#site-reputation-abuse
And of course, Google AI search results present the company with a highly refined and confident-sounding way to launder spam into product recommendations:
https://pluralistic.net/2025/07/15/inhuman-gigapede/#coprophagic-ai
Could Google do better? Provably so. Kagi, a small company that runs a search engine powered by Google's own search index consistently delivers results that are substantially superior to Google's – using Google's own infrastructure:
https://pluralistic.net/2024/04/04/teach-me-how-to-shruggie/#kagi
If Kagi (a startup with a handful of engineers) can extract useful search results from Google's databases, then Google – a thrice-convicted monopolist that's had its pick of thousands of the top computer scientists from the world's most prestigious universities for a generation – could also do so.
They just choose not to.
They're too big to fail. They're too big to jail. They're too big to care.
Google's AI search isn't a way to fix its broken core product: it's a way to partially remediate the damage Google itself inflicted on the open internet, while imprisoning the web in a walled garden that would make Steve Jobs drool:
https://pluralistic.net/2026/06/29/arsonist-firefighters/#im-feeling-lucky
It's a deadly combination: Google has committed hundreds of billions to stock buybacks and its AI money-furnace, financed by mass layoffs targeting the people who keep the core services useful. The too-big-to-care company is still the internet's gatekeeper, but half the guards at the gate have been fired and the other half have pulled so much overtime that they keep falling asleep on the job.
Google has become a scammer's paradise.
Take Google's "answer box." This is the part of the search results page that tries to answer your query directly, without sending you elsewhere for that info. Back in 2023, Google's Answer Box was taken over by scammers who impersonated airline help desks. When Google's users searched for airlines' toll-free phone numbers, Google directed them to phones that rang in the scammers' boiler room, where they were tricked into giving up their passport info and credit card numbers to boiler-room thieves:
(This was an especially devastating attack because the airlines themselves hide their customer service phone numbers – as enshittified monopolists, they want your money, not your complaints – so it's normal to search Google for the number you're seeking, rather than scouring the airlines' deliberately confusing customer service sites.)
This is especially galling because Google has an extensive "verified merchant" program that goes to enormous lengths to establish the true identity of every merchant whose businesses are listed on Google, in maps, ads and search results. Google "knows" which URLs belong to the airlines. If it can be tricked into scraping a different website for the airlines' phone numbers, that's because Google couldn't be bothered to connect its own database of canonical airline URLs to the process that serves phone numbers to the 90% of the web-using public who search with Google.
Google's database of the canonical URLs for businesses doesn't stop at airlines or even large businesses. Nearly every local merchant has undergone Google's verification process, which includes a step where Google physically mails a postcard with a unique number to the merchant's registered address, which the merchant must then key into Google to prove that they're located where they say they are.
Despite this, Google's ad-sales system will happily sell anyone the right to advertise a different website for queries for specific merchants, and those ads appear above the real result for the business's website. To make this even worse, Google's spent years making it more difficult to distinguish ads from "organic" search results, changing the font and size of the "ad" warning to make it harder to spot, and making the font and color of the ad itself closer to the color of the search results below it.
This is a gift to fraudsters. I had my own run-in with it in 2023, when I was tricked by a Google ad into ordering dinner from my local Thai place using a scam site that had cloned the restaurant's menu. The scammers marked up the price by 15%, then passed the order on to the restaurant, pocketing the vig:
https://pluralistic.net/2023/02/24/passive-income/#swiss-cheese-security
This scammer – based out of a UC Berkeley dorm-room – had copied hundreds of restaurant websites, then bought Google ads for the restaurants' names, ensuring that searchers would see the scam result before the real one. Remember: Google knows what the true URL is for every one of those restaurants but it sold the scammer ads for a different URL that appeared when people searched for the restaurant by name.
Google could trivially add a step to the ad sales pipeline that detects mismatches between a merchant's known URL and the URL in an ad bought against the merchant's name. It could automatically resolve these mismatches by sending an email to the merchant's verified email address that says, "Hey, are you buying an ad with a new URL? If so, just reply to this email."
I don't know why Google doesn't do this. Maybe they make huge sums from these scam ads and they don't want to forego the revenue. Or maybe they just don't care.
Whichever it is, there's real consequences for this negligence by the internet's absentee landlord. Take abortions: fake abortion clinics – where pregnant women are bullied or tricked out of the abortions they're seeking – buy Google ads against the names of real abortion clinics. Google makes millions sending abortion-seekers to fake abortion providers:
https://pluralistic.net/2023/06/15/paid-medical-disinformation/#crisis-pregnancy-centers
Google started off as the ideal "intermediary" – the fancy economist's term for a "middleman." They took as their duty to figure out the best websites for you to look at based on your interests, serving as an honest broker between internet users and internet publishers. In the quarter-century since the company's founding, as it transformed itself into a monopolist, it developed the curse of every intermediary: it got Main Character Syndrome.
This is Tim Wu's formulation: the reason for an intermediary existence is to serve the parties to the transaction. Ebay says it exists to connect buyers and sellers, Uber is supposed to connect drivers and riders, dating sites are supposed to connect people with their love-matches. But intermediaries are cursed with an enviable position: by dint of sitting between these different groups of people, the intermediary learns everything about both sides of the transaction, while each side only knows about its own position.
Amazon knows the price you're willing to pay, it knows who's set the lowest price, and it knows how many identical items that match your query are for sale. But the sellers don't know any of that, and you only know some of it. By capitalizing on that information (rather than using it to efficiently match buyers and sellers), Amazon can match you with the sellers willing to pay the highest junk fees, rather than the ones who offer the best price for the best goods:
https://pluralistic.net/2023/11/03/subprime-attention-rent-crisis/#euthanize-rentiers
This is Wu's Main Character Syndrome in action. Once Amazon attains a dominant market share, it can maximize its own welfare at the expense of its buyers and sellers, transforming itself from a helper to a parasite:
https://www.lawfaremedia.org/article/lawfare-daily–tim-wu-on–the-age-of-extraction
Google says it wants to "organize the world's information and make it universally accessible and useful," but every dime it spends fighting fraud (a critical part of this mission!) is a dime it can't spend on stock buybacks, executive compensation and AI servers. "Organize the world's information and make it universally accessible and useful" is the mission of a good intermediary; "do the absolute minimum to fight fraud" is the mission of a formerly good intermediary with terminal Main Character Syndrome.
Google keeps finding ways to expose its users to fraud while lining its own pockets. That restaurant markup scam that caught me in 2023? Three years later, it's way worse.
San Francisco City Attorney David Chiu just filed suit against GuestReservations.com, BookOnline.com and Booking Holdings for running a massive version of the restaurant menu scam – one that extracted millions from people booking hotel rooms:
Here's how the scam worked: these companies put up websites with deceptive URLs, like SanFranciscoMarriott.GuestReservations.com, and then bought the associated Google ad-word ("San Francisco Marriott"). At the top of Google searches for "San Francisco Marriott booking" was the ad for SanFranciscoMarriott.GuestReservations.com. This site would sell you a room at the Marriott, at a markup of 35% to 85%.
This is a pure ripoff. If Google had served the correct result at the top of the page – if it had used its own database of confirmed merchants and their associate websites to validate its ads – then people booking hotels would have saved 35% to 85% on their rooms.
City Attorney Chiu says that the perps here registered domains for all kinds of hotels, even tiny ones in small towns, all over America. That means that it's not just visitors to San Francisco who got screwed by these creeps – it's also San Franciscans who booked hotel rooms around the country.
Google bears the lion's share of the blame here, but Visa and the other credit card companies are critical to these scams. Card companies allow merchants to set terms of service that refuse refunds under almost any circumstances, and, more often than not, the card issuers side with the merchants over their own customers when they call to cancel a charge from one of these scammers.
I discovered this for myself when I was tricked into buying theater tickets from a ripoff site that had registered the URL of the show I wanted to go to. I figured out that I'd been rooked within a minute of clicking the buy button, but it took months and multiple appeals – and ultimately a threat to cancel my credit card – to get Visa to refund me.
Visa – another bloated monopolist with terminal Main Character Syndrome – can see that it has merchants who generate zillions of appeals and charge-backs because they run scam businesses like these. They could treat these merchants as the fraudsters they are, but because the crooks wreathe themselves in gauzy excuses and lengthy terms of service, Visa enables these massive, nationwide cons.
Google, Visa and the other monopolists who serve as de facto regulators for our society have arrogated to themselves the power to observe every transaction and block the obvious scams. We pay for their failure to take minimal, obvious steps to protect us from the scammers who thrive on their platforms.
Why should they? They're the main characters. They're Bizarro-world spidermen, whose great power confers no responsibility.
Gavin Newsom Makes An Ass Of Himself On Antitrust, Paramount Merger https://www.techdirt.com/2026/08/04/gavin-newsom-makes-an-ass-of-himself-on-antitrust-paramount-merger/
Against Self-Fulfilling Prophecy https://www.hamiltonnolan.com/p/against-self-fulfilling-prophecy
Arson markets https://www.merkley.senate.gov/wp-content/uploads/2026.08.03-LTR-Wildfire-Prediction-Markets-FINAL.pdf
Eight Myths on Software Engineering and GenAI https://queue.acm.org/detail.cfm?id=3807963
#25yrsago Steve Ballmer: DEVELOPERS DEVELOPERS DEVELOPERS DEVELOPERS DEVELOPERS http://www.ntk.net/ballmer/dancemonkeyboy.mpg
#15yrsago HOWTO E-Z realistic corpse from a cheap plastic skeleton https://propnomicon.blogspot.com/2011/08/quick-and-dirty-corpses.html
#15yrsago $300 Million Button: making customers create logins to buy cost etailer $300M/year https://centercentre.com/
#10yrsago 1 billion computer monitors vulnerable to undetectable firmware attacks https://www.defcon.org/html/defcon-24/dc-24-speakers.html#Cui
#10yrsago Stiglitz quits Panama’s official money-laundering panel over internal sabotage https://www.reuters.com/article/us-panama-tax-idUSKCN10G24Z/
#10yrsago BBC will use surveillance powers to sniff Britons’ wifi and find license-cheats https://web.archive.org/web/20160806155022/https://www.telegraph.co.uk/news/2016/08/05/bbc-to-deploy-detection-vans-to-snoop-on-internet-users/
#10yrsago How and why to short Uber https://qz.com/707947/investors-have-placed-a-one-way-bet-on-uber-which-made-us-want-to-figure-out-a-way-to-short-it
#5yrsago Facebook's official disinformation research portal is a bad joke https://pluralistic.net/2021/08/06/get-you-coming-and-going/#potemkin-research-program
#5yrsago Scammers sell griefers social media banning services https://pluralistic.net/2021/08/06/get-you-coming-and-going/#curse-of-bigness
#1yrago Which jobs can be replaced with AI? https://pluralistic.net/2025/08/06/unmerchantable-substitute-goods/#customer-disservice
Edinburgh International Book Festival with Jimmy Wales, Aug 17
https://www.edbookfest.co.uk/events/the-front-list-cory-doctorow-and-jimmy-wales
Sydney: The Festival of Dangerous Ideas, Aug 23-24
https://festivalofdangerousideas.com/program/
Melbourne: Enshittification at the Wheeler Centre, Aug 25
https://www.wheelercentre.com/events-tickets/season-2026/cory-doctorow-enshittification
Brighton: The Reverse Centaur's Guide to Life After AI with Carole Cadwalladr (Brighton Dome), Sep 8
https://brightondome.org/whats-on/LSC-cory-doctorow-the-reverse-centaurs-guide-to-life-after-ai/
London: The Reverse Centaur's Guide to Life After AI with Riley Quinn (Foyle's Picadilly), Sep 9
https://www.foyles.co.uk/events/enshittification-cory-doctorow-riley-quinn
South Bend: An Evening With Cory Doctorow (Notre Dame), Oct 6
https://franco.nd.edu/events/2026/10/06/an-evening-with-cory-doctorow/
Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/
F@#$ the AI Overlords (On The Media)
https://www.wnycstudios.org/podcasts/otm/articles/f-the-ai-overlords
Why AI Won't Replace Workers, But Will Crash The Economy (Smart Cookies)
https://www.youtube.com/watch?v=rRRmUuxJolY
AI and the Enshittification Era (The Weekly Show with Jon Stewart)
https://www.youtube.com/watch?v=-dAIJRjb-Bw
AI is not inevitable (Betakit)
https://www.youtube.com/watch?v=DbiTVkq1WHo
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
"The Memex Method," Farrar, Straus, Giroux, 2027
Today's top sources:
Currently writing:
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
OAuth originally assumed clients would be pre-registered at an authorization server.
Before an app can talk to an OAuth server, a developer signs up for an account, registers the client by providing the name and logo and other client information, configures redirect URIs, and gets a client_id. The server has some record of who this client is and who is responsible for it.
That works fine when the ecosystem is closed. Google can require developers to register before accessing their API. Salesforce can do the same. But what about ecosystems where any client should be able to talk to any server, where it's not possible for the client developer to be aware of every server ahead of time?
This is the "open web" problem. Mastodon users expect any Mastodon client to work with any Mastodon server. BlueSky works the same way. The MCP ecosystem is heading in the same direction, users expect to be able to connect their own MCP client to any MCP server. When you have potentially thousands of clients and thousands of servers, you can't require every client developer to register with every server operator in advance.
Dynamic Client Registration (DCR) was designed to solve this. A client shows up at a server, registers itself on the spot, and gets credentials. No prior relationship required.
The problem is DCR pushes all the trust decisions onto the authorization server, with nothing to actually base those decisions on, and no real link to the client developer.
DCR is defined in RFC 7591. The client sends a POST request to the server's registration endpoint with its metadata: a display name, logo URL, redirect URIs, contact information. The server responds with a client_id and optionally a client_secret. From that point on, the client uses those credentials in OAuth flows with that server.
sequenceDiagram
    participant C as Client
    participant AS as Authorization Server

    C->>AS: POST /register<br/>(name, logo, redirect_uris, ...)
    Note over C,AS: Unauthenticated — no credentials required
    AS->>C: 201 Created<br/>(client_id, client_secret)
This works, at least in the sense that it solves the bootstrapping problem. The client can show up without any prior arrangement and get credentials.
But there is a deeper problem that this flow makes hard to see.
The registration endpoint must be open to the world by design. That is the whole point of dynamic registration in an open ecosystem. Any actor, whether that's a legitimate app, a bot, or an attacker, can call it and create a client registration.
graph LR
    A[Web App\nname: Acme\nlogo: acme.com/logo.png]
    B[Desktop App\nname: Acme\nlogo: acme.com/logo.png]
    C[Attacker\nname: Acme\nlogo: acme.com/logo.png]

    A -->|POST /register| R[/Register Endpoint/]
    B -->|POST /register| R
    C -->|POST /register| R

    R --> D[client_id: aaa]
    R --> E[client_id: bbb]
    R --> F[client_id: ccc]

    style C fill:#ffdddd
    style F fill:#ffdddd
The metadata in the request is entirely self-asserted. The server has no way to verify that the entity calling /register controls the logo URL it submitted, runs the website it claims to represent, or is in any way connected to the app name it provided. The authorization server is simply asked to accept claims it cannot check. The only clue as to the real identity of this client is the redirect_uri, which is only a partial solution as we'll discuss shortly.
Once a client registers, the authorization server is responsible for managing that registration indefinitely. This creates an operational problem that has no clean solution.
There are a few approaches servers take to clean up stale registrations:
Delete if unused within N hours. This seems reasonable until you realize it breaks clients that register in advance of a user session, or clients used infrequently. It also does nothing for malicious registrations that were used once.
Delete when the last refresh token expires. This is a cleaner signal, but it still requires keeping a record of every client until its tokens expire. For servers with high legitimate usage, this table grows continuously.
Leave it to the client to re-register. The problem here is clients have no reliable way to know whether their registration is still valid before sending a user through an OAuth flow. The client doesn't even discover the registration is gone when the flow fails, because this failure mode ends with the user on the authorization server screen, never being sent back to the client. To avoid dead ends, clients tend to re-register on every login. This compounds the very bloat you were trying to avoid.
| client_id | created | last used |
|---|---|---|
| aaa1 | 6 months ago | unknown |
| bbb2 | 3 months ago | unknown |
| ccc3 | 3 months ago | today |
| ddd4 | 1 month ago | unknown |
| eee5 | today | today |
| ... 10,000 more |
The authorization server is stuck guessing which records are safe to delete, while new ones keep arriving.
The most serious problem with DCR is not the operational overhead. It is that impersonation is structurally impossible to detect.
Nothing in DCR prevents an attacker from registering a client with the same name, logo, and description as a legitimate app. Both will have a client_id. Both will show users the same consent screen. The authorization server has no mechanism to distinguish them.
graph LR
    subgraph Legitimate App
        L[client_id: abc123\nname: Acme Wallet\nlogo: acme.com/logo.png]
    end
    subgraph Malicious App
        M[client_id: xyz789\nname: Acme Wallet\nlogo: acme.com/logo.png]
    end

    L --> U1[User sees:\n'Acme Wallet wants access']
    M --> U2[User sees:\n'Acme Wallet wants access']

    style M fill:#ffdddd
    style U2 fill:#ffdddd
This presents a real OAuth phishing risk. A fake app can present a consent screen that looks identical to a legitimate service. If the user authorizes it, from the server's side, nothing looks wrong.
There are defenses against this, but they all require clients to opt into something extra: signed software statements, app attestation, platform-issued certificates. That pushes a significant burden onto every legitimate developer, and leaves the protection entirely voluntary.
From the client developer's perspective, DCR introduces a class of credential that OAuth was supposed to eliminate: per-server identities that have to be managed, stored, and refreshed.
For each authorization server the client works with, it now needs to:
/register to receive a client_id and client_secretThere is also no standard mechanism for a client to verify its client_id is still valid before starting a flow. When the authorization server is about to present an OAuth consent screen, it realizes the client_id doesn't exist and ends the flow there, not sending the user back to the invalid client. The user sees a generic error screen, and the client doesn't even know this happened.
All four of these issues trace back to the same structural flaw: DCR separates the assertion of identity from any authority over that identity.
The authorization server accepts claims about who the client is, but has no external signal to verify those claims against. The client says "I am Acme App" and the server has nothing to cross-reference that against.
Compare this to what we do for humans. When a user logs in, the server asks them to prove something: a password, a passkey, an OTP. The claim "I am Alice" is backed by something. DCR never asks the client for anything comparable.
The question is: what does a client actually control in the real world? A web app controls its domain. A mobile app has a backend, or an app store identity. These are real anchors. The question is whether the protocol uses them.
Client ID Metadata Document (CIMD) is built around that insight. The client_id is a URL. The authority comes from who controls that URL.
With CIMD, there is no registration step. The client's identifier is a URL on a domain the client controls. When an authorization server encounters a client_id it has not seen before, it fetches that URL to discover the client's metadata.
sequenceDiagram
    participant App as Client App
    participant Browser as Browser
    participant AS as Authorization Server
    participant Meta as app.example.com

    App->>Browser: Redirect to AS<br/>client_id=https://app.example.com/client
    Browser->>AS: GET /authorize?client_id=https://app.example.com/client&...
    AS->>Meta: GET https://app.example.com/client
    Note over AS,Meta: Back-channel fetch from client-controlled domain
    Meta->>AS: Returns JSON metadata document
    AS->>Browser: Show consent screen using fetched metadata
    Browser->>AS: User approves
    AS->>Browser: Redirect to redirect_uri with auth code
    Browser->>App: Delivers auth code
    App->>AS: POST /token
    AS->>App: Access token
The client publishes its own display name, logo, redirect URIs, supported authentication methods, and JWKS. The AS discovers this at runtime. Nothing needs to happen in advance.
This one change, making the client_id a URL on a client-controlled domain, solves most of the problems described above.
When the AS fetches the client metadata, it knows what domain it fetched it from. That domain is something it can actually start making decisions about. This opens up trust tiers that were structurally impossible with DCR:
graph TD
    subgraph Authorization Server Policy
        A{Client domain\nseen before?}
        A -->|No, first time| B[Show extra confirmation\nto user]
        A -->|Yes, pre-approved| C[Proceed normally]
        A -->|Flagged/blocked| D[Deny request]
    end

    B --> E[User approves]
    E --> C
An AS can prompt users for extra confirmation when a client from a newly seen domain requests access — similar to how browsers warn about unfamiliar download sources. Once enough users have authorized clients at a domain and nothing suspicious has come up, the AS can gradually reduce the friction for that domain. It can integrate domain reputation services. It can maintain an explicit allowlist of verified domains for frictionless access, and block suspicious ones.
None of this requires the client to behave differently based on which AS it is talking to. A client that has been pre-enrolled by an enterprise admin and a client talking to the same AS for the first time present their client_id URL identically. The domain is implicit in the URL, and the AS decides what to do with it.
Enterprise admins need control over which apps can access company resources. With DCR, this is nearly impossible: the client_id is generated dynamically at registration time, so the admin has no way to reference it before the employee runs the app.
With CIMD, the admin pre-registers the client_id URL (for example, https://myapp.example.com/oauth/client) in the AS. When an employee runs the app, the app presents its client_id URL as it always does. The AS fetches the metadata, finds the URL is already registered by the admin, and proceeds with the enterprise-approved experience.
sequenceDiagram
    participant User
    participant App as Client App
    participant AS as Authorization Server
    participant Admin

    Admin->>AS: Pre-register client URL<br>https://myapp.example.com/oauth/client
    Note over Admin,AS: Setup happens once, in advance

    User->>App: Starts OAuth flow
    App->>AS: client_id=https://myapp.example.com/oauth/client
    AS->>App: Fetch metadata from URL
    App->>AS: Returns metadata
    Note over AS: URL matches pre-registered entry
    AS->>User: Proceeds with approved experience
The client doesn't know or care whether it is being used in an enterprise context. Its client_id URL is the same everywhere. The enterprise filtering happens entirely at the AS.
Because the client publishes a JWKS (or a JWKS URI) in its metadata document, it can rotate keys without coordinating with the authorization server. The AS fetches fresh metadata when the cache expires and picks up the new keys automatically. This makes private_key_jwt client authentication practical for any client with a web presence.
Authorization servers that want to enforce strong client authentication can validate the signatures. Servers that do not have that requirement can ignore the signature and proceed with whatever they accept. The client publishes good metadata and lets each AS enforce what it needs.
Mobile apps have always been a challenging case for client identity. The app binary has no inherent web identity, and DCR gives it none.
With CIMD, a mobile app can follow the pattern in OAuth Attestation-Based Client Authentication: the app's backend (an "attester backend") hosts the CIMD document and manages the client's keys. The AS fetches the CIMD URL, which points to the attester backend, and can perform attestation checks against the key material there.
sequenceDiagram
    participant App as Mobile App
    participant AB as Attester Backend
    participant AS as Authorization Server

    Note over AB: Publishes CIMD at<br>https://attester.example.com/client
    Note over AB: Manages JWKS and<br>attestation material

    App->>AS: client_id=https://attester.example.com/client
    AS->>AB: Fetch CIMD document
    AB->>AS: Returns metadata + JWKS URI
    AS->>AB: Fetch JWKS
    AB->>AS: Returns public keys
    Note over AS: Can now verify app-signed assertions<br>using attester-managed keys
Mobile platforms also give apps a way to "claim" an https redirect URL, linking the app binary to a domain the developer controls. This connects the redirect URL and the CIMD URL to the same domain end to end, giving the AS another corroborating signal.
One thing worth noting for readers familiar with DCR: the spec does define a software_statement property that was intended to solve a similar problem. In practice it was left underspecified — the DCR spec itself says nothing about how to create one, what it should contain, or how keys should be managed. Any ecosystem trying to use it would need to define all of that separately, and then convince every mobile app developer and every AS to adopt the new behavior. CIMD combined with Attestation-Based Client Authentication layers on top of the existing jwks_uri mechanism, which means it composes with what implementations already support rather than requiring a new convention from scratch.
This gives the AS a meaningful level of confidence in the mobile app's identity.
| Dynamic Client Registration | Client ID Metadata Document | |
|---|---|---|
| Registration step | Required (unauthenticated POST) | None |
| Authority anchor | None (self-asserted) | Domain ownership |
| Client impersonation | Undetectable | Domain-keyed, harder to fake |
| Client lifecycle management | AS must manage cleanup | Client controls its own document |
| Key rotation | Requires AS coordination | Client-controlled, AS fetches on use |
| Enterprise pre-approval | Out-of-band coordination required | Admin registers URL; client behavior unchanged |
| Mobile attestation | Requires special-casing | Natural fit via attester backend |
| Per-AS credential to store | client_id + secret | None |
CIMD is not a complete solution to the open ecosystem trust problem. A few things are worth calling out, either as known limitations or as possible future work.
Domain spoofing at the visual layer is still possible. An attacker pretending to be acme.com can register acme-login.com and host a convincing CIMD document there. Domain reputation services help, but do not eliminate this. The improvement over DCR is that there is now a domain to leverage in any decisions, and domain-based signals are much richer than nothing.
CIMD only helps as much as the AS acts on it. A server that accepts any CIMD URL without applying any domain-based policy gets roughly the same trust posture as DCR on the impersonation dimension, though the client lifecycle and credential sprawl problems are still improved.
For machine-to-machine clients without an attester backend, CIMD without private_key_jwt or mTLS is still self-asserted metadata, just fetched from a URL rather than submitted via POST. Strong client authentication still requires key material.
Desktop apps are the hardest case. Mobile platforms provide attestation APIs and let apps claim https redirect URLs. Desktop platforms currently do not. A desktop app cannot cleanly connect its running instance to a domain the developer controls, and localhost redirect URLs (which desktop apps are forced to use) can be intercepted by any app on the same machine and provide no protection against app impersonation.
This means client impersonation for desktop apps remains possible even with CIMD. That said, it is no worse than DCR, which also provides no solution here. And adopting CIMD for desktop apps still removes the credential sprawl problem and makes the AS implementation uniform across all client types, rather than requiring special handling for desktop.
Token binding is still available to desktop apps. Specs like DPoP bind access tokens and refresh tokens to client-asserted keys without trying to solve client authentication. A desktop app can leverage DPoP to limit token reuse even when client identity itself cannot be strongly verified.
DCR solved the bootstrapping problem but could not solve the trust problem. It gave authorization servers a way to accept unknown clients, without giving them any tools to reason about which unknown clients to trust.
CIMD is not a drop-in replacement for DCR in every deployment. But for open ecosystems like MCP, decentralized social, and federated enterprise, it provides the trust hooks that DCR structurally cannot. The domain is a useful anchor. Enterprise pre-enrollment of clients requires no client changes. Key management stays with the client. Mobile app attestation fits naturally.
For AS operators, the path forward is to accept client_id values that are HTTPS URLs, fetch the metadata document on first encounter, and build domain-based trust policies from there. For client developers, the change is even simpler: publish a metadata document at a stable URL on your domain and use that URL as your client_id.
The specs are live and moving through the IETF process. Client ID Metadata Document covers the metadata document format and discovery. Attestation-Based Client Authentication describes the architecture of using an attester backend with mobile apps.
If you are building in this space, both documents are worth reading, and the OAuth working group is actively discussing both. Feel free to chime in on the OAuth mailing list or on the individual GitHub repos for the specs.
Hello! I’m on a funny journey right now where I’m trying to learn how to make websites in a sort of 2010 style, where I have an SQL database and render some HTML on the backend.
It’s kind of an interesting journey because it doesn’t necessarily feel “easy” to me to make websites in this way: I never learned how to do it in the 2000s or 2010s, and there’s a lot I need to learn.
So here are some Django features that make building this kind of site feel more achievable than when I was trying and failing to use Go’s standard library or Flask. And I’ll talk about a couple of issues with Django I’ve run into.
Previously the toolkit I felt confident with for making websites was:
I really liked this frontend-heavy approach for these super simple applications but when I started thinking about making something with a lot of different pages (instead of literally just one page), I didn’t feel so excited about the options I saw that involved a lot of frontend code. So I figured I’d try the backend.
Writing a backend-focused site that uses as little JS as possible feels the same to me in a way as writing a single-page JS website that does as little on the backend as possible, even though they might seem like opposites. In both cases I’m just trying to keep as much of the logic as possible in one place.
Now for some thoughts about Django!
I learned that I can define a “query set” class in Django with a bunch of
methods with different WHERE statements I might want to use while constructing
a query:
Here’s how I use it in my view code once I’ve defined what all the methods mean:
Events.objects.approved()
  .for_tab(tab)
  .with_festivals(tab_params.festival_slugs)
  .is_free(tab_params.free)
  .is_outdoors(tab_params.outdoors)
and here’s how I define the methods:
class EventQuerySet(SearchableQuerySetMixin, models.QuerySet):
    def approved(self):
        return self.filter(approved_at__isnull=False)

    def future(self):
        today = timezone.localdate()
        return self.filter(end__gt=self._midnight(today))

    def with_tags(self, tags):
        if tags:
            return self.filter(tags__name__in=tags).distinct()
        return self
The syntax for defining the filters isn’t my favourite, but I spend most of my time just using the methods, and it feels super readable and nice to use, and it makes me want to look into other query builder libraries in the future. In the past I thought “I know SQL, who needs a query builder?”, but this kind of structure does make it really nice to read.
I found an example of someone who wrote their own small query builder in Python that I want to read later to think about whether I would enjoy using a more minimal version of this.
There are a bunch of little quality of life filters available in Django templates that are super useful for generating HTML. The ones I’ve used so far are:
<br> ({{ event.description|urlize|linebreaksbr }} ){{ row.date|date:"M j" }})json_script, which takes a Python dictionary and automatically converts it to JSON and inserts it into the HTML as a <script> tag in a safe wayThese are all small things individually but I feel like it makes a big difference somehow to just have them available.
querystring is coolI think my favourite template filter is querystring: in this site sometimes
we use filters like ?date=2026-06-01 to decide what’s displayed. querystring
that will make a link to the same query string with one change, like this to
link to the previous date:
<a href="{% querystring date=nav.prev_date%}">
Or to remove the outdoors parameter:
<a href="{% querystring outdoors=None %}">
I still really love Django’s automatic database system. It’s amazing to be able to just edit a model to add a new field or whatever, and then Django automatically generates the migration.
So far we have done 19 database migrations and I think there will probably be more! It makes a huge difference for me to be able to just easily change the database as my understanding of the problem changes.
Django’s documentation sometimes offers the option of using class-based views and inheritance to organize the code in your views. For example I have four views that share a lot of code, and I could use inheritance to manage that by defining some kind of parent class and then having my other views inherit from it.
I tried it out and I did not enjoy the experience of using inheritance to share code between views. I switched to using functions instead, sort of how this post advocates, and that was a lot more straightforward. I’ve never had a good experience using inheritance in Python and I don’t think I’ll try to use it again.
But I don’t mind using inheritance to use the interfaces Django itself provides: for
example if I want to define a query set I need to write something like
class EventQuerySet(SearchableQuerySetMixin, models.QuerySet).
I don’t think too hard about it and it seems to work.
(as a meta comment: I’ve been working on talking about my programming opinions by just saying “THING does not feel good to me, I prefer OTHER THING instead”. That post I linked to says that function-based views are the “right way”. I’m not very invested in whether it’s “right”, but it’s validating to know that other people feel similarly to me about inheritance)
At some point the LLM scrapers discovered our site, and started sending us maybe 10 requests per second. I blocked them which is working for now, but it made me think about what the site’s capacity is. I’m used to writing Go backends where the performance situation is pretty straightforward (usually everything is just fast enough), and a Django site is very different.
Some light load testing (with (ab -n 1000 -c 1) shows that right now we can
serve about 2-3 requests per second (on a ~$10/month VM).
It’s tempting for me to go down a rabbit hole where I do a bunch of profiling to figure out what’s slow and try to make it faster (there’s py-spy for that, and py-spy is great and super easy to use, and profiling is fun!) But I really don’t understand what I should expect in terms of performance from a Django site and how I should be thinking about at a higher level.
Some things I haven’t figured out yet:
I think one thing I’m learning about Django is that because it’s a Framework (tm), it’s easy to accidentally misconfigure it. For example, when I was thinking about why my site was slow just now, I read the django performance docs and I noticed a comment saying:
Enabling the cached template loader often improves performance drastically, as it avoids compiling each template every time it needs to be rendered.
When I’d done CPU profiling I’d noticed that it was spending a lot of time rendering templates! Maybe this could help me!
Clicking through the link, I saw that the cached template loader was supposed to be on by default, but I’d turned it off by accident while trying to do something else. I think this “I turned off the cached template loader by default” things is an example of how I still find the django settings file to be pretty confusing and difficult. I guess I should just be careful when I go in there.
After turning on template caching, it seems like the site can now pretty easily handle 12 requests per second or so without using all of the CPU. I have not carefully benchmarked the before and after but it seems like it’s made a pretty big difference.
One thing that’s been surprising to me about Django performance is that I’ve always heard the advice “if you have a performance problem, check your database queries! Maybe add an index!”. But I’ve been running into a variety of performance issues (like this template caching thing) that are not because of slow queries, so instead it’s been more useful for me so far to start by running a CPU profile. And since I’m using SQLite, any slow database query problem will show up on the CPU profile anyway.
Anyway I don’t want to get too far into site performance. Like I said it’s easy for me to get interested in profiling, but actually I know a lot about profiling and it’s not the most important thing for me to learn about.
I might say more about what I’m enjoying (or having a hard time with!) about Django later. Trying to write some shorter blog posts recently.
Hi all,
I owe the working group a review of the "OAuth Profile for Open Public Clients", and apologies for sending this so late after the last IETF meeting, and the night before this IETF meeting.
Please note that I have not followed all of the discussion about this draft on the mailing list or recent meetings. If any of my suggestions have already been discussed and decided against, the justification for the decision would be worth noting in the draft for future reference.
My feedback is ordered most significant to least significant.
Overall, this spec is in good shape. It avoids defining new OAuth mechanisms, it establishes no new relationships between OAuth roles and it uses the standard Resource Owner / Client / AS / RS model.
My largest piece of feedback is about the use of Dynamic Client Registration. The use of DCR in "open world" OAuth will lead to significant operational burden. I believe I already shared this feedback a couple of years ago. Since then, there has been another large scale deployment of DCR that has since moved away to an alternative.
The initial version of the MCP spec from March 2025 required MCP clients register using DCR. Many of the authorization servers that immediately added support for it have since come to regret the challenges with operating it long term, and there are many other authorization servers that refused to add support in the first place, requiring manual configuration instead.
In the time between then and now, the OAuth working group has adopted Client ID Metadata Document (CIMD) https://datatracker.ietf.org/doc/draft-ietf-oauth-client-id-metadata-document/ which provides a way for a client to publish its metadata at a URL and use that URL as the OAuth client_id. Both the BlueSky/atproto ecosystem as well as the MCP ecosystem now recommend CIMD as the default client registration option. Since both of these ecosystems are also "open world" OAuth like the email ecosystem, it would also be a natural fit here.
While it is not yet an RFC, it is already getting quite a lot of adoption, and I expect that to continue.
Despite the client_id being a URL, this works just fine with desktop and native apps. The URL would be hosted on the app's website, and since most apps have a website you can download them from, this isn't a problem in practice. And for the clients that are already web based, this is a natural fit. Which also leads me to the next point...
I realize that most of the clients that will implement this spec are desktop/mobile clients, so will be considered public clients since they won't have a way to be provisioned with credentials. However there will also be clients that are running on a web server, in which case they do have the ability to manage credentials.
Paired with CIMD, a web-based client would publish its public key and link to it from the jwks_uri property in the CIMD, and would then be able to strongly authenticate all outgoing requests using private_key_jwt (described in Section 8.2 https://www.ietf.org/archive/id/draft-ietf-oauth-client-id-metadata-document-02.html#section-8.2). For these clients, it means the client metadata is not only hosted at a URL, but the metadata can actually be considered to be authenticated so is much more trustworthy than both unauthenticated CIMD metadata and especially DCR metadata. The other nice thing about this is if an authorization server doesn't care about client authentication it can just ignore the header and process the request identical to a client that doesn't use client authentication.
offline_access scopeThe offline_access scope is not defined in any OAuth RFC, it originates from the OpenID Connect Core spec. Using it in a non-OIDC OAuth profile is fine, but registering it in the IANA "OAuth Scope" registry is probably not appropriate. I think you can just remove this from the IANA registration section and the references to it in the scope sections are sufficient.
Requiring DPoP would provide meaningfully stronger security, as token theft is a realistic threat against long-running desktop clients. The draft acknowledges DPoP's value but leaves it optional. Given that the minimum access token lifetime is one hour (see below), a stolen token has significant value. DPoP substantially limits the risk.
Combining with the feedback above, an option could be to require DPoP for public clients, but leave it optional for clients using client authentication published in the CIMD.
Most OAuth security guidance recommends short-lived access tokens, in the order of minutes, not hours. Setting a minimum of 1 hour in the spec is unusual and goes against the direction of most OAuth security profiles. This isn't necessarily a dealbreaker, but is at least worth justifying in a little more detail.
If you are using DPoP, you can also generally justify longer-lived access tokens, so another option is to have different recommendations depending on whether DPoP is used.
Pushed Authorization Requests (RFC 9126) prevents authorization request parameters from appearing in browser history and eliminates certain parameter-manipulation attacks. For this use case, where the client constructs the full authorization URL locally before handing it to the browser, PAR would provide meaningful additional protection. To my earlier point, if there was a conscious decision to not require PAR, it would be worth noting the reasons at the very least.
There is a mention in Security Considerations that "The issuer is expected to be autodetected from the user's email address", but there is no description of how this is expected to be done. I see that this mechanism is described in the "Automatic Configuration of Email, Calendar, and Contact Server Settings" draft, but there should probably be a reference to that from somewhere in this profile.
The spec references RFC 6819 as the OAuth threat model but not RFC 9700 (OAuth 2.0 Security Best Current Practices, published 2025). RFC 9700 supersedes much of RFC 6819's threat analysis and is the current normative security reference. This should be added.
Thanks, and I am happy to discuss any of this further during the meeting or if you find me during any breaks this week.
Hello! I’ve been working on a Django site recently, and I decided to use SQLite as the database. When I was getting started with using SQLite as database for a website I read a bunch of blog posts about how it is totally fine to use SQLite in production for a small site and I think it is totally fine, but what I did not fully appreciate is that SQLite is still a database, databases are complicated, and I do not know a lot about operating databases.
So here are a couple of small things I’ve been learning about running SQLite. This is the 4th website I’ve used SQLite for, and I think this one is harder because with the power of the Django ORM I’ve been making the database do more work than I was previously without Django.
I started by turning on WAL mode like all the blog posts said to do and hoping for the best.
ANALYZE is apparently importantToday I was running a query (using SQLite’s FTS5 for full-text search) on a table with 4000 rows and it took 5 seconds. That seemed wrong to me: computers are fast!
It turned out that what I needed to do was to run ANALYZE!
Immediately the problem query went from taking 5 seconds to like 0.05 seconds
(or some other number small enough that I didn’t care to investigate further).
I still don’t know exactly what went wrong in the query plan,
but my best guess is that it was some sort of accidentally quadratic thing.
ANALYZE generates “statistics” (I guess about the number of rows in each table? and presumably other things?)
so that the query planner can make better choices.
Maybe one day I’ll learn to read a query plan.
Occasionally I’ve run into situations where I accidentally put a bunch of rows in my database that I don’t want to be there (for example completed tasks from django-tasks-db), and I want to clean them up.
What’s happened to me a few times in this case is:
My approach so far has been to just do these cleanup operations in small batches so that I don’t need to do database queries that take more than 5 seconds to run. This whole experience has given me more of an appreciation for why someone might want to use a “real” database like Postgres which can have more than one writer at the same time though.
Maybe in the future I’ll just take the site down for scheduled maintenance instead when I need to do this kind of thing, but I haven’t figured out a workflow for that yet.
So far I’ve been using Django’s ORM to make any query I want without paying any
attention at all to query performance and it’s mostly been going okay other
than the ANALYZE thing. The database is pretty small (maybe 10000 rows?) and
I expect it to stay pretty small forever, so I’m hoping that that plan will
keep working.
I’ve done SQLite backups a couple of ways. I don’t think I’ve actually tested restoring from my backups but I do usually try to monitor them with a dead man’s switch.
way 1: restic
sqlite3 /data/calendar.db "VACUUM INTO '/tmp/calendar.sqlite'"
gzip /tmp/calendar.sqlite

# Upload backup to S3
# Sometimes the backup gets OOM killed and so it stays locked, do an unlock
restic -r s3://s3.amazonaws.com/some_bucket/ unlock
# Do the backup & prune old backups
restic -r s3://s3.amazonaws.com/some_bucket/ backup /tmp/calendar.sqlite.gz
restic -r s3://s3.amazonaws.com/some_bucket/ snapshots
restic -r s3://s3.amazonaws.com/some_bucket/ forget -l 1 -H 6 -d 2 -w 2 -m 2 -y 2
restic -r s3://s3.amazonaws.com/some_bucket/ prune
way 2: litestream
I started trying out Litestream recently because I felt like doing incremental backups might be more efficient: my restic backups were sometimes getting OOM killed, and I was a bit tired of it. Basically I just write a config file and run:
litestream replicate -config litestream.yml
I set retention: 400h in my config file in an attempt to
retain some amount of history of the database but I have no idea if it works.
I’ve been backing up to AWS, which is always a pain because it’s annoying to navigate the AWS console to generate credentials. Maybe one day I’ll move away to some other S3-compatible alternative.
My current project only has one database, but one trick I used with Mess with DNS was to split the tables into three separate database files because I didn’t actually need my tables to be in the same db. I think it was helpful.
Mess with DNS has been running on SQLite for 4 years now (since 2022) and it’s been great, I think the move from Postgres was a great choice for that project.
It’s always kind of fun to see how long it takes me to learn sort of basic
things about the technologies I’m using. I think I used SQLite for a web project
for the first time in 2022 and I only learned that ANALYZE existed today!
I imagine in a year or two I’ll be learning about some other very basic feature.
Some blog posts I’ve looked at, other than the official docs:
Cross-domain access is everywhere in today's software landscape. Whether you look at enterprise SaaS applications, AI agents interacting with user data across multiple platforms, or "integrated experiences" pulling information from a calendar, a chat tool, and a wiki—everything eventually needs to talk across boundaries.
Development teams frequently reach for the quickest path to wire these systems together. Usually, teams fall back on two "obvious" architectural shortcuts. However, as experience deploying these architectures at scale demonstrates, both models break down in production.
Let's take a closer look at why these shortcuts fail and what a resilient cross-domain pattern actually looks like.
🧶 Shortcut #1: Have the IdP issue the access token directly
The pattern: the client takes its ID Token to the IdP, exchanges it for an access token, and sends that access token straight to the resource app's API.
Why it's tempting: it reuses the IdP that everyone already trusts. It feels like a clean, one-stop shop.
Why it breaks: every API on the receiving end now has to trust a growing list of foreign token issuers — each with its own quirks around token format, claim conventions, key rotation, and revocation.
Suddenly your API team is in the federation business, doing one-off integrations per IdP. That's not a sustainable model for building APIs at scale. APIs are far better served by having a local authorization server issuing the tokens they validate — one issuer, one model, one set of rules.
🪪 Shortcut #2: Send the ID Token across domains
The pattern: skip the IdP-issued access token and present the original ID Token directly at the receiving app's authorization server, exchanging it for a locally issued access token.
Why it's tempting: ID Tokens are standardized, so it feels like it sidesteps the trust-fan-out problem from #1.
Why it breaks: ID Tokens are issued for one audience — the application the user signed into. Sending them somewhere else violates that audience binding, opens up replay and misuse risks.
🎯 What Cross-App Access does differently
Cross-App Access (XAA) uses a two-stage flow — and each stage exists specifically to fix one of the problems above.
Stage 1: The client makes a Token Exchange request to the IdP to exchange the ID Token for an ID-JAG: a purpose-built, short-lived, audience-bound grant for the resource authorization server.
No ID Token misuse, no audience confusion. The IdP also stays in the loop to govern whether this cross-app access should happen at all — exactly where enterprise IT already manages who can access what.
Stage 2: The resource app's authorization server exchanges the ID-JAG for its own access token. The API keeps its local AS, its own token format, and its own revocation story. It only has to trust the access tokens issued by its own AS — not a foreign access token.
We can push all the complexity of user login, token minting, and cross-domain policy evaluation onto the specialized identity components, keeping the resource API free to do the much simpler task of validating its own domain's access tokens and serving data.
If you're designing cross-domain access for an AI agent, an enterprise suite, or any multi-vendor ecosystem, this is the pattern to follow. The IETF draft: https://datatracker.ietf.org/doc/draft-ietf-oauth-identity-assertion-authz-grant/
Hello! 8 years ago, I wrote excitedly about discovering Tailwind.
At that time I really had no idea how to structure my CSS code and given the choice between a pile of complete chaos and Tailwind, I was really happy to choose Tailwind. It helped me make a lot of tiny sites!
I spent the last week or so migrating a couple of sites away from Tailwind and towards more semantic HTML + vanilla CSS, and it was SO fun and SO interesting, so here are some things I learned!
As usual I’m not a full-time frontend developer and so all of my CSS learning has happened in fits and starts over many years.
When I started thinking about structuring CSS, I was intimidated at first: I’m not very good at structuring my CSS! But then I started reading blog posts talking about how to structure CSS (like A whole cascade of layers or How I write CSS in 2024) and I realized a couple of things:
For example, Tailwind has:
I’m going to talk about a few aspects of my CSS codebase and my thoughts so far what kind of rules I want to impose on the codebase for each one. Some of them are copied from Tailwind and some aren’t.
I just copied Tailwind’s “preflight styles”
by going into tailwind.css and copying the first 200 lines or so.
I noticed that I’ve developed a relationship with Tailwind’s CSS reset over time,
for example Tailwind sets box-sizing: border-box on every element (which means
that an element’s width includes its padding and border):
* { box-sizing: border-box; }
I think it would be a real adjustment for me to switch to writing CSS without
these, and I’m sure there are lots of other things in the Tailwind reset (like
html {line-height: 1.5;}) that I’m subconsciously used to and don’t even realize are
there.
This next part is the bulk of the CSS!
The idea here is to organize CSS by “components”, in a way that’s spiritually related to Vue or React components. (though there might not actually be any Javascript at all in the site)
Basically the idea is that:
So editing the CSS for one component won’t mysteriously break something in another component. And probably like 80% of the CSS that I would actually want to change is in various component files, so if I’m editing a 100-line component, I just have to think about those 100 lines. It’s way easier for me to think about.
For example, this HTML might be the .zine “component”.
<figure class="zine horizontal">
    <img src="whatever.jpg">
</figure>
And the CSS looks something like this, using nested selectors:
.zine {
  ...
  &.horizontal {
    ...
  }
  &.vertical {
    ...
  }
  &:hover {
    ...
  }
}
I haven’t done anything programmatic (like web components or @scope) that ensures that components won’t interfere with each other, but just having a convention and trying my best already feels like a big improvement.
Next: conventions to maintain some consistency across the site and keep these components in line with each other!
colours.css has a bunch of variables like this which I can use as necessary.
Colour is really hard and I didn’t want to revisit my use of colour in this
refactor, so I left this alone.
The only guideline I’m trying to enforce here is that all colours used in the site are listed in this file.
:root {
  --pink: #fea0c2;
  --pink-light: #F9B9B9;
  --red: #f91a55;
  --orange: rgb(222, 117, 31);
  ...
}
One thing I appreciated about Tailwind was that if I wanted to set a font
size, I could just think “hm, I want the text to be big”, write text-lg, and
be done with it! And maybe if it’s not big enough I’d use xl or 2xl instead.
No trying to remember whether I’m using em or px or rem.
So I defined a bunch of variables, taken from Tailwind, like this:
  --size-xs: 0.75rem;
  --line-height-xs: 1rem;

  --size-sm: 0.875rem;
  --line-height-sm: 1.25rem;
Then if I want to set a font size, I can do it like this. It’s a little more verbose than Tailwind but I’m happy with it for now.
h3 {
  font-size: var(--size-lg);
  line-height: var(--line-height-lg);
}
There are some things like buttons that appear in many different components. I’m calling these “utilities”.
I copied some utility classes from Tailwind (like .sr-only for things that
should only appear for screenreader users).
This section is pretty small and I try to be careful about making changes here.
“base” styles are styles that apply across the whole site that I chose myself. I
have to keep this section really small because I’m not confident enough to
enforce a lot of styles across the whole site. These are the only two I feel
okay about right now, and I might change the <section> one:
/* put a 950px column in the middle of each <section> */
section {
  --inner-width: 950px;
  padding: 3rem max(1rem, (100% - var(--inner-width))/2);
}

a {
  color: var(--orange);
}
I think for the base styles it’s going to be easiest for me to work kind of bottom up – first start with almost nothing in the base styles, and then move some styles from the components into base styles as I identify common things I want.
I haven’t completely worked out an approach to managing padding and margins yet. I’m definitely trying to be more principled than how I was doing it in Tailwind though, where I would just haphazardly put padding and margins everywhere until it looked the way I wanted.
Right now I’m working towards making the outer layout components in charge of
spacing as much as possible. For example if I have a <section> with a bunch of
children that I want to have space between them, I might use this to space the
children evenly:
section > *+* {
  margin-top: 1rem;
}
Some inspiration blog posts:
The way I was doing responsive design in Tailwind was to use a lot of media
queries. Tailwind has this md:text-xl syntax that means “apply the text-xl
style at sizes md or larger”.
I’m trying something pretty different now, which is to make more flexible CSS grid layouts that don’t need as many breakpoints. This is hard but it’s really interesting to learn about what’s possible with grid, and it’s a good example of something that I don’t think is possible with Tailwind.
For example, I’ve been learning about how to use auto-fit to automatically use
2 columns on a big screen and 1 column on a small screen like this:
  display: grid;
  grid-template-columns: repeat(auto-fit, minmax(min(100%, 400px), max-content));
  justify-content: center;
I also used grid-template-areas a lot which is an amazing feature that I don’t think you can use with Tailwind.
Some inspiration:
In development, I don’t need a build system: CSS now has both built in import statements, like this:
@import "reset.css";
@import "typography.css";
@import "colors.css";
and built in nested selectors, like this:
.page {
  h2 { ...}
}
If I want, I can use esbuild to bundle the CSS file for production. That looks something like this.
esbuild style.css --bundle --loader:.svg=dataurl --loader:.woff2=file --outfile=/tmp/out.css
Even though I usually avoid using CSS and JS build systems, I don’t mind using esbuild (which I wrote about in 2021 here) because it’s based on web standards and because it’s a static Go binary.
A few people asked why I was migrating away from Tailwind. A few factors that contributed are:
tailwind.min.css
files (270K gzipped) in a lot of my projects and it feels a little silly.While doing this I learned about a lot of CSS features that I didn’t use but am curious about learning about one day:
@layer (from A Whole Cascade of Layers)I’ve been talking a lot in this post about what I learned from using Tailwind, and that’s all true.
But I read this post 3 years ago called Tailwind and the Femininity of CSS that really stuck with me. I honestly probably started out with an attitude towards CSS a little like that post describes:
They’ve heard it’s simple, so they assume it’s easy. But then when they try to use it, it doesn’t work. It must be the fault of the language, because they know that they are smart, and this is supposed to be easy.
But in the last 10 years I’ve learned to really love and respect CSS as a technology.
So I decided years ago that I wanted to react to “CSS is hard” by getting better at CSS and taking it seriously as a technology, instead of devaluing it. Doing that changed everything for me: I learned that so many of my frustrations (“centering is impossible”) had been addressed in CSS a long time ago, and that also what “centering” means is not always straightforward and it makes sense that there are many ways to do it. CSS is hard because it’s solving a hard problem!
I’ve been so impressed by the new CSS features that have been built in the last 10-15 years (some of which I’ve talked about in this post!) and how they make it easier to use CSS, and spending the time to improve my CSS skills has been a really cool experience.
And that post made me feel like Tailwind contributes to the devaluing of CSS expertise, and like that’s not something I want to be a part of, even if Tailwind has been a useful tool for me personally. Especially in this time of LLMs where it feels more important than ever to value humans’ expertise.
Another blog post criticizing Tailwind that influenced me:
Thanks to Melody Starling who originally designed and wrote the CSS for wizardzines.com, everything cool and fun about the site is thanks to Melody.
Also I read so many incredible blog posts about CSS while working on this (from CSS Tricks, Smashing Magazine, and more), I’ve tried to link some of them throughout this post and I really appreciate how much folks in the CSS community share their practices.
A while back I decided to stop using Tailwind for new projects and to just write vanilla CSS instead.
But one thing I missed about Tailwind was the colour palette (here as CSS).
If I wanted a light blue I could just use blue-100 and if I didn’t like it
maybe try blue-200 or blue-50. I’m not very good with colours so it makes
a big difference to me to have a reasonable colour palette that somebody who is
better at colour than me has thought about.
But I’m also a little tired of those Tailwind colours, so I asked on Mastodon today what other colour palettes were out there. And then a friend said they wanted links to those colour palettes, so here’s a blog post so my friend can see them, and all the rest of you too :)
The ones I liked the most were:
Folks also linked to a bunch of colour palette generators
I’ve always found these types of generators too hard to use but maybe one day I will get better enough at colour that I’m able to use a colour palette generator successfully so I’ll leave those links there anyway.
and more colour tools:
oklchGenerative colors with CSS gives an example of
how to use the oklch CSS function to dynamically generate colors.
Hello! One of my long term projects on here is figuring out how to write frontend Javascript without using Node or any other server JS runtime.
One issue I run into a lot in my frontend JS projects is that I don’t know how to write tests for them. I’ve tried to use Playwright in the past, but it felt slow and unwieldy to be starting these new browser processes all the time, and it involved some Node code to orchestrate the tests.
The result is that I just don’t test my frontend code which doesn’t feel great. Usually I don’t update my projects much either so it doesn’t come up that much, but it would be nice to be able to make changes with more confidence! So a way to do frontend testing that I like has been on my wishlist for a long time.
Alex Chan wrote a great post a while back called Testing JavaScript without a (third-party) framework in response to one of my previous posts in this series that explained how to write a tiny unit-testing framework that runs in a page in browser.
I loved this post at the time, but it only talked about unit testing and I wanted to write end-to-end integration tests for my Vue components, and I didn’t know how to do that.
So when I was talking to Marco the other day and he said something like “you know, you can just run tests for your Vue components in the browser”, I thought “hey, I should try that again!!!”
I just did all of this yesterday so certainly there’s a lot to improve but I wanted to write down a few things I noticed about the process before I forget.
This was a bit tricky for me because the Vue site usually assumes that you’re
using Node as part of your build process in some way (there’s a lot of “step 1:
npm install THING), and I didn’t want to use Node/Deno/etc. But it turned
out to not be too complicated.
The project I’m going to talk about testing is this zine feedback site I wrote in 2023.
I used QUnit. It worked great but I don’t have anything interesting to say about how it works so I’ll leave it at that. I think that Alex’s “write your own test framework” approach would have worked too. I followed these directions.
I did appreciate that QUnit has a “rerun test” button that will only rerun 1 test. Because there are so many network requests in my tests, having a way to run just 1 test makes it a lot less confusing to debug the test.
The first thing I needed to do was get my Vue components set up in the test environment.
I changed my main app to put all my components in window._components,
kind of like this:
const components = {
  'Feedback': FeedbackComponent,
  ...
}
window._components = components;
Then I was able to write a mountComponent function which
does basically exactly the same thing my normal main app does
(render a tiny template with the component I want to use).
The only differences are:
position: absolute; top: -10000, ...) so you can’t see it.Here’s what using the mountComponent function looks like:
const {div} = mountComponent(
  '<Page :feedbacks="feedbacks" id=2 />',
  {feedbacks: [testFeedback]},
);
and here’s the code for it:
function mountComponent(template, data) {
  const app = Vue.createApp({
    template: template,
    data: () => data,
  })
  for (const [c, v] of Object.entries(window._components)) {
    app.component(c, v);
  }
  const div = document.getElementById('qunit-fixture')
             .appendChild(document.createElement('div'));
  return div;
}
The result is a div where I can programmatically click, fill in form data, check that the right content appears, etc.
Because I was writing end-to-end integration tests to make sure my client JS worked properly with my server, I needed to have some test data in my database. So I wrote ~25 lines of SQL to set up some test data in my database, and added an endpoint to my dev server to run the SQL to reset the test data to a known state.
async function reset() {
    return fetch('/api/reset_test_data', {method: "POST"})
}
Then I just run await reset() at the beginning of any test that needs the
test data.
My reset() function actually doesn’t always totally reset everything which is
kind of bad, but it was workable to start with and can always be improved.
Here’s what a basic test looks like! Basically we’re rendering the div and make sure it contains some approximately correct data.
QUnit.test('renders feedback content', async function (assert) {
  const {div} = mountComponent(
    '<Page :feedbacks="feedbacks" id=2 image=2 page_hash=2 />',
    {feedbacks: [testFeedback]},
  );
  assert.ok(div.textContent.includes('loved this section'));
})
Those are all the basic pieces! Now here are a few issues I ran into along the way
I have a lot of network requests in my tests, and it takes time for them to finish and for the Vue code to do what it has to do with the results and update the DOM.
I think we all learned a long time ago that putting random sleep() calls in
your tests and hoping that the timings are right is slow and flaky and extremely
frustrating, so I needed a different way.
As far as I can tell the normal way to deal with this is to figure out a way to tell from the DOM whether it’s okay to proceed or not. Like “if this button is visible, we can “.
So I wrote a little waitFor() function that polls every 20ms to see if a
condition has finished yet. It times out after 2 seconds.
Here’s what using it looks like:
QUnit.test("click item", async function (assert) {
  const {div} = mountComponent(
    '<Feedback zine_id="test123" image_width="800px" />',
    {});
  const item = await waitFor(() => div.querySelector('.feedback-item'));
  item.click();
  // rest of test goes here...
})
It looks like there are a lot of implementations of this concept out there and they’re all better thought-through than mine. (from a quick Google: qunit-wait-for, playwright expect.poll)
In some cases I thought I’d identified the right thing to wait for in the DOM (“just wait for this textarea to appear!’) but it turned out that because of some internal details of how my program works, actually I needed to wait for something else later on which was hard to pin down.
I ended up changing one of my components to add some random value to the DOM
when it was finished an important action (like data-this-thing-is-ready=true)
which didn’t feel great.
My best guess is that the right way to fix this kind of test issue is a refactor that also makes the app more reliable for the users: if there’s an element in the DOM that isn’t actually ready for the user to interact with, maybe I shouldn’t be displaying it yet!
I ended up adding a few classes to HTML elements that I needed to find in the tests, either because I needed to click on them or wait for them to appear in the DOM.
I might want to change this approach later - frontend testing frameworks seem to suggest avoiding using CSS classes and instead using something like getByRole or as a last resort something like a data-testid. Feels like there’s a way to make the app more accessible and easier to test at the same time.
To fill out a form, I can’t just set the value, I also need to dispatch an
event to tell Vue that the element has changed. For example, checkbox and
textarea need different kinds of events.
textarea.value = 'banana banana banana';
textarea.dispatchEvent(new Event('input'));
checkbox.checked = true;
checkbox.dispatchEvent(new Event('change'));
This is kind of annoying and it made me realize why I might want to use some kind of UI testing library, for example:
I want to have an idea of what my test coverage was, and it turns out that Chrome actually has a built-in code coverage feature for JS and CSS!
My JS is bundled into a file called bundle.js with esbuild, so I could just
look at bundle.js and see which lines weren’t covered.
The process was a little finicky: I had to turn off sourcemaps in the Chrome devtools to get this to work, and there’s a specific not super obvious series of actions I have to do in order to see the coverage data.
As usual with these posts I’ve never really worked as a frontend or backend developer (other than for myself!) and I feel like I’m constantly learning how to do super basic tasks.
I really had a blast doing this. My frontend projects always feel so fragile because they’re untested, and maybe one day I’ll have a test suite I’m confident in!
Some things I’m still thinking about:
.umd.js file
that works without Node.Hello! My big takeaway from last month’s musings about man pages was that examples in man pages are really great, so I worked on adding (or improving) examples to two of my favourite tools’ man pages.
Here they are:
The goal here was really just to give the absolute most basic examples of how to use the tool, for people who use tcpdump or dig infrequently (or have never used it before!) and don’t remember how it works.
So far saying “hey, I want to write an examples section for beginners and infrequent users of this tools” has been working really well. It’s easy to explain, I think it makes sense from everything I’ve heard from users about what they want from a man page, and maintainers seem to find it compelling.
Thanks to Denis Ovsienko, Guy Harris, Ondřej Surý, and everyone else who reviewed the docs changes, it was a good experience and left me motivated to do a little more work on man pages.
I’m interested in working on tools’ official documentation right now because:
tcpdump -w out.pcap, it’s useful to pass -v to print
a live summary of how many packets have been captured so far. That’s really
useful, I didn’t know it, and I don’t think I ever would have noticed it on
my own.It’s kind of a weird place for me to be because honestly I always kind of assume documentation is going to be hard to read, and I usually just skip it and read a blog post or Stack Overflow comment or ask a friend instead. But right now I’m feeling optimistic, like maybe the documentation doesn’t have to be bad? Maybe it could be just as good as reading a really great blog post, but with the benefit of also being actually correct? I’ve been using the Django documentation recently, and it’s really good! We’ll see.
The tcpdump project tool’s man page is
written in the roff language,
which is kind of hard to use and that I really did not feel like learning it.
I handled this by writing a very basic markdown-to-roff script to convert Markdown to roff, using similar conventions to what the man page was already using. I could maybe have just used pandoc, but the output pandoc produced seemed pretty different, so I thought it might be better to write my own script instead. Who knows.
I did think it was cool to be able to just use an existing Markdown library’s ability to parse the Markdown AST and then implement my own code-emitting methods to format things in a way that seemed to make sense in this context.
I went on a whole rabbit hole learning about the history of roff, how it’s
evolved since the 70s, and who’s working on it today, inspired by learning about
the mandoc project that BSD systems (and some Linux
systems, and I think Mac OS) use for formatting man pages. I won’t say more
about that today though, maybe another time.
In general it seems like there’s a technical and cultural divide in how documentation works on BSD and on Linux that I still haven’t really understood, but I have been feeling curious about what’s going on in the BSD world.
Hello! After spending some time working on the Git man pages last year, I’ve been thinking a little more about what makes a good man page.
I’ve spent a lot of time writing cheat sheets for tools (tcpdump, git, dig, etc) which have a man page as their primary documentation. This is because I often find the man pages hard to navigate to get the information I want.
Lately I’ve wondering – could the man page itself have an amazing cheat sheet in it? What might make a man page easier to use? I’m still very early in thinking about this but I wanted to write down some quick notes.
I asked some people on Mastodon for their favourite man pages, and here are some examples of interesting things I saw on those man pages.
If you’ve read a lot of man pages you’ve probably seen something like this in
the SYNOPSIS: once you’re listing almost the entire alphabet, it’s hard
ls [-@ABCFGHILOPRSTUWabcdefghiklmnopqrstuvwxy1%,]

grep [-abcdDEFGHhIiJLlMmnOopqRSsUVvwXxZz]
The rsync man page has a solution I’ve never seen before: it keeps its SYNOPSIS very terse, like this:
 Local:
     rsync [OPTION...] SRC... [DEST]
and then has an “OPTIONS SUMMARY” section with a 1-line summary of each option, like this:
--verbose, -v            increase verbosity
--info=FLAGS             fine-grained informational verbosity
--debug=FLAGS            fine-grained debug verbosity
--stderr=e|a|c           change stderr output mode (default: errors)
--quiet, -q              suppress non-error messages
--no-motd                suppress daemon-mode MOTD
Then later there’s the usual OPTIONS section with a full description of each option.
The strace man page organizes its options by category (like “General”, “Startup”, “Tracing”, and “Filtering”, “Output Format”) instead of alphabetically.
As an experiment I tried to take the grep man page and make an
“OPTIONS SUMMARY” section grouped by category, you can see the results
here. I’m not
sure what I think of the results but it was a fun exercise. When I was writing
that I was thinking about how I can never remember the name of the -l grep
option. It always takes me what feels like forever to find it in the man page
and I was trying to think of what structure would make it easier for me to find.
Maybe categories?
A couple of people pointed me to the suite of Perl man pages (perlfunc, perlre, etc), and one thing I
noticed was man perlcheat, which has
cheat sheet sections like this:
 SYNTAX
 foreach (LIST) { }     for (a;b;c) { }
 while   (e) { }        until (e)   { }
 if      (e) { } elsif (e) { } else { }
 unless  (e) { } elsif (e) { } else { }
 given   (e) { when (e) {} default {} }
I think this is so cool and it makes me wonder if there are other ways to write condensed ASCII 80-character-wide cheat sheets for use in man pages.
A common comment was something to the effect of “I like any man page that has examples”. Someone mentioned the OpenBSD man pages, and the openbsd tail man page has examples of the exact 2 ways I use tail at the end.
I think I’ve most often seen the EXAMPLES section at the end of the man page, but some man pages (like the rsync man page from earlier) start with the examples. When I was working on the git-add and git rebase man pages I put a short example at the beginning.
This isn’t a property of the man page itself, but one issue with man pages in the terminal is it’s hard to know what sections the man page has.
When working on the Git man pages, one thing Marie and I did was to add a table of contents to the sidebar of the HTML versions of the man pages hosted on the Git site.
I’d also like to add more hyperlinks to the HTML versions of the Git man pages at some point, so that you can click on “INCOMPATIBLE OPTIONS” to get to that section. It’s very easy to add links like this in the Git project since Git’s man pages are generated with AsciiDoc.
I think adding a table of contents and adding internal hyperlinks is kind of a nice middle ground where we can make some improvements to the man page format (in the HTML version of the man page at least) without maintaining a totally different form of documentation. Though for this to work you do need to set up a toolchain like Git’s AsciiDoc system.
It would be amazing if there were some kind of universal system to make it easy
to look up a specific option in a man page (“what does -a do?”).
The best trick I know is use the man pager to search for something like ^ *-a
but I never remember to do it and instead just end up going through
every instance of -a in the man page until I find what I’m looking for.
The curl man page has examples for every option, and there’s also a table of contents on the HTML version so you can more easily jump to the option you’re interested in.
For instance the example for --cert makes it easy to see that you likely also want to pass the --key option, like this:
curl --cert certfile --key keyfile https://example.com
The way they implement this is that there’s [one file for each option](https://github.com/curl/curl/blob/dc08922a61efe546b318daf964514ffbf41583 25/docs/cmdline-opts/append.md) and there’s an “Example” field in that file.
Quite a few people said that man ascii was their favourite man page, which looks like this:
 Oct   Dec   Hex   Char
 ───────────────────────────────────────────
 000   0     00    NUL '\0' (null character)
 001   1     01    SOH (start of heading)
 002   2     02    STX (start of text)
 003   3     03    ETX (end of text)
 004   4     04    EOT (end of transmission)
 005   5     05    ENQ (enquiry)
 006   6     06    ACK (acknowledge)
 007   7     07    BEL '\a' (bell)
 010   8     08    BS  '\b' (backspace)
 011   9     09    HT  '\t' (horizontal tab)
 012   10    0A    LF  '\n' (new line)
Obviously man ascii is an unusual man page but I think what’s cool about this man page (other than the fact that it’s always
useful to have an ASCII reference) is it’s very easy to scan to find the
information you need because of the table format. It makes me wonder if there
are more opportunities to display information in a “table” in a man page to make
it easier to scan.
When I talk about man pages it often comes up that the GNU coreutils man pages (for example man tail) don’t have examples, unlike the OpenBSD man pages, which do have examples.
I’m not going to get into this too much because it seems like a fairly political topic and I definitely can’t do it justice here, but here are some things I believe to be true:
info tool. I’ve heard from some Emacs users that they like the Emacs info browser. I don’t think I’ve ever talked to anyone who uses the standalone info tool.After a certain level of complexity a man page gets really hard to navigate: while I’ve never used the coreutils info manual and probably won’t, I would almost certainly prefer to use the GNU Bash reference manual or the The GNU C Library Reference Manual via their HTML documentation rather than through a man page.
Here are some tools I think are interesting:
tldr grep. Lots of people have told me they find it useful.
Man pages are such a constrained format and it’s fun to think about what you can do with such limited formatting options.
Even though I’m very into writing I’ve always had a bad habit of never reading documentation and so it’s a little bit hard for me to think about what I actually find useful in man pages, I’m not sure whether I think most of the things in this post would improve my experience or not. (Except for examples, I LOVE examples)
So I’d be interested to hear about other man pages that you think are well designed and what you like about them, the comments section is here.
Hello! One of my favourite things is starting to learn an Old Boring Technology that I’ve never tried before but that has been around for 20+ years. It feels really good when every problem I’m ever going to have has been solved already 1000 times and I can just get stuff done easily.
I’ve thought it would be cool to learn a popular web framework like Rails or Django or Laravel for a long time, but I’d never really managed to make it happen. But I started learning Django to make a website a few months back, I’ve been liking it so far, and here are a few quick notes!
I spent some time trying to learn Rails in 2020,
and while it was cool and I really wanted to like Rails (the Ruby community is great!),
I found that if I left my Rails project alone for months, when I came
back to it it was hard for me to remember how to get anything done because
(for example) if it says resources :topics in your routes.rb, on its own
that doesn’t tell you where the topics routes are configured, you need to
remember or look up the convention.
Being able to abandon a project for months or years and then come back to it is really important to me (that’s how all my projects work!), and Django feels easier to me because things are more explicit.
In my small Django project it feels like I just have 5 main files (other
than the settings files): urls.py, models.py, views.py, admin.py, and
tests.py, and if I want to know where something else is (like an HTML template)
is then it’s usually explicitly referenced from one of those files.
For this project I wanted to have an admin interface to manually edit or view some of the data in the database. Django has a really nice built-in admin interface, and I can customize it with just a little bit of code.
For example, here’s part of one of my admin classes, which sets up which fields to display in the “list” view, which field to search on, and how to order them by default.
@admin.register(Zine)
class ZineAdmin(admin.ModelAdmin):
    list_display = ["name", "publication_date", "free", "slug", "image_preview"]
    search_fields = ["name", "slug"]
    readonly_fields = ["image_preview"]
    ordering = ["-publication_date"]
In the past my attitude has been “ORMs? Who needs them? I can just write my own SQL queries!”.
I’ve been enjoying Django’s ORM so far though, and I think it’s cool how Django
uses __ to represent a JOIN, like this:
Zine.objects
    .exclude(product__order__email_hash=email_hash)
This query involves 5 tables: zines, zine_products, products, order_products, and orders.
To make this work I just had to tell Django that there’s a ManyToManyField
relating “orders” and “products”, and another ManyToManyField relating
“zines”, and “products”, so that it knows how to connect zines, orders, products.
I definitely could write that query, but writing product__order__email_hash is
a lot less typing, it feels a lot easier to read, and honestly I think it would
take me a little while to figure out how to construct the query
(which needs to do a few other things than just those joins).
I have zero concern about the performance of my ORM-generated queries so I’m pretty excited about ORMs for now, though I’m sure I’ll find things to be frustrated with eventually.
The other great thing about the ORM is migrations!
If I add, delete, or change a field in models.py, Django will automatically
generate a migration script like migrations/0006_delete_imageblob.py.
I assume that I could edit those scripts if I wanted, but so far I’ve just been running the generated scripts with no change and it’s been going great. It really feels like magic.
I’m realizing that being able to do migrations easily is important for me right now because I’m changing my data model fairly often as I figure out how I want it to work.
I had a bad habit of never reading the documentation but I’ve been really enjoying the parts of Django’s docs that I’ve read so far. This isn’t by accident: Jacob Kaplan-Moss has a talk from PyCon 2011 on Django’s documentation culture.
For example the intro to models lists the most important common fields you might want to set when using the ORM.
After having a bad experience trying to operate Postgres and not being able to
understand what was going on, I decided to run all of my small websites with
SQLite instead. It’s been going way better, and I love being able to backup by
just doing a VACUUM INTO and then copying the resulting single file.
I’ve been following these instructions for using SQLite with Django in production.
I think it should be fine because I’m expecting the site to have a few hundred writes per day at most, much less than Mess with DNS which has a lot more of writes and has been working well (though the writes are split across 3 different SQLite databases).
Django seems to be very “batteries-included”, which I love – if I want CSRF
protection, or a Content-Security-Policy, or I want to send email, it’s all
in there!
For example, I wanted to save the emails Django sends to a file in dev mode (so that it didn’t send real email to real people), which was just a little bit of configuration.
I just put this settings/dev.py:
EMAIL_BACKEND = "django.core.mail.backends.filebased.EmailBackend"
EMAIL_FILE_PATH = BASE_DIR / "emails"
and then set up the production email like this in settings/production.py
EMAIL_BACKEND = "django.core.mail.backends.smtp.EmailBackend"
EMAIL_HOST = "smtp.whatever.com"
EMAIL_PORT = 587
EMAIL_USE_TLS = True
EMAIL_HOST_USER = "xxxx"
EMAIL_HOST_PASSWORD = os.getenv('EMAIL_API_KEY')
That made me feel like if I want some other basic website feature, there’s likely to be an easy way to do it built into Django already.
I’m still a bit intimidated by the settings.py file: Django’s settings system
works by setting a bunch of global variables in a file, and I feel a bit
stressed about… what if I make a typo in the name of one of those variables?
How will I know? What if I type WSGI_APPLICATOIN = "config.wsgi.application"
instead of WSGI_APPLICATION?
I guess I’ve gotten used to having a Python language server tell me when I’ve made a typo and so now it feels a bit disorienting when I can’t rely on the language server support.
I haven’t really successfully used an actual web framework for a project before (right now almost all of my websites are either a single Go binary or static sites), so I’m interested in seeing how it goes!
There’s still lots for me to learn about, I still haven’t really gotten into Django’s form validation tooling or authentication systems.
Thanks to Marco Rogers for convincing me to give ORMs a chance.
(we’re still experimenting with the comments-on-Mastodon system! Here are the comments on Mastodon! tell me your favourite Django feature!)
Hello! This past fall, I decided to take some time to work on Git’s documentation. I’ve been thinking about working on open source docs for a long time – usually if I think the documentation for something could be improved, I’ll write a blog post or a zine or something. But this time I wondered: could I instead make a few improvements to the official documentation?
So Marie and I made a few changes to the Git documentation!
After a while working on the documentation, we noticed that Git uses the terms “object”, “reference”, or “index” in its documentation a lot, but that it didn’t have a great explanation of what those terms mean or how they relate to other core concepts like “commit” and “branch”. So we wrote a new “data model” document!
You can read the data model here for now. I assume at some point (after the next release?) it’ll also be on the Git website.
I’m excited about this because understanding how Git organizes its commit and branch data has really helped me reason about how Git works over the years, and I think it’s important to have a short (1600 words!) version of the data model that’s accurate.
The “accurate” part turned out to not be that easy: I knew the basics of how Git’s data model worked, but during the review process I learned some new details and had to make quite a few changes (for example how merge conflicts are stored in the staging area).
git push, git pull, and moreI also worked on updating the introduction to some of Git’s core man pages. I quickly realized that “just try to improve it according to my best judgement” was not going to work: why should the maintainers believe me that my version is better?
I’ve seen a problem a lot when discussing open source documentation changes where 2 expert users of the software argue about whether an explanation is clear or not (“I think X would be a good way to explain it! Well, I think Y would be better!”)
I don’t think this is very productive (expert users of a piece of software are notoriously bad at being able to tell if an explanation will be clear to non-experts), so I needed to find a way to identify problems with the man pages that was a little more evidence-based.
I asked for test readers on Mastodon to read the current version of documentation and tell me what they find confusing or what questions they have. About 80 test readers left comments, and I learned so much!
People left a huge amount of great feedback, for example:
Most of the test readers had been using Git for at least 5-10 years, which I think worked well – if a group of test readers who have been using Git regularly for 5+ years find a sentence or term impossible to understand, it makes it easy to argue that the documentation should be updated to make it clearer.
I thought this “get users of the software to comment on the existing documentation and then fix the problems they find” pattern worked really well and I’m excited about potentially trying it again in the future.
We ended updating these 4 man pages:
git add (before, after)git checkout (before, after)git push (before, after)git pull (before, after)The git push and git pull changes were the most interesting to me: in
addition to updating the intro to those pages, we also ended up writing:
Making those changes really gave me an appreciation for how much work it is
to maintain open source documentation: it’s not easy to write things that are
both clear and true, and sometimes we had to make compromises, for example the sentence
“git push may fail if you haven’t set an upstream for the current branch,
depending on what push.default is set to.” is a little vague, but the exact
details of what “depending” means are really complicated and untangling that is
a big project.
It took me a while to understand Git’s development process. I’m not going to try to describe it here (that could be a whole other post!), but a few quick notes:
I also found the mailing list archives on lore.kernel.org hard to navigate, so I hacked together my own git list viewer to make it easier to read the long mailing list threads.
Many people helped me navigate the contribution process and review the changes: thanks to Emily Shaffer, Johannes Schindelin (the author of GitGitGadget), Patrick Steinhardt, Ben Knoble, Junio Hamano, and more.
(I’m experimenting with comments on Mastodon, you can see the comments here)
The new MCP authorization spec is here! Today marks the one-year anniversary of the Model Context Protocol, and with it, the launch of the new 2025-11-25 specification.
I’ve been helping out with the authorization part of the spec for the last several months, working to make sure we aren't just shipping something that works for hobbyists, but something that even scales to the enterprise. If you’ve been following my posts like Enterprise-Ready MCP or Let's Fix OAuth in MCP, you know this has been a bit of a journey over the past year.
The new spec just dropped, and while there are a ton of great updates across the board, far more than I can get in to in this blog post, there are two changes in the authorization layer that I am most excited about. They fundamentally change how clients identify themselves and how enterprises manage access to AI-enabled apps.
If you’ve ever tried to work with an open ecosystem of OAuth clients and servers, you know the "Client Registration" problem. In traditional OAuth, you go to a developer portal, register your app, and get a client_id and client_secret. That works great when there is one central server (like Google or GitHub) and many clients that want to use that server.
It breaks down completely in an open ecosystem like MCP, where we have many clients talking to many servers. You can't expect a developer of a new AI Agent to manually register with every single one of the 2,000 MCP servers in the MCP server registry. Plus, when a new MCP server launches, that server wouldn't be able to ask every client developer to register either.
Until now, the answer for MCP was Dynamic Client Registration (DCR). But as implementation experiences has shown us over the last several months, DCR introduces a massive amount of complexity and risk for both sides.
For Authorization Servers, DCR endpoints are a headache. They require public-facing APIs that need strict rate limiting to prevent abuse, and they lead to unbounded database growth as thousands of random clients register themselves. The number of client registrations will only ever increase, so the authorization server is likely to implement some sort of "cleanup" mechanism to delete old client registrations. The problem is there is no clear definition of what an "old" client is. And if a dynamically registered client is deleted, the client doesn't know about it, and the user is often stuck with no way to recover. Because of the security implications of an endpoint like this, DCR has also been a massive barrier to enterprise adoption of MCP.
For Clients, it’s just as bad. They have to manage the lifecycle of their client credentials on top of the actual access tokens, and there is no standardized way to check if the client registration is still valid. This frequently leads to sloppy implementations where clients simply register a brand new client_id every single time a user logs in, further increasing the number of client registrations at the authorization server. This isn't a theoretical problem, this is also how Mastodon has worked for the last several years, and has some GitHub issue threads describing the challenges it creates.
The new MCP spec solves this by adopting Client ID Metadata Documents.
The OAuth Working Group adopted the Client ID Metadata Document spec in October after about a year of discussion, so it's still relatively new. But seeing it land as the default mechanism in MCP is huge. Instead of the client registering with each authorization server, the client establishes its own identity with a URL it controls and uses the URL to identify itself during an OAuth flow.
When the client starts an OAuth request to the MCP authorization server, it says, "Hi, I'm https://example-app.com/client.json." The server fetches the JSON document at that URL and finds the client's metadata (logo, name, redirect URIs) and proceeds on as usual.
This creates a decentralized trust model based on DNS. If you trust example.com, you trust the client. It removes the registration friction entirely while keeping the security guarantees we need. It’s the same pattern we’ve used in IndieAuth for over a decade, and it fits MCP perfectly.
There are definitely some new considerations and risks this brings, so it's worth diving into the details about Client ID Metadata Documents in the MCP spec as well as the IETF spec. For example, if you're building an MCP client that is running on a web server, you can actually manage private keys and publish the public keys in your metadata document, enabling strong client authentication. And like Dynamic Client Registration, there are still limitations for how desktop clients can leverage this, which can hopefully be solved by a future extension. I talked more about this during a hugely popular session at the Internet Identity Workshop in October, you can find the slides here.
You can try out this new flow today in VSCode, the first MCP client to ship support for CIMD even before it was officially in the spec. You can also learn more and test it out at the excellent website the folks at Stytch created: client.dev.
This is the big one for anyone asking, "Is MCP safe to use in the enterprise?"
Until now, when an AI agent connected to an MCP server, the connection was established directly between the MCP client and server. For example if you are using ChatGPT to connect to the Asana MCP server, ChatGPT would start an OAuth flow to Asana. But if your Asana account is actually connected to an enterprise IdP like Okta, Okta would only see that you're logging in to Asana, and wouldn't be aware of the connection established between ChatGPT and Asana. This means today there are a huge number of what are effectively unmanaged connections between MCP clients and servers in the enterprise. Enterprise IT admins hate this because it creates "Shadow IT" connections that bypass enterprise policy.
The new MCP spec incorporates Cross App Access (XAA) as the authorization extension "Enterprise-Managed Authorization".
This builds on the work I discussed in Enterprise-Ready MCP leveraging the Identity Assertion Authorization Grant. The flow puts the enterprise Identity Provider (IdP) back in the driver's seat.
Here is how it works:
Single Sign-On: First you log into an MCP Client (like Claude or an IDE) using your corporate SSO, the client gets an ID token.
Token Exchange: Instead of the client starting an OAuth flow to ask the user to manually approve access to a downstream tool (like an Asana MCP server), the client takes that ID token back to the Enterprise IdP to ask for access.
Policy Check: The IdP checks corporate policy. "Is Engineering allowed to use Claude to access Asana?" If the policy passes, the IdP issues a temporary token (ID-JAG) that the client can take to the MCP authorization server.
Access Token Request: The MCP client takes the ID-JAG to the MCP authorization server saying "hey this IdP says you can issue me an access token for this user". The authorization server validates the ID-JAG the same way it would have validated an ID Token (remember this app is also set up for SSO to the same corporate IdP), and issues an access token.
This happens entirely behind the scenes without user interaction. The user doesn't get bombarded with consent screens, and the enterprise admin gets full visibility and revocability. If you want to shut down AI access to a specific internal tool, you do it in one place: your IdP.
There is a lot more in the full spec update, but these two pieces—CIMD for scalable client identity and Cross App Access for enterprise security—are the two I am most excited about. They take MCP to the next level by solving the biggest challenges that were preventing scalable adoption of MCP in the enterprise.
You can read more about the MCP authorization spec update in Den's excellent post, and more about all the updates to the MCP spec in the official announcement post.
Links to docs and specs about everything mentioned in this post are below.
In October, I launched an instance of Meetable for the MCP Community. They've been using it to post working group meetings as well as in-person community events. In just 2 months it already has 41 events listed!
One of the aspects of opening up the software to a new community is stress testing some of the design decisions. An early design decision was intentionally to not support recurring events. For a community calendar, recurring events are often problematic. Once a recurring event is created for something like a weekly meetup, it's no longer clear whether the event is actually going to happen, which is especially true for virtual events. If an organizer of the event silently drops away from the community, it's very likely they will not go delete the event, and you can end up with stale events on the calendar quickly. It's better to have people explicitly create the event on the calendar so that every event was created with intention. To support this, I made a "Clone Event" button to quickly copy the details from a previous instance, and it even predicts the next date based on how often the event has been happening in the past.
But for the MCP community, which is a bit more formal than a purely community calendar, most of the events on their site are weekly or biweekly working group meetings. I had been hearing quite a bit of feedback that the current process of scheduling out the events manually, even with the "clone event" feature, was too much of a burden. So I set out to design a solution for recurring events to strike a balance between ease of use and hopefully avoiding some of the pitfalls of recurring events.
What I landed on is this:
You can create an "event template" from any existing event on the calendar, and give it a recurrence interval like "Every week on Tuesdays" or "Monthly on the 9th".
(I'll add an option for "Monthly on the second Tuesday" later if this ends up being used enough.)
Once the schedule is created, copies of the event will be created at the chosen interval, but only a few weeks out. For weekly events, 4 weeks in advance will be created, biweekly will get scheduled 8 weeks out, monthly events 4 months out, and yearly events will have only the next year scheduled. Every day a cron job will create future events at the scheduled interval in advance. If the event template is deleted, future scheduled events will also be deleted.
So effectively for organizers there is nothing they need to do after creating the recurring event schedule. My hope is by having it work this way, instead of like recurring events on a typical Google calendar, it strikes a balance between ease of use but avoids orphaned events on the calendar. It still requires an organizer to delete a recurrence, so should only be used for events that truly have a schedule and are unlikely to be cancelled often.
Hopefully this makes Meetable even more useful for different kinds of communities! You can install your own copy of Meetable from the source code on GitHub.
Today I just launched support for BlueSky as a new authentication option in IndieLogin.com!
IndieLogin.com is a developer service that allows users to log in to a website with their domain. It delegates the actual user authentication out to various external services, whether that is an IndieAuth server, GitHub, GitLab, Codeberg, or just an email confirmation code, and now also BlueSky.
This means if you have a custom domain as your BlueSky handle, you can now use it to log in to websites like indieweb.org directly!
Alternatively, you can add a link to your BlueSky handle from your website with a rel="me atproto" attribute, similar to how you would link to your GitHub profile from your website.
<a href="https://example.bsky.social" rel="me atproto">example.bsky.social</a>
This is made possible thanks to BlueSky's support of the new OAuth Client ID Metadata Document specification, which was recently adopted by the OAuth Working Group. This means as the developer of the IndieLogin.com service, I didn't have to register for any BlueSky API keys in order to use the OAuth server! The IndieLogin.com website publishes its own metadata which the BlueSky OAuth server can use to fetch the metadata from. This is the same client metadata that an IndieAuth server will parse as well! Aren't standards fun!
The hardest part about the whole process was probably adding DPoP support. Actually creating the DPoP JWT wasn't that bad but the tricky part was handling the DPoP server nonces sent back. I do wish we had a better solution for that mechanism in DPoP, but I remember the reasoning for doing it this way and I guess we just have to live with it now.
This was a fun exercise in implementing a bunch of the specs I've been working on recently!
Here's the link to the full ATProto OAuth docs for reference.
Hello! Earlier this summer I was talking to a friend about how much I love using fish, and how I love that I don’t have to configure it. They said that they feel the same way about the helix text editor, and so I decided to give it a try.
I’ve been using it for 3 months now and here are a few notes.
I think what motivated me to try Helix is that I’ve been trying to get a working language server setup (so I can do things like “go to definition”) and getting a setup that feels good in Vim or Neovim just felt like too much work.
After using Vim/Neovim for 20 years, I’ve tried both “build my own custom configuration from scratch” and “use someone else’s pre-buld configuration system” and even though I love Vim I was excited about having things just work without having to work on my configuration at all.
Helix comes with built in language server support, and it feels nice to be able to do things like “rename this symbol” in any language.
One of my favourite things about Helix is the search! If I’m searching all the files in my repository for a string, it lets me scroll through the potential matching files and see the full context of the match, like this:
For comparison, here’s what the vim ripgrep plugin I’ve been using looks like:
There’s no context for what else is around that line.
One thing I like about Helix is that when I press g, I get a little help popup
telling me places I can go. I really appreciate this because I don’t often use
the “go to definition” or “go to reference” feature and I often forget the
keyboard shortcut.
ma, 'a, instead I’ve been using Ctrl+O and
Ctrl+I to go back (or forward) to the last cursor location% (to highlight everything), then s
to select (with a regex) the things I want to change, then I can just edit
all of them as needed.<space>b)
I can use to switch to the buffer I want. There’s a
pull request here to implement neovim-style tabs.
There’s also a setting bufferline="multiple" which can act a bit like tabs
with gp, gn for prev/next “tab” and :bc to close a “tab”.Here’s everything that’s annoyed me about Helix so far.
:reflow works much less than how
vim reflows text with gq. It doesn’t work as well with lists. (github issue):reload-all (:ra<tab>) to manually reload them. Not a big deal.The crashes look something like this:
thread 'main' panicked at helix-core/src/transaction.rs:499:9:
Positions [(2959, AfterSticky), (2959, AfterSticky)] are out of range for changeset len 2945!
note: run with `RUST_BACKTRACE=1` environment variable to display a backtrace
The “markdown list” and reflowing issues come up a lot for me because I spend a lot of time editing Markdown lists, but I keep using Helix anyway so I guess they can’t be making me that mad.
I was worried that relearning 20 years of Vim muscle memory would be really hard.
It turned out to be easier than I expected, I started using Helix on a vacation for a little low-stakes coding project I was doing on the side and after a week or two it didn’t feel so disorienting anymore. I think it might be hard to switch back and forth between Vim and Helix, but I haven’t needed to use Vim recently so I don’t know if that’ll ever become an issue for me.
The first time I tried Helix I tried to force it to use keybindings that were more similar to Vim and that did not work for me. Just learning the “Helix way” was a lot easier.
There are still some things that throw me off: for example w in vim and w in
Helix don’t have the same idea of what a “word” is (the Helix one includes the
space after the word, the Vim one doesn’t).
For many years I’d mostly been using a GUI version of vim/neovim, so switching to actually using an editor in the terminal was a bit of an adjustment.
I ended up deciding on:
It works pretty well, I might actually like it better than my previous workflow.
I appreciate that my configuration is really simple, compared to my neovim configuration which is hundreds of lines. It’s mostly just 4 keyboard shortcuts.
theme = "solarized_light"
[editor]
# Sync clipboard with system clipboard
default-yank-register = "+"

[keys.normal]
# I didn't like that Ctrl+C was the default "toggle comments" shortcut
"#" = "toggle_comments"

# I didn't feel like learning a different way
# to go to the beginning/end of a line so
# I remapped ^ and $
"^" = "goto_first_nonwhitespace"
"$" = "goto_line_end"

[keys.select]
"^" = "goto_first_nonwhitespace"
"$" = "goto_line_end"

[keys.normal.space]
# I write a lot of text so I need to constantly reflow,
# and missed vim's `gq` shortcut
l = ":reflow"
There’s a separate languages.toml configuration where I set some language
preferences, like turning off autoformatting.
For example, here’s my Python configuration:
[[language]]
name = "python"
formatter = { command = "black", args = ["--stdin-filename", "%{buffer_name}", "-"] }
language-servers = ["pyright"]
auto-format = false
Three months is not that long, and it’s possible that I’ll decide to go back to Vim at some point. For example, I wrote a post about switching to nix a while back but after maybe 8 months I switched back to Homebrew (though I’m still using NixOS to manage one little server, and I’m still satisfied with that).
The IETF OAuth Working Group has adopted the Client ID Metadata Document specification!
This specification defines a mechanism through which an OAuth client can identify itself to authorization servers, without prior dynamic client registration or other existing registration.
Clients identify themselves with their own URL, and host their metadata (name, logo, redirect URL) in a JSON document at that URL. They then use that URL as the client_id to introduce themselves to an authorization server for the first time.
The mechanism of clients identifying themselves as a URL has been in use in IndieAuth for over a decade, and more recently has been adopted by BlueSky for their OAuth API. The recent surge in interest in MCP has further demonstrated the need for this to be a standardized mechanism, and was the main driver in the latest round of discussion for the document! This could replace Dynamic Client Registration in MCP, dramatically simplifying management of clients, as well as enabling servers to limit access to specific clients if they want.
The folks at Stytch put together a really nice explainer website about it too! cimd.dev
Thanks to everyone for your contributions and feedback so far! And thanks to my co-author Emilia Smith for her work on the document!
I just released some updates for Meetable, my open source event listing website.
The major new feature is the ability to let users log in with a Discord account. A Meetable instance can be linked to a Discord server to enable any member of the server to log in to the site. You can also restrict who can log in based on Discord "roles", so you can limit who can edit events to only certain Discord members.
One of the first questions I get about Meetable is whether recurring events are supported. My answer has always been "no". In general, it's too easy for recurring events on community calendars go get stale. If an organizer forgets to cancel or just stops showing up, that isn't visible unless someone takes the time to clean up the recurrence. Instead, it's healthier to require each event be created manually. There is a "clone event" feature that makes it easy to copy all the details from a previous event to be able to quickly manually create these sorts of recurring events. In this update, I just added a feature to streamline this even further. The next recurrence is now predicted based on the past interval of the event.
For example, for a biweekly cadence, the following steps happen now:
Currently this only works by counting days, so wouldn't work for things like "first Tuesday of the month" or "the 1st of the month", but I hope this saves some time in the future regardless. If "first Tuesday" or specific days of the month are an important use case for you, let me know and I can try to come up with a solution.
Minor changes/fixes below:
Every time I take a Lyft from the San Francisco airport to downtown going up 101, I notice the billboards. The billboards on 101 are always such a good snapshot in time of the current peak of the Silicon Valley hype cycle. I've decided to capture photos of the billboards every time I am there, to see how this changes over time.
Here's a photo dump from the 101 billboards from August 2025. The theme is clearly AI. Apologies for the slightly blurry photos, these were taken while driving 60mph down the highway, some of them at night.
Hello! After many months of writing deep dive blog posts about the terminal, on Tuesday I released a new zine called “The Secret Rules of the Terminal”!
You can get it for $12 here: https://wizardzines.com/zines/terminal, or get an 15-pack of all my zines here.
Here’s the cover:
Here’s the table of contents:
I’ve been using the terminal every day for 20 years but even though I’m very confident in the terminal, I’ve always had a bit of an uneasy feeling about it. Usually things work fine, but sometimes something goes wrong and it just feels like investigating it is impossible, or at least like it would open up a huge can of worms.
So I started trying to write down a list of weird problems I’ve run into in terminal and I realized that the terminal has a lot of tiny inconsistencies like:
^[[DIf you use the terminal daily for 10 or 20 years, even if you don’t understand exactly why these things happen, you’ll probably build an intuition for them.
But having an intuition for them isn’t the same as understanding why they happen. When writing this zine I actually had to do a lot of work to figure out exactly what was happening in the terminal to be able to talk about how to reason about it.
It turns out that the “rules” for how the terminal works (how do
you edit a command you type in? how do you quit a program? how do you fix your
colours?) are extremely hard to fully understand, because “the terminal” is actually
made of many different pieces of software (your terminal emulator, your
operating system, your shell, the core utilities like grep, and every other random
terminal program you’ve installed) which are written by different people with different
ideas about how things should work.
So I wanted to write something that would explain:
Terminal internals are a mess. A lot of it is just the way it is because someone made a decision in the 80s and now it’s impossible to change, and honestly I don’t think learning everything about terminal internals is worth it.
But some parts are not that hard to understand and can really make your experience in the terminal better, like:
cating a binary to stdout messes up your terminal, you can just type reset and move onWhen I wrote How Git Works, I thought I
knew how Git worked, and I was right. But the terminal is different. Even
though I feel totally confident in the terminal and even though I’ve used it
every day for 20 years, I had a lot of misunderstandings about how the terminal
works and (unless you’re the author of tmux or something) I think there’s a
good chance you do too.
A few things I learned that are actually useful to me:
reset works under the hood (it does the equivalent of stty sane; sleep 1; tput reset) – basically I learned that I don’t ever need to worry about
remembering stty sane or tput reset and I can just run reset insteadunbuffer program > out; less out)sqlite3 are so annoying to use (they use libedit instead of readline)As usual these days I wrote a bunch of blog posts about various side quests:
terminfo database is serving us well todayA long time ago I used to write zines mostly by myself but with every project I get more and more help. I met with Marie Claire LeBlanc Flanagan every weekday from September to June to work on this one.
The cover is by Vladimir Kašiković, Lesley Trites did copy editing, Simon Tatham (who wrote PuTTY) did technical review, our Operations Manager Lee did the transcription as well as a million other things, and Jesse Luehrs (who is one of the very few people I know who actually understands the terminal’s cursed inner workings) had so many incredibly helpful conversations with me about what is going on in the terminal.
Here are some links to get the zine again:
As always, you can get either a PDF version to print at home or a print version shipped to your house. The only caveat is print orders will ship in August – I need to wait for orders to come in to get an idea of how many I should print before sending it to the printer.
I have never been a C programmer but every so often I need to compile a C/C++
program from source. This has been kind of a struggle for me: for a
long time, my approach was basically “install the dependencies, run make, if
it doesn’t work, either try to find a binary someone has compiled or give up”.
“Hope someone else has compiled it” worked pretty well when I was running Linux but since I’ve been using a Mac for the last couple of years I’ve been running into more situations where I have to actually compile programs myself.
So let’s talk about what you might have to do to compile a C program! I’ll use a couple of examples of specific C programs I’ve compiled and talk about a few things that can go wrong. Here are three programs we’ll be talking about compiling:
This is pretty simple: on an Ubuntu system if I don’t already have a C compiler I’ll install one with:
sudo apt-get install build-essential
This installs gcc, g++, and make. The situation on a Mac is more
confusing but it’s something like “install xcode command line tools”.
Unlike some newer programming languages, C doesn’t have a dependency manager. So if a program has any dependencies, you need to hunt them down yourself. Thankfully because of this, C programmers usually keep their dependencies very minimal and often the dependencies will be available in whatever package manager you’re using.
There’s almost always a section explaining how to get the dependencies in the README, for example in paperjam’s README, it says:
To compile PaperJam, you need the headers for the libqpdf and libpaper libraries (usually available as libqpdf-dev and libpaper-dev packages).
You may need
a2x(found in AsciiDoc) for building manual pages.
So on a Debian-based system you can install the dependencies like this.
sudo apt install -y libqpdf-dev libpaper-dev
If a README gives a name for a package (like libqpdf-dev), I’d basically
always assume that they mean “in a Debian-based Linux distro”: if you’re on a
Mac brew install libqpdf-dev will not work. I still have not 100% gotten
the hang of developing on a Mac yet so I don’t have many tips there yet. I
guess in this case it would be brew install qpdf if you’re using Homebrew.
./configure (if needed)Some C programs come with a Makefile and some instead come with a script called
./configure. For example, if you download sqlite’s source code, it has a ./configure script in
it instead of a Makefile.
My understanding of this ./configure script is:
Makefile or fails because you’re missing some
dependency./configure script is part of a system called
autotools
that I have never needed to learn anything about beyond “run it to generate
a Makefile”.I think there might be some options you can pass to get the ./configure
script to produce a different Makefile but I have never done that.
makeThe next step is to run make to try to build a program. Some notes about
make:
make -j8 to parallelize the build and make it go
fasterHere’s an error I got while compiling paperjam on my Mac:
/opt/homebrew/Cellar/qpdf/12.0.0/include/qpdf/InputSource.hh:85:19: error: function definition does not declare parameters
   85 |     qpdf_offset_t last_offset{0};
      |                   ^
Over the years I’ve learned it’s usually best not to overthink problems like
this: if it’s talking about qpdf, there’s a good change it just means that
I’ve done something wrong with how I’m including the qpdf dependency.
Now let’s talk about some ways to get the qpdf dependency included in the right way.
Before we talk about how to fix dependency problems: building C programs is split into 2 steps:
gcc or clang)ld)It’s important to know this when building a C program because sometimes you need to pass the right flags to the compiler and linker to tell them where to find the dependencies for the program you’re compiling.
make uses environment variables to configure the compiler and linkerIf I run make on my Mac to install paperjam, I get this error:
c++ -o paperjam paperjam.o pdf-tools.o parse.o cmds.o pdf.o -lqpdf -lpaper
ld: library 'qpdf' not found
This is not because qpdf is not installed on my system (it actually is!). But
the compiler and linker don’t know how to find the qpdf library. To fix this, we need to:
"-I/opt/homebrew/include" to the compiler (to tell it where to find the header files)"-L/opt/homebrew/lib -liconv" to the linker (to tell it where to find library files and to link in iconv)And we can get make to pass those extra parameters to the compiler and linker using environment variables!
To see how this works: inside paperjam’s Makefile you can see a bunch of environment variables, like LDLIBS here:
paperjam: $(OBJS)
	$(LD) -o $@ $^ $(LDLIBS)
Everything you put into the LDLIBS environment variable gets passed to the
linker (ld) as a command line argument.
CPPFLAGSMakefiles sometimes define their own environment variables that they pass to
the compiler/linker, but make also has a bunch of “implicit” environment
variables which it will automatically pass to the C compiler and linker. There’s a full list of implicit environment variables here,
but one of them is CPPFLAGS, which gets automatically passed to the C compiler.
(technically it would be more normal to use CXXFLAGS for this, but this
particular Makefile hardcodes CXXFLAGS so setting CPPFLAGS was the only
way I could find to set the compiler flags without editing the Makefile)
makeI learned thanks to @zwol that there are actually two ways to pass environment variables to make:
CXXFLAGS=xyz make (the usual way)make CXXFLAGS=xyzThe difference between them is that make CXXFLAGS=xyz will override the
value of CXXFLAGS set in the Makefile but CXXFLAGS=xyz make won’t.
I’m not sure which way is the norm but I’m going to use the first way in this post.
CPPFLAGS and LDLIBS to fix this compiler errorNow that we’ve talked about how CPPFLAGS and LDLIBS get passed to the
compiler and linker, here’s the final incantation that I used to get the
program to build successfully!
CPPFLAGS="-I/opt/homebrew/include" LDLIBS="-L/opt/homebrew/lib -liconv" make paperjam
This passes -I/opt/homebrew/include to the compiler and -L/opt/homebrew/lib -liconv to the linker.
Also I don’t want to pretend that I “magically” knew that those were the right arguments to pass, figuring them out involved a bunch of confused Googling that I skipped over in this post. I will say that:
-I compiler flag tells the compiler which directory to find header files in, like /opt/homebrew/include/qpdf/QPDF.hh-L linker flag tells the linker which directory to find libraries in, like /opt/homebrew/lib/libqpdf.a-l linker flag tells the linker which libraries to link in, like -liconv means “link in the iconv library”, or -lm means “link math”make $FILENAMEYesterday I discovered this cool tool called
qf which you can use to quickly
open files from the output of ripgrep.
qf is in a big directory of various tools, but I only wanted to compile qf.
So I just compiled qf, like this:
make qf
Basically if you know (or can guess) the output filename of the file you’re
trying to build, you can tell make to just build that file by running make $FILENAME
I sometimes write 5-line C programs with no dependencies, and I just learned
that if I have a file called blah.c, I can just compile it like this without creating a Makefile:
make blah
It gets automaticaly expanded to cc -o blah blah.c, which saves a bit of
typing. I have no idea if I’m going to remember this (I might just keep typing
gcc -o blah blah.c anyway) but it seems like a fun trick.
If you’re having trouble building a C program, maybe other people had problems building it too! Every Linux distribution has build files for every package that they build, so even if you can’t install packages from that distribution directly, maybe you can get tips from that Linux distro for how to build the package. Realizing this (thanks to my friend Dave) was a huge ah-ha moment for me.
For example, this line from the nix package for paperjam says:
env.NIX_LDFLAGS = lib.optionalString stdenv.hostPlatform.isDarwin "-liconv";
This is basically saying “pass the linker flag -liconv to build this on a
Mac”, so that’s a clue we could use to build it.
That same file also says env.NIX_CFLAGS_COMPILE = "-DPOINTERHOLDER_TRANSITION=1";. I’m not sure what this means, but when I try
to build the paperjam package I do get an error about something called a
PointerHolder, so I guess that’s somehow related to the “PointerHolder
transition”.
Once you’ve managed to compile the program, probably you want to install it somewhere!
Some Makefiles have an install target that let you install the tool on your
system with make install. I’m always a bit scared of this (where is it going
to put the files? what if I want to uninstall them later?), so if I’m compiling
a pretty simple program I’ll often just manually copy the binary to install it
instead, like this:
cp qf ~/bin
Once I figured out how to do all of this, I realized that I could use my new
make knowledge to contribute a paperjam package to Homebrew! Then I could
just brew install paperjam on future systems.
The good thing is that even if the details of how all of the different packaging systems, they fundamentally all use C compilers and linkers.
I think all of this is an interesting example of how it can useful to understand some basics of how C programs work (like “they have header files”) even if you’re never planning to write a nontrivial C program if your life.
It feels good to have some ability to compile C/C++ programs myself, even
though I’m still not totally confident about all of the compiler and linker
flags and I still plan to never learn anything about how autotools works other
than “you run ./configure to generate the Makefile”.
Two things I left out of this post:
LD_LIBRARY_PATH / DYLD_LIBRARY_PATH (which you use to tell the dynamic
linker at runtime where to find dynamically linked files) because I can’t
remember the last time I ran into an LD_LIBRARY_PATH issue and couldn’t
find an example.pkg-config, which I think is important but I don’t understand yetI've seen a lot of complaints about how MCP isn't ready for the enterprise.
I agree, although maybe not for the reasons you think. But don't worry, this isn't just a rant! I believe we can fix it!
The good news is the recent updates to the MCP authorization spec that separate out the role of the authorization server from the MCP server have now put the building blocks in place to make this a lot easier.
But let's back up and talk about what enterprise buyers expect when they are evaluating AI tools to bring into their companies.
At a minimum, an enterprise admin expects to be able to put an application under their single sign-on system. This enables the company to manage which users are allowed to use which applications, and prevents their users from needing to have their own passwords at the applications. The goal is to get every application managed under their single sign-on (SSO) system. Many large companies have more than 200 applications, so having them all managed through their SSO solution is a lot better than employees having to manage 200 passwords for each application!
There's a lot more than SSO too, like lifecycle management, entitlements, and logout. We're tackling these in the IPSIE working group in the OpenID Foundation. But for the purposes of this discussion, let's stick to the basics of SSO.
So what does this have to do with MCP?
An AI agent using MCP is just another application enterprises expect to be able to integrate into their single-sign-on (SSO) system. Let's take the example of Claude. When rolled out at a company, ideally every employee would log in to their company Claude account using the company identity provider (IdP). This lets the enterprise admin decide how many Claude licenses to purchase and who should be able to use it.
The next thing that should happen after a user logs in to Claude via SSO is they need to connect Claude to their other enterprise apps. This includes the built-in integrations in Claude like Google Calendar and Google Drive, as well as any MCP servers exposed by other apps in use within the enterprise. That could cover other SaaS apps like Zoom, Atlassian, and Slack, as well as home-grown internal apps.
Today, this process involves a somewhat cumbersome series of steps each individual employee must take. Here's an example of what the user needs to do to connect their AI agent to external apps:
First, the user logs in to Claude using SSO. This involves a redirect from Claude to the enterprise IdP where they authenticate with one or more factors, and then are redirected back.
Next, they need to connect the external app from within Claude. Claude provides a button to initiate the connection. This takes the user to that app (in this example, Google), which redirects them to the IdP to authenticate again, eventually getting redirected back to the app where an OAuth consent prompt is displayed asking the user to approve access, and finally the user is redirected back to Claude and the connection is established.
The user has to repeat these steps for every MCP server that they want to connect to Claude. There are two main problems with this:
Both of these are significant problems. If you have even just 10 MCP servers rolled out in the enterprise, you're asking users to click through 10 SSO and OAuth prompts to establish the connections, and it will only get worse as MCP is more widely adopted within apps. But also, should we really be asking the user if it's okay for Claude to access their data in Google Drive? In a company context, that's not actually the user's decision. That decision should be made by the enterprise IT admin.
In "An Open Letter to Third-party Suppliers", Patrick Opet, Chief Information Security Officer of JPMorgan Chase writes:
"Modern integration patterns, however, dismantle these essential boundaries, relying heavily on modern identity protocols (e.g., OAuth) to create direct, often unchecked interactions between third-party services and firms' sensitive internal resources."
Right now, these app-to-app connections are happening behind the back of the IdP. What we need is a way to move the connections between the applications into the IdP where they can be managed by the enterprise admin.
Let's see how this works if we leverage a new (in-progress) OAuth extension called "Identity and Authorization Chaining Across Domains", which I'll refer to as "Cross-App Access" for short, enabling the enterprise IdP to sit in the middle of the OAuth exchange between the two apps.
In this example, we'll use Claude as the application that is trying to connect to Slack's (hypothetical) MCP server. We'll start with a high-level overview of the flow, and later go over the detailed protocol.
First, the user logs in to Claude through the IdP as normal. This results in Claude getting either an ID token or SAML assertion from the IdP, which tells Claude who the user is. (This works the same for SAML assertions or ID tokens, so I'll use ID tokens in the example from here out.) This is no different than what the user would do today when signing in to Claude.
Then, instead of prompting the user to connect Slack, Claude takes the ID token back to the IdP in a request that says "Claude is requesting access to this user's Slack account."
The IdP validates the ID token, sees it was issued to Claude, and verifies that the admin has allowed Claude to access Slack on behalf of the given user. Assuming everything checks out, the IdP issues a new token back to Claude.
Claude takes the intermediate token from the IdP to Slack saying "hi, I would like an access token for the Slack MCP server. The IdP gave me this token with the details of the user to issue the access token for." Slack validates the token the same way it would have validated an ID token. (Remember, Slack is already configured for SSO to the IdP for this customer as well, so it already has a way to validate these tokens.) Slack is able to issue an access token giving Claude access to this user's resources in its MCP server.
This solves the two big problems:
The other nice side effect of this is since there is no user interaction required, the first time a new user logs in to Claude, all their enterprise apps will be automatically connected without them having to click any buttons!
Now let's look at what this looks like in the actual protocol. This is based on the adopted in-progress OAuth specification "Identity and Authorization Chaining Across Domains". This spec is actually a combination of two RFCs: Token Exchange (RFC 8693), and JWT Profile for Authorization Grants (RFC 7523). Both RFCs as well as the "Identity and Authorization Chaining Across Domains" spec are very flexible. While this means it is possible to apply this to many different use cases, it does mean we need to be a bit more specific in how to use it for this use case. For that purpose, I've written a profile of the Identity Chaining draft called "Identity Assertion Authorization Grant" to fill in the missing pieces for the specific use case detailed here.
Let's go through it step by step. For this example we'll use the following entities:
First, Claude gets the user to sign in using a standard OpenID Connect (or SAML) flow in order to obtain an ID token. There isn't anything unique to this spec regarding this first stage, so I will skip the details of the OpenID Connect flow and we'll start with the ID token as the input to the next step.
Claude, the requesting application, then makes a Token Exchange request (RFC 8693) to the IdP's token endpoint with the following parameters:
requested_token_type: The value urn:ietf:params:oauth:token-type:id-jag indicates that an ID Assertion JWT is being requested.audience: The Issuer URL of the Resource Application's authorization server.subject_token: The identity assertion (e.g. the OpenID Connect ID Token or SAML assertion) for the target end-user.subject_token_type: Either urn:ietf:params:oauth:token-type:id_token or urn:ietf:params:oauth:token-type:saml2 as defined by RFC 8693.This request will also include the client credentials that Claude would use in a traditional OAuth token request, which could be a client secret or a JWT Bearer Assertion.
POST /oauth2/token HTTP/1.1
Host: acme.okta.com
Content-Type: application/x-www-form-urlencoded

grant_type=urn:ietf:params:oauth:grant-type:token-exchange
&requested_token_type=urn:ietf:params:oauth:token-type:id-jag
&audience=https://auth.slack.com/
&subject_token=eyJraWQiOiJzMTZ0cVNtODhwREo4VGZCXzdrSEtQ...
&subject_token_type=urn:ietf:params:oauth:token-type:id_token
&client_assertion_type=urn:ietf:params:oauth:client-assertion-type:jwt-bearer
&client_assertion=eyJhbGciOiJSUzI1NiIsImtpZCI6IjIyIn0...
At this point, the IdP evaluates the request and decides whether to issue the requested "ID Assertion JWT". The request will be evaluated based on the validity of the arguments, as well as the configured policy by the customer.
For example, the IdP validates that the ID token in this request was issued to the same client that matches the provided client authentication. It evaluates that the user still exists and is active, and that the user is assigned the Resource Application. Other policies can be evaluated at the discretion of the IdP, just like it can during a single sign-on flow.
If the IdP agrees that the requesting app should be authorized to access the given user's data in the resource app's MCP server, it will respond with a Token Exchange response to issue the token:
HTTP/1.1 200 OK
Content-Type: application/json
Cache-Control: no-store

{
  "issued_token_type": "urn:ietf:params:oauth:token-type:id-jag",
  "access_token": "eyJhbGciOiJIUzI1NiIsI...",
  "token_type": "N_A",
  "expires_in": 300
}
The claims in the issued JWT are defined in "Identity Assertion Authorization Grant". The JWT is signed using the same key that the IdP signs ID tokens with. This is a critical aspect that makes this work, since again we assumed that both apps would already be configured for SSO to the IdP so would already be aware of the signing key for that purpose.
At this point, Claude is ready to request a token for the Resource App's MCP server
The JWT received in the previous request can now be used as a "JWT Authorization Grant" as described by RFC 7523. To do this, Claude makes a request to the MCP authorization server's token endpoint with the following parameters:
grant_type: urn:ietf:params:oauth:grant-type:jwt-bearerassertion: The Identity Assertion Authorization Grant JWT obtained in the previous token exchange stepFor example:
POST /oauth2/token HTTP/1.1
Host: auth.slack.com
Authorization: Basic yZS1yYW5kb20tc2VjcmV0v3JOkF0XG5Qx2

grant_type=urn:ietf:params:oauth:grant-type:jwt-bearer
assertion=eyJhbGciOiJIUzI1NiIsI...
Slack's authorization server can now evaluate this request to determine whether to issue an access token. The authorization server can validate the JWT by checking the issuer (iss) in the JWT to determine which enterprise IdP the token is from, and then check the signature using the public key discovered at that server. There are other claims to be validated as well, described in Section 6.1 of the Identity Assertion Authorization Grant.
Assuming all the validations pass, Slack is ready to issue an access token to Claude in the token response:
HTTP/1.1 200 OK
Content-Type: application/json
Cache-Control: no-store

{
  "token_type": "Bearer",
  "access_token": "2YotnFZFEjr1zCsicMWpAA",
  "expires_in": 86400
}
This token response is the same format that Slack's authorization server would be responding to a traditional OAuth flow. That's another key aspect of this design that makes it scalable. We don't need the resource app to use any particular access token format, since only that server is responsible for validating those tokens.
Now that Claude has the access token, it can make a request to the (hypothetical) Slack MCP server using the bearer token the same way it would have if it got the token using the traditional redirect-based OAuth flow.
Note: Eventually we'll need to define the specific behavior of when to return a refresh token in this token response. The goal is to ensure the client goes through the IdP often enough for the IdP to enforce its access policies. A refresh token could potentially undermine that if the refresh token lifetime is too long. It follows that ultimately the IdP should enforce the refresh token lifetime, so we will need to define a way for the IdP to communicate to the authorization server whether and how long to issue refresh tokens. This would enable the authorization server to make its own decision on access token lifetime, while still respecting the enterprise IdP policy.
Here's the flow again, this time as a sequence diagram.
At this point, the user is logged in to the MCP client. Everything up until this point has been a standard OpenID Connect flow.
For a more detailed step by step of the flow, see Appendix A.3 of the Identity Assertion Authorization Grant.
If this is something you're interested in, we'd love your help! The in-progress spec is publicly available, and we're looking for people interested in helping prototype it. If you're building an MCP server and you want to make it enterprise-ready, I'd be happy to help you build this!
You can find me at a few related events coming up:
And of course you can always find me on LinkedIn or email me at aaron.parecki@okta.com.
Hello! Today I want to talk about ANSI escape codes.
For a long time I was vaguely aware of ANSI escape codes (“that’s how you make text red in the terminal and stuff”) but I had no real understanding of where they were supposed to be defined or whether or not there were standards for them. I just had a kind of vague “there be dragons” feeling around them. While learning about the terminal this year, I’ve learned that:
So I wanted to put together a list for myself of some standards that exist around escape codes, because I want to know if they have to feel unreliable and frustrating, or if there’s a future where we could all rely on them with more confidence.
Have you ever pressed the left arrow key in your terminal and seen ^[[D?
That’s an escape code! It’s called an “escape code” because the first character
is the “escape” character, which is usually written as ESC, \x1b, \E,
\033, or ^[.
Escape codes are how your terminal emulator communicates various kinds of information (colours, mouse movement, etc) with programs running in the terminal. There are two kind of escape codes:
ESC[D, “Ctrl+left arrow” might be ESC[1;5D, and clicking the mouse might
be something like ESC[M :3.Now let’s talk about standards!
The first standard I found relating to escape codes was ECMA-48, which was originally published in 1976.
ECMA-48 does two things:
ESC[ + something and “OSC” codes, which are ESC] + something)ESC[D, or “turn text red” is ESC[31m. In the spec, the “cursor left”
one is called CURSOR LEFT and the one for changing colours is called
SELECT GRAPHIC RENDITION.The formats are extensible, so there’s room for others to define more escape codes in the future. Lots of escape codes that are popular today aren’t defined in ECMA-48: for example it’s pretty common for terminal applications (like vim, htop, or tmux) to support using the mouse, but ECMA-48 doesn’t define escape codes for the mouse.
There are a bunch of escape codes that aren’t defined in ECMA-48, for example:
I believe (correct me if I’m wrong!) that these and some others came from xterm, are documented in XTerm Control Sequences, and have been widely implemented by other terminal emulators.
This list of “what xterm supports” is not a standard exactly, but xterm is extremely influential and so it seems like an important document.
In the 80s (and to some extent today, but my understanding is that it was MUCH more dramatic in the 80s) there was a huge amount of variation in what escape codes terminals actually supported.
To deal with this, there’s a database of escape codes for various terminals called “terminfo”.
It looks like the standard for terminfo is called X/Open Curses, though you need to create an account to view that standard for some reason. It defines the database format as well as a C library interface (“curses”) for accessing the database.
For example you can run this bash snippet to see every possible escape code for “clear screen” for all of the different terminals your system knows about:
for term in $(toe -a | awk '{print $1}')
do
  echo $term
  infocmp -1 -T "$term" 2>/dev/null | grep 'clear=' | sed 's/clear=//g;s/,//g'
done
On my system (and probably every system I’ve ever used?), the terminfo database is managed by ncurses.
I think it’s interesting that there are two main approaches that applications take to handling ANSI escape codes:
TERM environment variable. Fish does this, for example.Some examples of programs/libraries that take approach #2 (“don’t use terminfo”) include:
I got curious about why folks might be moving away from terminfo and I found this very interesting and extremely detailed rant about terminfo from one of the fish maintainers, which argues that:
[the terminfo authors] have done a lot of work that, at the time, was extremely important and helpful. My point is that it no longer is.
I’m not going to do it justice so I’m not going to summarize it, I think it’s worth reading.
I was just talking about the idea that you can use a “common set” of escape codes that will work for most people. But what is that set? Is there any agreement?
I really do not know the answer to this at all, but from doing some reading it seems like it’s some combination of:
and maybe ultimately “identify the terminal emulators you think your users are going to use most frequently and test in those”, the same way web developers do when deciding which CSS features are okay to use
I don’t think there are any resources like Can I use…? or Baseline for the terminal though. (in theory terminfo is supposed to be the “caniuse” for the terminal but it seems like it often takes 10+ years to add new terminal features when people invent them which makes it very limited)
I also asked on Mastodon why people found terminfo valuable in 2025 and got a few reasons that made sense to me:
TERM environment variable to
control how programs behave (for example with TERM=dumb), and there’s
no standard for how that should work in a post-terminfo worldThe way that ncurses uses the TERM environment variable to decide which
escape codes to use reminds me of how webservers used to sometimes use the
browser user agent to decide which version of a website to serve.
It also seems like it’s had some of the same results – the way iTerm2 reports itself as being “xterm-256color” feels similar to how Safari’s user agent is “Mozilla/5.0 (Macintosh; Intel Mac OS X 14_7_4) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/18.3 Safari/605.1.15”. In both cases the terminal emulator / browser ends up changing its user agent to get around user agent detection that isn’t working well.
On the web we ended up deciding that user agent detection was not a good practice and to instead focus on standardization so we can serve the same HTML/CSS to all browsers. I don’t know if the same approach is the future in the terminal though – I think the terminal landscape today is much more fragmented than the web ever was as well as being much less well funded.
A few more documents and standards related to escape codes, in no particular order:
I sometimes see people saying that the unix terminal is “outdated”, and since I love the terminal so much I’m always curious about what incremental changes might make it feel less “outdated”.
Maybe if we had a clearer standards landscape (like we do on the web!) it would be easier for terminal emulator developers to build new features and for authors of terminal applications to more confidently adopt those features so that we can all benefit from them and have a richer experience in the terminal.
Obviously standardizing ANSI escape codes is not easy (ECMA-48 was first published almost 50 years ago and we’re still not there!). I don’t even know what all of the challenges are. But the situation with HTML/CSS/JS used to be extremely bad too and now it’s MUCH better, so maybe there’s hope.
I was talking to a friend about how to add a directory to your PATH today. It’s
something that feels “obvious” to me since I’ve been using the terminal for a
long time, but when I searched for instructions for how to do it, I actually
couldn’t find something that explained all of the steps – a lot of them just
said “add this to ~/.bashrc”, but what if you’re not using bash? What if your
bash config is actually in a different file? And how are you supposed to figure
out which directory to add anyway?
So I wanted to try to write down some more complete directions and mention some of the gotchas I’ve run into over the years.
Here’s a table of contents:
If you’re not sure what shell you’re using, here’s a way to find out. Run this:
ps -p $$ -o pid,comm=
97295 bash97295 zsh$$ isn’t valid syntax in fish, but in any case the error
message tells you that you’re using fish, which you probably already knew)Also bash is the default on Linux and zsh is the default on Mac OS (as of 2024). I’ll only cover bash, zsh, and fish in these directions.
~/.zshrc~/.bashrc, but it’s complicated, see the note in the next section~/.config/fish/config.fish (you can run echo $__fish_config_dir if you want to be 100% sure)Bash has three possible config files: ~/.bashrc, ~/.bash_profile, and ~/.profile.
If you’re not sure which one your system is set up to use, I’d recommend testing this way:
echo hi there to your ~/.bashrc~/.bashrc is being used! Hooray!~/.bash_profile~/.profile if the first two options don’t work.(there are a lot of elaborate flow charts out there that explain how bash decides which config file to use but IMO it’s not worth it to internalize them and just testing is the fastest way to be sure)
Let’s say that you’re trying to install and run a program called http-server
and it doesn’t work, like this:
$ npm install -g http-server
$ http-server
bash: http-server: command not found
How do you find what directory http-server is in? Honestly in general this is
not that easy – often the answer is something like “it depends on how npm is
configured”. A few ideas:
cargo, npm, homebrew, etc),
when you first set it up it’ll print out some directions about how to update
your PATH. So if you’re paying attention you can get the directions then.PATH for younpm config get prefix (then append /bin/)go env GOPATH (then append /bin/)asdf info | grep ASDF_DIR (then append /bin/ and /shims/)Once you’ve found a directory you think might be the right one, make sure it’s
actually correct! For example, I found out that on my machine, http-server is
in ~/.npm-global/bin. I can make sure that it’s the right directory by trying to
run the program http-server in that directory like this:
$ ~/.npm-global/bin/http-server
Starting up http-server, serving ./public
It worked! Now that you know what directory you need to add to your PATH,
let’s move to the next step!
Now we have the 2 critical pieces of information we need:
~/.npm-global/bin/)~/.bashrc, ~/.zshrc, or ~/.config/fish/config.fish)Now what you need to add depends on your shell:
bash instructions:
Open your shell’s config file, and add a line like this:
export PATH=$PATH:~/.npm-global/bin/
(obviously replace ~/.npm-global/bin with the actual directory you’re trying to add)
zsh instructions:
You can do the same thing as in bash, but zsh also has some slightly fancier syntax you can use if you prefer:
path=(
  $path
  ~/.npm-global/bin
)
fish instructions:
In fish, the syntax is different:
set PATH $PATH ~/.npm-global/bin
(in fish you can also use fish_add_path, some notes on that further down)
Now, an extremely important step: updating your shell’s config won’t take effect if you don’t restart it!
Two ways to do this:
bash to start a new shell (or zsh if you’re using zsh, or fish if you’re using fish)I’ve found that both of these usually work fine.
And you should be done! Try running the program you were trying to run and hopefully it works now.
If not, here are a couple of problems that you might run into:
If the wrong version of a program is running, you might need to add the directory to the beginning of your PATH instead of the end.
For example, on my system I have two versions of python3 installed, which I
can see by running which -a:
$ which -a python3
/usr/bin/python3
/opt/homebrew/bin/python3
The one your shell will use is the first one listed.
If you want to use the Homebrew version, you need to add that directory
(/opt/homebrew/bin) to the beginning of your PATH instead, by putting this in
your shell’s config file (it’s /opt/homebrew/bin/:$PATH instead of the usual $PATH:/opt/homebrew/bin/)
export PATH=/opt/homebrew/bin/:$PATH
or in fish:
set PATH ~/.cargo/bin $PATH
All of these directions only work if you’re running the program from your shell. If you’re running the program from an IDE, from a GUI, in a cron job, or some other way, you’ll need to add the directory to your PATH in a different way, and the exact details might depend on the situation.
in a cron job
Some options:
/home/bork/bin/my-programecho "PATH=$PATH".I’m honestly not sure how to handle it in an IDE/GUI because I haven’t run into that in a long time, will add directions here if someone points me in the right direction.
PATH entries making it harder to debugIf you edit your path and start a new shell by running bash (or zsh, or
fish), you’ll often end up with duplicate PATH entries, because the shell
keeps adding new things to your PATH every time you start your shell.
Personally I don’t think I’ve run into a situation where this kind of
duplication breaks anything, but the duplicates can make it harder to debug
what’s going on with your PATH if you’re trying to understand its contents.
Some ways you could deal with this:
PATH, open a new terminal to do it in so you get
a “fresh” state. This should avoid the duplication.PATH at the end of your shell’s config (for example in
zsh apparently you can do this with typeset -U path)PATH when adding it (for
example in fish I believe you can do this with fish_add_path --path /some/directory)How to deduplicate your PATH is shell-specific and there isn’t always a
built in way to do it so you’ll need to look up how to accomplish it in your
shell.
PATHHere’s a situation that’s easy to get into in bash or zsh:
PATHbash to reload your configThis happens because in bash, by default, history is not saved until you exit the shell.
Some options for fixing this:
bash to reload your config, run source ~/.bashrc (or
source ~/.zshrc in zsh). This will reload the config inside your current
session.sourceWhen you install cargo (Rust’s installer) for the first time, it gives you
these instructions for how to set up your PATH, which don’t mention a specific
directory at all.
This is usually done by running one of the following (note the leading DOT):

. "$HOME/.cargo/env"        	# For sh/bash/zsh/ash/dash/pdksh
source "$HOME/.cargo/env.fish"  # For fish
The idea is that you add that line to your shell’s config, and their script
automatically sets up your PATH (and potentially other things) for you.
This is pretty common (for example Homebrew suggests you eval brew shellenv), and there are
two ways to approach this:
. "$HOME/.cargo/env" to your shell’s config). "$HOME/.cargo/env" in my shell (or the fish version if using fish)echo "$PATH" | tr ':' '\n' | grep cargo to figure out which directories it added/Users/bork/.cargo/bin and shorten that to ~/.cargo/bin~/.cargo/bin to PATH (with the directions in this post)I don’t think there’s anything wrong with doing what the tool suggests (it might be the “best way”!), but personally I usually use the second approach because I prefer knowing exactly what configuration I’m changing.
fish_add_pathfish has a handy function called fish_add_path that you can run to add a directory to your PATH like this:
fish_add_path /some/directory
This is cool (it’s such a simple command!) but I’ve stopped using it for a couple of reasons:
fish_add_path will update the PATH for every session in the
future (with a “universal variable”) and sometimes it will update the PATH
just for the current session and it’s hard for me to tell which one it will
do. In theory the docs explain this but I could not understand them.PATH a few weeks or
months later because maybe you made a mistake, it’s kind of hard to do
(there are instructions in this comments of this github issue though).Hopefully this will help some people. Let me know (on Mastodon or Bluesky) if you there are other major gotchas that have tripped you up when adding a directory to your PATH, or if you have questions about this post!
A few weeks ago I ran a terminal survey (you can read the results here) and at the end I asked:
What’s the most frustrating thing about using the terminal for you?
1600 people answered, and I decided to spend a few days categorizing all the responses. Along the way I learned that classifying qualitative data is not easy but I gave it my best shot. I ended up building a custom tool to make it faster to categorize everything.
As with all of my surveys the methodology isn’t particularly scientific. I just posted the survey to Mastodon and Twitter, ran it for a couple of days, and got answers from whoever happened to see it and felt like responding.
Here are the top categories of frustrations!
I think it’s worth keeping in mind while reading these comments that
These comments aren’t coming from total beginners.
Here are the categories of frustrations! The number in brackets is the number of people with that frustration. I’m mostly writing this up for myself because I’m trying to write a zine about the terminal and I wanted to get a sense for what people are having trouble with.
People talked about struggles remembering:
One example comment:
There are just so many little “trivia” details to remember for full functionality. Even after all these years I’ll sometimes forget where it’s 2 or 1 for stderr, or forget which is which for
>and>>.
People talked about struggling with switching systems (for example home/work computer or when SSHing) and running into:
as well as differences inside the same system like pagers being not consistent with each other (git diff pagers, other pagers).
One example comment:
I got used to fish and vi mode which are not available when I ssh into servers, containers.
Lots of problems with color, like:
This comment felt relatable to me:
Getting my terminal theme configured in a reasonable way between the terminal emulator and fish (I did this years ago and remember it being tedious and fiddly and now feel like I’m locked into my current theme because it works and I dread touching any of that configuration ever again).
Half of the comments on keyboard shortcuts were about how on Linux/Windows, the keyboard shortcut to copy/paste in the terminal is different from in the rest of the OS.
Some other issues with keyboard shortcuts other than copy/paste:
Ctrl-W in a browser-based terminal and closing the windowCtrl-Shift-, no Super, no Hyper, lots of ctrl- shortcuts aren’t
possible like Ctrl-,)Ctrl+left arrow for something else)Aside from “the keyboard shortcut for copy and paste is different”, there were a lot of OTHER issues with copy and paste, like:
There were lots of comments about this, which all came down to the same basic complaint – it’s hard to discover useful tools or features! This comment kind of summed it all up:
How difficult it is to learn independently. Most of what I know is an assorted collection of stuff I’ve been told by random people over the years.
A lot of comments about it generally having a steep learning curve. A couple of example comments:
After 15 years of using it, I’m not much faster than using it than I was 5 or maybe even 10 years ago.
and
That I know I could make my life easier by learning more about the shortcuts and commands and configuring the terminal but I don’t spend the time because it feels overwhelming.
Some issues with shell history:
One example comment:
It wasted a lot of time until I figured it out and still annoys me that “history” on zsh has such a small buffer; I have to type “history 0” to get any useful length of history.
People talked about:
Here’s a representative comment:
Finding good examples and docs. Man pages often not enough, have to wade through stack overflow
A few issues with scrollback:
One example comment:
When resizing the terminal (in particular: making it narrower) leads to broken rewrapping of the scrollback content because the commands formatted their output based on the terminal window width.
Lots of comments about how the terminal feels hampered by legacy decisions and how users often end up needing to learn implementation details that feel very esoteric. One example comment:
Most of the legacy cruft, it would be great to have a green field implementation of the CLI interface.
Lots of complaints about POSIX shell scripting. There’s a general feeling that shell scripting is difficult but also that switching to a different less standard scripting language (fish, nushell, etc) brings its own problems.
Shell scripting. My tolerance to ditch a shell script and go to a scripting language is pretty low. It’s just too messy and powerful. Screwing up can be costly so I don’t even bother.
Some more issues that were mentioned at least 10 times:
Ctrl-S, cating a binary, etc)There were also 122 answers to the effect of “nothing really” or “only that I can’t do EVERYTHING in the terminal”
One example comment:
Think I’ve found work arounds for most/all frustrations
I’m not going to make a lot of commentary on these results, but here are a couple of categories that feel related to me:
Trying to categorize all these results in a reasonable way really gave me an appreciation for social science researchers’ skills.
Hello! Recently I ran a terminal survey and I asked people what frustrated them. One person commented:
There are so many pieces to having a modern terminal experience. I wish it all came out of the box.
My immediate reaction was “oh, getting a modern terminal experience isn’t that hard, you just need to….”, but the more I thought about it, the longer the “you just need to…” list got, and I kept thinking about more and more caveats.
So I thought I would write down some notes about what it means to me personally to have a “modern” terminal experience and what I think can make it hard for people to get there.
Here are a few things that are important to me, with which part of the system is responsible for them:
p in vim to paste (text editor, maybe the OS/terminal emulator too)ls (shell config)Ctrl+left arrow to work (shell or application)less: (terminal emulator and applications)There are a million other terminal conveniences out there and different people value different things, but those are the ones that I would be really unhappy without.
My basic approach is:
fish shell. Mostly don’t configure it, except to:
EDITOR environment variable to my favourite terminal editorls to ls --color=autoneovim, with a configuration that I’ve been very slowly building over the last 9 years or so (the last time I deleted my vim config and started from scratch was 9 years ago)A few things that affect my approach:
What if you want a nice experience, but don’t want to spend a lot of time on configuration? Figuring out how to configure vim in a way that I was satisfied with really did take me like ten years, which is a long time!
My best ideas for how to get a reasonable terminal experience with minimal config are:
fish or zsh with oh-my-zshEDITOR environment variable to your favourite terminal text
editorls to ls --color=autoCtrl-C to copy, Ctrl-V to paste, Ctrl-A to select all) in micro and
they do what you’d expect. I would probably try switching to helix except
that retraining my vim muscle memory seems way too hard. Also helix doesn’t
have a GUI or plugin system yet.Personally I wouldn’t use xterm, rxvt, or Terminal.app as a terminal emulator, because I’ve found in the past that they’re missing core features (like 24-bit colour in Terminal.app’s case) that make the terminal harder to use for me.
I don’t want to pretend that getting a “modern” terminal experience is easier than it is though – I think there are two issues that make it hard. Let’s talk about them!
bash and zsh are by far the two most popular shells, and neither of them provide a default experience that I would be happy using out of the box, for example:
And even though I love fish, the fact that it isn’t POSIX does make it hard for a lot of folks to make the switch.
Of course it’s totally possible to learn how to customize your prompt in bash
or whatever, and it doesn’t even need to be that complicated (in bash I’d
probably start with something like export PS1='[\u@\h \W$(__git_ps1 " (%s)")]\$ ', or maybe use starship).
But each of these “not complicated” things really does add up and it’s
especially tough if you need to keep your config in sync across several
systems.
An extremely popular solution to getting a “modern” shell experience is oh-my-zsh. It seems like a great project and I know a lot of people use it very happily, but I’ve struggled with configuration systems like that in the past – it looks like right now the base oh-my-zsh adds about 3000 lines of config, and often I find that having an extra configuration system makes it harder to debug what’s happening when things go wrong. I personally have a tendency to use the system to add a lot of extra plugins, make my system slow, get frustrated that it’s slow, and then delete it completely and write a new config from scratch.
In the terminal survey I ran recently, the most popular terminal text editors
by far were vim, emacs, and nano.
I think the main options for terminal text editors are:
micro or helix which seem to offer a pretty good out-of-the-box
experience, potentially occasionally run into issues with using a less
mainstream text editorcode as their EDITOR in the terminal.The last issue is that sometimes individual programs that I use are kind of
annoying. For example on my Mac OS machine, /usr/bin/sqlite3 doesn’t support
the Ctrl+Left Arrow keyboard shortcut. Fixing this to get a reasonable
terminal experience in SQLite was a little complicated, I had to:
I find that debugging application-specific issues like this is really not easy and often it doesn’t feel “worth it” – often I’ll end up just dealing with various minor inconveniences because I don’t want to spend hours investigating them. The only reason I was even able to figure this one out at all is that I’ve been spending a huge amount of time thinking about the terminal recently.
A big part of having a “modern” experience using terminal programs is just
using newer terminal programs, for example I can’t be bothered to learn a
keyboard shortcut to sort the columns in top, but in htop I can just click
on a column heading with my mouse to sort it. So I use htop instead! But discovering new more “modern” command line tools isn’t easy (though
I made a list here),
finding ones that I actually like using in practice takes time, and if you’re
SSHed into another machine, they won’t always be there.
Something I find tricky about configuring my terminal to make everything “nice” is that changing one seemingly small thing about my workflow can really affect everything else. For example right now I don’t use tmux. But if I needed to use tmux again (for example because I was doing a lot of work SSHed into another machine), I’d need to think about a few things, like:
and probably more things I haven’t thought of. “Using tmux means that I have to change how I manage my colours” sounds unlikely, but that really did happen to me and I decided “well, I don’t want to change how I manage colours right now, so I guess I’m not using that feature!”.
It’s also hard to remember which features I’m relying on – for example maybe my current terminal does have OSC 52 support and because copying from tmux over SSH has always Just Worked I don’t even realize that that’s something I need, and then it mysteriously stops working when I switch terminals.
Personally even though I think my setup is not that complicated, it’s taken me 20 years to get to this point! Because terminal config changes are so likely to have unexpected and hard-to-understand consequences, I’ve found that if I change a lot of terminal configuration all at once it makes it much harder to understand what went wrong if there’s a problem, which can be really disorienting.
So I usually prefer to make pretty small changes, and accept that changes can
might take me a REALLY long time to get used to. For example I switched from
using ls to eza a year or two ago and
while I like it (because eza -l prints human-readable file sizes by default)
I’m still not quite sure about it. But also sometimes it’s worth it to make a
big change, like I made the switch to fish (from bash) 10 years ago and I’m
very happy I did.
Trying to explain how “easy” it is to configure your terminal really just made me think that it’s kind of hard and that I still sometimes get confused.
I’ve found that there’s never one perfect way to configure things in the terminal that will be compatible with every single other thing. I just need to try stuff, figure out some kind of locally stable state that works for me, and accept that if I start using a new tool it might disrupt the system and I might need to rethink things.
Recently I’ve been thinking about how everything that happens in the terminal is some combination of:
top or vim or cat)The first three (your operating system, shell, and terminal emulator) are all kind of known quantities – if you’re using bash in GNOME Terminal on Linux, you can more or less reason about how how all of those things interact, and some of their behaviour is standardized by POSIX.
But the fourth one (“whatever program you happen to be running”) feels like it could do ANYTHING. How are you supposed to know how a program is going to behave?
This post is kind of long so here’s a quick table of contents:
Ctrl-CqCtrl-D on an empty lineCtrl-W should delete the last word- means stdin/stdoutAs far as I know, there are no real standards for how programs in the terminal should behave – the closest things I know of are:
cp should work but AFAIK it doesn’t have anything to say about how for
example htop should behave.But even though there are no standards, in my experience programs in the terminal behave in a pretty consistent way. So I wanted to write down a list of “rules” that in my experience programs mostly follow.
My goal here isn’t to convince authors of terminal programs that they should follow any of these rules. There are lots of exceptions to these and often there’s a good reason for those exceptions.
But it’s very useful for me to know what behaviour to expect from a random new terminal program that I’m using. Instead of “uh, programs could do literally anything”, it’s “ok, here are the basic rules I expect, and then I can keep a short mental list of exceptions”.
So I’m just writing down what I’ve observed about how programs behave in my 20 years of using the terminal, why I think they behave that way, and some examples of cases where that rule is “broken”.
There are a bunch of common conventions that I think are pretty clearly the program’s responsibility to implement, like:
~/.BLAHrc or ~/.config/BLAH/FILE or /etc/BLAH/ or something--help should print help textBut in this post I’m going to focus on things that it’s not 100% obvious are
the program’s responsibility. For example it feels to me like a “law of nature”
that pressing Ctrl-D should quit a REPL, but programs often
need to explicitly implement support for it – even though cat doesn’t need
to implement Ctrl-D support, ipython does. (more about that in “rule 3” below)
Understanding which things are the program’s responsibility makes it much less surprising when different programs’ implementations are slightly different.
Ctrl-CThe main reason for this rule is that noninteractive programs will quit by
default on Ctrl-C if they don’t set up a SIGINT signal handler, so this is
kind of a “you should act like the default” rule.
Something that trips a lot of people up is that this doesn’t apply to
interactive programs like python3 or bc or less. This is because in
an interactive program, Ctrl-C has a different job – if the program is
running an operation (like for example a search in less or some Python code
in python3), then Ctrl-C will interrupt that operation but not stop the
program.
As an example of how this works in an interactive program: here’s the code in prompt-toolkit (the library that iPython uses for handling input)
that aborts a search when you press Ctrl-C.
qTUI programs (like less or htop) will usually quit when you press q.
This rule doesn’t apply to any program where pressing q to quit wouldn’t make
sense, like tmux or text editors.
Ctrl-D on an empty lineREPLs (like python3 or ed) will usually quit when you press Ctrl-D on an
empty line. This rule is similar to the Ctrl-C rule – the reason for this is
that by default if you’re running a program (like cat) in “cooked mode”, then
the operating system will return an EOF when you press Ctrl-D on an empty
line.
Most of the REPLs I use (sqlite3, python3, fish, bash, etc) don’t actually use cooked mode, but they all implement this keyboard shortcut anyway to mimic the default behaviour.
For example, here’s the code in prompt-toolkit that quits when you press Ctrl-D, and here’s the same code in readline.
I actually thought that this one was a “Law of Terminal Physics” until very recently because I’ve basically never seen it broken, but you can see that it’s just something that each individual input library has to implement in the links above.
Someone pointed out that the Erlang REPL does not quit when you press Ctrl-D,
so I guess not every REPL follows this “rule”.
Terminal programs rarely use colours other than the base 16 ANSI colours. This
is because if you specify colours with a hex code, it’s very likely to clash
with some users’ background colour. For example if I print out some text as
#EEEEEE, it would be almost invisible on a white background, though it would
look fine on a dark background.
But if you stick to the default 16 base colours, you have a much better chance that the user has configured those colours in their terminal emulator so that they work reasonably well with their background color. Another reason to stick to the default base 16 colours is that it makes less assumptions about what colours the terminal emulator supports.
The only programs I usually see breaking this “rule” are text editors, for example Helix by default will use a purple background which is not a default ANSI colour. It seems fine for Helix to break this rule since Helix isn’t a “core” program and I assume any Helix user who doesn’t like that colorscheme will just change the theme.
Almost every program I use supports readline keybindings if it would make
sense to do so. For example, here are a bunch of different programs and a link
to where they define Ctrl-E to go to the end of the line:
None of those programs actually uses readline directly, they just sort of
mimic emacs/readline keybindings. They don’t always mimic them exactly: for
example atuin seems to use Ctrl-A as a prefix, so Ctrl-A doesn’t go to the
beginning of the line.
Also all of these programs seem to implement their own internal cut and paste
buffers so you can delete a line with Ctrl-U and then paste it with Ctrl-Y.
The exceptions to this are:
git, cat, and nc) don’t have any line editing support at all (except for backspace, Ctrl-W, and Ctrl-U)I wrote more about this “what keybindings does a program support?” question in entering text in the terminal is complicated.
I’ve never seen a program (other than a text editor) where Ctrl-W doesn’t
delete the last word. This is similar to the Ctrl-C rule – by default if a
program is in “cooked mode”, the OS will delete the last word if you press
Ctrl-W, and delete the whole line if you press Ctrl-U. So usually programs
will imitate that behaviour.
I can’t think of any exceptions to this other than text editors but if there are I’d love to hear about them!
Most programs will disable colours when writing to a pipe. For example:
rg blah will highlight all occurrences of blah in the output, but if the
output is to a pipe or a file, it’ll turn off the highlighting.ls --color=auto will use colour when writing to a terminal, but not when
writing to a pipeBoth of those programs will also format their output differently when writing
to the terminal: ls will organize files into columns, and ripgrep will group
matches with headings.
If you want to force the program to use colour (for example because you want to
look at the colour), you can use unbuffer to force the program’s output to be
a tty like this:
unbuffer rg blah | less -R
I’m sure that there are some programs that “break” this rule but I can’t think
of any examples right now. Some programs have an --color flag that you can
use to force colour to be on, in the example above you could also do rg --color=always | less -R.
- means stdin/stdoutUsually if you pass - to a program instead of a filename, it’ll read from
stdin or write to stdout (whichever is appropriate). For example, if you want
to format the Python code that’s on your clipboard with black and then copy
it, you could run:
pbpaste | black - | pbcopy
(pbpaste is a Mac program, you can do something similar on Linux with xclip)
My impression is that most programs implement this if it would make sense and I can’t think of any exceptions right now, but I’m sure there are many exceptions.
These rules took me a long time for me to learn because I had to:
Ctrl-C will exit programs")Ctrl-C will exit find but not less”)Ctrl-C will generally quit
noninteractive programs, but in interactive programs it might interrupt the
current operation instead of quitting the program")A lot of my understanding of the terminal is honestly still in the “subconscious pattern recognition” stage. The only reason I’ve been taking the time to make things explicit at all is because I’ve been trying to explain how it works to others. Hopefully writing down these “rules” explicitly will make learning some of this stuff a little bit faster for others.
Here’s a niche terminal problem that has bothered me for years but that I never really understood until a few weeks ago. Let’s say you’re running this command to watch for some specific output in a log file:
tail -f /some/log/file | grep thing1 | grep thing2
If log lines are being added to the file relatively slowly, the result I’d see is… nothing! It doesn’t matter if there were matches in the log file or not, there just wouldn’t be any output.
I internalized this as “uh, I guess pipes just get stuck sometimes and don’t
show me the output, that’s weird”, and I’d handle it by just
running grep thing1 /some/log/file | grep thing2 instead, which would work.
So as I’ve been doing a terminal deep dive over the last few months I was really excited to finally learn exactly why this happens.
The reason why “pipes get stuck” sometimes is that it’s VERY common for programs to buffer their output before writing it to a pipe or file. So the pipe is working fine, the problem is that the program never even wrote the data to the pipe!
This is for performance reasons: writing all output immediately as soon as you can uses more system calls, so it’s more efficient to save up data until you have 8KB or so of data to write (or until the program exits) and THEN write it to the pipe.
In this example:
tail -f /some/log/file | grep thing1 | grep thing2
the problem is that grep thing1 is saving up all of its matches until it has
8KB of data to write, which might literally never happen.
Part of why I found this so disorienting is that tail -f file | grep thing
will work totally fine, but then when you add the second grep, it stops
working!! The reason for this is that the way grep handles buffering depends
on whether it’s writing to a terminal or not.
Here’s how grep (and many other programs) decides to buffer its output:
isatty function
So if grep is writing directly to your terminal then you’ll see the line as
soon as it’s printed, but if it’s writing to a pipe, you won’t.
Of course the buffer size isn’t always 8KB for every program, it depends on the implementation. For grep the buffering is handled by libc, and libc’s buffer size is
defined in the BUFSIZ variable. Here’s where that’s defined in glibc.
(as an aside: “programs do not use 8KB output buffers when writing to a terminal” isn’t, like, a law of terminal physics, a program COULD use an 8KB buffer when writing output to a terminal if it wanted, it would just be extremely weird if it did that, I can’t think of any program that behaves that way)
One annoying thing about this buffering behaviour is that you kind of need to remember which commands buffer their output when writing to a pipe.
Some commands that don’t buffer their output:
I think almost everything else will buffer output, especially if it’s a command where you’re likely to be using it for batch processing. Here’s a list of some common commands that buffer their output when writing to a pipe, along with the flag that disables block buffering.
--line-buffered)-u)fflush() function)-l)-u)-u)Those are all the ones I can think of, lots of unix commands (like sort) may
or may not buffer their output but it doesn’t matter because sort can’t do
anything until it finishes receiving input anyway.
Also I did my best to test both the Mac OS and GNU versions of these but there are a lot of variations and I might have made some mistakes.
Also, here are a few programming language where the default print statement will buffer output when writing to a pipe, and some ways to disable buffering if you want:
setvbuf)python -u, or PYTHONUNBUFFERED=1, or sys.stdout.reconfigure(line_buffering=False), or print(x, flush=True))STDOUT.sync = true)$| = 1)I assume that these languages are designed this way so that the default print function will be fast when you’re doing batch processing.
Also whether output is buffered or not might depend on how you print, for
example in C++ cout << "hello\n" buffers when writing to a pipe but cout << "hello" << endl will flush its output.
Ctrl-C on a pipe, the contents of the buffer are lostLet’s say you’re running this command as a hacky way to watch for DNS requests
to example.com, and you forgot to pass -l to tcpdump:
sudo tcpdump -ni any port 53 | grep example.com
When you press Ctrl-C, what happens? In a magical perfect world, what I would
want to happen is for tcpdump to flush its buffer, grep would search for
example.com, and I would see all the output I missed.
But in the real world, what happens is that all the programs get killed and the
output in tcpdump’s buffer is lost.
I think this problem is probably unavoidable – I spent a little time with
strace to see how this works and grep receives the SIGINT before
tcpdump anyway so even if tcpdump tried to flush its buffer grep would
already be dead.
After a little more investigation, there is a workaround: if you find
tcpdump’s PID and kill -TERM $PID, then tcpdump will flush the buffer so
you can see the output. That’s kind of a pain but I tested it and it seems to
work.
It’s not just pipes, this will also buffer:
sudo tcpdump -ni any port 53 > output.txt
Redirecting to a file doesn’t have the same “Ctrl-C will totally destroy the
contents of the buffer” problem though – in my experience it usually behaves
more like you’d want, where the contents of the buffer get written to the file
before the program exits. I’m not 100% sure whether this is something you can
always rely on or not.
Okay, let’s talk solutions. Let’s say you’ve run this command:
tail -f /some/log/file | grep thing1 | grep thing2
I asked people on Mastodon how they would solve this in practice and there were 5 basic approaches. Here they are:
Historically my solution to this has been to just avoid the “command writing to pipe slowly” situation completely and instead run a program that will finish quickly like this:
cat /some/log/file | grep thing1 | grep thing2 | tail
This doesn’t do the same thing as the original command but it does mean that you get to avoid thinking about these weird buffering issues.
(you could also do grep thing1 /some/log/file but I often prefer to use an
“unnecessary” cat)
You could remember that grep has a flag to avoid buffering and pass it like this:
tail -f /some/log/file | grep --line-buffered thing1 | grep thing2
Some people said that if they’re specifically dealing with a multiple greps
situation, they’ll rewrite it to use a single awk instead, like this:
tail -f /some/log/file | awk '/thing1/ && /thing2/'
Or you would write a more complicated grep, like this:
tail -f /some/log/file | grep -E 'thing1.*thing2'
(awk also buffers, so for this to work you’ll want awk to be the last command in the pipeline)
stdbufstdbuf uses LD_PRELOAD to turn off libc’s buffering, and you can use it to turn off output buffering like this:
tail -f /some/log/file | stdbuf -o0 grep thing1 | grep thing2
Like any LD_PRELOAD solution it’s a bit unreliable – it doesn’t work on
static binaries, I think won’t work if the program isn’t using libc’s
buffering, and doesn’t always work on Mac OS. Harry Marr has a really nice How stdbuf works post.
unbufferunbuffer program will force the program’s output to be a TTY, which means
that it’ll behave the way it normally would on a TTY (less buffering, colour
output, etc). You could use it in this example like this:
tail -f /some/log/file | unbuffer grep thing1 | grep thing2
Unlike stdbuf it will always work, though it might have unwanted side
effects, for example grep thing1’s will also colour matches.
If you want to install unbuffer, it’s in the expect package.
It’s a bit hard for me to say which one is “best”, I think personally I’m
mostly likely to use unbuffer because I know it’s always going to work.
If I learn about more solutions I’ll try to add them to this post.
I think it’s not very common for me to have a program that slowly trickles data into a pipe like this, normally if I’m using a pipe a bunch of data gets written very quickly, processed by everything in the pipeline, and then everything exits. The only examples I can come up with right now are:
tail -fkubectl logsI think it would be cool if there were a standard environment variable to turn
off buffering, like PYTHONUNBUFFERED in Python. I got this idea from a
couple of blog posts by Mark Dominus
in 2018. Maybe NO_BUFFER like NO_COLOR?
The design seems tricky to get right; Mark points out that NETBSD has environment variables called STDBUF, STDBUF1, etc which gives you a
ton of control over buffering but I imagine most developers don’t want to
implement many different environment variables to handle a relatively minor
edge case.
I’m also curious about whether there are any programs that just automatically flush their output buffers after some period of time (like 1 second). It feels like it would be nice in theory but I can’t think of any program that does that so I imagine there are some downsides.
Some things I didn’t talk about in this post since these posts have been getting pretty long recently and seriously does anyone REALLY want to read 3000 words about buffering?
I like writing Javascript without a build system and for the millionth time yesterday I ran into a problem where I needed to figure out how to import a Javascript library in my code without using a build system, and it took FOREVER to figure out how to import it because the library’s setup instructions assume that you’re using a build system.
Luckily at this point I’ve mostly learned how to navigate this situation and either successfully use the library or decide it’s too difficult and switch to a different library, so here’s the guide I wish I had to importing Javascript libraries years ago.
I’m only going to talk about using Javacript libraries on the frontend, and only about how to use them in a no-build-system setup.
In this post I’m going to talk about:
There are 3 basic types of Javascript files a library can provide:
<script src> and it’ll Just Work. Great if you
can get it but not always availableI’m not sure if there’s a better name for the “classic” type but I’m just going to call it “classic”. Also there’s a type called “AMD” but I’m not sure how relevant it is in 2024.
Now that we know the 3 types of files, let’s talk about how to figure out which of these the library actually provides!
Every Javascript library has a build which it uploads to NPM. You might be thinking (like I did originally) – Julia! The whole POINT is that we’re not using Node to build our library! Why are we talking about NPM?
But if you’re using a link from a CDN like https://cdnjs.cloudflare.com/ajax/libs/Chart.js/4.4.1/chart.umd.min.js, you’re still using the NPM build! All the files on the CDNs originally come from NPM.
Because of this, I sometimes like to npm install the library even if I’m not
planning to use Node to build my library at all – I’ll just create a new temp
folder, npm install there, and then delete it when I’m done. I like being able to poke
around in the files in the NPM build on my filesystem, because then I can be
100% sure that I’m seeing everything that the library is making available in
its build and that the CDN isn’t hiding something from me.
So let’s npm install a few libraries and try to figure out what types of
Javascript files they provide in their builds!
First let’s look inside Chart.js, a plotting library.
$ cd /tmp/whatever
$ npm install chart.js
$ cd node_modules/chart.js/dist
$ ls *.*js
chart.cjs  chart.js  chart.umd.js  helpers.cjs  helpers.js
This library seems to have 3 basic options:
option 1: chart.cjs. The .cjs suffix tells me that this is a CommonJS
file, for using in Node. This means it’s impossible to use it directly in the
browser without some kind of build step.
option 2:chart.js. The .js suffix by itself doesn’t tell us what kind of
file it is, but if I open it up, I see import '@kurkle/color'; which is an
immediate sign that this is an ES module – the import ... syntax is ES
module syntax.
option 3: chart.umd.js. “UMD” stands for “Universal Module Definition”,
which I think means that you can use this file either with a basic <script src>, CommonJS,
or some third thing called AMD that I don’t understand.
When I was using Chart.js I picked Option 3. I just needed to add this to my code:
<script src="./chart.umd.js"> </script>
and then I could use the library with the global Chart environment variable.
Couldn’t be easier. I just copied chart.umd.js into my Git repository so that
I didn’t have to worry about using NPM or the CDNs going down or anything.
dist directoryA lot of libraries will put their build in the dist directory, but not
always! The build files’ location is specified in the library’s package.json.
For example here’s an excerpt from Chart.js’s package.json.
  "jsdelivr": "./dist/chart.umd.js",
  "unpkg": "./dist/chart.umd.js",
  "main": "./dist/chart.cjs",
  "module": "./dist/chart.js",
I think this is saying that if you want to use an ES Module (module) you
should use dist/chart.js, but the jsDelivr and unpkg CDNs should use
./dist/chart.umd.js. I guess main is for Node.
chart.js’s package.json also says "type": "module", which according to this documentation
tells Node to treat files as ES modules by default. I think it doesn’t tell us
specifically which files are ES modules and which ones aren’t but it does tell
us that something in there is an ES module.
@atcute/oauth-browser-client@atcute/oauth-browser-client
is a library for logging into Bluesky with OAuth in the browser.
Let’s see what kinds of Javascript files it provides in its build!
$ npm install @atcute/oauth-browser-client
$ cd node_modules/@atcute/oauth-browser-client/dist
$ ls *js
constants.js  dpop.js  environment.js  errors.js  index.js  resolvers.js
It seems like the only plausible root file in here is index.js, which looks
something like this:
export { configureOAuth } from './environment.js';
export * from './errors.js';
export * from './resolvers.js';
This export syntax means it’s an ES module. That means we can use it in
the browser without a build step! Let’s see how to do that.
Using an ES module isn’t an easy as just adding a <script src="whatever.js">. Instead, if
the ES module has dependencies (like @atcute/oauth-browser-client does) the
steps are:
import { configureOAuth } from '@atcute/oauth-browser-client'; in your JS code<script type="module" src="YOURSCRIPT.js"></script>The reason we need an import map instead of just doing something like import { BrowserOAuthClient } from "./oauth-client-browser.js" is that internally the module has more import statements like import {something} from @atcute/client, and we need to tell the browser where to get the code for @atcute/client and all of its other dependencies.
Here’s what the importmap I used looks like for @atcute/oauth-browser-client:
<script type="importmap">
{
  "imports": {
    "nanoid": "./node_modules/nanoid/bin/dist/index.js",
    "nanoid/non-secure": "./node_modules/nanoid/non-secure/index.js",
    "nanoid/url-alphabet": "./node_modules/nanoid/url-alphabet/dist/index.js",
    "@atcute/oauth-browser-client": "./node_modules/@atcute/oauth-browser-client/dist/index.js",
    "@atcute/client": "./node_modules/@atcute/client/dist/index.js",
    "@atcute/client/utils/did": "./node_modules/@atcute/client/dist/utils/did.js"
  }
}
</script>
Getting these import maps to work is pretty fiddly, I feel like there must be a tool to generate them automatically but I haven’t found one yet. It’s definitely possible to write a script that automatically generates the importmaps using esbuild’s metafile but I haven’t done that and maybe there’s a better way.
I decided to set up importmaps yesterday to get github.com/jvns/bsky-oauth-example to work, so there’s some example code in that repo.
Also someone pointed me to Simon Willison’s download-esm, which will download an ES module and rewrite the imports to point to the JS files directly so that you don’t need importmaps. I haven’t tried it yet but it seems like a great idea.
I did run into some problems with using importmaps in the browser though – it needed to download dozens of Javascript files to load my site, and my webserver in development couldn’t keep up for some reason. I kept seeing files fail to load randomly and then had to reload the page and hope that they would succeed this time.
It wasn’t an issue anymore when I deployed my site to production, so I guess it was a problem with my local dev environment.
Also one slightly annoying thing about ES modules in general is that you need to
be running a webserver to use them, I’m sure this is for a good reason but it’s
easier when you can just open your index.html file without starting a
webserver.
Because of the “too many files” thing I think actually using ES modules with importmaps in this way isn’t actually that appealing to me, but it’s good to know it’s possible.
If the ES module doesn’t have dependencies then it’s even easier – you don’t need the importmaps! You can just:
<script type="module" src="YOURCODE.js"></script> in your HTML. The type="module" is important.import {whatever} from "https://example.com/whatever.js" in YOURCODE.jsIf you don’t want to use importmaps, you can also use a build system like esbuild. I talked about how to do that in Some notes on using esbuild, but this blog post is about ways to avoid build systems completely so I’m not going to talk about that option here. I do still like esbuild though and I think it’s a good option in this case.
CanIUse says that importmaps are in
“Baseline 2023: newly available across major browsers” so my sense is that in
2024 that’s still maybe a little bit too new? I think I would use importmaps
for some fun experimental code that I only wanted like myself and 12 people to
use, but if I wanted my code to be more widely usable I’d use esbuild instead.
@atproto/oauth-client-browserLet’s look at one final example library! This is a different Bluesky auth
library than @atcute/oauth-browser-client.
$ npm install @atproto/oauth-client-browser
$ cd node_modules/@atproto/oauth-client-browser/dist
$ ls *js
browser-oauth-client.js  browser-oauth-database.js  browser-runtime-implementation.js  errors.js  index.js  indexed-db-store.js  util.js
Again, it seems like only real candidate file here is index.js. But this is a
different situation from the previous example library! Let’s take a look at
index.js:
There’s a bunch of stuff like this in index.js:
__exportStar(require("@atproto/oauth-client"), exports);
__exportStar(require("./browser-oauth-client.js"), exports);
__exportStar(require("./errors.js"), exports);
var util_js_1 = require("./util.js");
This require() syntax is CommonJS syntax, which means that we can’t use this
file in the browser at all, we need to use some kind of build step, and
ESBuild won’t work either.
Also in this library’s package.json it says "type": "commonjs" which is
another way to tell it’s CommonJS.
Originally I thought it was impossible to use CommonJS modules without learning a build system, but then someone Bluesky told me about esm.sh! It’s a CDN that will translate anything into an ES Module. skypack.dev does something similar, I’m not sure what the difference is but one person mentioned that if one doesn’t work sometimes they’ll try the other one.
For @atproto/oauth-client-browser using it seems pretty simple, I just need to put this in my HTML:
<script type="module" src="script.js"> </script>
and then put this in script.js.
import { BrowserOAuthClient } from "https://esm.sh/@atproto/oauth-client-browser@0.3.0"
It seems to Just Work, which is cool! Of course this is still sort of using a build system – it’s just that esm.sh is running the build instead of me. My main concerns with this approach are:
I also learned that you can also use esbuild to convert a CommonJS module
into an ES module, though there are some limitations – the import { BrowserOAuthClient } from syntax doesn’t work. Here’s a github issue about that.
I think the esbuild approach is probably more appealing to me than the
esm.sh approach because it’s a tool that I already have on my computer so I
trust it more. I haven’t experimented with this much yet though.
Here’s a summary of the three types of JS files you might encounter, options for how to use them, and how to identify them.
Unhelpfully a .js or .min.js file extension could be any of these 3
options, so if the file is something.js you need to do more detective work to
figure out what you’re dealing with.
<script src="whatever.js"></script>.umd.js extension<script src=... tag and see if it worksimport {whatever} from "./my-module.js" directly in your codeimport {whatever} from "my-module"
import or export statement. (not module.exports = ..., that’s CommonJS).mjs extension"type": "module" in package.json (though it’s not clear to me which file exactly this refers to)https://esm.sh/@atproto/oauth-client-browser@0.3.0require() or module.exports = ... in the code.cjs extension"type": "commonjs" in package.json (though it’s not clear to me which file exactly this refers to)The main difference between CommonJS modules and ES modules from my perspective is that ES modules are actually a standard. This makes me feel a lot more confident using them, because browsers commit to backwards compatibility for web standards forever – if I write some code using ES modules today, I can feel sure that it’ll still work the same way in 15 years.
It also makes me feel better about using tooling like esbuild because even if
the esbuild project dies, because it’s implementing a standard it feels likely
that there will be another similar tool in the future that I can replace it
with.
A lot of the time when I talk about this stuff I get responses like “I hate javascript!!! it’s the worst!!!”. But my experience is that there are a lot of great tools for Javascript (I just learned about https://esm.sh yesterday which seems great! I love esbuild!), and that if I take the time to learn how things works I can take advantage of some of those tools and make my life a lot easier.
So the goal of this post is definitely not to complain about Javascript, it’s to understand the landscape so I can use the tooling in a way that feels good to me.
Here are some questions I still have, I’ll add the answers into the post if I learn the answer.
atcute-client.js), but so that in the browser I can still import multiple
different paths from that file (like both @atcute/client/lexicons and
@atcute/client)?Here’s a list of every tool we talked about in this post:
Writing this post has made me think that even though I usually don’t want to
have a build that I run every time I update the project, I might be willing to
have a build step (using download-esm or something) that I run only once
when setting up the project and never run again except maybe if I’m updating my
dependency versions.
Thanks to Marco Rogers who taught me a lot of the things in this post. I’ve probably made some mistakes in this post and I’d love to know what they are – let me know on Bluesky or Mastodon!
I added a new section to this site a couple weeks ago called TIL (“today I learned”).
One kind of thing I like to post on Mastodon/Bluesky is “hey, here’s a cool thing”, like the great SQLite repl litecli, or the fact that cross compiling in Go Just Works and it’s amazing, or cryptographic right answers, or this great diff tool. Usually I don’t want to write a whole blog post about those things because I really don’t have much more to say than “hey this is useful!”
It started to bother me that I didn’t have anywhere to put those things: for example recently I wanted to use diffdiff and I just could not remember what it was called.
So I quickly made a new folder called /til/, added some
custom styling (I wanted to style the posts to look a little bit like a tweet),
made a little Rake task to help me create new posts quickly (rake new_til), and
set up a separate RSS Feed for it.
I think this new section of the blog might be more for myself than anything, now when I forget the link to Cryptographic Right Answers I can hopefully look it up on the TIL page. (you might think “julia, why not use bookmarks??” but I have been failing to use bookmarks for my whole life and I don’t see that changing ever, putting things in public is for whatever reason much easier for me)
So far it’s been working, often I can actually just make a quick post in 2 minutes which was the goal.
My page is inspired by Simon Willison’s great TIL blog, though my TIL posts are a lot shorter.
This came about because I spent a lot of time on Twitter, so I’ve been thinking about what I want to do about all of my tweets.
I keep reading the advice to “POSSE” (“post on your own site, syndicate elsewhere”), and while I find the idea appealing in principle, for me part of the appeal of social media is that it’s a little bit ephemeral. I can post polls or questions or observations or jokes and then they can just kind of fade away as they become less relevant.
I find it a lot easier to identify specific categories of things that I actually want to have on a Real Website That I Own:
and then let everything else be kind of ephemeral.
I really believe in the advice to make email lists though – the first two (blog posts & comics) both have email lists and RSS feeds that people can subscribe to if they want. I might add a quick summary of any TIL posts from that week to the “blog posts from this week” mailing list.